codexU prices your Codex usage in dollars, then refuses to score it that way
macOS desktop widget for OpenAI Codex usage, quota tracking, token usage, and today task board
At a glance
- What is it?
- A macOS menu bar app that reads ~/.codex/ and ~/.claude/ to show quota windows, token trends and a today board, and adds two newer layers: an AI leadership score built only from verifiable Agent lifecycle evidence, and a monthly API equivalent value estimate. The Windows build is a separate Tauri app with a narrower feature set.
- Who is it for?
- Use codexU if you run Codex or Claude Code several times a day and want quota, reset time and token movement without opening a browser or a terminal, and if you are willing to grant file access to `~/.codex/` and `~/.claude/`. Do not adopt it as a billing tool, since the dollar figure is an API price equivalent and the project says outright that it is not an invoice or a rebate amount.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly Swift, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
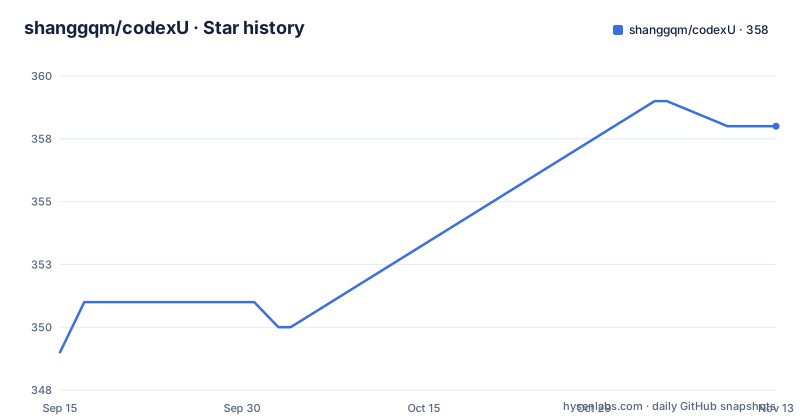
- shanggqm/codexU358 ★ · +9
| Repository | 2026-09-15 | 2026-11-13 |
|---|---|---|
| shanggqm/codexU | 349 | 358 |
9 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The leadership score is built to exclude token counts
The AI leadership model is the feature the project leads with, and the interesting part is what it refuses to use. Scoring relies only on locally verifiable or derivable evidence: Agent lifecycle data, parent-child relationships, concurrency, and autonomous operation records. Unreliable numbers stay out, specifically cost figures, delivery estimates and estimation ranges. The stated reason is that the score measures the AI labour a person commands rather than the volume they spend, and that the two do not track each other. It is computed across Codex and Claude Code together, not split per runtime, and cross-project peaks are not simply added up. The visible form is a badge pinned at the centre of a command radius orbit, with a 2x2 matrix beside it carrying the score, leader Agents over the last 28 days, AI work hours over 28 days, and peak concurrency. Seven badge tiers sit on a fixed 0 to 100 progress scale.
Wool progress turns your token mix into a dollar figure
The feature the README calls wool progress, a nickname for value recovered, exists to solve one specific gap. A Codex quota window shows you a percentage and a reset time, and a raw token count does not tell you what that represents in money. So codexU parses normal input, cache write, cache-hit input and output tokens out of local sessions, prices each against the model's own unit price for the service tier actually used, and converts the total to dollars. It then compares that against Plus, Pro 100, Pro 200 and a reference monthly ceiling, which is how you see roughly how much of a subscription you have got back. The current reference is about $7.75 per million tokens and about $46,500 for a month, derived from 200 million tokens per day over 30 days at a mix of 30 percent uncached input, 50 percent cached input and 20 percent output.
Two honesty notes come with the number. The bar uses a segmented, non-linear scale, so its width is for scanning progress through phases rather than reading off a linear dollar share. And the amount is an equivalent estimate built from public API prices, not a bill and not a rebate from anyone.
The estimate has four guard rails against double counting
The calculation is worth reading closely because token accounting is easy to get wrong. Four components are summed: uncached input, cache write, cache-hit input and output, each divided by a million and multiplied by that model's price for that input class. Four details keep it honest.
First, cache write and cache hits are both capped at the input token count, so the same token cannot be charged twice under two headings. Second, when the parsed `service_tier` is priority or fast, the official Fast mode price is used instead of the standard one. Third, for models that support long context pricing, a single input above 272K tokens switches to the long context price. Fourth, reasoning effort is never multiplied in again, because reasoning tokens are already contained in the output token count.
There is also an explicit honesty marker for gaps. GPT-5.3-Codex-Spark is still a research preview with no published final rate, so it and any unknown model are priced at a GPT-5.5 reference rate and tagged with an approximate sign rather than presented as an official price.
The inference scatter plot says what it is not
The scatter plot at the top of today's Codex tasks plots model against reasoning effort, switchable between today, a 7 day average and a 28 day average. Its axis design is unusually specific. The horizontal axis is the P50 of full call duration over the selected window, with a line extending to P90, and the axis ceiling is set to 1.4 times the largest P90 across all combinations. The vertical axis is output tokens divided by full call duration, so a bubble high and to the left is fast with a lot of output.
Bubble size is where the project is most careful. For today, size is the model's call count. For the 7 and 28 day views, size is the average daily call count across the record coverage period, so a longer window does not inflate the bubbles. The README states plainly that none of these counts are Sessions, threads or tool calls. Samples persist to local Application Support and backfill from the last 28 days of rollout, recording no prompt, reply or path. The stated caveat is that this is a way to compare objective feel over time, and it does not claim to be TTFT or visible text decoding throughput.
The Windows build is a separate app with a narrower feature set
The Windows version shipped with the v1.3.1 release and is described as an independent Tauri desktop implementation, not a port of the Swift app. Installers come in two flavours: `codexU-1.3.1-windows-x86_64.msi` for Windows Installer and `codexU-1.3.1-windows-x86_64-setup.exe` for the NSIS wizard. It targets Windows 10 and 11 on x86_64, and ARM64 is not packaged yet.
Three limitations are stated rather than buried. It supports only Codex and not Claude Code. The release package is not code signed by the repository's default flow, so Windows may show a security prompt on first run. And the two platforms are still evolving separately, so feature coverage is not identical. Verification detail is given too: this round of native visual matrix and shell lifecycle acceptance was completed on a Windows 11 environment classified as build 26200, while Windows 10 remains a support target that was not observed on real hardware in that round. Like the macOS build it reads local data such as `%USERPROFILE%\.codex\` and uploads nothing.
Gatekeeper friction is the price of skipping the App Store
codexU is distributed as a DMG from GitHub Releases and does not go through the Mac App Store, which is why first launch needs help. The documented sequence is to open `codexU.app` once and dismiss the warning if it appears, then go to System Settings, Privacy and Security, find `codexU.app` under Security, click Open Anyway, confirm with Touch ID or a password, and open it again. Right-clicking the app in Finder and choosing Open is the alternative.
The permission story is the part to understand before installing. codexU reads Codex data from `~/.codex/`, and if Claude Code statistics are enabled it also reads local transcripts, tasks and state caches from `~/.claude/`. If macOS prompts for file or folder access and you decline, the widget cannot read local usage, thread and automation task information, so the panels stay empty rather than degraded. Everything else is local too: usage, thread, path, log and account data are not uploaded to a third party service, and the leadership scoring runs entirely on the Mac.
The status bar has three density levels and a battery aware particle effect
Clicking the menu bar icon opens a Runtime menu showing Codex and Claude Code cards, 5 hour and 7 day remaining, and today's plus total tokens. That surface is configurable in three steps. Minimal keeps a bold quota ring. Classic puts the quota numbers inside independent progress rings. Rich shows full labels, progress bars and reset time. When only one valid quota window exists, the layout collapses to a single quota rather than drawing an empty second ring.
The ring direction encodes the basis instead of spending text on it: used is clockwise and left to right, remaining is counterclockwise and right to left. You can switch between them, and between showing 5 hour, 7 day or monthly quota. Quota type is identified from the window duration the protocol actually returns, which is why a Team account monthly window of 43800 minutes is now classified correctly instead of showing as unrecognised.
The particle effect on the ring is where power handling shows. It renders only when the main window is visible, frontmost and focused, drops to hover-only in power saving mode, and switches off entirely in the background, on low battery, under thermal pressure, or when reduce motion is set.
The Makefile reads its version from Info.plist and gates on the SDK
The build file explains several of the app's constraints. Version is not stored in the Makefile: it shells out to PlistBuddy to read `CFBundleShortVersionString` from `Resources/Info.plist`, falling back to 0.1.0 if that fails. Architecture is derived the same indirect way, from the host through a target triple, with the DMG name assembled from the app name, that version and the architecture name pulled back out of the triple:
DEPLOYMENT_TARGET ?= 13.0
APPLE_SILICON_TARGET_TRIPLE ?= arm64-apple-macos$(DEPLOYMENT_TARGET)
INTEL_TARGET_TRIPLE ?= x86_64-apple-macos$(DEPLOYMENT_TARGET)
TARGET_TRIPLE ?= $(HOST_ARCH)-apple-macos$(DEPLOYMENT_TARGET)
ARCH_NAME := $(shell echo "$(TARGET_TRIPLE)"" | sed -E 's/-apple-macos.*//')
DMG_NAME := $(APP_NAME)-$(VERSION)-mac-$(ARCH_NAME).dmg
Two conditional blocks matter. A Liquid Glass feature flag is only defined when the macOS SDK major version is at least 26, so the same source builds on older SDKs without the newer styling. And when no signing identity is supplied, codesigning is ad hoc with `--force --deep --sign -`, while a real identity switches to hardened runtime with a timestamp.
Editorial conclusion
Use codexU if you run Codex or Claude Code several times a day and want quota, reset time and token movement without opening a browser or a terminal, and if you are willing to grant file access to `~/.codex/` and `~/.claude/`. Do not adopt it as a billing tool, since the dollar figure is an API price equivalent and the project says outright that it is not an invoice or a rebate amount. Four things to verify for yourself. That you are on macOS 13 or newer, which is the deployment target, and that your macOS SDK is recent enough for the Liquid Glass paths to compile in at all. Which features you actually get, because the Windows build ships with a separate Tauri Dashboard, supports only Codex, is unsigned, and has no ARM64 package. Which colour schemes you can install, since community palettes are curated through review, a licence check and CI rendering rather than dropped in by users. And that your model pricing assumption still holds, because unknown and research preview models are priced at a GPT-5.5 reference rate and marked as an approximation. Versions v1.2.1, v1.3.0 and v1.3.1 shipped between July and September 2026, with the last push to main dated 8 September 2026.
Frequently asked questions
What is shanggqm/codexU and what does it show?
It is a macOS menu bar and desktop app that shows quota windows, token usage, today's tasks and a local AI leadership figure for OpenAI Codex, ChatGPT Codex and Claude Code. It reads local data from ~/.codex/ and, when Claude Code statistics are on, from ~/.claude/.
How does codexU calculate the monthly dollar estimate?
It prices locally parsed uncached input, cache write, cache-hit input and output tokens at the model's per class unit price, with cache categories capped at the input token count to avoid double counting, Fast mode pricing when service_tier is priority or fast, and long context pricing above 272K input tokens. Unknown and research preview models use a GPT-5.5 reference price marked as approximate.
What does the codexU AI leadership score measure?
It uses only locally verifiable or derivable evidence: Agent lifecycle data, parent-child relationships, concurrency and autonomous operation records. Cost, delivery and estimation figures are excluded, the score covers Codex and Claude Code together rather than per runtime, and it is presented on seven badge tiers with a fixed 0 to 100 scale.
Does codexU have a Windows version and what does it miss?
Yes. The Windows x86_64 build ships with v1.3.1 as MSI and NSIS installers and includes a standalone Tauri Dashboard. It supports only Codex, not Claude Code, it is not code signed by the default flow so Windows may prompt on first run, and ARM64 is not packaged yet.
Why does macOS block codexU the first time it opens?
It is distributed as a DMG from GitHub Releases rather than through the Mac App Store, so Gatekeeper stops the first launch. Open the app once, dismiss the warning, then allow it under System Settings, Privacy and Security via Open Anyway. It also needs file access to ~/.codex/ and ~/.claude/ or its panels cannot read anything.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shanggqm-codexu)Star history chart for your README
[](https://hysenlabs.com/projects/shanggqm-codexu)Was this useful?