Datasette ships two release lines, bakes SQLite files into a publish image, and needs no server in the browser
An open source multi-tool for exploring and publishing data
At a glance
- What is it?
- Datasette turns SQLite database files into an explorable website and a JSON API, and it reaches users through three different doors: a local web server on port 8001, a Docker image deployed by datasette publish, and a WebAssembly build called Datasette Lite. Its own files show the friction, from two release lines published about half a minute apart to a Docker build that fails unless you pass a version tag.
- Who is it for?
- Datasette suits people who already have data in SQLite files and want a browsable site plus an API without building a frontend, and the metadata file is the part worth getting right before publishing.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
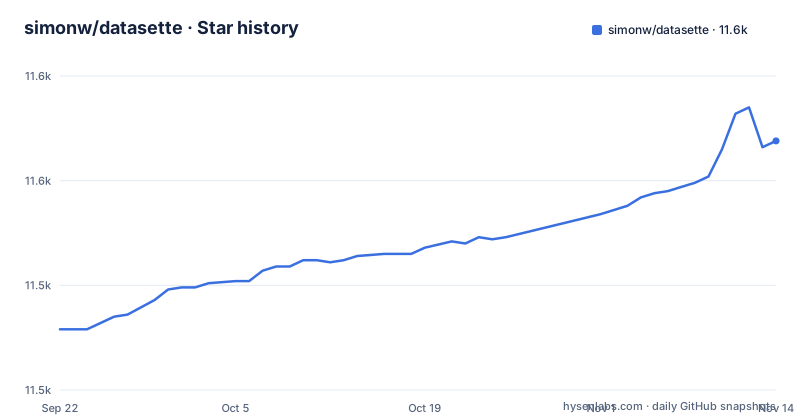
Star history
- simonw/datasette11,569 ★ · +90
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| simonw/datasette | 11.5k | 11.6k |
90 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two release lines published minutes apart in the same window
The release list contains three entries and they do not belong to one line. There is 1.0a41 dated September 24, 2026, then 1.0a40 dated September 16, 2026, then 0.65.5 dated September 16, 2026, and the last two were tagged about half a minute apart. The alpha marker in 1.0a41 is the honest signal about the 1.0 track, and pyproject.toml classifies the project as Development Status :: 4 - Beta rather than a finished 1.0. Consequence for anyone pinning: the maintenance line and the next major line are moving in the same period, so a hard pin to 0.65.5 is a pin to a different product than a pin to 1.0a40. It also matters for the container image, which installs a source archive by tag, so the tag you pass to the build is the only place that choice gets recorded.
The container installs a tag archive and has no default version
The Dockerfile shows exactly how the image is assembled:
FROM python:3.11-slim-bookworm AS build
ARG VERSION
RUN pip install https://github.com/simonw/datasette/archive/refs/tags/${VERSION}.zip && \
    find /usr/local/lib -name '__pycache__' | xargs rm -r && \
    rm -rf /root/.cache/pip

EXPOSE 8001
CMD ["datasette"]
Consequence: ARG VERSION has no default, so a build without that argument resolves to an empty string and the pip install step has no URL to fetch, which fails at build time rather than at run time. The image also installs libsqlite3-mod-spatialite, so spatial functions in the SQLite build are available inside the container, and the image uses Python 3.11. The package requirement depends on the release; PyPI metadata for 0.65.5 and 1.0a41 specifies Python 3.10 or newer. CMD runs the datasette entry point with no subcommand, which works because serve is the default subcommand, and EXPOSE 8001 matches the port the local web server uses.
Port 8001 and --nolock exist because Datasette reads other people's SQLite files
The shortest possible usage is one subcommand and a file path:
datasette serve path/to/database.dbThat starts a web server on port 8001, reachable at http://localhost:8001/, and serve is the default subcommand so it can be dropped. The Chrome history example is the interesting case, because it points Datasette at a database another program owns:
datasette ~/Library/Application\ Support/Google/Chrome/Default/History --nolockThe README runs this with --nolock against the Chrome History file, which Chrome may be writing at the same time. Consequence for readers: that flag is a deliberate trade, useful for a scratch look at your own data and wrong for anything that assumes a consistent snapshot, since rows can change between two page loads. It is also why the URL is a path of names, with the downloads table in that history database surfacing at /History/downloads.
metadata.json is the only place license and source reach both the page and the API
Licensing and provenance are not inferred from the database, they are supplied in a side file. The shape is a title, a license string, a license_url, a source, and a source_url, saved as metadata.json and passed with the -m flag:
datasette serve fivethirtyeight.db -m metadata.jsonThe license and source information then shows on the index page and in the footer, and the same values are included in the JSON produced by the API. Consequence for a publisher: this is how the README attributes license and source on the site and in the API, and it is optional. If your data comes from someone else's repository, the source_url field is the place the README uses for that provenance.
datasette publish puts the database inside the image it deploys
Publishing is a second command with a different cost profile. If Heroku or Google Cloud Run is configured:
datasette publish heroku database.dbor
datasette publish cloudrun database.dbThe README is explicit about the mechanics: this creates a Docker image containing both the Datasette application and the specified SQLite database files, deploys that image, and returns a URL for the website and the API. Consequence for anyone who expects a live database: the data is a layer in the image, so changing a row means a new build and a new deployment, not an update to a running service. That is a reasonable shape for a dataset that changes on a publication cycle and a poor one for anything that changes by the minute. The command also assumes the target is already configured, since the platform credentials are not part of this repository.
Datasette Lite is a different runtime in a different repository
The third door runs the application with no Python web application server at all. Datasette Lite is Datasette packaged using WebAssembly so that it runs entirely in the browser, and it is served from lite.datasette.io. The detail that matters for anyone tracking versions is that the documentation for it lives in a separate repository, datasette-lite, not here, so the browser build and the pip package are developed apart. The top level also contains test-in-pyodide-with-shot-scraper.sh, a script that exercises the browser build under Pyodide with shot-scraper. Consequence: three delivery paths means three places where a behaviour can differ, and the README points at a live demo of the current main branch as another one, so checking which build you are reading about is part of evaluating an answer.
Installing the package also installs pip and a pytest plugin
The runtime dependency list in pyproject.toml is longer than a web server needs. It includes click and click-default-group for the command line, uvicorn and asgiref for serving, Jinja2 for templating, hupper for reloading, sqlite-utils, pydantic, opentelemetry-api, and both setuptools and pip. Consequence for anyone who installs into a shared environment: a single pip install datasette also places a package manager and a build backend into the same site-packages, which matters when that environment belongs to unrelated work. Two more things ride along. The project registers a pytest entry point, datasette = "datasette._pytest_plugin", so any test run in an environment with Datasette installed loads its plugin without being asked. And installation has three documented routes, brew install datasette for Mac, pip or pipx, or Docker covered in the installation docs, and the Python floor depends on the selected release. PyPI metadata for 0.65.5 and 1.0a41 specifies Python 3.10 or newer.
The JavaScript side is a rollup bundle with prettier as the only dev tool
The npm side of the repository is small and specific. package.json is marked private, so it is not published as a package, and its devDependencies hold exactly one entry, prettier at ^3.0.0, with scripts named fix and prettier that run against 'datasette/static/*[!.min|bundle].js'. The runtime entries are the CodeMirror editor packages, codemirror and @codemirror/lang-sql, plus rollup with its node-resolve and terser plugins. Consequence for contributors: npm is not an install route for users of Datasette, it is a formatting and bundling step for the static JavaScript and the SQL editor, and the glob deliberately skips files already minified or bundled. For readers of the repository, the absence of a front end framework here is the signal about the shape of the product, since the interface is server rendered Jinja2 and the browser JavaScript is a small set of static files.
Editorial conclusion
Datasette suits people who already have data in SQLite files and want a browsable site plus an API without building a frontend, and the metadata file is the part worth getting right before publishing. Before you rely on it, decide which release line you are on, because 1.0 is still an alpha while 0.65.5 was tagged about half a minute before 1.0a40, and note the two hard limits: data travels inside the image when you publish, and Datasette reads a SQLite file another process may be writing, which is why the browser history example needs --nolock.
Frequently asked questions
What is a datasette?
Datasette is an open source tool for exploring and publishing data: it takes data of any shape or size and publishes it as an interactive, explorable website with an accompanying API. It targets data journalists, museum curators, archivists, local governments, scientists and researchers who want to share data.
how to install datasette
On a Mac the simplest route is `brew install datasette`, otherwise use `pip` or `pipx` with `pip install datasette`, and check the Python requirement for the chosen release. PyPI metadata for 0.65.5 and 1.0a41 specifies Python 3.10 or newer. Detailed installation instructions on docs.datasette.io also cover other options such as Docker.
how to use datasette
Run `datasette serve path/to/database.db` to start a web server on port 8001 and open http://localhost:8001/, with serve as the default subcommand you can omit. Add `-m metadata.json` to attach license and source details, which appear on the index page, in the footer, and in the JSON from the API.
datasette alternatives
Datasette is presented as a multi-tool with more than one way to run: a local web server through `datasette serve`, deployment to Heroku or Google Cloud Run through `datasette publish`, and Datasette Lite packaged with WebAssembly so it runs entirely in the browser with no Python web application server. There is also a live demo of the current main branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simonw-datasette)Star history chart for your README
[](https://hysenlabs.com/projects/simonw-datasette)Was this useful?