async's last nine releases are all scheduler correctness fixes, two of them about the wrong end value
An awesome asynchronous event-driven reactor for Ruby.
At a glance
- What is it?
- A composable fiber-based asynchronous I/O framework for Ruby, whose readme is mostly a changelog. What that changelog documents is a scheduler being stabilised release by release: premature wake-ups, a value contract inverted in two separate places, and one architectural change that made the whole thing compose with ordinary Ruby iteration.
- Who is it for?
- async is worth considering if you want non-blocking I/O in Ruby without callbacks and you are willing to read the scheduler guide before you use it. Two things to weigh.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
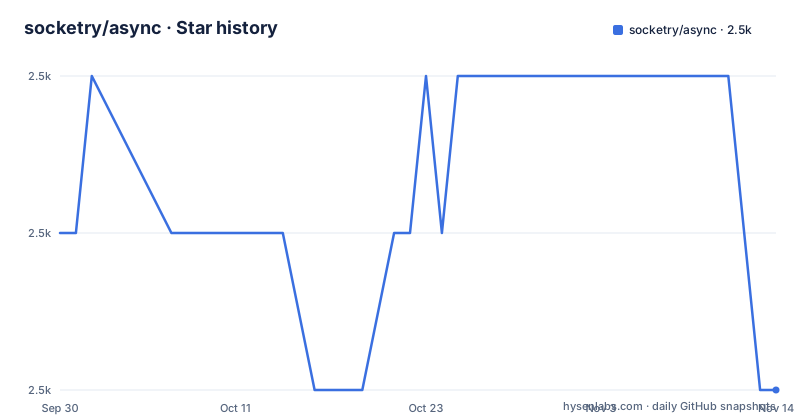
Star history
- socketry/async2,459 ★ · -1
| Repository | 2026-09-30 | 2026-11-14 |
|---|---|---|
| socketry/async | 2.5k | 2.5k |
-1 Stars in the last 45 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Nine consecutive releases, and every one is a scheduler correctness fix
The readme's Releases section lists nine versions in a row, and not one of them adds a capability.
The newest fixes a type error raised when killing a thread that had an active reactor. The one before that fixes a wait returning the wrong value when an explicit timeout expired. The one before that fixes I/O and process waits returning prematurely after wake-ups that were stale or interrupted. Then cleanup after forking while other fibers were blocked. Then propagation of cancellation causes through task trees. Then an interrupt-exception guard on the initial task.
The remaining three are smaller and all are about observability or feedback: a count of how many tasks are waiting on a condition, a barrier that returns how many tasks it waited for, and a barrier bug where a yielding parent let the wait return early before the child had registered itself.
That is the shape of the project in one list. It is a scheduler, and the scheduler has been having exactly the problems a scheduler has: spurious wake-ups, wrong end values, cleanup races at fork, cancellation that stops at a task boundary. The features list is four lines long and the changelog is nine. For a library thousands of Ruby projects depend on, that ratio is the most useful thing the readme tells you.
Two releases got the same value contract backwards in different places
Ruby has a convention for what a non-blocking wait returns, and it is easy to get wrong because two of the three answers are falsey: false means a timeout elapsed, nil means no blocking was needed at all.
Release 2.45.1 got it wrong in the scheduler's own I/O wait. It returned nil where callers expected false on an explicit timeout, and the readme names the consequence precisely: native callers such as a socket connect with a connect timeout check for false to detect a timeout, so a nil produced a type error about converting nil to an integer rather than the timeout error the caller was written to handle.
That is not a small bug. A timeout turned into a crash, in a path used by every network operation in the framework, and it surfaced as an error message about integer conversion that points nowhere near the cause.
Release 2.45.0, the release before, had the same class of error in a different place and had to be careful not to introduce the opposite mistake: non-blocking process waits should still return nil, so fixing the timeout case could not be done by simply making everything return false.
So two adjacent releases, two different call sites, one convention, and in both cases the wrong member of a falsey pair. If you are integrating with Ruby's own wait interfaces, that is the specific area to test.
Premature wake-up returns are the bug class worth reading twice
Release 2.45.0 is the most interesting entry in the list, because it describes the hardest class of bug in this whole field.
The symptom was that scheduler I/O waits and process waits were returning early after wake-ups that were stale or interrupted. In an event-driven system a wake-up can arrive for a reason that is no longer current: the operation you were waiting for has already been resolved elsewhere, or the wake-up was consumed by a different fiber, or the signal that interrupted you was handled and the original condition is gone. Returning from that state means resuming a task that believes it has data it does not.
The fix is described as three different behaviours, one per wait kind. I/O waits now preserve their original timeout. Blocking process waits retry. And non-blocking process waits still return nil, preserving the convention from the previous entry.
That is a careful fix: three paths, three rules, and the third one is there specifically so the second one did not break the interface. And the third rule is exactly the nil-versus-false distinction the previous release got wrong in the other direction.
Two adjacent releases, one fixing an early return and one fixing a value the fix could have got wrong. If you read one entry from this changelog, read that pair.
The change that made it compose with ordinary Ruby was running the reactor on a blocking fiber
Release 2.42.0 is the one entry that reads as a design decision rather than a repair.
Before it, calling the two entry points from a non-blocking fiber with no scheduler of its own raised an error with a fairly blunt message about running a scheduler on a non-blocking fiber. The readme names the situations: inside an enumerator, or inside a fiber you created yourself.
Those are not exotic. Any library that yields from a block, or any code that wraps your code in a fiber for its own reasons, would have hit that error and had no way to satisfy it.
The fix is one architectural change: the reactor is now run inside a blocking fiber, so the scheduler always runs on a fiber that is permitted to block. Everything else about how the reactor works is unchanged.
It is also the change with the longest reach, because it alters where the event loop lives rather than what any individual function returns. It sits in the middle of the nine entries, which suggests it landed after the release team had already been fixing consequences rather than the cause.
Cancellation now travels through the task tree
Release 2.43.0 is one line and it changes how failures read.
Cancellation causes are now propagated through task trees, so a child task observes the original cause rather than a generic cancellation. Before this, a tree of tasks where something deep failed would unwind, and the tasks above it would report that they were cancelled without saying why. With the cause attached, an error crossing a task boundary keeps its identity.
The next entry, 2.44.0, fixed cleanup after forking while other fibers were blocked. Those two are adjacent and related: a task tree that has to unwind correctly on cancellation and also has to survive a fork with waiters on it is the hard case, and getting both right in consecutive releases is what stabilising looks like from the outside.
The three observability entries around them point the same way. A condition can report how many tasks are currently waiting on it. A barrier reports how many tasks it waited for, or nil if there were none. And the barrier fix addresses the case where a parent yields before the child block runs, so the wait returned before the task had even registered itself.
That last one is the kind of bug that makes an instrument like this necessary: once you can count the waiters, a barrier that silently misses one is visible.
The debugging story is native debugger extensions for fibers
The related projects list is five items and four of them are obvious. An asynchronous HTTP client and server, a Rack-compatible server built on top of it, asynchronous websockets, and an asynchronous DNS resolver.
The fifth is a set of debugger extensions for two native debuggers, and the description says what they are for: debugging Ruby applications that use fibers.
That is the most informative line in the document. A concurrency library that most applications can use through ordinary Ruby abstractions does not need native debugger integration. One whose execution model involves fibers you cannot step through with a stock debugger does, and someone built it, and it lives in the same organisation's repository list.
The guides match. There is a debugging guide for programs that use this framework, and a thread-safety guide whose description names the failure modes explicitly: fibers and threads, common pitfalls, and problems like data corruption, race conditions and deadlocks.
The example directory is named the same way. Alongside buffer, callback, capture, count, dataloader, debug, load, queue and stop there are dining-philosophers, bugs, and a test named for a hangup signal. A library whose examples include dining philosophers and signal handling is telling you what it thinks its hard parts are.
Releases are signed and so are contributions, and the reason given is user protection
Two supply-chain paragraphs, and they are short.
The project requires every contributor to comply with the Developer Certificate of Origin, and gives the reason: to protect users of the project, by ensuring that all contributions are properly licensed and attributed.
That is the standard argument for sign-off, and it matters more than usual for a library that sits at the bottom of other people's dependency trees. The value of the guarantee is that it is verifiable per commit rather than trusted per maintainer, and a project at version two point four six with a nine-entry changelog of scheduler repairs is exactly the kind of dependency where you want that.
The root of the repository carries a release certificate file, so the signing is not aspirational.
The other half is the release mechanics, and they are two commands:
bundle exec susruns the test suite, on a framework-agnostic test runner invoked through a task tool rather than on a bundled test framework, and a new release is cut by invoking the same task tool with a patch, minor or major argument.
Both of those mean the day-to-day workflow needs the task tool installed. There is no fallback path in the readme for running the tests without it.
The changelog lives in two files and the scale claim is not tied to the benchmark
The readme's Releases section reproduces nine entries that also exist in a releases file at the root of the repository. That duplication is why this readme is longer than a library's readme usually is, and it is the kind of thing that quietly goes stale: one copy is regenerated by a release command and the other is pasted.
There is a releases page on the documentation site as well, which is a third place.
Against that, the feature list is four lines, and the first of them is a scale claim: thousands of clients per process, with an exclamation mark and no configuration, no hardware and no figure beyond the word thousands.
The repository has a benchmark directory. So the measurements exist somewhere, and the number in the readme is not drawn from them or does not say which run it came from.
The rest of the feature list is more careful. It claims fiber-based concurrency with no callbacks, and multi-thread and multi-process containers for parallelism above that, which is three levels of concurrency and an honest description of the shape. It also describes a growing ecosystem of event-driven components, which the related-projects list then makes concrete in four links.
So the only number in the document is the one without a measurement, and it is in the first bullet.
Editorial conclusion
async is worth considering if you want non-blocking I/O in Ruby without callbacks and you are willing to read the scheduler guide before you use it. Two things to weigh. The nine most recent releases are nine correctness fixes in the scheduler, two of which inverted Ruby's convention for what a wait returns on timeout, so the honest reading is that this layer is young and the fix rate is still high. And the project's own thread-safety guide names data corruption, race conditions and deadlocks as the failure modes, which is the correct thing to document and a fair warning about the layer you are opting into.
Frequently asked questions
What is the async Ruby framework?
A composable asynchronous I/O framework built on a separate event loop library. It uses fiber-based concurrency so no callbacks are needed, and adds multi-thread and multi-process containers for parallelism above that. The readme's feature list is four lines long, and most of the document is a changelog and links to six guides.
Why does the async changelog contain so many scheduler fixes?
Because the recent releases are all scheduler corrections: a thread-kill type error, premature returns from stale or interrupted wake-ups, cleanup after forking with blocked fibers, cancellation not propagating through task trees, and a barrier that could return before a yielding child registered itself. The last nine entries contain no new capability.
What is the nil-versus-false issue in async?
In Ruby, a non-blocking wait returns false on a timeout and nil when no blocking was needed. Two releases got that backwards in different places. One made the scheduler return nil on an explicit timeout, so native callers checking for false crashed with a type error instead of raising the timeout error they handle. The other had to be fixed without breaking the nil convention for non-blocking waits.
How do I run the async test suite?
With the project's task tool invoking a framework-agnostic test runner. The release process uses the same tool with a patch, minor or major argument. Both commands require the task tool to be installed, and the readme offers no alternative way to run the tests.
What does the async documentation say about thread safety?
There is a dedicated guide, and its description names the failure modes directly: fibers and threads, common pitfalls, and problems like data corruption, race conditions and deadlocks. There is also a separate debugging guide, and the related projects include debugger extensions for two native debuggers built specifically for debugging Ruby programs that use fibers.
Does async require signed contributions?
Yes. The project requires contributors to comply with the Developer Certificate of Origin, giving the reason as protecting users by ensuring contributions are properly licensed and attributed. A release certificate file is present at the root of the repository, so the signing applies to releases as well.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/socketry-async)Star history chart for your README
[](https://hysenlabs.com/projects/socketry-async)Was this useful?