roshi: equal timestamps resolve in favour of the first writer, and a read returns the union of disagreeing replicas
Roshi is a large-scale CRDT set implementation for timestamped events.
At a glance
- What is it?
- A SoundCloud system that stores timestamped events as a last-writer-wins element set across independent Redis clusters, with no consensus protocol and three operations. Its own table of add and remove combinations shows that an equal or older write is discarded, that reads can surface a value a write quorum removed, and that its dependency floor is six years behind its last commit.
- Who is it for?
- roshi fits a service that needs a high write throughput index of timestamped events and can accept eventual consistency, which is exactly the case its originating stream was. Four things to know before you build on it.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
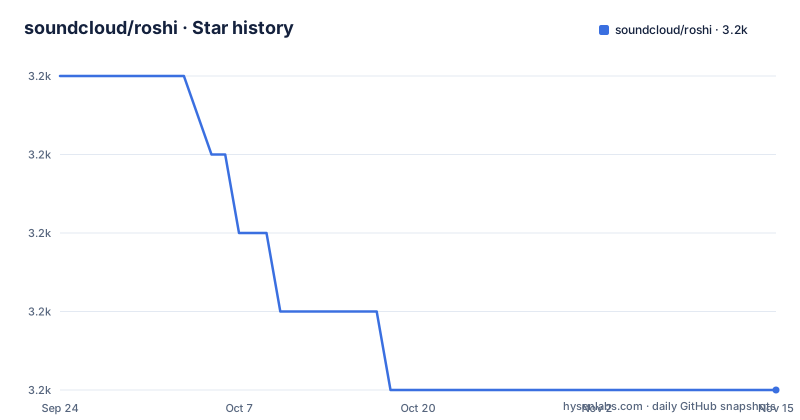
- soundcloud/roshi3,175 ★ · -4
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| soundcloud/roshi | 3.2k | 3.2k |
-4 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Equal timestamps resolve in favour of whoever wrote first
The most useful thing in this README is its table. It enumerates every combination of an existing add set, an existing remove set and an incoming operation, with the resulting state in each row, and the pattern is unambiguous. An incoming write replaces an existing tuple only when the incoming timestamp is strictly greater. An equal timestamp is a no-op: an element sitting in the remove set at timestamp one stays there when an addition arrives with timestamp one, and an element in the add set at timestamp one stays there when a removal arrives with timestamp one. A removal with a greater timestamp moves the element into the remove set; an addition with a greater timestamp moves it back and drops the removal. So there is no tiebreaker anywhere in the design, and two clients writing the same value with the same millisecond produce a deterministic result that depends on arrival order.
The ordering comes from the caller's clock and not from the server
Every operation takes a timestamp as an argument: insert takes a key, a timestamp and a value, delete takes the same three, and select takes a key, an offset and a limit. The sets are ordered by that external timestamp, newest first, and the formal description of the data type writes the tuple as the element paired with the current time. Nothing in the system measures time itself. That is the deliberate trade that lets the layer be stateless and let replicas converge without talking to each other, and it puts the correctness of the ordering in the hands of whoever calls the API. A client whose clock is behind will lose writes to the same key, and a client whose clock jumps forward will win them, including against a removal. For an event stream where the timestamp is a property of the event rather than of the write, that is exactly right; for anything that treats the timestamp as a write time, it is a hazard with no timeout.
A read returns the union of disagreeing replicas and repairs in the background
Replication is described in two phases, and the read phase is the one with a visible consequence. Writes go to every cluster and the operation is declared successful once a user-defined number of them acknowledge; a cluster that did not answer may have been merely slow and may still have taken the write, or it may have failed outright, in which case a later read may repair it. On the read side, a strategy that queries several clusters can spot that they disagree. When it does, the documented behaviour is to return the unioned set to the client and trigger a read-repair in the background that lazily converges every replica. The practical consequence is that a read is not a consistent snapshot: an element a write quorum removed can reappear in a read until the repair has run, and a client that reads and acts on the union will act on data the store has already decided against.
The write quorum is user-defined and a slow cluster may still have taken the write
The number of clusters that must acknowledge before a write returns is not fixed by the system. It is a parameter the operator chooses, and every value of it is a different consistency story: acknowledge on one cluster gives the lowest latency and loses writes when that cluster dies, while acknowledging on all of them gives the write path the availability the rest of the design is arguing for. The README is careful about the middle case, which is the one that surprises people. A cluster that did not acknowledge is either slow, in which case it has probably accepted the write anyway, or it failed, in which case its copy is behind and a later read may reconcile it. So a failed write acknowledgement does not mean a lost write, and a client cannot infer anything about what was stored from what the call returned. That is why the repair path exists, and why the read strategy is where the operator's real configuration decision lives.
Crash safety rests on idempotence and only transient state is lost
The fault tolerance section is short and its argument is structural. The system is homogeneous: every instance can serve every operation for a client and talks to every Redis instance, so an instance carries no authoritative state. What it does hold is transient. If one crashes, two things are lost, and the README names both. Open client connections are lost, which clients handle by reconnecting elsewhere and re-executing their operation. And any repair that had not finished is lost, which a later read may trigger again. Both are survivable for one reason, the same reason the whole data type works: every operation is idempotent. Re-running a write that already landed changes nothing, which is what makes both the reconnect path and the lazy repair safe, and it is the property the three rules in the theory section exist to guarantee.
A vendored directory and a module that replaces itself with the local tree
The repository root has a directory named for vendoring, which is unusual next to a module file that already pins every dependency by version. The module file has one more surprise: it declares a replacement of the module with the current directory. That pattern makes the module's own packages resolve to the working tree, which is how a module can consume its internals during development without publishing itself first. The rest of the tree maps one directory per word the README uses, a cluster package, a farm package for replication and repair, a connection pool, shared code, instrumentation, the server itself, and a walker that reads across the data. The separate farm repository linked from the replication section carries the detail the README defers.
The dependency floor and the language version are six years behind the last commit
The module file declares a language version from 2020, and its direct dependencies are pinned to the same period: a Redis client at a version from 2019, a metrics client still in its pre one series, a router from the same generation, and an indirect system library pinned to a June 2020 revision. Meanwhile the default branch's last commit is dated in September 2026 and the repository has no published releases at all. So the project is being committed to on a dependency floor chosen years ago, which for a Redis client and a metrics exporter is defensible, since both are stable and the surface used here is narrow. It does mean a new adopter inherits versions that receive no updates, and that the version numbers a reader would check for security fixes are not the ones in use. The README's own claim that the layer is stateless and eventually consistent is the right summary of what this codebase is.
Editorial conclusion
roshi fits a service that needs a high write throughput index of timestamped events and can accept eventual consistency, which is exactly the case its originating stream was. Four things to know before you build on it. The ordering is decided by timestamps the caller supplies, so client clock skew decides who wins. An equal or older write is discarded rather than merged, which is why out-of-order delivery can leave an addition looking lost. Reads are documented to return the union of disagreeing clusters and repair in the background, so a read can show a value that a later write quorum removed. And the module's language version and direct dependencies are pinned to 2020 while the branch is being committed to, so check what you inherit.
Frequently asked questions
What is Roshi?
A distributed, stateless layer over Redis that stores timestamped events as sets, using a last-writer-wins element set so replicas converge without a consensus protocol. It exposes insert, delete and a paged select, and it is designed to sit in the request path of an application; its originating use case was the SoundCloud stream.
How does Roshi resolve two writes with the same timestamp?
The existing tuple wins. A write replaces an existing one only when the incoming timestamp is strictly greater, so an equal or older write is a no-op, which the README's table of every add and remove combination states explicitly.
What happens when a Roshi read finds disagreeing replicas?
The documented behaviour is to return the union of the disagreeing clusters to the client and trigger a background repair that lazily converges the sets across replicas. A read can therefore surface a value that a later write quorum removed, until the repair runs.
How does Roshi decide that a write succeeded?
The write goes to all clusters and returns success as soon as a user-defined number acknowledge. A cluster that did not answer may have been too slow and still have taken the write, or may have failed, in which case a later read may repair it.
What state does Roshi keep, and what is lost if an instance dies?
An instance is effectively stateless but holds transient state: open client connections, and any repair that had not finished. Clients can reconnect elsewhere and re-execute their operation, and a later read may trigger the repair again. The README argues neither loss blocks convergence because every operation is idempotent.
How current are the Roshi dependencies?
The module file declares a language version from 2020 and pins its direct dependencies to that era, including a Redis client and a metrics client in their pre one series, while the default branch's last commit is dated 2026-09-11. The module also declares a replacement of itself with the local directory so internal packages resolve inside the tree.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/soundcloud-roshi)Star history chart for your README
[](https://hysenlabs.com/projects/soundcloud-roshi)Was this useful?