reims-vgpu reuses Apple's bundled driver instead of shipping one of its own
reims-vgpu is an experimental virtual GPU for macOS guests
At a glance
- What is it?
- An experimental virtual GPU that lets a macOS guest inside a virtual machine reach the host GPU, built as a QEMU device in Rust with an on-host command-stream decoder. The architectural shortcut is that macOS already ships a paravirtual display driver, so the guest needs nothing installed, which is also what bounds its compatibility.
- Who is it for?
- reims-vgpu suits someone bringing up macOS acceleration in a virtual machine who wants to experiment and can afford to provision a guest from scratch, and it is not a product to deploy on. Read the status note first, because the device interface, boot scripts and supported pathways are all declared unstable, and budget for the setup, since the disk images and firmware variables you need are deliberately absent from the repository.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
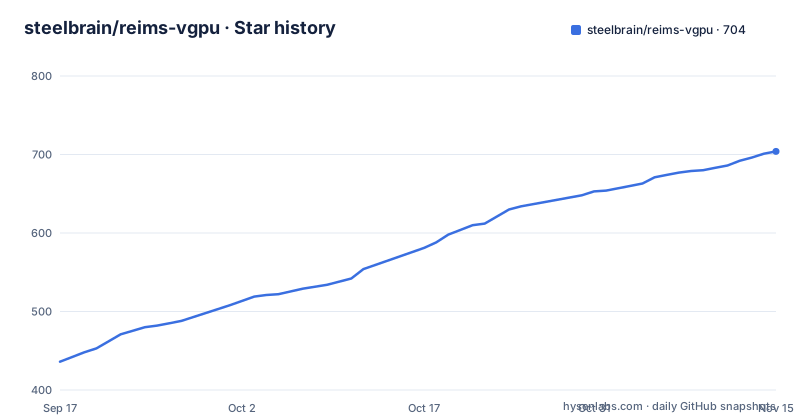
- steelbrain/reims-vgpu704 ★ · +268
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| steelbrain/reims-vgpu | 436 | 704 |
268 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The guest driver already exists, so the guest installs nothing
The central design decision is that the project does not ship a graphics driver for the guest at all.
macOS already includes a paravirtual GPU driver, named in the documentation as a kernel extension. That driver looks for a specific device. reims-vgpu's job is to be that device, implementing the QEMU side that the built-in driver attaches to. Once attached, the guest submits its usual graphics commands and the host decodes that command stream and executes it.
There is no custom kernel extension and nothing to install on the guest.
That shortcut buys a great deal. No signing problem, no system integrity considerations, no per-version guest build, and the guest stays an unmodified macOS installation, which is what makes the claim of accelerated graphics in a virtual machine credible rather than aspirational.
It also sets the compatibility boundary. The approach only works on macOS releases that ship that particular driver, and any change in how the driver probes for its device would break attachment silently rather than loudly. The documentation's own advice to treat the whole thing as bring-up quality rather than a finished product follows from that dependency more than from the amount of code involved.
Three pathways, two attachment mechanisms, and a backend marked as unfinished
The supported matrix is three rows wide, and reading across them explains most of the design.
On a Linux host with hardware virtualisation, an x86_64 macOS guest attaches the device over PCI, and the host executes through its own Vulkan stack via a translation layer. On an Apple Silicon host, an arm64 macOS guest attaches over a system-bus memory-mapped interface instead, and the host can execute either natively through Metal or again through Vulkan, the latter on top of MoltenVK.
Two things follow from the table. The attach mechanism is not an implementation detail you can choose freely, it is tied to the host virtualisation technology. And the guest side is a Metal guest in all three rows, because the in-guest driver is always the same one; only the host execution path varies.
There is a tension worth flagging. The overview says the host executes through Metal, marked as unfinished, or through Vulkan. The table nevertheless lists a pathway whose backend is host Metal. Either the table is describing an intended configuration rather than a working one, or the overview note is out of date. Nothing in the visible text resolves it.
The author's list of areas wanted for collaboration is more revealing: correctness, visual glitches, synchronization bugs, command-stream decoding, translation, and making more host and guest combinations reliable. That is a list of things known to be hard or unfinished, written by the author.
No disk image ships with the project
The getting started section is explicit that the tree contains boot scripts and the device, not a ready-made macOS installation. Guest disks, firmware variables and OpenCore blobs are private and excluded from version control under the virtual machine directory.
So there is nothing to download and boot. You provision a guest once, freeze it as a known-good state, and then work against copies of that state. macOS 13 Ventura is the recommended guest release for bring-up, even though the rail naming scheme spans guest releases from the oldest listed line to the newest.
The two architectures get there differently. The x86 path needs KVM on the host, a working Vulkan stack, and a build of the in-tree QEMU, and then borrows another project to generate the bootloader, firmware variables and an installed guest. The documentation is careful about what that borrow is for: the goal is only to produce a working guest that has finished its setup assistant, not to keep using that project's own long-term launcher.
The arm path has no equivalent borrowing step. It uses the framework virtualization layer installed through a Homebrew package, then QEMU's virtual machine type for Apple platforms, and provisions from an Apple installer image with the project's own helper scripts. The difference in effort between the two is substantial, and the arm path is the one the author is developing on.
Every boot clones a golden image and throws the clone away
The virtual machine management is the most transferable idea in the project.
Guests are organised into rails, one rail per guest operating system line, each with its own snapshot history. Capturing the first immutable snapshot is a one-time operation run from a clean guest state:
mkdir -p vm/disks/rails/macos-15
vm/boot-x86.sh --rail macos-15 --capture --device vmware-svga
From then on, every boot clones the rail's current snapshot, using copy-on-write where the filesystem supports it, and discards the clone on exit. The stated reason is the important part: wedges and hard kills then cannot poison the golden image, because the thing that got wedged was a copy.
Importing a guest built elsewhere uses the same structure without the boot step. Drop the disk, the bootloader disk and the firmware variables into the rail's base directory, make them read-only, and point the current marker at base with a symbolic link. The documentation also suggests a copy command with automatic reflink support so that on a filesystem which supports it the import consumes no additional disk.
Two details protect the arrangement from footguns. Neither the rail flag nor the snapshot flag repoints anything, and an omitted rail follows a separate current marker that you change yourself. So experimenting cannot accidentally reassign your default guest.
The release profile is tuned for a per-draw CPU path, not for build speed
The workspace manifest explains its own optimization settings in terms of where the time actually goes, which is unusual and useful.
The shipping artifact is a static library linked into QEMU, and the device's largest cost is host CPU inside that library. The specific hot path named is the per-draw chain phase, whose work is described as Rust computation rather than GPU computation. So maximum optimization, fat link-time optimization and a single codegen unit are presented as the settings the product runs under rather than as a developer convenience.
One setting in that profile is enabled that is not normally: incremental compilation. In a release profile that trades build time for faster incremental rebuilds, which says the authors are iterating on this code rather than building it once.
The other part of the comment is the more important engineering statement. The panic strategy must not be changed to abort. Every entry point that QEMU calls wraps its body in a panic catch, because a Rust panic unwinding into QEMU's C frames is undefined behaviour. Aborting instead would convert every caught panic into a killed virtual machine.
That single constraint dictates the shape of the whole device integration layer, and it is the kind of note that only exists because somebody hit it.
Firmware initialization lives in a workspace that is deliberately excluded
The workspace lists ten crates for the host side and explicitly excludes an eleventh.
The excluded one is a UEFI option ROM, built for a bare-metal target and kept as its own separate workspace so that host builds never pull in that no-std graph. The stated reason is build hygiene rather than architectural necessity.
The reason an option ROM is needed at all is worth understanding, because it says something about the device's role. A display device has to be initialized before an operating system driver attaches to it, and that initialization happens in firmware. So the project carries a component that runs at boot, on hardware that knows nothing about macOS, and whose only job is to make the device present enough for the Apple driver to bind to.
The remaining crates split along obvious lines: the product crate holds decoding, the device model and the host backends, a separate crate holds the derived wire layout serializers and parsers which the decoder treats as the authority for covered records, and others cover configuration, memory, paging, observation, protocol types, a test kit and the Vulkan backend.
Treating the wire format as a separate crate with a stated authority relationship is the right call for a component like this, since protocol drift is the failure mode that would otherwise be hardest to diagnose.
Bring-up uses a different device than the product path
The day-to-day commands are organised around the idea that you debug the host stack with something simpler than the thing you are building.
Two device options appear. One is a mainstream virtual display adapter that gives console output only and is described as the kind of VGA device the other macOS virtualisation tooling uses, for debugging the host side before the product device is involved. The other is the product device itself, which requires the in-tree QEMU build and the project's Vulkan backend, selected with a backend environment variable on the build script.
The rest of the command surface is small: list which guest lines exist with a marker for the default, list the snapshots in a rail, and take a screenshot of the host window, which the documentation notes works on either a Linux desktop or a macOS host.
What is absent from this section is as informative as what is present. There is no documented way to get logs out of the decoder, no described failure output, and no guidance on what a partially working device looks like from the guest's side beyond the author's mention of visual glitches. For a project whose own status note invites experimentation, that is where the documentation is thinnest.
Editorial conclusion
reims-vgpu suits someone bringing up macOS acceleration in a virtual machine who wants to experiment and can afford to provision a guest from scratch, and it is not a product to deploy on. Read the status note first, because the device interface, boot scripts and supported pathways are all declared unstable, and budget for the setup, since the disk images and firmware variables you need are deliberately absent from the repository.
Frequently asked questions
What is reims-vgpu and how does it work?
It is an experimental virtual GPU that lets a macOS guest in a virtual machine use the host GPU. macOS already ships a paravirtual display driver, so the project implements the QEMU device that driver attaches to and decodes the guest's command stream on the host, meaning no custom kernel extension and no guest driver to install.
Does reims-vgpu ship a macOS disk image?
No. The tree contains boot scripts and the device, while guest disks, firmware variables and bootloader blobs are private and excluded from version control. You provision a guest once, freeze it as a snapshot, and every later boot clones and discards that copy.
Which host and guest combinations does reims-vgpu support?
Three pathways: an x86_64 macOS guest on a Linux host over KVM attaching by PCI and executing on the host through Vulkan, and an arm64 macOS guest on an Apple Silicon host attaching by a system-bus memory-mapped interface, executing through either host Metal or host Vulkan on top of MoltenVK.
What status is reims-vgpu in?
The project describes itself as early alpha and research quality, and warns that the device interface, boot scripts, crate layout, backend behavior and supported pathways may change without a stable compatibility guarantee. The last push to the repository is dated 2026-09-03.
What does reims-vgpu use for Vulkan support on macOS?
Vulkan execution goes through a separate translation crate maintained by the same author, and on a macOS host that path runs on top of MoltenVK. The thin QEMU device shims are tracked in a separate repository and contain only interface plumbing, with the decoding logic living in the Rust product crate.
Does UTM support GPU acceleration like reims-vgpu?
That question is about a different project. This repository documents only the pathways built around an in-tree QEMU build and the project's own device, and says nothing about other macOS virtualisation tools.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/steelbrain-reims-vgpu)Star history chart for your README
[](https://hysenlabs.com/projects/steelbrain-reims-vgpu)Was this useful?