GarminDb: a version tuple read by regex, and a make target that skips two of three databases
Download and parse data from Garmin Connect or a Garmin watch, FitBit CSV, and MS Health CSV files into and analyze data in Sqlite serverless databases with Jupyter notebooks.
At a glance
- What is it?
- tcgoetz/GarminDB downloads Garmin Connect data into SQLite files for notebook analysis, and its build is a setup.py that greps a version tuple out of a source file, reads its dependency list with readlines so a comment becomes a requirement, and offers a default make target that refreshes the Garmin database only.
- Who is it for?
- Use it if you want your own health data in a SQLite file you control and you are prepared to hold a Garmin Connect password in a plaintext config while it runs, and install from PyPI rather than from source so you avoid the SSH submodule requirement.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
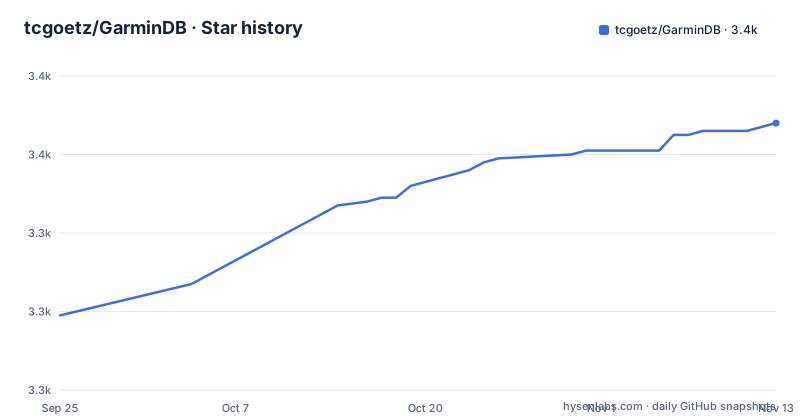
- tcgoetz/GarminDB3,368 ★ · +49
| Repository | 2026-09-25 | 2026-11-13 |
|---|---|---|
| tcgoetz/GarminDB | 3.3k | 3.4k |
49 Stars in the last 49 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README opens with the same wiki link three times before the project title
The first eight lines of this README are not prose. They are three identical empty markdown links, each one pointing at the Screenshots page of the project wiki, with two horizontal rules between them. The project title, GarminDB, does not appear until line nine.
Empty link syntax with a URL inside it is an image placeholder whose image source failed to render. Three of them, stacked, means the intent was three screenshot images at the top of the page and what arrived was three copies of the same stub. The repository listing does contain a Screenshots directory, so the images exist as files; they are simply not referenced from the README, which points at a wiki page instead.
Two horizontal rules around empty images also means the page renders as three blank bands before a reader reaches the title. On a project whose main selling point is that you can graph your own health data, the first impression of the repository is three broken embeds.
The rest of the README is unusually practical once you are past that. It lists what the scripts do in seven bullets, from downloading daily monitoring files through to exporting activities as TCX, and it tells you which SQLite browsers to use afterwards. The header is the accident; the body is a working manual.
The version is a tuple in a Python file, read by a regex with no failure branch
There is no version field in a project file. setup.py defines a function called get_version that opens garmindb/version_info.py, reads it, and searches the text with a regular expression matching the shape version_info = (digits, digits, digits), then joins the three captured groups with dots.
So the single source of truth for the released version is a tuple literal inside a Python source file, and the build reads it with a regex rather than importing it. The function has an if and no else. If the pattern does not match, the function falls off the end and returns nothing, and setup() is then called with that nothing as the version. Nothing raises, nothing warns, and the failure surfaces as whatever setuptools does with a missing version, some distance away from the cause.
The same file has three more helper functions with the same shape, one each for the long description and the requirements, and all four announce themselves. Every one of them prints a line to standard output before doing its work, naming the file it is loading and the current working directory, and a final print states which module and version are being built. So installing from a source tree prints four progress lines to your terminal during the build.
The three docstrings also each contain the same misspelling of from, written as fron, in the version, description and requirements helpers. Minor on its own, and worth noting only because it is three identical copies rather than one.
install_requires comes from readlines, so the comment in requirements.txt becomes a requirement
Look at how the requirements reach setuptools. The helper opens requirements.txt, calls readlines, and returns the result. That list is passed straight to setup() as install_requires.
readlines returns every line with its newline still attached, including any line that is a comment. The requirements file in this repository has a comment in it, sitting on its own line between the pinned packages and tornado. So that comment string, with its trailing newline, is handed to setuptools as if it were a package name.
This is the ordinary consequence of using a human-maintained requirements file as a machine-consumed metadata source, and the usual fix is to filter anything that does not look like a requirement. There is no filter here. The result is that a line a human wrote as an explanatory note is passed into the packaging metadata verbatim, and the behaviour you get depends on how the installed setuptools version reacts to a line it cannot parse, which is to warn and carry on.
The newline retention is the quieter half of the same problem. Every entry in install_requires keeps its own line ending, so the value is not a clean package string.
None of this stops the install. It does mean the file that humans maintain for humans is being used as the single source for machine metadata with no translation step, which is why a comment ends up where a dependency should be.
Five dependencies are pinned exactly, four float, and one comment explains a security fix
The requirements file has ten entries and two different pinning disciplines in the same list. Five use an exact equals pin: SQLAlchemy at 2.0.52, python-dateutil at 2.9.0.post0, cached-property at 2.0.1, tqdm at 4.67.1 and garminconnect at 0.3.11. Four use a floor instead: fitfile, tcxfile, idbutils and tornado, each with a greater than or equal to constraint.
The tightest of those is garminconnect, pinned to an exact patch of a third party client for Garmin Connect. That is the constraint most likely to block an upgrade, and it is also the dependency that reaches the outside world, since it is the piece that talks to Garmin.
The last entry is preceded by a comment reading security fixes. That is the only explanation in the file, and it explains why tornado is in the list at all. A streaming web framework is not something a command line ETL tool needs for its own sake, so its presence is the residue of a security advisory rather than a feature dependency, and nothing in the repository records which issue prompted it. A reader has to take the comment on trust.
The same pattern shows up in the packaging layout. The repository carries requirements.in next to requirements.txt and dev-requirements.in next to dev-requirements.txt, which is the pip-compile arrangement: hand-written inputs and generated outputs, both committed. And pyproject.toml exists only as pyproject.toml.in, a template, with setup.py doing the actual build.
Bare make updates the Garmin database only, while the README promises one command keeps everything current
The README's source instructions end with a single sentence: keep all of your local data up to date by periodically running only one command, make. The Makefile's dependency graph does not deliver that.
The default target is all, and all depends on update_dbs, and update_dbs depends on update_garmin. That is the end of the chain. The Fitbit and Microsoft Health databases appear in create_dbs alongside garmin, and in build_dbs, and in rebuild_dbs, but none of them is reachable from all or from update_dbs. There is a separate update target for Garmin built against the installed binary rather than the virtual environment script, and a separate target for a copy of the Garmin database, but again neither includes the other two data sources.
So if you only ever import from Garmin, the README sentence is accurate. If you also imported Fitbit CSV or Microsoft Health CSV, which the packaging metadata clearly supports, then a bare make refreshes one of your three databases and quietly leaves the other two at whatever they were when they were created.
Two other things about the same file. The Makefile exports PROJECT_BASE as the current directory and derives a virtual environment path and pip and python paths from it, and the setup_repo target depends on the config file path as a Make prerequisite, so a missing config stops the pipeline at the prerequisite rather than inside the recipe. It also prints five informational lines at parse time, before any target runs, including the detected platform and shell.
The parsers exist twice, as submodules for source builds and as packages for releases
There are two documented ways to install this project and they resolve their file parsers from different places.
The release path is pip install garmindb from PyPI, and the requirements file asks PyPI for fitfile and tcxfile. Those two packages are the FIT activity file parser and the TCX export parser.
The source path is different. The README instructs you to clone using SSH rather than HTTPS and states the reason: the submodules require SSH and not HTTPS. The Makefile names those submodules as Fit, Tcx and utilities, and the repository listing shows all three as top level entries, alongside a .gitmodules file and a submodules_update target that setup depends on.
So the same parsing code is present twice in this project. A release build pulls fitfile and tcxfile from PyPI. A source build clones local copies of Fit and Txc over SSH and installs them from the working tree. Anything fixed in one is not automatically in the other, and the two versions can drift with nothing in the build to notice.
The SSH requirement is the part that catches people out. It is not a preference; it is a hard requirement of the submodule step, and it means a source install needs a working SSH key before make setup will get anywhere. The release path needs neither submodules nor SSH, which is the strongest argument for using the PyPI route unless you intend to change the parsers yourself.
A config key called steps holds course ids inside course_views
The notes section documents a configuration key that almost certainly used to be something else. In GarminConnectConfig.json, the steps element of the course_views object is a list of course ids, and a per-course database view gets generated for each one so you can compare every activity from that course.
The inconsistency is the pairing. A key named steps, inside an object named course_views, holding identifiers of courses. Courses are not steps, and the object name matches the content while the key name matches neither. It reads like a field that was renamed at the config level and never renamed at the key level, or like two generations of vocabulary left side by side.
The consequence is practical. Anyone writing that JSON by hand or generating it from a script has to guess that steps is the right key for a list of course ids, and a wrong guess produces an empty list rather than an error, because nothing validates the shape of the file. The rest of the same file is where you put your Garmin Connect username and password and your start dates, so it is a file people do edit by hand.
That notes section has other rough edges worth naming in the same breath, because they tell you how much of the file is prose rather than specification. One instruction ends with runt he download again, with the word run and the word the run together. Another says all of your data will not be redownloaded from Garmin, which is a double negative for none of your data. And the development note says the scripts were developed on MacOS and invites information or patches on other platforms.
The credentials are plaintext in a dot directory in your home, and the daily data comes from a web page
Two things about the data source are worth putting side by side.
The first is where the daily monitoring data comes from. The README describes it as the Garmin daily monitoring files, covering all day heart rate, activity, climb and descend, stress and intensity minutes, downloaded from the user's Garmin Connect Daily Summary page. A page, not an API. Sleep, weight and resting heart rate are described differently, as extracted from Garmin Connect and stored as JSON files before import, and the requirements file does pin garminconnect to an exact patch, so more than one route exists. But the daily monitoring path is described in terms of a web page, and a page is a thing that can be redesigned without notice.
The second is the credential. You copy GarminConnectConfig.json.example to ~/.GarminDb/GarminConnectConfig.json and put your Garmin Connect username and password in it as plaintext, alongside the start dates for your data range. The path is a dot directory in your home rather than anything under a config directory, and the README says nothing about the file's permissions, anything at rest, or who else can read it.
That combination is the trade this project asks you to make. It keeps the downloaded JSON and FIT files on disk so the databases can be rebuilt without ever connecting to Garmin again, which is genuinely useful when a vendor changes a page. The cost is that a first-party Garmin account password lives in a plain file the whole time the tool is configured, on a machine that also holds years of health data.
The README does offer a check for this. When a database update finishes, a summary is written to stats.txt recording the date ranges covered by the downloaded files and the record counts for daily monitoring, activities, sleep, resting heart rate and weight, and the suggested use is to confirm that everything you expected actually arrived.
Editorial conclusion
Use it if you want your own health data in a SQLite file you control and you are prepared to hold a Garmin Connect password in a plaintext config while it runs, and install from PyPI rather than from source so you avoid the SSH submodule requirement. Three things to check: bare make refreshes only the Garmin database even though the packaging supports Fitbit and Microsoft Health as well, a schema change means rebuilding from the files already on disk rather than re-fetching, and the requirements file mixes exact pins with floors while explaining its tornado entry only as a security fix. Skip it if you need a maintained server or a documented permissions story for the credential file.
Frequently asked questions
Where does GarminDb keep my Garmin Connect password?
In GarminConnectConfig.json, copied from GarminConnectConfig.json.example to ~/.GarminDb/GarminConnectConfig.json. You add your Garmin Connect username and password there as plaintext, along with the start dates that match your data range. The README does not discuss file permissions for it.
How do I update an existing GarminDb database?
Run garmindb_cli.py --all --download --import --analyze --latest, which downloads the latest data and imports it; the initial run drops the --latest. If the schema changed and you hit a DB version exception, garmindb_cli.py --rebuild_db regenerates the databases from files already on disk without redownloading from Garmin.
Do I need SSH to install GarminDb?
Only from source. The README says the submodules require SSH rather than HTTPS, and the Makefile names them Fit, Tcx and utilities. Installing the release from PyPI with pip install garmindb requires neither SSH nor submodules.
Can GarminDb import Fitbit or Microsoft Health data?
Yes. The package list in setup.py includes fitbitdb and mshealthdb subpackages, and scripts/fitbit.py and scripts/mshealth.py are installed alongside the main CLI. The requirements file pins garminconnect, the client used for the Garmin side.
What is stats.txt for?
It is written when a database update finishes. It records the date ranges covered by the downloaded daily monitoring files and activities, plus record counts for daily monitoring, activities, sleep, resting heart rate and weight. The README suggests using it to check that everything was downloaded.
How does GarminDb find the right Garmin Connect data?
You set the start dates in GarminConnectConfig.json to match the dates of your data. When a build finishes it writes a summary to stats.txt with the date ranges covered and the record counts, so you can tell whether anything is missing and adjust those dates and run again.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tcgoetz-garmindb)Star history chart for your README
[](https://hysenlabs.com/projects/tcgoetz-garmindb)Was this useful?