TNTSearch's README has a section written for agents and six rules for what trips them up
A fully featured full text search engine written in PHP
At a glance
- What is it?
- teamtnt/tntsearch is a MIT licensed PHP full-text search engine that keeps an inverted index in SQLite, MySQL, or Redis and returns document identifiers rather than rows. Its documentation separates the database your data lives in from the database the index lives in, and warns that the stemmer is fixed when the index is written.
- Who is it for?
- TNTSearch suits a PHP application that needs search over data it already stores, since the engine does not return documents and leaves row fetching to you, which keeps it out of your persistence layer. Two things to know before wiring it up.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
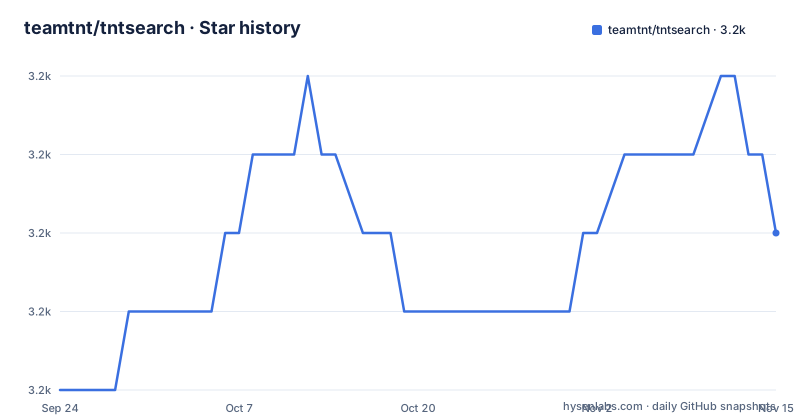
Star history
- teamtnt/tntsearch3,200 ★ · +2
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| teamtnt/tntsearch | 3.2k | 3.2k |
2 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README has a section written for agents, with six rules for what trips them up
There is a section near the top of the file with a heading that addresses AI agents directly, and it is the most unusual thing in the repository.
It gives a one-line description of what the library is, then a mental model in three steps: index your data once, which creates an index file in a storage folder; select that index; search it and get back an array of document identifiers ordered by relevance.
Then comes a list headed as the rules that trip agents up, and there are six of them.
They are not stylistic warnings. They are the actual failure modes, stated as things you will get wrong: the search calls return identifiers rather than rows; you must create an index before indexing and select one before searching; the first column of the indexer query is the primary key; the relevance search is an OR rather than an AND; the storage folder must be writable and the source database and the index are separate things; and the stemmer and tokenizer are fixed when the index is built.
A library that writes a section for a machine reader is making a statement about who it expects to use it. The rules are the same ones a human would need, but they are front-loaded rather than scattered.
search returns identifiers and a formatted time string
The return shape of the relevance search is documented as a literal array, which is more useful than prose describing it.
'ids'            => [7, 3, 10],
'hits'           => 42,
'docScores'      => [7 => 5.1, 3 => 4.8],
'execution_time' => '3.1 ms',
Three things follow from those four lines.
The ordering lives in the identifiers array, and the scores array is keyed by identifier rather than being a parallel list, so any consumer that reads scores positionally gets the wrong association for every result after the first.
The timing value is a formatted string with a unit in it, not a number. Nothing in the library can do arithmetic on it, so anything that wants to log, threshold, or aggregate it has to parse it first.
And the hit count is a separate field from the number of identifiers returned, because the search call takes a maximum result count as its second argument, defaulting to a hundred. The two numbers answer different questions and are easy to confuse.
The README is explicit that the identifiers are the deliverable and that fetching the rows is the caller's job, including the note that the order has to be preserved on the way back.
The database your data lives in and the database the index lives in are two axes
The configuration table has two rows that look like one setting and are in fact four combinations.
The `driver` key is where your source data lives. It accepts five values: SQLite, MySQL, PostgreSQL, SQL Server, and the filesystem.
The `engine` key is where the index is written. It accepts three values, a SQLite engine that is the default, a MySQL engine, and a Redis engine, and the file notes that all three expose the same API.
So a MySQL source with a SQLite index is a valid configuration, and so is a directory of text files with an index in Redis. The two rows are independent and the table presents them side by side without a sentence explaining what that independence means.
The filesystem driver is the one worth noticing, because it is not a database at all. Indexing from it uses a `location` key for the directory to scan and an `extension` key for the file type, and neither of those two keys appears in the configuration table.
There is a second thing the table carries that prose usually misses. An `options` key passes extra options straight to the database connection, and the example given is the TLS certificate attribute, offered as the way to connect to a managed MySQL provider that requires TLS.
The stemmer is fixed when the index is written, not when you search
One of the six agent rules is the sharpest thing in the file, and it is worth stating on its own.
The stemmer and the tokenizer are baked into the index at index time. The instruction is to set them when you create the index, not when you search.
The index is a file on disk. Whatever stemming and tokenisation rules were applied when that file was written are the rules the search will use, and configuring them at search time does not change them. A search that returns fewer results than expected, or results that look unstemmed, is the symptom of a configuration set on the wrong side of the indexing step.
Two defaults are named, and both are no-ops unless you change them. The stemmer defaults to a class that does no stemming at all. The tokenizer defaults to a class that splits on Unicode words while keeping digits and three punctuation characters attached.
There is a language shortcut as well. The indexer accepts a method to pick a stemmer by language, and the example uses a language name rather than a class.
Combined with the identifier-returning API, this means the index file is the place where search behaviour is decided, and the configuration object is the place where the index file is described.
The documented failure is a missing PDO driver where CLI and web differ
The installation section is one command and one requirements line, followed by a note about a specific exception.
The command is a Composer require. The requirements are PHP 7.4 or newer, the database abstraction layer, the SQLite driver extension for the default engine, and a multibyte string extension.
The note is about the exception `PDOException: could not find driver`, and it is unusually specific about the cause and about who is not responsible. The extension is not enabled for the PHP binary that is running the code, the CLI and the web frequently differ in that respect, and it is an environment problem rather than a library one.
That is a real class of failure that costs hours, because the same code fails in one context and works in the other. Naming it in the installation section rather than in a troubleshooting page is the right place for it.
The PHP floor is the other thing to note. Version 7.4 is the minimum the library declares, and it is well past the point where that version receives anything from its own maintainers. Nothing in the file says what happens on a newer version, or what the project has been tested against.
Two of the eleven advertised features appear nowhere else
The feature set is written as a single line with separators rather than as a list, and it names eleven things.
Fuzzy search, search-as-you-type, boolean search, geo-search, ranking by two named algorithms, stemming across many languages, custom tokenizers, result highlighting, text classification, and dynamic index updates.
Most of those are visible elsewhere in the file. The relevance search and the boolean search each have their own section with an example. The ranking function is named in the shape of the returned array. Dynamic index updates have a section describing insert, update, and delete against a selected index, each insert wrapped in its own transaction.
Two are not. Geo-search and text classification appear in that one line and nowhere in the configuration table, none of the usage sections, or the cheat-sheet the file points to at the bottom. There is no configuration key for either, no method named for either, and no note about what either does.
That does not mean they are absent from the code. It means the README's own index of features is broader than the documentation behind it, and a reader working from the feature line to plan an integration will not find where to turn.
The filesystem indexing path is documented separately and is complete, with its own example showing the directory and the file extension.
Two conduct files, a Travis configuration, and an attribution file in one root
The repository root has seventeen entries, and several of them overlap.
There are two conduct files, one named for the code of conduct and one named simply as conduct. There is also a separate contribution guide and a change log.
An attribution file sits among them, named for a commercial package vendor rather than for anything in this project.
The test configuration is split across two files with related names: one with an XML extension and one with a PHP extension, both at the root, alongside a test directory and a benchmark directory.
Continuous integration is a single Travis configuration file. There is no directory for the other common CI provider, which means a reader looking at the root sees a project built on a service the PHP community has largely moved off.
There is a helper directory at the root, named in the singular.
None of this is broken, and none of it is unusual enough to matter on its own. Taken together it is a picture of a project that has accumulated root-level files over years without a periodic pass, which is worth knowing before you assume the file list is a curated index.
A release titled after a dependency, and a missing minor version
The three most recent releases have inconsistent titles, and the version sequence has a gap.
The tags themselves are conventional: two with a version prefix, at 5.3.0 and at 5.2.0.
Two of the release titles repeat the version number. The third is titled with the name of a dependency.
That dependency is the Redis client for PHP. So one of the three most recent releases announces itself by naming a package it pulls in, which means the title cannot be read as a description of what changed and a reader has to open the change log to find out.
The gap is between the third and the second. The 5.0.3 release is dated March 2026, the 5.2.0 release is dated August 2026, and there is no 5.1 release in between.
The two August releases are also nine and a half hours apart on the same day, which reads as a minor bump followed by a patch rather than as two separate decisions.
The homepage recorded for the project is not the project's own site but an article on the maintainers' site about solving search with Laravel and this engine. So the first thing a reader lands on is a write-up rather than documentation.
Editorial conclusion
TNTSearch suits a PHP application that needs search over data it already stores, since the engine does not return documents and leaves row fetching to you, which keeps it out of your persistence layer. Two things to know before wiring it up. The stemmer and tokenizer are fixed when the index is written, so a search-time change to either is silently ignored and has to be a reindex. And the index and the source data are separate stores by default, with SQLite holding one and your database holding the other, so a deployment has two things to back up and two things to keep in step.
Frequently asked questions
What does TNTSearch return from a search?
Document identifiers and scores, not the documents themselves. The array has an identifiers list ordered best match first, a total hit count, a map of identifier to ranking score, and an execution time given as a formatted string with its unit. You fetch the rows from your own database using those identifiers and preserve the order.
Where can TNTSearch keep its index?
Three backends, selected with the engine key: a SQLite engine that is the default and needs no server, a MySQL engine that keeps the index in your MySQL database, and a Redis engine that keeps it in Redis. All three expose the same API, and the choice is independent of where your source data lives.
How do I install TNTSearch and what does it require?
One Composer require command. The requirements are PHP 7.4 or newer, the database abstraction layer, the SQLite PDO extension for the default engine, and a multibyte string extension. The file also names the specific failure where the SQLite driver is missing for one PHP binary but present for another.
Can I change the stemmer or tokenizer after building the index?
Not for an existing index. Both are baked into the index when it is created, so the instruction is to set them at index time rather than at search time. Changing them afterwards does nothing until the index is rebuilt. The stemmer defaults to a class that does no stemming, and the indexer also accepts a language shortcut for picking one.
Does TNTSearch need a full reindex when data changes?
No. Once an index is selected you can insert, update, and delete individual records against it, and each insert is wrapped in its own transaction. For a large initial load, the run method streams the source query and writes the index in batched transactions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/teamtnt-tntsearch)Star history chart for your README
[](https://hysenlabs.com/projects/teamtnt-tntsearch)Was this useful?