Portable AI Studio: four local engines, and an anchor left from the old name
Uncensored local AI studio for Windows, Linux, and macOS. Zero-setup GUI for Image Generation, GGUF LLMs, Text to Speech & Speech to Text
At a glance
- What is it?
- techjarves/Uncensored-Local-Studio is an offline desktop studio bundling Stable Diffusion, llama.cpp, whisper.cpp and Kokoro behind one interface. Its own support matrix refuses most of the popular image architectures, and its Linux build can reject a valid model before reading it.
- Who is it for?
- This suits someone who already knows which checkpoint formats they have and wants four local inference paths behind one interface: the plain SD 1.5 and SDXL single-file case is well covered, with exact filenames and sizes listed. It does not suit anyone starting from a Flux or Wan workflow, since those are refused outright along with every companion file.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
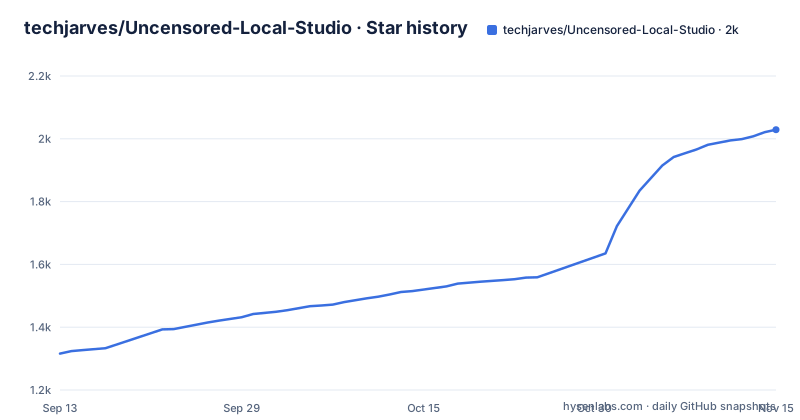
- techjarves/Uncensored-Local-Studio2,029 ★ · +713
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| techjarves/Uncensored-Local-Studio | 1.3k | 2k |
713 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The product was renamed and the old anchor survived
The repository is still called Uncensored-Local-Studio and its one-line description still opens with the word uncensored. The document inside has been renamed. The section heading reads What is Portable AI Studio?, the opening summary calls it a portable, zero-configuration local AI studio, and the banner points at a setup and demo video. The rename is not finished: the table of contents entry for that heading still jumps to `#what-is-uncensored-ai-studio`, and the same obsolete string sits in a raw anchor tag directly above the heading it no longer matches. One page, two names for the same section, and a working in-page link that survives only because the old anchor was never removed. Nothing else in the tree carries the old name. The root holds .gitattributes, .gitignore, LICENSE, README.md, app/, linux.sh, mac.sh, scripts/ and windows.bat.
Text and image workspaces cannot run at the same time
The two heavy engines are mutually exclusive by default, so the app does not exhaust system RAM or VRAM, and you switch between them inside the interface. Each workspace then gets its own directory, and the split shows up in the layout: image weights in `app/models/`, GGUF weights in `app/llm-models/`, whisper.cpp `.bin` files in `app/speech-models/`, and Kokoro spread across two folders, with manifests in `app/tts-models/` and assets in `app/tts-runtime/`. A small Qwen2.5 Coder starter model can be fetched from the Text Chat panel itself. Speech is the odd one out in the arrangement. Whisper runs as a localized `whisper-cli` process, and Kokoro runs through `kokoro-js` on the server side, so neither is a workspace you switch into.
Two of the five acceleration backends also change the model folder
Acceleration is picked by auto-detecting the hardware, and there are five targets: CUDA for Nvidia, ROCm for AMD, Vulkan for Intel, AMD and NVIDIA, Metal on macOS, and OpenVINO for Intel NPUs. Two of them change where files go. OpenVINO image models are Intel NPU only and belong in `app/openvino-models/`, fetched from the Model Manager after the OpenVINO setup has run. CoreML image models go into `app/models/` but need macOS on Apple Silicon and the CoreML setup path. Everything else reads from that same `app/models/` folder whatever the backend, which means one directory can hold checkpoints intended for several different hardware paths at once, with nothing in the filename saying which is which.
The largest entry in the support matrix is a refusal
The model table is the most useful page in the repository, and its widest row is a no. Flux, HiDream, Hunyuan, Wan, Qwen Image and Z-Image workflows are all marked unsupported, with the reason given plainly: they usually require separate diffusion, VAE and text encoder files, and are not one-click checkpoint loads here. Every companion file is refused on the same grounds. LoRA, ControlNet, VAE-only, text-encoder-only and diffusion-only files are all no, because companion files are not loaded as standalone image models. Single-file SD and SDXL GGUF checkpoints are marked Limited, and the limit is spelled out: only complete single-file checkpoints work. What is covered properly is the plain case, SD 1.5 and SDXL as `.safetensors` or `.ckpt`, with SDXL noted as needing more RAM and VRAM than SD 1.5.
A valid model can fail before it is loaded
One warning note does more work than the rest of the documentation combined, and it concerns Linux binaries rather than models. The release builds target Ubuntu 24.04-era systems and need `glibc 2.38+` plus `GLIBCXX_3.4.32+`. The failure described is the awkward kind: on an older Ubuntu or Debian VM, a model such as CyberRealistic may be entirely valid and the backend still fails before loading it. The model file is not the problem, the C library is. Two remedies are offered, upgrade the VM operating system or build the backend from source, which makes the documented escape hatch for an unsupported base image a compiler rather than a different download. Windows and macOS carry no equivalent requirement in the document, so the constraint is specific to the Linux build.
Six known-good checkpoints, and one labelled a test model
The Model Manager publishes six image models with exact filenames, types and approximate sizes, which makes this the most checkable table in the project. Juggernaut XL v9 Lightning and DreamShaper XL Lightning are SDXL checkpoints of 6.6 GB each. DreamShaper 8, CyberRealistic V8 and Rev Animated are SD 1.5 checkpoints between 2.0 GB and 2.1 GB, described as faster and lower-memory, realistic, and stylized respectively. The sixth, LCM DreamShaper OpenVINO at 2.7 GB, has its recommended use written out as an Intel Core Ultra NPU test model, a candid label for the one entry that will not run on most of the hardware the app otherwise targets. Weights arrive either by pasting a Hugging Face URL for the Model Manager to fetch or by dragging local files in.
Three launchers at the root, and no release to name them
The root of the repository is nine entries, and three of them are launchers: `windows.bat`, `linux.sh` and `mac.sh`, sitting beside `scripts/` and `app/`. There is no package.json at the top level even though the repository's primary language is JavaScript, which fits the promise that the runtime, Node.js included, is bundled rather than installed and that there are no global system changes. The project has no GitHub releases at all, so no tag, no release note and no version string is attached to any of those launchers. The folder listing in the documentation is even shorter: it opens with the project root and one child, `windows.bat`, and ends there, so the directory map a reader is given runs to a single line while the model folders described elsewhere add up to six.
No telemetry, and one JSON record per generated image
The privacy claim and the output gallery describe two different kinds of data. The claim is absolute: inferences run locally, with no internet, telemetry, cloud logging or API keys required. The feature list also promises a local output gallery that saves every generated image side by side with its prompt parameters and a metadata JSON file. Nothing leaves the machine, and the app also keeps a durable local record of what was prompted, in a plain format, one file per image, which is the sort of trace that matters more than any telemetry once images move between machines. A live performance monitor completes the picture, tracking CPU, RAM, GPU and VRAM utilization in real time inside the web UI, so the resource cost of a generation is visible while it is still running.
Editorial conclusion
This suits someone who already knows which checkpoint formats they have and wants four local inference paths behind one interface: the plain SD 1.5 and SDXL single-file case is well covered, with exact filenames and sizes listed. It does not suit anyone starting from a Flux or Wan workflow, since those are refused outright along with every companion file. Before installing, check two things the documentation makes explicit: that your Linux base image has glibc 2.38 and GLIBCXX_3.4.32 or newer, since the failure looks like a broken model file, and that the model you own is a complete single file rather than a diffusion, VAE and text encoder trio. With no releases published, there is also no version to pin, so keep your own copy of whatever build you install.
Frequently asked questions
What is Portable AI Studio?
It is an offline, zero-setup desktop studio for Windows, Linux and macOS that bundles four local capabilities: Stable Diffusion image generation, chat with GGUF language models through llama.cpp, Whisper speech-to-text through whisper.cpp, and Kokoro text-to-speech using the Kokoro-82M ONNX model. It is published under the MIT license from the techjarves/Uncensored-Local-Studio repository.
Which image models does Uncensored-Local-Studio support?
SD 1.5 and SDXL checkpoints as .safetensors or .ckpt files in app/models/, plus limited support for complete single-file SD and SDXL GGUF checkpoints. Flux, HiDream, Hunyuan, Wan, Qwen Image and Z-Image are not supported, and neither are LoRA, ControlNet, VAE-only, text-encoder-only or diffusion-only files.
Why does the Linux build fail to load a model that looks valid?
The Linux binaries are built for Ubuntu 24.04-era systems and require glibc 2.38+ and GLIBCXX_3.4.32+. On older Ubuntu or Debian virtual machines the backend can fail before loading a model such as CyberRealistic even though the file itself is fine, and the two documented remedies are upgrading the VM operating system or building the backend from source.
Does Portable AI Studio need an internet connection?
Inference runs locally with no internet, telemetry, cloud logging or API keys. Models are added either by pasting a Hugging Face URL for the Model Manager to download or by dragging local weight files into the app, and generated images are kept in a local gallery alongside their prompt parameters and a metadata JSON file.
How are the text and image workspaces separated in Portable AI Studio?
They are mutually exclusive by default so the app does not exhaust system RAM or VRAM, and you switch between them inside the interface. Image weights live in app/models/, GGUF weights in app/llm-models/, whisper.cpp models in app/speech-models/, and Kokoro manifests and assets in app/tts-models/ and app/tts-runtime/.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/techjarves-uncensored-local-studio)Star history chart for your README
[](https://hysenlabs.com/projects/techjarves-uncensored-local-studio)Was this useful?