organize: the pip package is organize-tool, the v3 migration note is still the headline, and the advanced example is commented out
The file management automation tool.
At a glance
- What is it?
- tfeldmann's organize is a Python command line tool that applies YAML rules to your files, positioned as an open source alternative to Hazel and File Juggler. Its safety story is simulation before action and trash instead of unlink. Its README, however, is still the announcement of a migration whose version shipped two years ago.
- Who is it for?
- Use it if your downloads and documents folders need repeatable rules and you would rather dry-run every action first, which the tool supports properly. Skip it if you need an admin interface or scheduled runs configured through a UI, since neither is in scope here.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
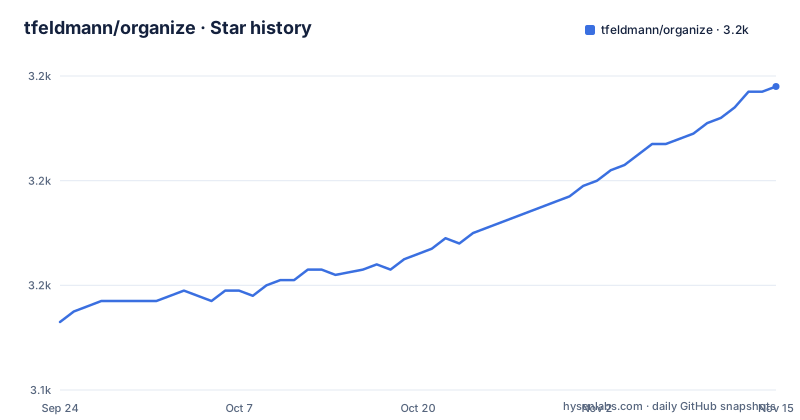
- tfeldmann/organize3,198 ★ · +45
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| tfeldmann/organize | 3.2k | 3.2k |
45 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three names for one thing: the repository, the package, the command
The naming is worth stating once because it is the first thing that trips people up.
The repository is organize. The distribution on PyPI is not: the readme says plainly that the package name is organize-tool, and the manifest confirms it with name = "organize-tool". The command you run afterwards is organize again, declared in the manifest as the script organize = "organize.cli:cli".
So the installation line is:
pip install -U organize-tooland the same command doubles as the updater, since the readme notes it can be used to move to the newest version. Checking that it worked is `organize --help`.
Everything else in the tool is reached through that one executable. The usage block in the readme lists ten entry points: run, sim, new, edit, check, debug, show, list, docs, and the version and help flags. The command line parser is docopt, which is a declared dependency, and that dependency is the reason the usage block reads the way it does.
The top of the readme is still the v3 migration announcement
The first section a reader meets is a version announcement rather than a description of what the tool does.
It announces that v3 is now available, that the new version should be much faster and fix a lot of bugs, and that it comes with some new actions, filters and options. It asks readers to reach out if they hit other bugs during the migration, and it links a changelog and a migration guide for moving from v2 to v3.
The problem is the arithmetic. That announcement is for v3, and the current version is 3.3.0, whose tag is dated 2024-11-25. The most recent commit is dated 2026-09-28. So the headline of the file is still the migration note from the release that started this line, and the two links it offers are the only pointers to anything newer.
The tutorial below it has the same problem in a smaller way. After the first rule, the readme promises that showing the text Found PDF! for each file will change soon. That promise is still in the file.
None of this breaks the tool. It does mean a reader has to work out the actual version from the manifest or the release list rather than from the readme.
Simulation comes before every action, and deletion goes to the trash
Two design decisions carry most of the risk in a tool that moves and deletes files, and both are visible in the documentation.
The first is that everything can be simulated before touching your files. The getting started walkthrough builds a rule that finds PDFs in your downloads, shows what it found with organize run, then adds a move action, then has you run organize sim to see what would happen without touching anything, and only then organizes run for real. The simulation step is not an optional extra in that flow, it is the step between writing a rule and trusting it.
The second is what happens on deletion. The second example rule is recursively delete all empty directories, and the action it ends in is a plain delete. Yet the dependency list includes send2trash with its nativelib extra, which is the component that hands deleted files to the platform trash rather than unlinking them.
So a rule whose filter is empty and whose action is delete is recoverable by emptying the trash rather than by restoring from a backup, which is a different guarantee from the conflict resolution options the feature list offers for moves and copies.
The advanced example is present in the file and switched off, with the author's home path in it
One of the most useful examples in the readme is not one of the examples you can see.
After the two simple rules there is an advanced section, and the whole block, from its summary tag through its prose and its YAML, sits inside an HTML comment in the file. The content describes placeholder variables, pluggable actions, limited recursion through subfolders, and other filesystems including FTP and ZIP, and then the rule it shows searches three levels deep in a documents folder and on an FTP server for PDF and DOCX files that have a created timestamp, asks for confirmation per file, moves them by extension and created month, appends a counter when the destination name is taken, and copies the results into a zip backup on the desktop.
Two details inside it are worth knowing. The move destination is built from placeholders, one for the uppercased extension and one for a created timestamp formatted as year and month, with the conflict behaviour named as rename_new. And the backup destination is an absolute path with a specific account name in it, which is the author's own machine rather than a neutral example.
The prose above the commented block points readers at the full documentation for the rest, which is where those features are actually documented.
Three dependencies are pinned exactly, and two of them carry a reason
The dependency list is written in an unusual style, and the pins are the interesting part.
Most requirements are ranges: arrow, docopt-ng, jinja2, natsort, pdfminer-six, platformdirs, pydantic, pyyaml, rich, simplematch. Three are pinned to one exact version. exifread is held at 2.3.2, the library that does the EXIF extraction, and markupsafe, in the documentation extra, is held at 2.0.1.
The third pin explains itself in a comment. mypy is held at 1.10.1 with a note that a recent version seems to break CI, and that the author had been using it without the constraint, where the resolver would give 1.13.0. That is a maintainer writing down a reason next to the number rather than leaving the next person to rediscover it.
One dependency is platform conditional. macos-tags is required only when sys_platform is darwin, which is what lets the tool read Finder tags on macOS without carrying the library elsewhere.
The other categories explain the feature list. docx2txt and pdfminer-six are where text from documents comes from, jinja2 is the template engine behind renames, and natsort is for the natural ordering of numbered filenames.
The container adds exiftool and poppler-utils, and copies the package twice
The image is built on python:3.12-slim and installs two external programs before any Python code runs.
The apt layer pulls exiftool and poppler-utils, which are not Python packages at all. That matters for the feature list: EXIF tag extraction and text extraction from PDFs both depend on system tools being present, so a container built without them would install cleanly and then quietly do less than the documentation promises.
The build itself pins its installer. The uv binary is copied from a versioned image, ghcr.io/astral-sh/uv:0.7.14, so the resolver used inside the container is fixed rather than whatever is current. Two sync passes run against the committed uv.lock with --locked, the first with --no-install-project and cache mounts, then the whole context is added and the second sync runs.
After that, the package directory is copied a second time with a separate COPY of ./organize into ./organize, on top of a tree that already contains it. The entrypoint then runs the module rather than the installed console script, as python -m organize, with --help as the default command, so running the image with no arguments prints usage and exits.
Two documentation systems and two framework entry scripts in the root
The root listing is worth reading as a description of how this project is organised.
Documentation is built twice over: mkdocs.yml and docs/ for the site published through Read the Docs, configured by .readthedocs.yml, and a separate changelog rendered under the project's own github.io address. A CHANGELOG.md file also sits in the root. So there are two documentation toolchains and two published locations, plus a source changelog.
Two script names sit beside the package: main.py and manage.py. The manifest declares no console script by either name; the entry point is organize = "organize.cli:cli", inside the organize/ directory. Nothing in the visible documentation explains what the two root scripts do, and manage.py in particular is the conventional name for a web framework's command line utility, which this tool is not.
Quality tooling is present in the same root: pyrightconfig.json for type checking, .pre-commit-config.yaml for hooks, .editorconfig, uv.lock committed for reproducible resolution, and a tests/ directory.
Editorial conclusion
Use it if your downloads and documents folders need repeatable rules and you would rather dry-run every action first, which the tool supports properly. Skip it if you need an admin interface or scheduled runs configured through a UI, since neither is in scope here. Before you rely on a version, check the release list against your commit: the manifest says 3.3.0 and the newest tag is v3.3.0 from 2024-11-25, while commits have continued to 2026-09-28, so pip is not installing the newest code in the repository.
Frequently asked questions
What does organize mean?
In this repository, organize is a command line file management automation tool written in Python, published as the package organize-tool and invoked as the command organize. It is described as an open-source alternative to Hazel on macOS and File Juggler on Windows, applying YAML rules that match files and then move, rename, copy or delete them.
how to use organize your music
That question is about music software rather than this tool, and nothing here addresses it. What this repository does document is a first rule in five steps: run organize new, run organize edit, write a rule with locations, filters and actions, run organize run to see what matched, and run organize sim to preview a move before performing it.
Is it organize or organise?
The project uses the z spelling throughout: the repository, the command, the pyproject name and every example. Nothing in the documentation addresses the spelling question itself. The user documentation is published at organize.readthedocs.io, with the changelog at a separate site under the project's github.io address.
What should I remove first when decluttering?
The readme offers use cases rather than an order: sorting and tagging pictures into folder structures from EXIF data, sorting and renaming PDF invoices from their content, removing incomplete downloads from the Downloads folder, cleaning unused files off the Desktop, and removing duplicates to free disk space. Its example rules move invoice and receipt PDFs into a shopping folder and recursively delete empty directories.
organize vs manage
Nothing in the repository compares the two words. What it states is scope: safe moving, renaming, copying and deleting with conflict resolution options, fast duplicate detection, EXIF tag extraction, categorisation from text extracted out of PDF and DOCX files, a template engine, and inline Python and shell commands usable as both filters and actions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tfeldmann-organize)Star history chart for your README
[](https://hysenlabs.com/projects/tfeldmann-organize)Was this useful?