Claude Code Mastery argues that a hook is not the same as an instruction
The complete guide to Claude Code: CLAUDE.md, hooks, skills, MCP servers, and commands
At a glance
- What is it?
- A guide repository covering the configuration surfaces of Claude Code, from the global instructions file to MCP servers, custom commands, hooks and skills. Its central claim is that instructions are suggestions while hooks are enforcement, and it opens by marking itself obsolete in favour of a successor kit.
- Who is it for?
- This suits someone who has noticed that writing a rule in an instructions file does not reliably stop an assistant from breaking it, because the exit-code mechanism described here is the part that actually changes behaviour. It suits you less if you want a maintained toolkit rather than an argument, since the repository labels itself obsolete and points elsewhere.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Shell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
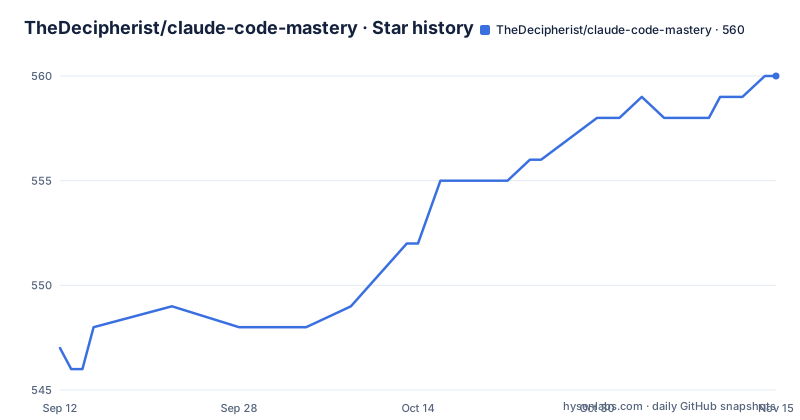
- TheDecipherist/claude-code-mastery560 ★ · +13
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| TheDecipherist/claude-code-mastery | 547 | 560 |
13 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository opens by declaring itself obsolete
The first thing the readme does is tell you not to use it.
The heading marks this as version 2 and labels it obsolete, with a line asking you to use a newer starter kit instead. Links are given to three later versions, two of them hosted as articles and one as a published site.
So what remains here is the second version of the guide, kept in place and cross-linked rather than deleted. That is worth knowing before you clone it, and it is arguably useful precisely because it is frozen: the configuration surfaces it describes have not moved, and the argument it makes about enforcement does not depend on which version number it was.
Two other products are advertised at the top and both live elsewhere. One is a standalone package on the language package registry, positioned as a development partner that insists every feature starts with documentation and every fix starts with an audit, with twenty-one modes reached through one command. The other is a starter kit that claims to bundle everything from all five guide versions into a project template, listing sixteen slash commands, hook enforcement, a database wrapper, monitoring and three layers of security.
So the repository is best read as the reasoning behind those products rather than as the current product.
An instruction can be weighed, a hook cannot
The argument the guide is built around is a distinction between two mechanisms that look similar from the outside.
A rule written in the global instructions file goes through the model. It is parsed, weighed against whatever else is in context, and followed or not followed depending on how that weighing lands. The guide's own diagram spells out the uncertainty:
CLAUDE.md saying "don't edit .env"
  → Parsed by LLM
  → Weighed against other context
  → Maybe followed

PreToolUse hook blocking .env edits
  → Always runs
  → Returns exit code 2
  → Operation blocked. Period.
The third line of the first chain is the whole claim. Maybe.
The second chain has no equivalent line, because a hook that runs before a tool does not consult the model at all. It is a program that either returns an exit code or does not, and the outcome does not depend on how the request was phrased or what else was in the conversation.
That distinction only matters for rules you cannot afford to have followed sometimes. A style preference that gets ignored occasionally costs nothing. A rule about secrets does not, which is why the example used throughout is denying access to environment files.
A community member's comment is quoted in support of the point, describing a hook that blocks access to secret files several times a week and concluding that the model does not follow the instructions file rules rigorously.
Exit code two is the entire mechanism
Three exit codes are documented, and only one of them does anything interesting.
Zero means success and allows the operation to proceed. One means an error, and the interesting detail is that this one is shown to the user only, not to the model. Two means block the operation, with standard error fed back to the model.
So the useful case is specific: returning two refuses the tool call and hands the reason back as text the model can read and respond to. The model learns it was blocked and why, rather than the tool simply failing.
That is the difference between a guardrail and a lock. A guardrail explains, and the next attempt can account for it. A lock just refuses, and the model is left guessing.
The distinction between codes one and two is the subtle part, because both are non-zero failures from the program's point of view. Only one of them stops the operation, and only one of them tells the model anything.
This is why hook scripts are ordinary programs you write yourself rather than configuration you toggle. The behaviour is entirely determined by what your script prints and what it returns, which is why the repository ships example hooks rather than a list of switches to set.
The hooks are written in two languages
Four example hooks are listed, each mapped to the point at which it runs.
One runs before a tool is used and blocks access to environment files. One runs before a tool is used and blocks destructive shell commands. One runs at the end of a turn and applies quality gates. One runs after a tool has edited something and invokes formatters.
The mapping matters more than the individual scripts. Two of them guard the moment before something happens, one guards the end of a response, and one cleans up after a change. Those are the three useful places to put automation: before, after, and at a boundary.
The languages differ, which tells you something about the cost. The secrets hook is written in Python while the others are shell scripts, and the stated prerequisites are a Python runtime for the Python hooks and a JSON processor for the shell hooks to parse configuration with.
So installing this is not a single dependency. You need Python, you need a JSON tool on your path, and you need to mark the shell scripts executable, because a hook that is not executable simply does not run and you will spend time wondering why nothing is being blocked.
A settings template wires the scripts to their trigger points, and it is the piece that turns four loose files into a working configuration.
Installation copies files into a directory you already use
The install procedure is a sequence of file copies into your user configuration directory, and it assumes you have nothing there yet.
Hooks go into a hooks directory and are made executable. A settings template is copied over your configuration file. Skills are copied into a skills directory. The global instructions template is copied and then edited in your editor.
# Copy the settings template (review and customize first!)
cp templates/settings.json ~/.claude/settings.json

# Copy skills
mkdir -p ~/.claude/skills
cp -r skills/* ~/.claude/skills/
The consequential line is that copy of the settings file. If you already have one, this overwrites it, and the installation notes acknowledge this by telling you that in that case you should merge the hooks section by hand instead.
That caveat appears in the step-by-step version but not in the shorter quick start, which is the version most people copy. It is the one thing worth reading twice before running anything.
Verification is done from inside the assistant itself: start it, then run the command that lists loaded hooks and the command that lists loaded skills. Both being populated is the only confirmation that a copy actually took effect.
The global instructions file and the project-level one are separate templates, matching the guide's split between what should apply everywhere and what should apply to one repository.
The performance figure is cited to a specific study
The guide's most quotable claim is a percentage, and it comes with a link.
Mixing topics in a single conversation is reported as causing a thirty-nine percent performance drop, attributed to a paper on multi-turn conversations.
Two further sources are listed alongside it. One is described as recall decreasing as context grows. The other reports a link between early misalignment and later failure, where a two percent early divergence is associated with a forty percent failure rate.
The second of those is the more interesting claim to sit with, because it is not about length at all. It is about direction. A conversation that starts down a slightly wrong path compounds, which is an argument for starting fresh rather than an argument for writing more carefully.
From those three, the guide states a rule in one line: one task, one chat.
That rule has an operational cost worth acknowledging, since it means abandoning a conversation rather than steering it, and abandoning a conversation means losing whatever context was built up in it. The guide does not discuss that tradeoff, so it is worth deciding for yourself how much accumulated context is worth more than a clean start.
The rest of the guide's structure follows the same pattern of one claim per chapter: a global instructions file that applies everywhere, scaffolding rules, MCP servers for external tools, live documentation access, custom commands, and then skills and hooks as the enforcement layer.
Wanted contributions are listed as empty checkboxes
The contribution section is short and unusually concrete about what is missing.
The process is the usual one: fork, branch, add, submit. What follows is a list of unchecked boxes, and those boxes are more informative than the process above them.
The first asks for more language-specific hooks, naming Go, Rust and Ruby. The existing hooks are Python and shell, so the gap is language coverage for projects written in something else.
The second asks for more skills, naming code review, documentation and testing as examples. The third asks for framework-specific scaffolding templates, which implies the current project-level template is generic.
The fourth asks for MCP server configuration examples, which is the most interesting of the four. The guide devotes a whole part to MCP servers and treats them as a capability to understand, but the repository appears to contain no worked configurations for any particular server.
So the gap is between the guide explaining the mechanism and the repository demonstrating it. Anyone adding one would be filling a real hole rather than adding a duplicate.
The repository itself holds the guide, the templates, the hooks, a skills directory, a commands directory, a directory of documentation and a directory of images.
Editorial conclusion
This suits someone who has noticed that writing a rule in an instructions file does not reliably stop an assistant from breaking it, because the exit-code mechanism described here is the part that actually changes behaviour. It suits you less if you want a maintained toolkit rather than an argument, since the repository labels itself obsolete and points elsewhere. Before copying anything, read the settings template rather than overwriting your existing configuration, since the install steps assume a machine that has none, and remember that a hook blocking a tool is a blunt instrument that will occasionally stop work you wanted done.
Frequently asked questions
What does Claude Code actually do?
It is a coding assistant configured through several surfaces: a global instructions file for rules that apply everywhere, a project-level instructions file, MCP servers for external tools, custom slash commands, hooks that run at defined points around tool calls, and skills that package reusable expertise.
Is the claude-code-mastery repository still current?
It labels itself obsolete at the top and points to a newer starter kit, with links to three later versions of the guide hosted elsewhere. The repository is best read as the reasoning behind those successor products rather than as the current recommended setup.
Why does the guide insist on hooks instead of instructions?
An instruction in a file is parsed by the model and weighed against other context, so it may or may not be followed. A hook runs before the tool, does not consult the model, and returns an exit code, so the operation is blocked regardless of how the request was phrased.
What do the hook exit codes mean?
Zero allows the operation. One is an error shown only to the user, not to the model. Two blocks the operation and feeds standard error back to the model, so it learns what happened and why rather than just failing.
What do I need installed before using the hooks in this guide?
The assistant itself, Python for the Python hooks, and a JSON processor for the shell hooks to parse configuration with. You also need to mark the shell scripts executable, since a hook that is not executable does not run at all.
Where does the thirty-nine percent figure in the guide come from?
It is reported as the performance drop from mixing topics in a single conversation, attributed to a paper on multi-turn conversations. Two related sources are also cited, one on recall decreasing as context grows and one on early misalignment compounding into later failure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thedecipherist-claude-code-mastery)Star history chart for your README
[](https://hysenlabs.com/projects/thedecipherist-claude-code-mastery)Was this useful?