3DUNDERWORLD-SLS decodes a projected grid pattern to reconstruct a point cloud on CPU or CUDA
A structured light scanner
At a glance
- What is it?
- The 3DUNDERWORLD structured light scanner is a C++ library and demo binary that turns a series of images lit by patterned light into a point cloud. The pattern carries the addressing: each cell of the projected grid has a unique sequence, so a point can be decoded from the two camera views. Reconstruction exists in two implementations, and the build picks which one to compile by looking for CUDA.
- Who is it for?
- This repository fits a research or teaching context that needs a readable reference implementation of structured light reconstruction, since the pipeline is split into two named components and the CPU path builds anywhere. It does not fit a product that needs to drive a camera, because acquisition is explicitly not implemented and only interfaces are provided.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 142 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
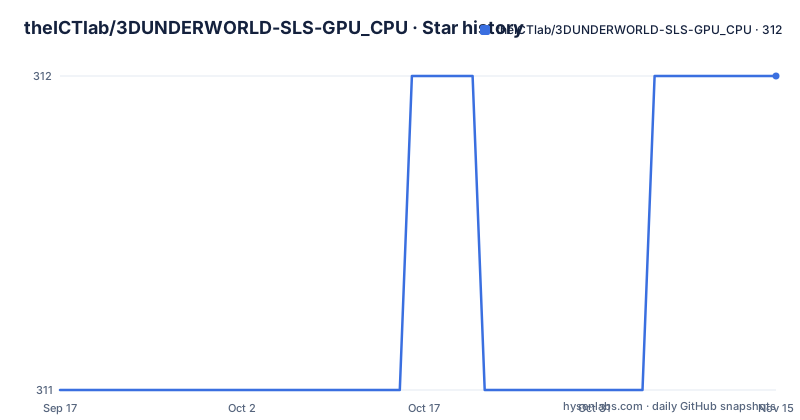
- theICTlab/3DUNDERWORLD-SLS-GPU_CPU312 ★ · +1
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| theICTlab/3DUNDERWORLD-SLS-GPU_CPU | 311 | 312 |
1 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The projected pattern carries the address of each point
The working principle is described in one paragraph, and it is worth understanding because everything else follows from it.
Patterns are projected onto the object in a grid manner. Each cell in that grid carries a unique sequence, so the projector is not illuminating uniformly, it is writing a code across the surface. A camera image then reads back that code, and the corresponding point is extracted by decoding the sequences from both images.
Two consequences follow. First, this is not photogrammetry: the reconstruction depends on a projector and a calibration, not only on overlapping photographs. Second, the two views are not redundant. Each contributes half of the decode, which is why the binary takes two camera folders and two calibration files.
The grid scheme also explains the data layout. Each cell has its own identifiable sequence, so points come back indexed by cell rather than as an unstructured cloud, and the intermediate representation can therefore be grouped before anything is merged.
That is the reason for the bucket stage described next: the per-cell work is done once, independently, and only the combining step needs global information.
Two components: ImageProcessor makes buckets, Reconstructor merges them
The library has two main building blocks, and the boundary between them is clean.
`ImageProcessor` takes images, projector parameters, and camera calibration parameters as input, and produces `Buckets`. `Reconstructor` then combines all the buckets to generate the point cloud.
So the split is per-view processing versus global merging, with the bucket as the hand-off format. Because each bucket corresponds to a cell of the projected grid, the processor stage can be parallelised and the reconstructor stage can see everything at once.
Both classes are exposed as a library, not only as the demo binary, and the repository says so directly: the project provides libraries that can be integrated into other projects, with a CPU example application and a GPU example application included in the source tree.
That separation is what makes the two reconstructor implementations possible. Since merging is isolated behind one class, the GPU version is a replacement for that class rather than a fork of the pipeline.
The same split is also the extension point. Anything that can produce buckets fits in front, and anything that can consume buckets fits behind, which is the natural shape for a reconstruction library that has to accommodate capture hardware it does not control.
The build compiles one reconstructor or two depending on whether CUDA is found
The build is a plain CMake out-of-source build, and the sequence is four commands.
git clone --recursive https://github.com/theICTlab/3DUNDERWORLD-SLS-GPU_CPU.git
cd 3DUNDERWORLD-SLS-GPU_CPU
mkdir build
cd build
cmake ..
make
The recursive clone matters, since the project depends on external components fetched as submodules.
The CUDA decision is automatic and stated as such. If CUDA is detected on the system, the `ENABLE_CUDA` flag is set to on by default and both the CPU and GPU constructors are created in the binary folder. If it is not detected, only the CPU constructor is generated.
So the output directory tells you which build you got. Two constructors means the CUDA path compiled, one means it silently fell back.
To force the CPU-only path, configure with `cmake .. -DENABLE_CUDA=off`. That is the setting to use on a build machine or a continuous integration runner without a GPU, and it is also the setting to verify that your fallback path works.
The declared requirements are OpenCV2, CUDA at version 6.0 or newer, and glm for the maths. A version floor of 6.0 for the toolkit is a reminder that the CUDA integration predates the current toolkit generations.
The output flag is documented twice and the two descriptions disagree
The demo binary takes eight parameters, in long and short form, and one of them is described inconsistently.
The camera inputs are two image folders, with calibration file paths alongside them for the left and right cameras. The remaining flags set the output location, the image file suffix, the projector width, and the height.
The inconsistency is in the output flag. Its entry in the usage text describes it as an output folder, while the note underneath states that it is the name and location of the output file, either ply or obj, with an example path ending in a ply file.
The note is the authoritative one, and you can confirm it from the demo command itself, which passes a path ending in a file name rather than a directory. A user following the usage text alone will create a directory where the program expects to write a file, or write a file where it expects a directory, depending on the version.
Two other operational details are worth carrying across. The camera configuration files are XML produced by the OpenCV calibration tool and contain intrinsic and extrinsic parameters, so you need a calibration step before any reconstruction. And most runtime output goes to a log file with a fixed name in the working directory, which you can follow live with a tail command in a second terminal.
Camera acquisition is the missing piece, and the project asks for it
The known issues section is short and leads with the gap that matters most.
Camera acquisition is not implemented, and the stated reason is that there is no good API for cameras. Interfaces are provided instead, and the project explicitly invites you to implement your own camera class and send a pull request.
So the library covers everything from images to point cloud and stops on either side of the capture device. For a lab with a fixed rig and a scripted capture step, that is a perfectly workable arrangement, and the interface existing means the adapter is a bounded piece of work rather than a redesign.
For anyone expecting a scanner application, it is a different story. There is no live preview, no capture trigger, and no device handling, and the example data in the repository is the substitute.
That second known issue is the one that affects everyone rather than only integrators. Because the example data files are committed to the repository, its size is around 300MB, and the documentation warns that a clone may take a while.
For a research codebase that is a reasonable trade, since the data is what makes the project reproducible. For a dependency, it is a cost paid at every fresh checkout.
Tests, documentation, and coverage are all configuration flags
Everything optional in the build is a CMake flag, and the three of them follow the same pattern.
Tests use the Google Test framework and are off unless you ask for them:
cmake .. -DGTEST=ON
make
make test
Google Test itself is downloaded and compiled during the build rather than being vendored, so enabling tests adds a network dependency to the configure-and-build step.
Documentation is Doxygen, enabled with a separate flag, and generated by a `make doc` target into a doc directory inside the build tree.
Coverage uses lcov and needs both flags, with tests and coverage turned on together, and a `make coverage` target that writes a report into a coverage directory in the build path.
The pattern is worth copying: no flag means no extra work, and the artefact lands somewhere predictable relative to the build directory rather than in the source tree.
The practical consequence for a fork is that the default build is the minimum one. Anything you rely on beyond the demo binary has to be switched on explicitly.
The demo run wires calibration paths straight into the binary
The quick start for the library path is a worked example on the bundled data, and every argument is spelled out.
You create a separate directory for it, make an output directory inside that, and copy the left and right camera folders out of the repository data directory. Then you configure, build, and run the binary with the camera folders pointed at one dataset inside each.
./bin/SLS --leftcam=./leftCam/dataset1 --rightcam=./rightCam/dataset1 --leftconfig=./leftCam/calib/output/calib.xml --rightconfig=./rightCam/calib/output/calib.xml --output=./Output/output.ply --format=jpg --width=1024 --height=768The command is informative about the data layout. Each camera folder contains a dataset directory and a calibration directory whose output holds the XML file, so the capture tool writes into the same tree the scanner reads.
Two of the flags are about the capture rig rather than the algorithm. The image format flag sets the suffix of the image files, given as jpg in the example. The width and height are the projector's dimensions, and they are declared as unsigned longs, which is consistent with a projector geometry that must be known exactly.
Notice also that the copy step exists rather than a relative path, which suggests the binary is happier with directories it can own than with paths that climb out of the working directory.
One release from 2016, a decade of commits, and a mandatory citation
The release history is a single tag, and it is old.
Version 4.0, described as the CPU and GPU implementation of the reconstructor, was tagged on 2016-06-01. The last push to the default branch, which is `dev` rather than `main`, is dated 2026-06-26.
So the tree is being worked on while the published version has not moved in a decade. For a research implementation with no package manager entry and no binary distribution, that is not unusual, and the demo binaries plus the committed data mean the build is the install.
Attribution spans two eras of the same lab. Version 4 credits one lead developer and two researchers; versions 1 through 3.2 credit a different lead developer with the same second researcher. Both are the Immersive and Creative Technologies Lab at Concordia University, and the project sits inside a wider 3DUNDERWORLD effort with its own site.
The licence is LGPL, which suits a library others embed.
The last thing to know before using any of it in writing is that the citation is not optional. The documentation states that any resulting publication must cite the work, and provides two entries: a 2014 preprint for the earlier system and a journal article whose journal field is still listed as to be announced.
Editorial conclusion
This repository fits a research or teaching context that needs a readable reference implementation of structured light reconstruction, since the pipeline is split into two named components and the CPU path builds anywhere. It does not fit a product that needs to drive a camera, because acquisition is explicitly not implemented and only interfaces are provided. Before building, clone with submodules and expect OpenCV, glm, and CUDA present or absent, and note that the example images are committed so the clone is large, and that the code carries a mandatory citation requirement.
Frequently asked questions
What does the 3DUNDERWORLD structured light scanner reconstruct?
It reconstructs a point cloud from a series of images lit by patterned light. Patterns are projected onto the object in a grid where each cell has a unique sequence, and the corresponding points are extracted by decoding those sequences from the two camera images.
What are the dependencies for building 3DUNDERWORLD-SLS?
OpenCV2, CUDA at version 6.0 or newer, and glm. The repository must be cloned recursively because components are fetched as submodules, and the build is CMake with an out-of-source build directory.
How do I enable the tests in 3DUNDERWORLD-SLS?
Configure with cmake .. -DGTEST=ON, then run make and make test. Google Test is downloaded and compiled during the build rather than vendored, so tests are off by default and enabling them adds a network step.
Does 3DUNDERWORLD-SLS capture images from a camera?
No. Camera acquisition is not implemented because there is no good API for cameras, and the project provides interfaces instead and invites you to implement your own camera class as a pull request. Everything from images onward is covered, and the bundled example data stands in for capture.
How does the GPU path get selected at build time?
Automatically. If CUDA is detected, the ENABLE_CUDA flag defaults to on and both the CPU and GPU constructors are produced in the binary folder; otherwise only the CPU constructor is built. Configure with cmake .. -DENABLE_CUDA=off to force the CPU-only path.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/theictlab-3dunderworld-sls-gpu-cpu)Star history chart for your README
[](https://hysenlabs.com/projects/theictlab-3dunderworld-sls-gpu-cpu)Was this useful?