Text Grab: four OCR modes, a Calc Pane, and one feature set that needs the Store build
Use OCR in Windows quickly and easily with Text Grab. With optional background process and notifications.
At a glance
- What is it?
- TheJoeFin/Text-Grab is a MIT licensed Windows OCR app that runs entirely on device. Its own instructions split the product in two: features built on the Windows OCR API that run on Windows 10, and Windows AI features that need a Copilot+ PC and the Microsoft Store install.
- Who is it for?
- Text Grab earns a place on a Windows workstation where text keeps ending up inside images, video frames, PDFs and applications where selection is disabled, and its on-device OCR means it works without a network path or a per-use bill. Take the Store install if you want the Windows AI features, because those need a Copilot+ PC and its Neural Processing Unit, and a GitHub Releases or package manager install is the one to pick otherwise.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
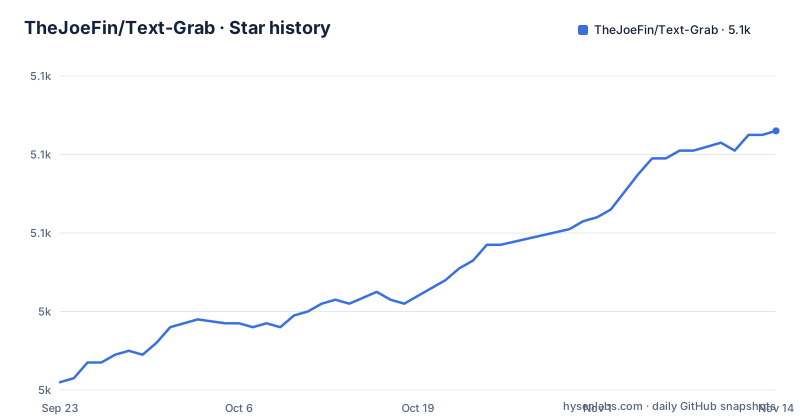
Star history
- TheJoeFin/Text-Grab5,086 ★ · +64
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| TheJoeFin/Text-Grab | 5k | 5.1k |
64 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Local text capture with several engines
Text Grab is a C# Windows application that can capture text using the Windows OCR API, Windows AI on supported Copilot+ PCs, Tesseract, or direct UI Automation where accessible text is available. The README says recognition runs locally. Windows OCR requires Windows 10 or later; Windows AI requires Windows 11 on a Copilot+ PC and a Microsoft Store installation. Tesseract language data may need to be downloaded.
Local recognition does not mean every subsequent action is offline: opening a web search or sending text to another application can disclose the captured text. Review the actions you enable for sensitive material. Full-Screen Grab is also cited as the basis of PowerToys Text Extractor.
Four modes are promised and the fourth heading stops at Qui
The README organises the product around four modes and the first three are described in full. Full-Screen Mode selects a region of the screen and copies the recognized text to the clipboard. Grab Frame Mode gives you a movable OCR window you can park over part of the display. The Edit Text Window turns whatever was grabbed into clean, usable content in plain text, spreadsheet style or markdown.
A single click copies one word because the API returns word boxes
In Full-Screen Mode you can click once and get a single word, and the reason is mechanical rather than clever: the Windows OCR API draws a bounding box around each recognized word, so a click lands on one word's region. Selecting an area works the same way, and the recognized text goes to the clipboard. When you click or drag over an area with no text, the Text Grab window stays active rather than dismissing, so a misclick costs you a second attempt instead of a restart. There are three ways out: press Escape, right-click and choose Cancel, or press Alt+F4. Grab Frame Mode can use the configured capture method, and its advice is geometric: adjust the size and position of the frame to improve accuracy, then grab text by searching for it, clicking a word border, or pressing the Grab button.
The Edit Text Window is where OCR output becomes structured data
The cleanup window is the part that decides whether a capture is useful, and it works as a list of transformations rather than a text box. Output can be flattened to a single line, switched between UPPERCASE, lowercase and Titlecase, stripped of spaces and empty lines, and deduplicated line by line. Reserved characters such as spaces, forward slashes and percent signs can be replaced in one action, and patterns can pull values out by shape, covering phone numbers, email addresses and customer patterns. Search work includes find and replace, extracting regular expressions and launching URLs. Structure work covers converting stacked data into table format, transposing captured table data when the OCR read the right content in the wrong orientation, and saving the result as delimited data for another tool. Three workflow helpers reach outside the window: listing files and folders in a chosen directory, watching the clipboard for changes, and copying text from every image in a folder.
The Calc Pane evaluates expressions on the line above
Inside the Edit Text Window sits a Calc Pane that works line by line, so numbers captured from an image can be checked without moving them to another program. It covers basic arithmetic with `+`, `-`, `*`, `/`, `%` and exponents, functions including `sin`, `cos`, `tan`, `sqrt`, `abs` and `log`, and variables and constants such as `x = 10`, `pi`, `e` and `tau`. Unit conversion is written the way you would say it, `5 miles to km` or `100 fahrenheit to celsius`, and date math reads the same way with expressions such as `today + 5 days` or a comparison of two dates in weeks. Aggregates cover sum, average, median, count, min, max and product. It also summarizes numeric values taken from spreadsheet selections, copies every calculation result out at once, and can hide or show errors, which matters when the OCR brought in something that is not a number.
Two official install channels and two community ones
There are four ways to install, and which one you pick decides which features you get. The official pair is the Microsoft Store and the GitHub Releases page, and the community pair is a package manager:
scoop install text-grab
choco install text-grab
The Microsoft Store link is the one the README points at when it describes the Copilot+ PC requirement, and the AI features are tied to that install. So the choice is not cosmetic. Someone on a Copilot+ machine who installs from GitHub Releases or from scoop gets the Windows OCR API features and not the Neural Processing Unit path. Everything else, the four modes, the Edit Text Window and the Calc Pane, sits on the Windows 10 requirement and does not depend on which channel delivered the binary.
Three build routes, and the SDK is pinned to 10.0.100
Building from source starts with Git, and the repository pins the .NET SDK exactly:
winget install git.git
git clone https://github.com/TheJoeFin/Text-Grab.git
`global.json` pins SDK `10.0.100`. The .NET SDK or VS Code route is three commands, `dotnet restore Text-Grab.sln`, `dotnet build Text-Grab\Text-Grab.csproj` and `dotnet test Tests\Tests.csproj`. The Visual Studio route is heavier and wants Visual Studio 2022 or 2026 with the Universal Windows Platform, .NET desktop and .NET cross-platform development workloads, plus Windows 10 SDK `10.0.22621.0`, with `Text-Grab-Package` set as the startup project and the CPU target set to `x64` or `ARM64`. There is also `build-unpackaged.ps1` at the root for a build outside the packaged form, and the UI automation inventory, the sign-off command, runner requirements and opt-in lanes live in `UiTests/README.md` rather than in the main README.
A C# app with .claude, GOALS and BUILT-WITH.md at the root
The root listing explains how the project is run as much as the code does. `Text-Grab/` holds the application, `Text-Grab-Package/` is the packaging project Visual Studio starts, `Text-Grab.sln` ties them together, and `Tests/`, `Tests.Core/`, `Tests.Core.Windows/` and `UiTests/` sit alongside as test surfaces. Then there are the files a small desktop app rarely has: a `.claude/` directory committed at the root, a `GOALS` file with no extension at all, `BUILT-WITH.md`, and a `ThirdPartyNotices/` directory next to the MIT `LICENSE`. `BUILT-WITH.md` and the third party notices together suggest that dependency provenance is tracked deliberately, which matters for an app redistributed through a store and through package managers at the same time. There is no changelog file in the root; the release titles carry the feature summary instead, with v4.15.0 named for Smart Patterns, Description, Text to Speech, HDR and Settings Polish, v4.16.0-beta1 cut on 2026-09-19 as a beta, and v4.16.0 released on 2026-10-27, the same day as the last push.
Editorial conclusion
Text Grab earns a place on a Windows workstation where text keeps ending up inside images, video frames, PDFs and applications where selection is disabled, and its on-device OCR means it works without a network path or a per-use bill. Take the Store install if you want the Windows AI features, because those need a Copilot+ PC and its Neural Processing Unit, and a GitHub Releases or package manager install is the one to pick otherwise. Read the requirements list before deploying it across machines rather than after, since the difference between the two feature sets is the hardware and the install channel, not a setting. For automation, start from the modes and the Calc Pane, which evaluate expressions line by line next to the text you just captured, and check `UiTests/README.md` for the sign-off command and runner requirements before wiring any of it into a release pipeline. MIT covers the code and `ThirdPartyNotices/` covers what came with it, which is the short answer on licensing.
Frequently asked questions
What is Text Grab?
Text Grab is a MIT licensed Windows application that captures text with OCR from images, video, PDFs and parts of applications where text cannot be selected. All OCR runs on the device, with no internet connection, no cloud service and no per-use cost, and the result goes to the clipboard or straight into an editor.
How do you use Text Grab day to day?
Launch it from the taskbar, open a specific mode from the command line, or enable the background process so global hotkeys work anywhere in Windows. From there you choose a mode: Full-Screen for a region, Grab Frame for a movable window, or the Edit Text Window to clean up what you grabbed.
How do I grab text from the screen with Text Grab?
Use Full-Screen Mode to select a region and copy the recognized text to the clipboard. Clicking once copies a single word, because the Windows OCR API draws a bounding box around each recognized word, and if the area has no text the window stays active so you can try again. Press Escape, choose Cancel from the right-click menu, or press Alt+F4 to exit.
Can Text Grab pull text out of an image?
Yes. You can open a supported file, run it through the OCR engine and send the result to the clipboard or into the editor, and the workflow helpers include copying text from every image in a chosen folder. Windows 10 or later is required for the features that use the Windows OCR API.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thejoefin-text-grab)Star history chart for your README
[](https://hysenlabs.com/projects/thejoefin-text-grab)Was this useful?