TinaCMS: GraphQL over Markdown in your repo, on a workspace that wants Node 22
TinaCMS is the leading open-source headless CMS that supports Markdown and Visual Editing. Your content is stored in your own GitHub repo.
At a glance
- What is it?
- TinaCMS is an Apache-2.0 headless CMS that stores Markdown, MDX, JSON and YAML in your own GitHub repo and serves it through a GraphQL API, with visual editing available only if you opt in. The repository is a pnpm and turbo monorepo whose release machinery tells you more about how it ships than its short readme does.
- Who is it for?
- TinaCMS fits a team that already keeps content in a Git repository and wants an editing layer plus a query API over the same files, and, if it plans to work inside the monorepo, that can commit to Node 22 or 24 with pnpm 11. It does not fit a team that wants a database backed admin panel, or one that expects visual editing to be on by default, since live preview is optional and opt-in.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
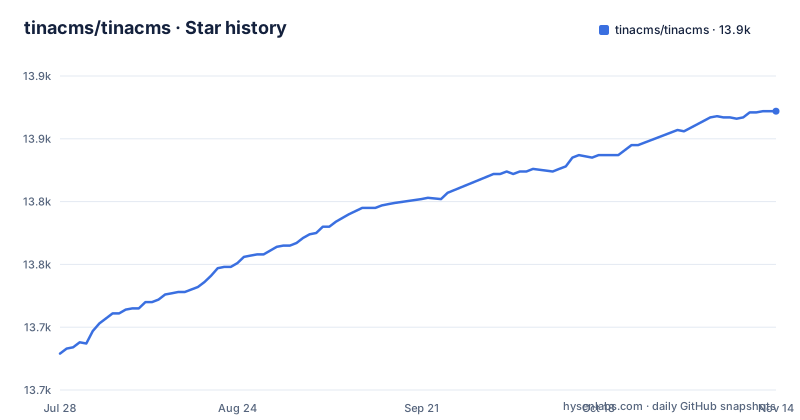
- tinacms/tinacms13,872 ★ · +193
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| tinacms/tinacms | 13.7k | 13.9k |
193 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Live preview is opt-in, so without it this is a form over Markdown files
The feature that distinguishes Tina from a plain content layer is not on by default. The readme states that Tina offers a live preview that is optional and opt-in, and that it exists to make editing Markdown files intuitive for less technical people. Everything else in the surface area is unconditional. Tina is a headless content management system supporting Markdown, MDX, JSON, YAML and more, and it ships a GraphQL API that returns content through dotted paths such as `post.author.firstName`. The API layer supports statically generated and server side rendered pages, so a build step and a request time renderer are both first class targets, and it supports references between documents, which is what lets one entry point at another. The practical consequence is a two step evaluation: turn on the preview to see the editing experience, because a build without it gives you content and an API but not the visual layer.
Your GitHub repo is the datastore, and the readme names no credential for it
The repository description makes the storage decision explicit: your content is stored in your own GitHub repo, and the stated vision is to be the world-leading CMS with Git support that developers love. That removes an entire class of work, since there is no separate database to provision and content changes arrive as commits with history attached. It also moves the hard part to the edges. Anything that writes content needs a path into your repository, and the readme names no credential, token, or permission model for that write, leaving it to the documentation site and the tinacms/tinacms discussions.
One scaffolding command, and engines that exclude most CI images
The only setup path written down in the readme is a single command that creates a TinaCMS starter site:
npx create-tina-app@latestThere is also a demo site at https://app.tina.io/quickstart on TinaCloud if you would rather look before you scaffold. What the readme does not show is what working inside the repository itself demands, and the root package.json answers that. The workspace is private, named root, at version 0.0.0, with workspaces globs for packages/@tinacms/*, examples/*/* and packages/[^@]*. The engines block is narrow:
"engines": {
		"node": "22.x || 24.x",
		"npm": "11.x",
		"pnpm": ">=11"
	},
Node 20 is not on the list, npm must be 11.x, and pnpm is expected at 11 or newer. A build image for this workspace pinned to an older Node does not meet that engines block.
Publishing runs across the workspace with git checks switched off
Releases are driven by changesets. The version script runs `pnpm exec changeset version`, tagging runs `pnpm exec changeset tag`, and `push-tags` pulls and pushes the follow tags. The publish scripts are where the governance detail sits:
"publish": "pnpm publish -r --no-git-checks --access public && pnpm exec changeset tag",
"publish:beta": "pnpm publish -r --tag beta --no-git-checks --access public",
"publish:dev": "pnpm publish -r --tag dev --no-git-checks --access public",
Three things follow. Publishing is recursive, so one command touches every package in the workspace rather than the one you changed. The git checks are disabled on all three paths, including beta and dev, so a dirty working tree is not a barrier to shipping. And the beta and dev tags are how pre-release builds move, which is what to install when you need a fix before it reaches the main tag. Two further scripts are dedicated to a Tina lock artifact, diff-tina-lock and update-tina-lock, run across the workspace with concurrency set to one and only in packages that define them.
Coverage is measured only under packages/v4 while the build covers everything
The scripts show two different scopes sitting next to each other. The build target and the test target both run through turbo with a filter that covers every package under the packages directory, so a green local run tells you about the whole tree. Coverage does not: its filter is narrowed to the packages/v4 directory and nothing else.
That single difference is worth pausing on, because a v4 package layout sitting inside packages while the published tinacms package sits at 3.15.1 means the coverage number describes a subset rather than the release you install. If you judge project health from it, remember which slice produced it. There is a companion local check as well: test:packages runs vitest in verbose reporter mode and then a package lint that shells out to publint with the strict flag, so passing locally includes a packaging check and not only unit tests. End to end work lives in playwright/tina-playwright, driven by npx playwright test with a ui variant for interactive debugging, and there is a .codecov.yml at the repository root for the coverage side of that pipeline.
Six example apps span the frameworks, each a separate workspace package
The examples directory is organised by framework rather than by feature: astro, hugo, next, react, shared and web-components, and the workspace glob examples/*/* pulls packages two levels below examples/ into the workspace, while examples/ carries its own AGENTS.md and CLAUDE.md alongside the framework folders. That breadth is the honest answer to framework coverage, spanning static site generators, a React based framework, a component format, and Hugo for a non JavaScript stack. The trade is that breadth is not depth. Each example is a starting point for a specific pairing, and nothing in the repository listing suggests a shared conformance suite that runs the same content assertions across all six. If your production target is one of these frameworks, read the example for that framework and treat the others as evidence the API is not tied to a single renderer. For anything outside the list, you are the first adopter for that combination.
The changelog section is commented out, so release notes live in changesets
The readme contains a changelog block that is not live: the section heading `## Changelog` and its link to ./CHANGELOG.md sit inside an HTML comment, so the page readers land on says nothing about what changed. Meanwhile CHANGELOG.md is present at the repository root and a .changeset/ directory drives versioning. Recent releases show why the tooling matters: [email protected] and @tinacms/[email protected] were both published on 2026-11-01, seconds apart, because a single change set in a monorepo moves several packages at once. The repository is not archived and the last push to main is 2026-10-30, so the cadence is current. The consequence for anyone tracking releases is that the readme will not tell you what landed. Watch the tagged releases or the changeset files, and expect to read several version bumps for what you may experience as one change.
The same maintainers own the CMS, the hosted service, and the marketing site
The maintainer block names nine people and three more as part time contributors. Matt Wicks is listed as product owner of both TinaCMS and TinaCloud, Gert Marx as product owner of the tina.io website, and Adam Cogan as key stakeholder, with Jack Pettit, Eli Kent, Brook Jeynes, Ben Neoh, Josh Berman and Ivan Gaiduk in the main group and Kelly Davis, Jeff See and Scott Gallant part time, alongside a link to the SSW team. Read as a governance fact, that means the open source editor, the hosted TinaCloud service, and the documentation you are sent to all sit with the same organisation. It also means the roadmap is a single one: priorities are published at tina.io/roadmap/, and questions go to the GitHub Discussions, the community Discord, or the project's Twitter account.
Editorial conclusion
TinaCMS fits a team that already keeps content in a Git repository and wants an editing layer plus a query API over the same files, and, if it plans to work inside the monorepo, that can commit to Node 22 or 24 with pnpm 11. It does not fit a team that wants a database backed admin panel, or one that expects visual editing to be on by default, since live preview is optional and opt-in. Before you start, check the engines block in the root package.json against your build images, decide whether a starter site from create-tina-app is enough or you want to work inside the monorepo, and remember that the release trains ship as changesets across several packages at once, so a version bump in tinacms can arrive alongside bumps in other packages such as @tinacms/mdx.
Frequently asked questions
Is TinaCMS free?
The repository is licensed under Apache-2.0 and Tina is described as an open-source headless CMS whose content is stored in your own GitHub repo. The readme says nothing about pricing for TinaCloud.
What is Tina Cloud?
It is the hosted side of the project. The readme points to a demo site at https://app.tina.io/quickstart on TinaCloud for trying the CMS without scaffolding, and Matt Wicks is named as product owner of both TinaCMS and TinaCloud, so the hosted service and the open source editor are the same product team.
how to install tinacms
The one install path given is the scaffolding command npx create-tina-app@latest, which creates a starter site, or trying the demo site on TinaCloud. Working on the repository itself means a pnpm workspace whose engines block requires Node 22.x or 24.x, npm 11.x and pnpm 11 or newer.
what is tinacms
Tina is a headless content management system with support for Markdown, MDX, JSON, YAML and more, and it comes with a GraphQL API where content is queried with dotted paths such as post.author.firstName. It supports statically generated and server side rendered pages, and supports references between documents.
how to use tinacms
Content is edited as files in your own repository and read back through the GraphQL API, with references between documents available across entries. The live preview that makes Markdown editing intuitive for less technical people is optional and opt-in, so it has to be enabled rather than assumed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tinacms-tinacms)Star history chart for your README
[](https://hysenlabs.com/projects/tinacms-tinacms)Was this useful?