PanWatch: nine agents in the headline, four analyst roles in the reference, and a market calendar that expires
PanWatch is a self-hosted AI stock-monitoring assistant integrating TradingAgents multi-agent investment decision-making, with real-time monitoring of A-shares, Hong Kong and US stocks, position management, intelligent analysis, and multi-channel push notifications.
At a glance
- What is it?
- PanWatch is a self-hosted stock monitor for three markets, deployed as a single Docker container with a named data volume, and it leans on another project's multi-agent research code for its deep analysis. Two things in it are worth reading closely. The agent count is stated twice and does not match, and the exchange calendar is a hand-bundled annual dataset whose expiry blocks scheduled runs rather than degrading them.
- Who is it for?
- This is a tool for your own watchlist and your own broker accounts, and the design decisions that matter are the ones about restraint. Nobody has to ship a default password, the scheduled agents refuse to run on days the bundled calendar does not know about, the alerts have cooldowns and daily limits, and the test suite will not send a real notification unless you pass a flag.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
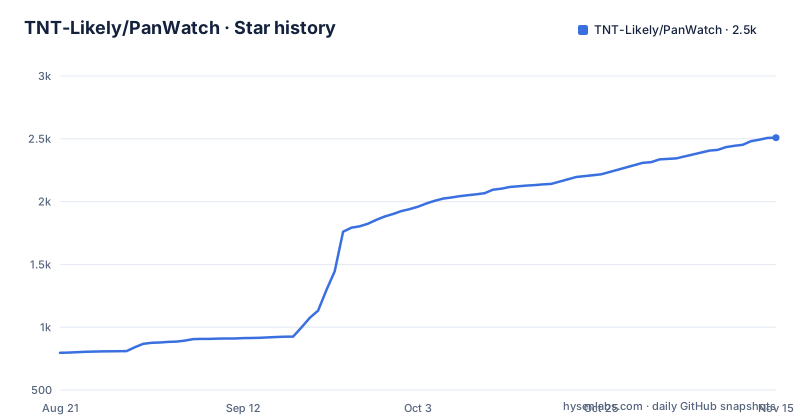
Star history
- TNT-Likely/PanWatch2,509 ★ · +1,713
| Repository | 2026-08-21 | 2026-11-15 |
|---|---|---|
| TNT-Likely/PanWatch | 796 | 2.5k |
1,713 Stars in the last 86 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The headline says nine agents, the reference says four analyst roles
The summary line at the top of the page describes a chain that starts from a portfolio holding, hands it to a nine-agent research team, follows a bull and bear debate and a risk review, and delivers a portfolio manager decision memo plus the complete reasoning trail to a messaging app within three to five minutes. Then the reference section describes the same feature with smaller numbers.
There, the instruction is to select a brain icon beside a holding to start deep analysis, and the pipeline is described as four analyst roles feeding a bull and bear debate, then a risk review, and then a portfolio manager decision. Four analysts plus two debate sides plus a risk reviewer plus a decision maker is eight positions, not nine, and the page never reconciles the two counts or explains what the ninth is. The mind icon as the entry point and the trajectory trail available in the app and through your configured channels are consistent between the two sections; only the headcount differs.
The timing claim is qualified in the same reference section. Three to five minutes appears as a headline promise, and the reference adds that runtime and cost depend on the selected models and configuration. Since every analyst role and every debate turn is a model call, and the default example configuration points at one specific hosted model, the wall clock number is a property of a configuration rather than of the software. It is worth treating it that way: pick a model, run one holding, and read the actual cost before you schedule anything.
The research code itself is somebody else's project. Deep analysis is built on TradingAgents, linked from the top of the page to its own repository, and the container build treats it as a special case, which the next section covers.
TradingAgents is fetched with git at image build time, and git is then discarded
The container recipe is a three stage build, and one of its stages exists only to get another project in. The Python stage installs git with the comment that git is used only for building TradingAgents and is not carried into the final image along with its Perl dependencies. So the agent framework your decisions are derived from arrives from a version control checkout during the build, not from a package index with a fixed version and a hash.
That is a deliberate trade. A source checkout can be pinned to a commit and carries its own history and dependencies, which a pure wheel does not, and the image is described as deeply adapted to a self-developed server stack elsewhere in this project's lineage. The cost is that the build needs network access and that what ends up inside the image depends on what the build fetched that day, unless the build pins the reference.
The stages themselves are laid out in the order you would expect. The frontend builds first on an Alpine Node image, then the Python dependencies are installed into a staging prefix, then a final runtime image is assembled. The same Python and Debian versions are used for the build stage and the runtime stage, and the comment says why: to keep the ABI of native wheels consistent between the two. That is the kind of detail that prevents a class of import error nobody can reproduce, and it is written down in the file rather than left to the base image tags.
The analysis paths are documented separately from the page itself. A deep analysis flowchart and a backend architecture document both live in the repository, linked from the reference section, which is the place to look if the four analyst roles in the reference section need more than a sentence each.
The market calendar is bundled per year, and running out of it blocks the agents
This is the most operationally interesting paragraph in the documentation, and it is about how a scheduled agent behaves when it does not know what day it is.
Published 2026 closures and half-days are bundled into the repository. On startup the service warms only the previous 30 days and the next 90, rather than downloading full history. A weekday with no published data shows a pending calendar and blocks automatic execution, and the bundled annual data must be updated for the next year.
So the failure mode is chosen deliberately. A missing calendar does not cause an agent to run against a closed exchange, and it does not cause a silent skip either. It stops the run. Given today falls inside the bundled year, that behaviour is invisible until it matters, and then it will look like the schedulers have simply gone quiet rather than like an error, which is why it is worth knowing before January rather than after.
The timezone design around it is stated with equal care. Opening and session times are shown in your browser timezone, while trade dates and market status use each exchange's local date, so a status strip comparing all three exchanges over the next fourteen dates is mixing two clocks on purpose. The page even spells out the case that confuses people: Beijing Saturday morning can still be New York Friday after close. A non-trading day shows closed, and a completed trading day shows market closed, which is two different labels for two different facts.
The scheduler itself is configured separately. Cron and interval settings for the agents are unchanged by any of this, and execution and schedule previews share the same calendar filter, so the gate is applied at run time rather than by rewriting your cron entry.
First startup downloads a browser into the volume you are mounting
The one-line install is a single container with a named volume and one published port:
docker run -d \
  --name panwatch \
  --restart unless-stopped \
  -p 8000:8000 \
  -v panwatch_data:/app/data \
  sunxiao0721/panwatch:latest
The compose file on the page declares the same image, the same port mapping, the same named volume and the same restart policy, so the two routes are equivalent, and either way you open port 8000 and create your login credentials yourself. There is no default account to change, which is worth saying because that is the usual first thing to look for in a self-hosted service.
The startup caveat is about the browser. The image includes the system dependencies Playwright needs, but Chromium's headless shell for screenshots is downloaded on first startup into the mounted volume, at a default path under the data directory, and that download needs network access and can take a few minutes. If you do not need browser features such as screenshots, an environment variable skips the installation.
That last detail is why the image is larger than a stock monitor needs to be. The runtime stage installs timezone data for the zoneinfo module, Noto CJK fonts because the screenshots include Chinese candlestick charts, two Pango libraries for the font layout that PDF export needs, and then a list of Chromium libraries taken from Playwright's own native dependency manifest for its pinned version. The comment also says GTK and EGL are deliberately not installed, because screenshots use Chromium's bundled software rendering.
One requirements file serves both a checkout and the image, and sed rewrites it
There are three requirements files and they are not redundant. The top level one includes the runtime file and adds the test runner, with a comment saying it is runtime dependencies plus the test runner for local development and CI. A separate file exists for OpenTelemetry. The runtime file is the one that matters for the interesting part.
The runtime requirements file contains editable installs, marked with a leading dash and an equals sign, so that a developer can work against a checkout of the local packages. The image cannot do that, because an editable install points at source that the image does not contain. So the build rewrites the file on the fly: it strips the editable prefix into a temporary copy, installs from that with bytecode compilation turned off, and installs into a staging prefix so the dependencies can be copied into the final image rather than inherited from the build stage.
Two details in those two flags are worth naming. Turning off bytecode compilation keeps compiled cache files out of the image, which is a size and staleness decision. Installing into a prefix is what makes a multi stage image work at all, since it lets the final stage copy a self-contained dependency tree instead of inheriting a build toolchain.
The local packages themselves are copied into the build context before that install runs, which is what the editable lines in the requirements file are pointing at. The project version is passed into the build as an argument with a default of dev, and a version file sits at the top of the repository, so the same number that appears in the release tags is injected rather than read from the package metadata at build time.
pyproject.toml configures pytest and nothing else, and live sends need a flag
This repository is not packaged as a library, and the manifest proves it. The pyproject file contains no project table, no name, no dependencies. It contains a pytest configuration block and four comments above it explaining how to run the tests.
Those comments are the most useful part. To run everything, a pytest invocation over the tests directory. To run one file, the same with a specific test file named, and the file they choose is the notification policy test. And to actually send notifications, a flag that is off by default, with a note in Chinese saying notifications are not sent by default.
That is a small design decision with a large safety margin. A test suite for a service whose job includes pushing messages to your phone could easily leave you with test alerts at three in the morning, and this one makes the live path opt in per run. A fourth comment points at a shell script for installing a pre-push hook, so the safety is meant to be enforced locally as well as in CI.
The top level layout matches an application rather than a package: a server entry point, a source tree, a frontend tree, a local packages tree, a prompts directory, scripts, tests, docs, a makefile, a build script, and the three requirements files. The prompts directory is worth noting on its own, because it means the agent instructions are data files checked into the repository rather than strings assembled in code, which is why there is a version file and an argument for it.
The image lives under an individual account, tagged latest, with no digest offered
The install command pulls from an individual Docker Hub account rather than from the organisation that owns the repository, and it asks for the latest tag. The releases are numbered, three of them in the last three days at the time of writing, from 0.17.0 through 0.17.2, and the default branch was pushed the same day the newest release was tagged.
So there is a real release cadence here, and the documentation still points at a rolling tag. That is a normal choice for a self-hosted convenience image, and it is also the one line in the quick start with no version in it. If you care which build you are running, the two things you can pin are a digest and a specific tag, and the page offers neither; the compose variant has the same latest tag.
The example environment file is where the rest of the configuration surface shows through. The default AI base URL points at a hosted Chinese model provider's OpenAI-compatible endpoint and the default model is from that same provider, with an API key placeholder, and the setup instructions name OpenAI, that provider, DeepSeek and Ollama as the options. So the provider layer is genuinely swappable and the shipped example is one choice among four.
There is also a full context budget block, commented out: a summary token ceiling, a total ceiling, a soft limit and a hard limit, a temperature, and a count of messages to keep recent. Those numbers describe a real compression stage that exists but is off by default. And two operational settings ship commented: an HTTP proxy on a local port, noted as possibly needed to reach Telegram, and a certificate file path for corporate proxies, empty meaning disabled.
Six hand-maintained documents, and a scheduler whose timezone is never named
The repository carries three readme files and three contributing files, one set each for English and Simplified Chinese, at the top level rather than generated from one source. There is also a separate security policy. That is six hand-synchronised documents for a project shipping releases every few days, and it is the kind of duplication that shows up as a translation lagging a week behind.
The default schedule in the example environment file is the other loose end worth naming. The daily report cron is set to half past three in the afternoon on weekdays, which lines up with the close of the mainland session, and the comment above it explains the cron field order in Chinese. What the page does not say is what timezone the scheduler evaluates that expression in. Timezone data is installed in the image for the zoneinfo module, which means the code is timezone aware, but the cron default still has an implied market clock that the documentation leaves unnamed.
It is a small gap with a real failure mode, because the daily report is the one workflow that runs on a timer with no human present, and an eight hour offset would move it from the close of one session to the middle of another. If you are setting this up, set the container timezone explicitly rather than inheriting the host's.
Everything else about the alerting side is designed for restraint, which is where a stock monitor earns trust. Price alerts combine conditions with and or logic and carry cooldowns, daily limits, expiration and a notification channel per alert. Notifications go to Telegram, WeCom, DingTalk, Feishu, Bark or a webhook. Paper fills require an open session for that stock's own market rather than any market being open, paper notifications follow each exchange's local clock including half days and daylight saving changes, and an alert set to fire all day still requires a trading day.
Editorial conclusion
This is a tool for your own watchlist and your own broker accounts, and the design decisions that matter are the ones about restraint. Nobody has to ship a default password, the scheduled agents refuse to run on days the bundled calendar does not know about, the alerts have cooldowns and daily limits, and the test suite will not send a real notification unless you pass a flag. That is a project that has thought about what happens when a scheduled agent wakes up at three in the morning. Four things to check before you point it at real money. The agent count is stated two different ways and the headline timing is qualified in the reference section, so measure cost on one holding before you schedule it daily. The calendar data is bundled per year and an unpublished weekday blocks automatic execution rather than skipping quietly, so your agents will go quiet in January unless a release ships next year's closures. The container image is published under an individual account with a rolling latest tag, so pin a digest if you care what is running. And the exchange comparison mixes browser timezone for session times with exchange local dates for trading status, which is the right call and also the kind of thing that surprises you at a half day. For research, paper trading and notification workflows on your own accounts, the feature list is real. For anything that places trades, nothing in this page does that, and the simulation is explicitly a simulation.
Frequently asked questions
What does PanWatch do?
It monitors A-shares, Hong Kong and U.S. stocks, manages holdings and profit and loss across multiple brokerage accounts, and runs scheduled pre-market, intraday and closing workflows on eligible exchange trading days. Deep analysis on a holding produces a decision memo with the reasoning trail.
How long does a PanWatch deep analysis take?
The summary line says within three to five minutes from holding to memo. The reference section qualifies it, stating that runtime and cost depend on the selected models and configuration, and it describes four analyst roles feeding a bull and bear debate, a risk review and a portfolio manager decision.
Does PanWatch need internet access on first startup?
For the browser, yes. Chromium's headless shell for screenshots is downloaded on first startup into the mounted volume and can take a few minutes. Setting PLAYWRIGHT_SKIP_BROWSER_INSTALL=1 skips it if you do not need screenshots or other browser features.
Which market calendars does PanWatch use?
Published 2026 closures and half-days are bundled locally, and startup warms only the previous 30 and next 90 days. A weekday with no published data shows a pending calendar and blocks automatic execution, so the bundled annual data has to be updated for the following year.
Where can PanWatch send its notifications?
Telegram, WeCom, DingTalk, Feishu, Bark, or a webhook. The example environment file also carries a commented HTTP proxy setting, noted as possibly needed to reach Telegram, and a certificate file option for corporate proxy environments.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tnt-likely-panwatch)Star history chart for your README
[](https://hysenlabs.com/projects/tnt-likely-panwatch)Was this useful?