Typesense's default branch is v31 and its build has both Bazel and CMake
Open Source alternative to Algolia + Pinecone and an Easier-to-Use alternative to ElasticSearch ⚡ 🔍 ✨ Fast, typo tolerant, in-memory fuzzy Search Engine for building delightful search experiences
At a glance
- What is it?
- Typesense is a GPL-licensed, typo-tolerant search engine written in C++ and shipped as a single binary with no runtime dependencies, with keyword retrieval, vector and hybrid search, conversational search, CLIP image search and Whisper voice search on the same engine. Two repository facts set expectations: the default branch is named v31 while releases sit on 30.x and 29.x, and the build is described by both a Bazel workspace and a CMake tree.
- Who is it for?
- Typesense fits a team that wants host-your-own search with typo tolerance, faceting and grouping out of the box, and would rather add vector or hybrid search to an existing keyword engine than run a separate vector database. It does not fit a team that wants the engine's own benchmarks read as a promise, since the published figures come from a 4 vCPU server, and it does not fit a build you have not chosen a build system for.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
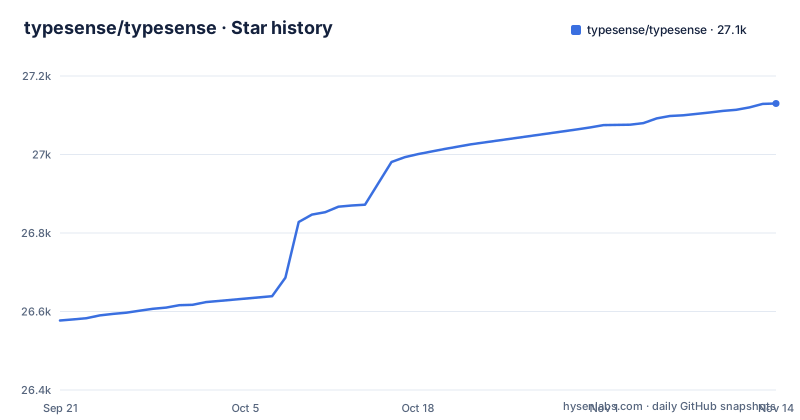
- typesense/typesense27,130 ★ · +553
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| typesense/typesense | 26.6k | 27.1k |
553 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default branch is v31, and the releases are on 30 and 29
The repository's default branch is named `v31`, which is the first thing to know before you read a version number anywhere in this project. The release list, meanwhile, holds v30.2 and v29.1, both dated 2026-04-19 and published about a minute apart, with v30.1 before them on 2026-01-29.
Two conclusions follow. The maintenance lines are the 29 and 30 series, with parallel patch releases on the same day, and the branch you land on when you open the repository is the next one rather than the current one. The last push was on 2026-10-30 and the repository is not archived, so all of this is current rather than abandoned.
For an adopter the practical step is to name the line you are deploying rather than tracking the default. For a contributor it means the feature work happens on a branch ahead of what ships, which is where the roadmap lives too, since the roadmap is a public board whose first column also explains how the project prioritises and what its release cadence is.
A Bazel workspace and a CMake tree in the same root
The top level describes the build twice over. There is a Bazel setup, with `BUILD`, `WORKSPACE`, `.bazelrc` and a pinned `.bazelversion`, and there is `CMakeLists.txt` with a `cmake/` directory beside it. Both are in the repository root, alongside a `bazel/` directory.
Then there are four build scripts with distinct jobs: `build.sh`, `docker-build.sh`, `ci_build.sh` and `ci_build_v2.sh`, plus `publish_release.sh` and a `debian-pkg/` directory for packaging. That last detail says releases ship as distribution packages as well as images and binaries.
Two smaller files tell you how the code is tested and built under sanitizers. There is a `tsan.supp`, a ThreadSanitizer suppression file, which is a sign that a race detector runs somewhere in the process, and the repository also carries `DESIGN.md`, `SHOWCASE.md`, `TODO.md`, a `SECURITY.md`, `api_tests/`, `benchmark/`, `test/` and `tests/`.
So a contributor has one decision before writing any code: which build system, and which of the two CI scripts is the one CI runs.
The published benchmark is 2.2 million recipes in 900MB
Typesense publishes its own benchmarks, and the numbers are specific enough to be useful and narrow enough to be careful with. On a dataset of 2.2 million recipes, consisting of recipe names and ingredients, the engine took about 900MB of RAM when indexed, took 3.6 minutes to index all 2.2 million records, and on a server with 4 vCPUs handled a concurrency of 104 concurrent search queries per second with an average search processing time of 11ms.
Those are the project's numbers on its own hardware. The feature list makes the related claim about latency, that the engine is built in C++ and architected for low-latency searches under 50ms.
The live demos are the other half of the evidence, and they are datasets rather than benchmarks: a 32 million song dataset from MusicBrainz, 28 million books from OpenLibrary, 2 million recipes, a million Git commit messages from the Linux Kernel, a spellchecker with 333 thousand English words, and semantic and hybrid search over 300 thousand Hacker News comments.
The shape to take from that is capacity per unit of hardware, not a throughput promise for your dataset.
The retrieval features are the core, and they are specific
The feature list is long because search engines are wide, but the items that describe the engine rather than a model are the ones to read. Typo tolerance is out of the box. Ranking is tunable. Results sort dynamically on a chosen field at query time, which is what a price sort needs. Faceting and filtering let a user drill down and refine, and grouping and distinct show more variety by grouping similar results.
Two of those are unusual for this kind of engine. Federated search queries multiple collections, described as indices, in a single HTTP request. And JOINs connect one or more collections through common reference fields and join them at query time, which the README frames as modelling SQL-like relationships elegantly.
On top of that sit the operator features: synonyms so a search for one word returns the others, curation and merchandising to boost particular records to a fixed position, geo search around a latitude and longitude or inside a bounding box, and scoped API keys that only allow access to certain records, which the README names as the mechanism for multi-tenant applications.
The design consequence is that a lot of what you would normally build in your application is data modelling inside the engine, which is convenient until the reference fields outlive the feature.
Five model-backed features, five different dependencies
The second half of the feature list is where the project's direction is, and each item names a model or a provider. Vector search indexes embeddings from your own machine learning models and does nearest-neighbour search, for similarity, semantic, visual search and recommendations. Semantic and hybrid search can generate embeddings inside Typesense with built-in models such as S-BERT and E-5, or use the OpenAI or PaLM APIs, for both the query and the indexed data, so you send JSON in and get semantic plus keyword search out.
Conversational search is described as built-in RAG: you send a question and the response is a fully-formed sentence based on the data you have indexed, framed as ChatGPT over your own data. Natural language search sits next to it, with LLM-powered intent detection converting free-form phrases into structured filters, sorts and queries.
Then two modalities. Image search uses the CLIP model, either for text descriptions of image contents or for similarity. Voice search captures a query as a recording, and Typesense transcribes it with the Whisper model before searching.
So the honest reading of that list is five mechanisms and five dependencies. Each one has a model and, in some cases, an external API, and a deployment that turns on conversational search has made a decision about where its data goes.
Raft clustering and an upgrade that means swapping a binary
The operational claims are the ones a team will actually feel. Typesense describes its distribution as Raft-based, which it says sets up a distributed cluster that is highly available. And the upgrade story is stated as a single action: as new versions come out, upgrading is as simple as swapping out the binary and restarting Typesense.
The third claim is the one that shapes everything else: no runtime dependencies, because Typesense is a single binary you can run locally or in production with a single command. There is no database server to provision, no message broker, nothing to version alongside it.
That simplicity is the pitch, and it is real, but it moves the cost rather than removing it. Availability depends on how many nodes you run and how you replace a binary across them, which is a cluster operation rather than a feature. And a self-contained binary has no runtime dependencies to fall back on, which is the other side of the same trade.
GPL-3.0, a hosted cloud next door, and a public roadmap
The licence is GPL-3.0 with `LICENSE.txt` at the repository root, and the project's own framing in the README is positional: an Open Source Algolia alternative and an easier-to-use ElasticSearch alternative, positioned against both hosted search and a general-purpose search cluster.
Alongside the open source engine there is a hosted cloud at cloud.typesense.org, and the support surface is unusually complete for a project of this size: the website and its documentation, a public roadmap, a Slack community, Community Threads at threads.typesense.org, and a Twitter account. The feature list closes by inviting you to search the issue tracker for an existing request and comment with your use case, or open a new one, and says the roadmap is prioritised from that feedback.
For a reader evaluating it, the order of the day is: read the roadmap board to see where the next major is going, since the default branch is already the next version, and read the benchmark numbers as the project's own rather than as a measurement of your workload.
Editorial conclusion
Typesense fits a team that wants host-your-own search with typo tolerance, faceting and grouping out of the box, and would rather add vector or hybrid search to an existing keyword engine than run a separate vector database. It does not fit a team that wants the engine's own benchmarks read as a promise, since the published figures come from a 4 vCPU server, and it does not fit a build you have not chosen a build system for. Before adopting, pick the branch deliberately, because the default is v31 while the released lines are 30.x and 29.x, and read the model-backed features as a list of dependencies, since each names a model and a provider.
Frequently asked questions
What is Typesense used for?
It is a fast, typo-tolerant search engine for building search experiences, described as an Open Source Algolia alternative and an easier-to-use ElasticSearch alternative. Beyond keyword search it adds faceting, grouping, sorting, geo search, synonyms, JOINs, scoped API keys and, with models, vector, semantic, conversational, image and voice search.
Is Typesense free to use?
The source is released under the GPL-3.0 licence, with LICENSE.txt at the repository root, and the engine has no runtime dependencies because it is a single binary you run locally or in production with a single command. There is also a hosted cloud option at cloud.typesense.org alongside the open source project.
How do I install Typesense?
The README describes Typesense as a single binary with no runtime dependencies that you run locally or in production with a single command, and links an install section in its documentation along with the Docker Hub tags. Building from source is covered separately in the repository, which carries both Bazel and CMake configuration.
Is Typesense a vector database?
It is a general search engine that also stores and searches vectors. The vector search feature lets you index embeddings from your own models and run nearest-neighbour queries, and semantic or hybrid search can generate those embeddings inside the engine with built-in models like S-BERT and E-5 or through the OpenAI and PaLM APIs.
What is a facet in Typesense?
Faceting is one of the feature-list entries described as faceting and filtering, which lets a user drill down and refine results. It sits alongside dynamic sorting on a chosen field at query time, grouping and distinct, and curation that boosts particular records to a fixed position.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/typesense-typesense)Star history chart for your README
[](https://hysenlabs.com/projects/typesense-typesense)Was this useful?