book-to-skill distills a book into SKILL.md, and your host decides where it lands
GitHub describes it as Turn any technical book PDF into a Claude Code skill , ready to study, reference, and use while you work.. The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- A Python extractor pulls clean text out of a document, then the agent you are already running writes the skill from it. Knowing which half fails tells you whether the generated chapters are worth trusting.
- Who is it for?
- Judge this as a converter plus a convention rather than a parser you can trust blind. The extractor half is ordinary Python behind per-format extras, and the half that writes your frameworks, decision rules, and anti-patterns is your own agent, so output quality tracks the model doing the writing.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
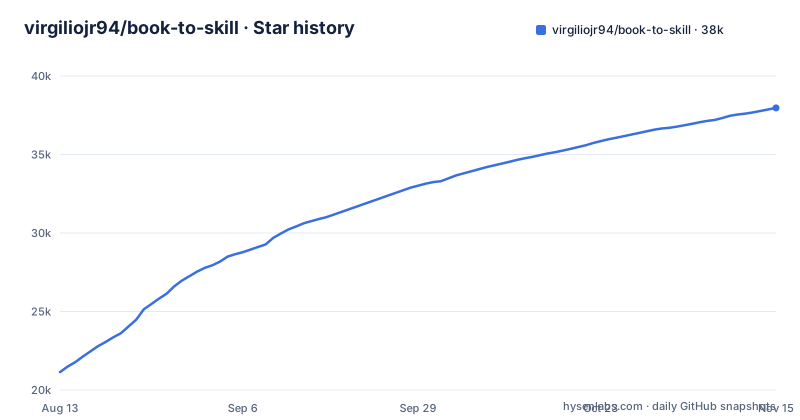
- virgiliojr94/book-to-skill37,970 ★ · +16,829
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| virgiliojr94/book-to-skill | 21.1k | 38k |
16,829 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Python package stops at clean text and the agent writes the skill
book-to-skill is two halves that never meet inside one process. The first is a deterministic Python extractor that turns a document into clean text plus metadata. The second is a spec-driven generator, and there the agent you are already running reads SKILL.md and does the structuring: frameworks, decision rules, anti-patterns, and one file per chapter. The practical consequence is that installing the package and pointing it at a file does not by itself leave a finished skill on disk. No chapter file, no glossary, and nothing in your skills directory appears until the generation half runs inside an agent host. If you evaluate this in a plain terminal or in CI, you are evaluating the extractor, not the deliverable you came for.
One skill, five hosts, and five different destination paths
A conversion writes to the user-level cross-agent directory `~/.agents/skills/<slug>/` so Copilot CLI, Amp, Codex, OpenCode, and OpenClaw can find one shared copy, and OpenCode also reads its own managed root at `~/.config/opencode/skills/<slug>/`. Claude Code does not sit on that path, so the converter attempts a symlink at `~/.claude/skills/<slug>/` and counts it as done only when a read-back confirms it; an unconfirmed link is reported in the run output instead of passing quietly. Hermes Agent partitions personal skills by category and never scans the cross-agent root, so the same run lands in `/skills/<category>/<slug>/`. OpenClaw picks a different destination again when `OPENCLAW_STATE_DIR` points somewhere other than the default, using the active state's `skills/` root. Which directory you end up with is a property of your host, not of your input file, and project-local, OpenCode-managed, and OpenClaw-managed destinations stay available when you ask for them explicitly.
Format support is bought one extra at a time
Packaging puts every parser behind an optional extra: `html` pulls trafilatura, `epub` pulls ebooklib and beautifulsoup4, `docx` pulls python-docx, `rtf` pulls striprtf, `technical` pulls docling, and `pdf` pulls pdf-inspector, pypdf, and pdfminer.six together. An `all` extra installs the entire list. The floor is Python 3.9, matching the py39 lint target, and pdf-inspector is the only dependency carrying a version range, held at >=1.15,<2. Release v1.2.0 from June 2026 is the one described as the installable package plus multilingual chapter detection, and v1.4.0 landed in August 2026. The consequence for a reader is that pointing the tool at any document is a promise about which extra you installed: a base install with no extras has no PDF path at all. Scanned books are a separate problem again, since their text lives in page images rather than an embedded text layer, and the project points at exactly that case as a conversion that stalled before it was tracked as issue 130.
The token saving only exists while chapter files stay out of context
The headline figure is 24x to 51x fewer tokens than dumping the book into context to answer one question, measured on real books, with per-book tables and the method kept in docs/performance.md. The design behind it shows up in the generated file table: SKILL.md carries core mental models and a chapter index at about 4,000 tokens, glossary.md about 1,500, patterns.md about 2,000, cheatsheet.md about 1,000, and each `chapters/ch01-*.md` file about 1,000 tokens but only once a question touches that chapter. Read as arithmetic instead of a slogan, the non-chapter files total roughly 8,500 tokens if all are loaded before a single chapter opens, and a chapter-heavy book keeps adding to that as you ask more questions. The saving is measured against the whole book sitting in context, not against a short summary of it, and it evaporates if your host loads the whole skill directory eagerly.
Fold-in merges new sources, and nothing documented reverses a bad chapter
The usage line is `/book-to-skill <path|folder|glob> [skill-name]`, with analyze-only, generate-from-analysis, and update or fold-in modes layered on top, and a path that publishes the result to GitHub privately by default so any host can install it with `npx skills add`. Fold-in is the stated way to merge a fresh stack of papers and your own notes into a skill you already have, which is how a research cluster stays current as more material lands.
CI lints for crashes only, and the install command sits in docs
The tooling config in pyproject.toml sets ruff to target py39 and narrows the lint gate to syntax errors and pyflakes, with style left ungated, and points pytest at a tests directory. That split tells you what the maintainers treat as breakable: a green build says nothing about naming, import order, or formatting. For installation, the README links to docs/install.md, and the packaging metadata declares a console script. The build backend is hatchling, and the tree ships English, Russian, and Simplified Chinese READMEs plus mkdocs.yml for the documentation site, so host-specific behavior often lives in prose rather than in a table you can diff across versions.
[project.scripts]
book-to-skill = "book_to_skill.cli:main"ruff check .
pytestExtraction mistakes become the ground truth your agent trusts
Everything the agent later treats as authoritative comes out of one extraction pass. A chapter boundary the extractor splits wrong becomes a file cut in the wrong place, a term it drops never reaches glossary.md, a technique it loses never reaches patterns.md, and nothing downstream notices because the finished skill looks complete either way. That is the structural cost of pairing a deterministic extractor with a generative writer: the two halves can disagree about the document. The promise is that the agent answers from real content with no hallucination, and the load-bearing part of that promise is the per-chapter files, not the summary wrapped around them, which is why a book that extracts badly produces a skill that fails quietly and only when you ask the question it got wrong.
Editorial conclusion
Judge this as a converter plus a convention rather than a parser you can trust blind. The extractor half is ordinary Python behind per-format extras, and the half that writes your frameworks, decision rules, and anti-patterns is your own agent, so output quality tracks the model doing the writing. Use it for a book you reopen every month, a docs/ folder, or a spec pile, and install the extra that matches your file type before anything else. Skip it if you need the same skill to land in the same directory on two different hosts.
Frequently asked questions
How do skill books work?
You point the command at a file, folder, or glob, and it creates a skill directory holding a SKILL.md with core mental models and a chapter index, plus one file per chapter that loads only when your question touches that topic. Chapters sit alongside glossary.md, patterns.md, and cheatsheet.md, and the directory lands in ~/.agents/skills/<slug>/ for the hosts that read the cross-agent root.
How to turn a book into a claude skill?
Run /book-to-skill against the PDF, folder, or glob, optionally with a skill name after it. The generated skill goes to ~/.agents/skills/<slug>/, and under Claude Code the converter also attempts a symlink at ~/.claude/skills/<slug>/, reporting in the run output when the read-back does not confirm it.
What is the 3 book rule?
The README's closest thing to a rule of thumb is a candidate test: if you reopen a document often enough to wish you had memorized it, it is worth converting, which the project applies to internal documentation, brand and design systems, research clusters, and specs.
What are the 7 types of skills?
It targets hosts that read the open Agent Skills SKILL.md format, naming GitHub Copilot CLI, Amp, Claude Code, Hermes Agent, OpenCode, and OpenClaw, with Codex picking the skill up from the shared cross-agent directory as well.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/virgiliojr94-book-to-skill)Star history chart for your README
[](https://hysenlabs.com/projects/virgiliojr94-book-to-skill)Was this useful?