Wechatsync republishes one article to 29 platforms using your own cookies
One-click sync of articles to multiple content platforms, including Toutiao, WordPress, Zhihu, Jianshu, Juejin, CSDN and Typecho - publish once, sync everywhere, and free up your own time.
At a glance
- What is it?
- A GPL-licensed Chrome extension that reuses the session you already have in the browser and calls each platform's own web API, with draft-first publishing, a CLI, an MCP server and a JS SDK layered on the same core. Nothing goes through a third-party server.
- Who is it for?
- Wechatsync fits an author who already writes in one place and spends the saved time pasting into a dozen destinations, and who is willing to review drafts before they go live. It does not fit a team that wants unattended publishing, because the documented default is a draft plus a human confirmation, and there is no scheduler in the documentation.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
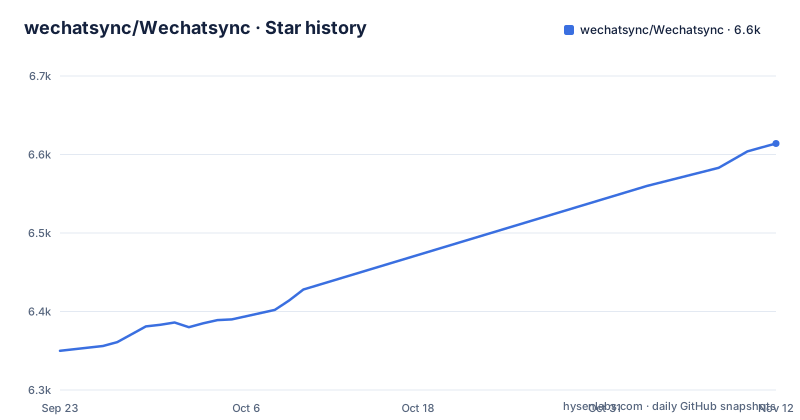
Star history
- wechatsync/Wechatsync6,614 ★ · +264
| Repository | 2026-09-23 | 2026-11-12 |
|---|---|---|
| wechatsync/Wechatsync | 6.4k | 6.6k |
264 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The extension borrows the session you already have instead of storing credentials
The design decision that defines this tool is stated up front: it is not a crawler, it does not simulate a login, and it does not go through any third-party server. It runs as a Chrome extension and works the way the browser already works. You log into each platform yourself in your own browser, and the extension reads the cookies that are already there, so there is no extra authorization step and no password to hand over. Publishing then calls the same official API the platform's own web editor uses, which the documentation treats as equivalent to publishing by hand.
The data path follows from that. Requests go from your browser straight to the platform, with no intermediate server and no upload, and the source is open so it can be audited. The diagram the documentation gives is only three lines: your logged-in browser, the extension reading the cookie, then the platform's web API. That is also the answer to the data-safety question in the FAQ, which says cookies, article content and account information never pass a third-party server. The trust argument rests on readable code plus a local execution path, not on a policy statement.
Draft first, publish later, with images moved for you
The default outcome of a sync is a draft. The documentation lists draft mode as the fourth of its working principles: an article is saved as a draft so you can edit it again before publishing, and nothing is posted automatically. That is a deliberate limit on automation, and it is worth understanding before you build anything around the tool, because an unattended pipeline would have to add its own confirmation step on top.
Alongside that, images are handled for you. The extension transfers article images to the target platform rather than leaving you to upload each one, and there is a separate tool exposed over the MCP interface for uploading a local image file to a platform. There is a second content path as well: any web page can be turned into Markdown by extracting the body text, filtering advertising noise, localising the images and packaging the result as a Markdown file plus a zip of images. Extraction of title, content and cover image is described as being based on the Safari reading mode implementation, and the v2.0.9 entry claims more accurate article detection across more pages.
Hexo and Hugo are not adapted, they are downloaded
Most of the platform table is a list of destinations with an adapter each: WeChat, Zhihu, Weibo, Xiaohongshu, Juejin, CSDN, Jianshu, Toutiao, Douyin, Bilibili, Baijiahao, Yuque, Douban, Sohu, Xueqiu, 51CTO, SegmentFault, CNBlogs, X, and others. Each row carries an identifier, a category and a status, and those identifiers are what you pass to the command line interface.
Two rows break the pattern. Hexo and Hugo both share the identifier zip-download and both are marked as supported through Markdown download rather than through a direct post. That is the honest limitation of the design for static site generators: the tool hands you a Markdown file and its images as a zip, and the actual publishing is left to your own static site build. Self-hosted WordPress, Typecho and CNBlogs go the other way and use the MetaWeblog API directly, so those are genuine adapters. For a blog running on anything not in that list, expect the zip and a manual step.
Four front doors sit on one shared core package
The repository is a monorepo with four packages: the Chrome extension built on Manifest V3, an MCP server speaking stdio and SSE, a command line tool, and a core package holding the shared logic. The core package is what makes the other three consistent, since the extension, the CLI and the MCP server all drive the same adapters.
Each of the other three has its own entry path. The CLI installs globally and needs no MCP configuration, but it still requires the extension to be installed and its MCP connection enabled so you can obtain a token. Once the token is exported, three commands cover the daily work:
npm install -g @wechatsync/cli

export WECHATSYNC_TOKEN="your token"

wechatsync sync article.md -p zhihu,juejin,csdn
wechatsync platforms --auth
wechatsync extract -o article.md
The MCP server is configured in the Claude desktop config file, where the command is node pointed at the built server and the token travels in an environment variable that must match the one set in the extension. It exposes five tools: list_platforms, check_auth, sync_article, extract_article and upload_image_file. There is also a separate Claude Code skill installed from a plugin marketplace, an OpenClaw skill, and a browser side JS SDK for editors that want to open the sync dialog themselves.
The workspace is declared for yarn while the setup instructions say pnpm
The root package.json declares workspaces as packages/* and every script is written against yarn: dev calls yarn workspace on the extension package, build runs yarn workspaces run build, and there are per-package build scripts for core, extension, mcp and cli. The engines field requires Node 20.0.0 or newer, and the pnpm key in the same file only names esbuild as a dependency allowed to run install scripts.
The development instructions tell you to run pnpm install, pnpm dev and pnpm build, and the repository root carries both a pnpm-workspace.yaml and a pnpm-lock.yaml next to a yarn.lock. So there are two package managers' worth of evidence in one tree, with the scripts pointing at one and the setup notes at the other. The mismatch is the sort of thing that wastes an afternoon when a workspace command behaves differently than expected. After a build you load the packages/extension/dist directory into Chrome.
Tagged releases stop at 1.0.10 while the changelog runs to 2.0.9
Version information is inconsistent in a way that affects how you install. The repository has no tagged release newer than 1.0.10, published in April 2021, with 1.0.9 and 1.0.8 before it. The changelog, by contrast, runs through 2.0.9 dated 2026-03-24, and the manual installation path points at a zip named wechatsync-2.0.9.zip. The default branch is v2 and the last push to it is dated 2026-05-27.
So the published GitHub releases are not where the current code lives. The recommended install is the Chrome Web Store listing, which auto-updates, and the manual path is a download of the zip rather than a release asset. Recent changelog entries give a sense of where effort has gone: Douyin image-and-text posting and a unified sync dialog and floating button in 2.0.8, SMZDM and NetEase platforms and Markdown publishing on Jianshu in 2.0.7, HTML formatting preservation in CLI and MCP sync plus reconnect stability fixes. Adapter churn is constant, which is why the adapter specification document is offered to anyone writing a new platform.
What this tool will not do for you
Read the feature list against what it excludes and the gaps are clear. There is no scheduling: articles sync when you trigger them, not on a calendar. There is no server-side execution, so the tool only works where a browser is logged in, and a headless machine with no session cannot use it. There is no team sharing or approval workflow in the documentation. There is no analytics feedback loop from the destination platforms back into the tool. And there is no publishing-to-scheduled-post option exposed anywhere in the command list or the tool table, only drafts.
The comparison answer in the FAQ makes the commercial pitch plainly: against tools such as Weixiaobao, Xinmeiti Guanjia, Jianmei and Yixiaoer, the argument is that this one is open source and free, runs locally in the browser, does not upload account information, and speaks MCP so AI tools can drive it. That is a fair set of differentiators for an individual author and a thin answer for an organisation that needs multi-user accounts and server-side scheduling, since none of those features appear anywhere in the project.
Editorial conclusion
Wechatsync fits an author who already writes in one place and spends the saved time pasting into a dozen destinations, and who is willing to review drafts before they go live. It does not fit a team that wants unattended publishing, because the documented default is a draft plus a human confirmation, and there is no scheduler in the documentation. Before relying on it, check that the platforms you care about are in the adapter table rather than on the request list, and confirm the version you install matches the 2.x line, since the tagged releases on the repository still stop at 1.0.10 from 2021 while the changelog runs to 2.0.9.
Frequently asked questions
What is Wechatsync and how does it work?
It is a GPL-3.0 Chrome extension that syncs one article to more than 29 platforms. It reuses the cookies already in your browser, calls each platform's own web API, keeps every request on your machine, and saves the result as a draft for you to review before publishing.
Does Wechatsync ask for my account passwords?
No. You log into each platform yourself in your own browser and the extension uses the existing session, with no extra authorization and no password entry. The documentation states that cookies, article content and account information never pass a third-party server, and the source is open for audit.
Which platforms does Wechatsync support?
The table covers WeChat, Zhihu, Weibo, Xiaohongshu, Juejin, CSDN, Jianshu, Toutiao, Douyin, Bilibili, Baijiahao, Yuque, Douban, Sohu, Xueqiu, 51CTO, SegmentFault, CNBlogs and X, plus self-hosted WordPress, Typecho and CNBlogs over the MetaWeblog API. Hexo and Hugo are marked as supported only through Markdown download.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wechatsync-wechatsync)Star history chart for your README
[](https://hysenlabs.com/projects/wechatsync-wechatsync)Was this useful?