Overgrowth's Makefile hardcodes an x86_64 binary name
Open Source codebase of the game Overgrowth by Wolfire Games LLC
At a glance
- What is it?
- The open source half of a commercial game: the engine and tools are on the repository, the art assets and levels are not, and a README that spells out both halves in plain language. What the build files show is a set of configuration targets that do not compose, a telemetry flag the documentation never mentions, and run targets that only work on one processor architecture.
- Who is it for?
- Treat this repository as engine source rather than as a buildable game, because that is exactly what it is. The code is permissively licensed and the data is not in the tree, so a clean checkout compiles only after you have bought the game and pointed the build at its data.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 52 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
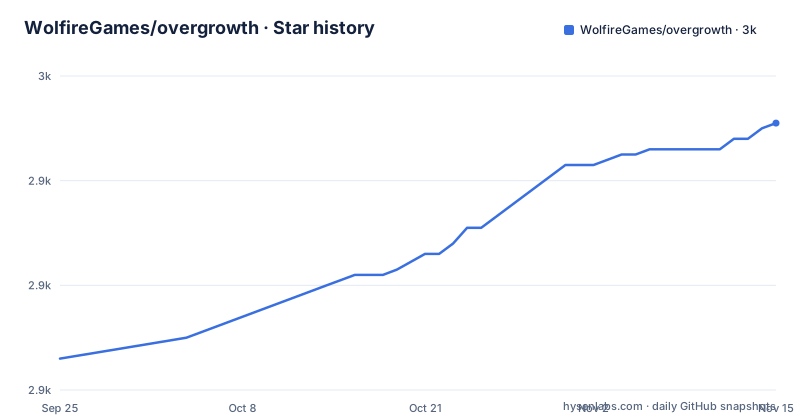
- WolfireGames/overgrowth2,951 ★ · +45
| Repository | 2026-09-25 | 2026-11-15 |
|---|---|---|
| WolfireGames/overgrowth | 2.9k | 3k |
45 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The code is open and the data is not
The first paragraph draws the line in one sentence. Only the code is available here, while the game data, meaning art assets and levels, can only be legally obtained by purchasing the game from the publisher. Distributing the original assets needs explicit written permission on top of that. Everything else in the repository follows from the split. What you can do with this tree is listed as five things: run the open code against the commercial data to experiment for educational purposes, propose changes to be merged back into the commercial game, create modifications that would otherwise be impossible, lift code snippets into your own projects, and build your own commercial total conversions on a completely new set of assets. So the repository is the engine and the tools, the data is a purchase, and the two halves meet only on a machine that has both.
A directory named Proprietary sits in the open repository
The top level has twenty four entries and two of them invite a question. One is a directory called Proprietary, sitting among the source, the tools and the frameworks, with no note in the repository file explaining what is inside it. The other is a directory called Data, in a repository whose central statement is that the game data is not distributed here. Both are visible in the tree listing, and neither is explained, which is exactly the kind of gap that costs a newcomer an afternoon. The rest of the layout is conventional for a large C++ project with third party code: a source directory, art source, tools, deploy scripts, documentation, auxiliary code, a frameworks directory and a libraries directory, with the CMake build rooted in a directory named Projects. Two of those library directories are pulled in through submodules, since a submodule file sits at the root. A static analysis configuration and a Steam application identifier are also committed at the top level.
Telemetry is compiled out in the release configuration
Every configuration target in the Makefile passes three flags to CMake: a build type, a telemetry switch and a switch for a component with an initialism. The release target sets the telemetry switch to on, which given the name means telemetry is disabled, and the debug target does the same. Exactly one target sets it the other way, a target whose only job is to turn telemetry on. The component switch is off in every setup target except the one that activates it. So the defaults are conservative on both counts: no telemetry, no extra component. What is missing is any mention of either in the repository file, which covers compiling, contributing and licensing in some detail and says nothing about a network capability compiled into a game engine. A build for local experiments therefore sends nothing, and anyone who wants telemetry has to find the flag rather than read about it.
Turning the extra component on drops the build type
The two component targets are two lines each. They create the build directory, change into it, and run CMake with the component flag and the projects path. What they do not pass is the build type. The release target passes it, and so do the debug and telemetry targets, but the component toggles do not, which means running one after a release configuration resets the build type to whatever CMake assumes when it is not given. A configuration that is supposed to be a release build with one component switched on is therefore not a release build. The same pattern of partial flags runs the other way: the clang target sets the two compiler variables and omits the telemetry and component flags that every other configuration target sets. Neither target is wrong on its own, and both compose badly. The Makefile offers no way to combine them, so a release build on clang or a release build with the extra component means editing the flags by hand.
run, debug and test all name one architecture
Three targets invoke the built binary by a name that ends in an architecture suffix:
test:
	cd Build; ./Overgrowth.bin.x86_64 --run-unit-tests
The run target launches the same file with no arguments, the debug target launches it under a graphical debugger, and the test target passes a flag that runs the unit tests inside the game binary itself. The naming means all three work on a machine where the build produced that exact filename, and the file says nothing about what happens on another processor architecture or where a differently named output lands. The unit tests are worth noting separately: they are not a separate test binary, they are a mode of the game executable, so testing requires building the game first. Everything else in the file is careful about parallelism, taking the core count from the system and passing a job limit through to the generated build system, and the clean target passes a clean request through rather than deleting the build directory.
The build lives in Build and the project root is Projects
The default target chains two steps: a setup that creates a directory called Build, changes into it, and points CMake at a sibling directory called Projects, then a build that hands control to the generated build system with a job limit. Every other setup target repeats those same two shell commands with a different set of flags, so there are seven near-identical recipes. Because the build directory name is fixed rather than parameterised, two checkouts in different directories still build separately, but a developer cannot keep two configurations side by side without moving the directory by hand, which is exactly what the component toggles invite. The repository also carries a formatting configuration for the C++ side and an editor configuration for everything else, which is a sensible split for a project of this size and a small sign of how many languages it actually contains.
The license summary includes a notice template
The license section is longer than the license section of most game repositories, and the reason is stated in the text: licences are hard to understand and this is no exception, so here is what it means in practice in most cases, with a note that this is not legal advice. Three obligations follow, and the third is the one people forget. Include the entire contents of the licence file, in the program or beside it, and the file shows how that can be done in a single line inside a licences file. Mark every file you have changed with a notice, and the file supplies a boilerplate template to copy:
//           Name: filename.h
//      Developer: Wolfire Games LLC
//    Modified By: Firstname Lastname
//    Description:
//        License: Read below
That last line is unusual: a template whose license field points at the file rather than naming a licence. And do not remove existing copyright notices. Since the licence is permissive, the summary says plainly that closed source use is permitted, which is why the repository file is worth reading in full before contributing.
Editorial conclusion
Treat this repository as engine source rather than as a buildable game, because that is exactly what it is. The code is permissively licensed and the data is not in the tree, so a clean checkout compiles only after you have bought the game and pointed the build at its data. Nothing here is a barrier to experimenting: the README lists running the code against the commercial data for educational experiments, submitting changes back into the commercial game, and building your own total conversion on a new asset set, and it is unusually direct about the licence obligations, including marking every file you modify. Three practical notes. Telemetry is compiled out by default in the release configuration and the documentation never mentions it, so check the flag you pass to the configuration step rather than assuming. The run and test targets name an x86_64 binary, so on another architecture you invoke the binary yourself. And there are no releases, so the branch is the version.
Frequently asked questions
what is overgrowth in this repository?
It is the official repository for the source code of the game Overgrowth by Wolfire Games, licensed under Apache-2.0 unless otherwise noted. Only the code is available there; the game data such as art assets and levels can only be legally obtained by purchasing the game, and distributing the original assets requires explicit written permission from Wolfire Games.
How do you get Overgrowth?
The repository file is explicit that the game data, meaning art assets and levels, can only be legally obtained by purchasing Overgrowth from Wolfire Games. The code alone is in the repository; compiling and running the commercial game needs both halves, and the compile instructions live in a separate document in the repository.
how to install overgrowth from source
You do not install it, you build it. The Makefile's default target creates a directory called Build, points CMake at the Projects directory, and then builds, with separate targets for a release configuration, a debug configuration, a clang build and one that enables telemetry. The resulting binary is launched from the build directory, and the run and test targets expect it to be named for the x86_64 architecture.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wolfiregames-overgrowth)Star history chart for your README
[](https://hysenlabs.com/projects/wolfiregames-overgrowth)Was this useful?