MaverickMCP: 37 tools, one dependency pin explained by somebody else's web page
MaverickMCP - Personal Stock Analysis MCP Server
At a glance
- What is it?
- MaverickMCP is a personal stock analysis server for MCP clients: market data, technical indicators, screening, portfolio tracking and a trade journal in the core, with backtesting and deep research as install-time extras. The parts worth reading closely are the security notice about the PyPI name, the screening design that only sees tickers you have already queried, and a manifest whose comments record exactly which upstream breaks forced each version pin.
- Who is it for?
- Reach for it if you want an agent to answer questions about your own holdings with indicators and a risk dashboard attached, and if you are the kind of user for whom a local server reading public market data is the right amount of trust. The core needs no key, needs no database, and starts with one make target, which is a low bar.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
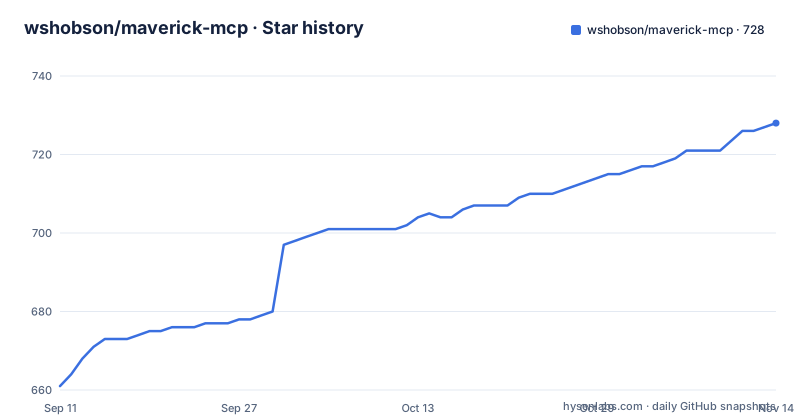
- wshobson/maverick-mcp728 ★ · +67
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| wshobson/maverick-mcp | 661 | 728 |
67 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The package name belongs to a dormant project, and the readme tells you not to use it
The most valuable paragraph in this readme is a security notice, and it is at the top of the installation section because that is where it belongs. The package is not on the public index. Its name is held by a dormant, unrelated project, and a name-transfer request under the packaging standard is pending with the index. Until that note is removed, the readme says explicitly not to install by that name, in either of the two ways a user would reach for it, because the name is not this project's and whatever its current owner publishes is what you would get. Think about what that failure mode is. A user copies an install line from a readme, gets code they did not audit from a project they did not choose, and that code ends up holding their market positions. The name-squat on an AI package is not a hypothetical; it is the obvious move once a tool's popularity is visible, and this project is telling you to expect it rather than hoping nobody notices. Three routes are offered and all three avoid the name entirely.
# Runs the v1.1.0 tag straight from GitHub via uvx, invoking its
# maverick-mcp console script (no checkout, nothing from PyPI)
uvx --from "git+https://github.com/wshobson/[email protected]" maverick-mcp --transport stdio

# With the backtesting and research extras
uvx --from "maverick-mcp-server[backtesting,research] @ git+https://github.com/wshobson/[email protected]" maverick-mcp --transport stdio
One asymmetry to keep in mind, because it will bite you later: the package still carries that name in its own metadata, so anything that resolves the name mechanically, such as a lockfile or a dependency list in another project, will resolve to the wrong place.
Thirty-seven tools in the core, and both extras are switched at install time
The core needs no API key at all, because market data comes from a library that scrapes a public finance site rather than from a paid feed. That single decision removes the usual first blocker, and it is why the setup section can claim there are no database migrations, no seed scripts and no key to configure before a single tool runs. What the core contains is worth listing because it is more than a quote lookup: historical and real-time prices with caching, technical analysis including a relative strength index, a moving-average convergence indicator and support and resistance levels, a combined full-analysis tool, three named screening strategies, and portfolio tracking with average cost basis, live profit and loss, a risk dashboard, watchlists and a trade journal. That last group is the part that makes it a personal tool rather than a data feed. The two extras add twelve backtesting tools, built on a vectorised engine with rule-based strategy templates, machine-learning strategy classes, optimisation, walk-forward analysis and simulation, and three research tools that run a graph-based deep research pass over companies, sectors and sentiment. The switch is the same everywhere: name the extras when you install, whether through the package runner, the dependency sync or the container image. Drop them and you get a smaller install with thirty-seven tools and none of those registered, which is the right default for a first run.
The screening tools only see tickers you have already queried
Read the description of the screening feature twice, because it is unusual. The three strategies, bullish, bearish and supply and demand, are computed over the tickers you have already queried. That is not a screener with a universe; it is a lens on your own query history. The consequences are concrete. You cannot ask which of four thousand symbols satisfies a condition without first pulling data on all four thousand, and at one market request per ticker that is a cost you pay before you have learned anything. And the results are scoped to what you happened to look at, so the tool cannot surprise you with a name you have never heard of, which is both the feature and the limit. For an individual investor with a fifty-name watchlist, this is the right shape and much cheaper than the alternative. For someone trying to find candidates, it is a wall. The same philosophy shows up in the caching, which is tiered: memory first, then an external cache server or a local database file, with a documented fallback when that server is not running. The environment example makes the tier a configuration choice rather than a capability you discover at runtime, since setting the cache host enables it and leaving it unset skips it entirely.
Two transports, and a trailing slash that breaks tool registration
The setup decision is one choice with a table that is unusually honest about the trade-offs. With the subprocess transport, your client launches the server itself, there is no endpoint, the configuration gives a command and its arguments, and it suits a single client on your own machine. With the streaming HTTP transport, you start the server yourself, the endpoint is a local address, the configuration gives a URL, and it suits several clients sharing one server process or access from somewhere else. The readme recommends the first as the default and the second when several clients should share one process, and it notes that clients configured for the subprocess transport launch the server themselves, so you do not need the development server running for them at all. That saves the most common confusion in this ecosystem, where people start the server and then wonder why their client spawns a second one. The failure worth memorising is in a callout further down. The HTTP endpoint must not have a trailing slash; with one it returns a redirect, and a client that does not follow redirects on a POST will fail to register its tools. The symptom appears in the client, looks like a protocol failure, and says nothing about the slash. If you write an MCP server of your own, that is the class of bug to design against.
The image caches dependencies before code, and compiles bytecode at build time
# Dockerfile for Maverick-MCP
# Python-only MCP server
#
# Two stages on the same base image, so the venv's interpreter symlinks
# (/usr/local/bin/python3.12) resolve in both. The builder installs the
# locked dependencies with uv; the runtime stage copies only the finished
# venv, so it carries no uv and no build toolchain. Every locked package
# ships a Linux wheel, so neither stage needs a compiler.
The container file is a better lesson than the feature list. Its header comment explains the whole design: two build stages on the same base image, so the virtual environment's interpreter symlinks resolve in both; the builder installing locked dependencies with the package manager; the runtime stage copying only the finished environment, so the shipped image carries neither the package manager nor a build toolchain; and every locked dependency shipping a prebuilt wheel for Linux, so neither stage needs a compiler. Two details in there are the kind you only write after being burned. Dependencies are installed before the project itself, so that layer stays cached until the manifest or the lock file changes, which means a source edit does not trigger a full reinstall. And the readme file is copied after the dependency layer rather than before it, with the comment explaining that the package metadata needs it and that a readme edit must not invalidate the dependency layer. The most interesting line is about bytecode. The runtime environment is read-only and writing bytecode at runtime is disabled, so without precompiling at build time every single start would compile the numeric stack from source. The package manager is also copied in at a pinned version and is absent from the final image.
A version pin explained by a logo letter on someone else's web page
The dependency list carries comments, and those comments are a record of failures rather than a description of intent, which makes them worth reading one by one. The HTTP client is pinned because the framework version stopped depending on it while one module in this project still imports it directly, and the comment calls the pin load-bearing. The validation library is pinned because every domain's configuration and types modules import it directly rather than reaching it through a framework, which is the normal reason a transitive dependency ends up as a direct one. The database layer is explained in more detail still: the object mapper loads drivers by URL scheme, the project rewrites a plain Postgres URL into an async form for its async engine, and one of the extras pulls a scheduler library on every platform while the mapper's own requirement skips it on one architecture. Then there is the scraping library, and its comment is the best single line in the repository. The pinned version reads a ticker from a cell's data attribute; the older version read the cell text, which now begins with a logo letter, so one company came back with a different symbol. That is what a scraper dependency costs: a cosmetic change on a page you do not control, and a quietly wrong row in somebody's portfolio.
SQLite by default, Postgres by uncommenting a line, Redis by setting a variable
The environment example opens with a claim worth checking rather than believing: this is a personal-use server, no authentication or billing configuration exists, and every variable in the file is read somewhere in the code. The file is arranged so that the claim is easy to test, with blocks for the database, the external cache, the cache itself and then per-domain settings further down. The database defaults to a SQLite file that needs no setup, and Postgres is one uncommented line. Pool tuning applies only to Postgres and is ignored for SQLite, every setting is named, and the statement timeout is given in milliseconds because it is. Several settings accept a second name as a fallback, which is the fingerprint of keys that were renamed at some point and kept working for people who had them in their configuration. The cache block tells you the design more honestly than the prose does: a seven-day default lifetime and a version key on the cache itself. That version key is how you invalidate every cached entry after a code change without touching anyone's database, and it is the difference between a cache you can deploy over and one that serves stale analysis for a week.
The compose file publishes the database and the cache to the host
The development stack is three services with health checks and explicit CPU and memory limits: the server, a Postgres image, and a cache server image. The two backing services are both published to the host on their standard ports, and the database credentials in the file are the default username and the default password. On a laptop that is fine and convenient. On a shared host, on a machine with a routable address, or inside anything that forwards ports, it is an open database with a guessable password, and the cache beside it is an open cache. The readme does not claim otherwise, since this is a personal-use server whose stated design is that no authentication configuration exists, and a compose file for local development is not a deployment description. The server service also carries an honest omission: there is no health check for it, with a comment explaining that the server exposes no HTTP health endpoint because it is a protocol server rather than a REST API. That is a real gap with a real consequence. Orchestration has nothing to probe, so a wedged server is discovered when a client fails to register tools rather than when a monitor notices, and in a stack where the two services that do have health checks are the ones you will never miss, that is the wrong signal to be missing.
Editorial conclusion
Reach for it if you want an agent to answer questions about your own holdings with indicators and a risk dashboard attached, and if you are the kind of user for whom a local server reading public market data is the right amount of trust. The core needs no key, needs no database, and starts with one make target, which is a low bar. Three cautions. Do not install it by its package name while the readme says not to, because that name belongs to a dormant project and installing it would give you somebody else's code. Treat the screening tools as a lens on what you have already looked at rather than as a way to find candidates, and do not expect the research extra to work without supplying two keys of your own. And read the compose file before you run it on anything reachable, because the database and the cache are published to the host with default credentials, which is fine on a laptop and not fine anywhere else.
Frequently asked questions
Can I install MaverickMCP from the Python package index?
Not yet. The package name is held by a dormant, unrelated project and a name-transfer request is pending, so the readme says explicitly not to install by that name in either of the usual ways, because whatever the current owner publishes is what you would get. Use the release tag through a package runner, the container image, or a source install.
Do MaverickMCP's core tools need an API key?
No. Market data comes from a library that reads a public finance site. The backtesting extra adds a vectorised backtesting engine with twelve tools, and the research extra needs both a web search key and your own model provider and key.
How many tools does MaverickMCP have?
Thirty-seven in the core, covering market data, technical analysis, screening, portfolio tracking with a risk dashboard, watchlists and a trade journal. The two optional extras add twelve backtesting tools and three research tools, and you opt into them by naming them at install time.
Should MaverickMCP use the subprocess transport or the HTTP transport?
The subprocess transport by default for one local client, where your client launches the server and the configuration gives a command and arguments. The HTTP transport when several clients should share one server process, where the configuration gives a URL. The HTTP endpoint must not have a trailing slash, or clients that do not follow redirects will fail to register tools.
What database and cache does MaverickMCP use by default?
A SQLite file with no setup, chosen by one variable, with Postgres a single uncommented line and pool tuning applying only to Postgres. The cache is tiered: memory first, then an external cache server or a local database file, and the external tier is enabled only when its host variable is set.
What does the MaverickMCP screening tool search over?
Over the tickers you have already queried, not over its own universe. Its bullish, bearish and supply-and-demand strategies are computed from data you have already pulled, which makes it a lens on your own history rather than a candidate finder.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wshobson-maverick-mcp)Star history chart for your README
[](https://hysenlabs.com/projects/wshobson-maverick-mcp)Was this useful?