BettaFish: A Multi-Agent Opinion Analysis System Built From Scratch
WeiYu (Micro Public Opinion): a multi-agent public-opinion analysis assistant for everyone, breaking filter bubbles, reconstructing the full picture of public sentiment, predicting future trends and supporting decision-making. Built from scratch with no framework dependencies.
At a glance
- What is it?
- BettaFish, also called 微舆, is a Python-based multi-agent system for public opinion analysis that coordinates specialized agents to search, analyze, and report on social media trends. This review examines its architecture, setup, and limitations.
- Who is it for?
- BettaFish suits developers who need a customizable, self-hosted opinion analysis tool and are willing to configure multiple LLM APIs and a database. It is not for users seeking a plug-and-play SaaS or those without Python and Docker experience.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 30 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
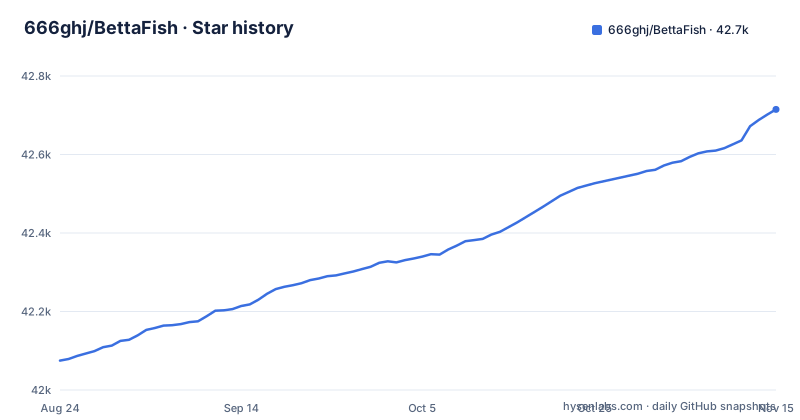
- 666ghj/BettaFish42,715 ★ · +640
| Repository | 2026-08-24 | 2026-11-15 |
|---|---|---|
| 666ghj/BettaFish | 42.1k | 42.7k |
640 Stars in the last 83 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What BettaFish Solves and Who It Is For
BettaFish addresses the problem of information silos in public opinion analysis. It aims to break filter bubbles by collecting data from over 30 domestic and international social media platforms and millions of user comments. The system is designed for users who want to ask a question in natural language and receive a structured report without manually browsing multiple sources. The project positions itself as a lightweight, extensible framework rather than a fixed product. According to the README, it can be adapted to other domains, such as financial market analysis, by modifying agent tool APIs and prompts. This flexibility appeals to developers who want to build custom analysis pipelines on top of a multi-agent architecture.
The Multi-Agent Architecture and Forum Collaboration
The system's core is a set of specialized agents that work in parallel and then collaborate through a forum mechanism. The README lists four agent types: Insight Agent for private database mining, Media Agent for multimodal content analysis, Query Agent for web search, and Report Agent for report generation. The analysis flow starts with a user query to the Flask main application. Then, three agents (Query, Media, Insight) start simultaneously, each using its own tools for an initial overview. After that, they enter a loop where they conduct deep research and share findings via the ForumEngine. The ForumEngine monitors agent contributions and generates moderator prompts to guide the discussion. This 'forum' approach is meant to avoid the homogeneity of a single model's thinking. The Report Agent later collects all results and forum content, selects a template, and renders an interactive HTML report. This design is a deliberate attempt to go beyond simple LLM calls by adding structured collaboration and reflection.
Getting Started with Docker and Source Setup
The README provides two paths: Docker Compose and source code. For Docker, you copy `.env.example` to `.env`, configure environment variables, and run `docker compose up -d`. The configuration includes database settings (PostgreSQL recommended, MySQL possible) with defaults like `DB_HOST=db`, `DB_PORT=5432`, `DB_USER=bettafish`, and `DB_PASSWORD=bettafish`. LLM settings follow the OpenAI API standard, so you can use any compatible provider. For source setup, the requirements are Python 3.9+, Conda or uv, a database, and at least 2GB RAM. You create a virtual environment, install dependencies with `pip install -r requirements.txt`, then install Playwright's Chromium driver with `playwright install chromium`. After editing `.env` with your API keys, you start the system with `python app.py`. The database is auto-detected and initialized on first run. This setup is straightforward but requires attention to LLM configuration, as each agent can have its own API endpoint.
The Reporting Pipeline: From IR to Interactive HTML
A distinctive feature is the report generation pipeline. After the agents complete their research, the Report Agent collects all analysis results and forum content. It then generates an intermediate representation (IR) by dynamically selecting templates and styles, and iteratively producing metadata. This IR is rendered into an interactive HTML report. The README mentions a sample report on Wuhan University's brand reputation, which is available as an HTML file. The system also supports PDF export, but that requires additional system dependencies for the weasyprint library. The report quality is a key selling point, but the actual output depends heavily on the LLM models used and the quality of the forum discussion.
Limitations and Failure Modes
BettaFish has several constraints that could make it the wrong tool in certain situations. First, it depends on external LLM APIs that must be OpenAI-compatible. If your provider does not follow that standard, you cannot use it. Second, the system requires significant configuration: you must set up a database, obtain API keys for each agent, and install browser drivers. This is not a zero-configuration tool. Third, the README warns that image pulling may be slow and provides alternative mirrors, indicating potential deployment friction. Fourth, the system's effectiveness relies on the forum collaboration mechanism, which may not work well if the LLM models are not capable of meaningful debate. Finally, the project is GPL-2.0 licensed, which means any derivative work must be open-sourced. This could be a barrier for commercial use where proprietary modifications are needed.
Alternatives and How They Differ
A direct alternative is the Manus, MiniMax, ChatGPT, or Perplexity comparison mentioned in the README. Those are general-purpose AI assistants that can perform web searches and generate reports, but they are not designed specifically for multi-agent opinion analysis. Another alternative is building a custom pipeline using LangChain or similar frameworks, which gives full control but requires more development effort. BettaFish's difference is its out-of-the-box agent structure and the reporting pipeline that produces interactive HTML. However, if you need a simple answer without a structured report, a general LLM might suffice. The choice depends on whether you value the multi-agent research approach over simplicity.
Maintenance and Upgrade Considerations
The latest release is v3.0.0, published in December 2025, and the repository's last push was on 2026-10-16. Upgrading involves pulling new Docker images or pulling the latest source code and re-installing dependencies. The code structure is modular, with separate directories for each agent, which should ease maintenance. However, the reliance on multiple external services (LLM APIs, search tools, browser automation) means that any upstream API changes can break functionality. The README notes that LLM calls use the OpenAI standard, so switching providers is possible but requires updating base URLs and keys. For long-term use, you should monitor the project's release notes for breaking changes and test the PDF export after system updates, as it depends on system libraries that may change.
Editorial conclusion
BettaFish suits developers who need a customizable, self-hosted opinion analysis tool and are willing to configure multiple LLM APIs and a database. It is not for users seeking a plug-and-play SaaS or those without Python and Docker experience. Before adoption, verify that your chosen LLM providers are compatible with the OpenAI API standard, confirm the database setup (PostgreSQL or MySQL) works with your environment, and test the PDF export feature if required, as it depends on system libraries. The project's GPL-2.0 license means derivative works must be open-sourced, so check your compliance needs. The system's strength lies in its agent collaboration and template-based reporting, but its complexity and external dependencies demand careful initial setup.
Frequently asked questions
what is bettafish github
666ghj/BettaFish is a Python multi-agent system for public opinion analysis, published under the name 微舆 and described as built from zero without depending on any agent framework. It crawls posts and comments across more than ten social platforms, has its agents debate in a forum loop moderated by an LLM, and renders an interactive HTML report.
How many LLM API keys does BettaFish need?
The .env.example file defines separate API key, base URL and model name triples for the Insight, Media, Query, Report, MindSpider, forum moderator and SQL keyword optimizer components. Every call uses the OpenAI request format, so any compatible service can be substituted.
Can BettaFish run without Docker?
Yes. The source path needs Python 3.9 or higher, Conda or uv, PostgreSQL or MySQL, and about 2GB of memory, and it runs on Windows, Linux and MacOS. Dependencies come from `pip install -r requirements.txt` and the crawler needs `playwright install chromium`.
What licence does BettaFish use?
The repository states GPL-2.0 and points at a LICENSE file at the root, with a THIRD_PARTY_NOTICES.md alongside it. Because GPL-2.0 is copyleft, check how it applies to your own distribution before embedding the code.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/666ghj-bettafish)Star history chart for your README
[](https://hysenlabs.com/projects/666ghj-bettafish)Was this useful?