aima-python: the book's pseudocode as a runnable Python package
Python implementation of algorithms from Russell And Norvig's "Artificial Intelligence - A Modern Approach"
At a glance
- What is it?
- aima-python turns the algorithms in Artificial Intelligence: A Modern Approach into an importable Python package, a notebook set and a pytest suite. It is a teaching companion, not a production library, and the repository structure makes that clear.
- Who is it for?
- Adopt aima-python if you are working through the book, teaching an AI course, or want a readable reference implementation of a specific algorithm such as astar_search, and you accept that the package targets Python 3.9 through 3.12 because tensorflow, keras and opencv-python do not yet ship wheels for 3.13 and later.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
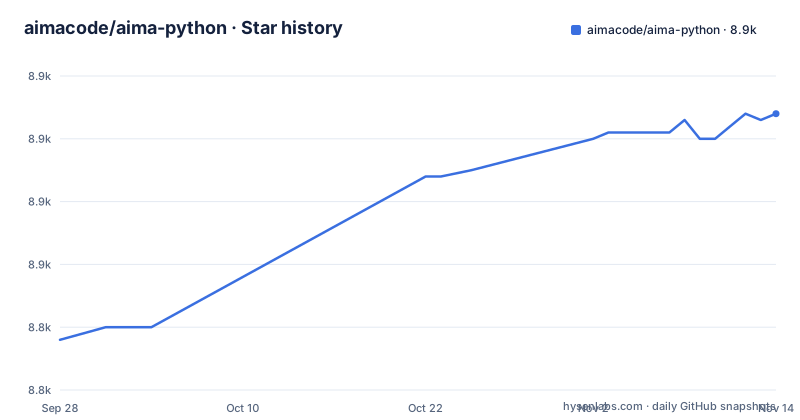
Star history
- aimacode/aima-python8,874 ★ · +36
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| aimacode/aima-python | 8.8k | 8.9k |
36 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What aima-python is for, and what it is not
The repository holds Python code for the book Artificial Intelligence: A Modern Approach. The README frames the audience directly: you can use this in conjunction with a course on AI, or for study on your own. That sentence is the whole scope statement. The project's value is that the book's pseudocode algorithms have counterparts you can call, inspect and step through, so a reader who is stuck on how A* actually orders its frontier can open aima/search.py instead of re-reading the figure.
It is not a library you would put behind a service. The package version in pyproject.toml is 4.0.0, but the repository has no published GitHub releases, so there is no versioned distribution channel to pin against. The interfaces track the book's presentation. When the book's notation changes between editions, the code follows the book, not a compatibility policy.
How the package, notebooks and tests fit together
Four top-level directories carry the project. The aima/ directory is the importable package, one module per major topic, so aima/search.py holds the search algorithms and their support classes. The notebooks/ directory holds the explanatory notebooks, including per-chapter demos under notebooks/chapterNN/. The tests/ directory holds a lightweight suite of assert statements intended for py.test but usable on their own. The lite/ directory is a JupyterLite proof of concept that runs a few notebooks in the browser through Pyodide with no install.
The notebooks and the package are wired together in a specific way. Each notebook opens with a %run bootstrap.ipynb cell that puts the repository root on sys.path, which is why from aima import ... works regardless of where the notebook was launched. A GitHub Action named notebooks-to-py.yml keeps a .py mirror of every notebook beside it, generated with jupytext. The README is explicit that the .ipynb is the source of truth and that you should edit the notebook, not the generated .py. If you send a patch to a generated mirror, it will be overwritten.
The edition policy is worth knowing before you read any module. The README states that the 3e/4e split is done, that no *4e.py files remain, and that the 4e-only modules (deep_learning.py, game_theory.py, making_simple_decisions.py, perception.py) were de-suffixed. Older tutorials that tell you to import from a *4e module are describing a layout that no longer exists.
Installing aima-python and running your first search
The README gives the sequence. Clone the repository, install the dependencies, then fetch the datasets, which live in a separate repository, aimacode/aima-data, wired in as a submodule. Skipping the submodule step leaves the datasets missing.
git clone https://github.com/aimacode/aima-python.git
cd aima-python
pip install -r requirements.txt
The README warns that the dataset download may take a while, so run the submodule commands and wait for them to finish before opening a notebook:
git submodule init
git submodule update
For an editable install, the README gives pip install -e. and notes that you can then run a module from the command line. The -i flag drops you into an interactive loop where the module's functions are already in scope:
pip install -e .
python -i -m aima.search
Two optional pieces are worth flagging before you start. The README states that a couple of notebooks need the Graphviz system binary (dot) for rendering, because the graphviz PyPI package is only a wrapper; install it with your OS package manager, for example apt install graphviz or brew install graphviz. And the test suite needs pytest, which the README installs separately before you run py.test. If you would rather not install anything, the README points at a Binder environment and at the browser-based JupyterLite build under lite/.
The dependency list is heavier than the algorithm code suggests
requirements.txt is not a small list. Alongside numpy, scipy, matplotlib, networkx, pandas and sortedcontainers, it pulls in tensorflow, keras, opencv-contrib-python, cvxopt, qpsolvers, jupyter, ipython, ipywidgets and ipythonblocks. The README explains why: the 4th edition puts more emphasis on Jupyter notebooks and more projects use external packages such as tensorflow.
The consequence is a real constraint. The README states that continuous integration runs the full test suite, including the deep-learning modules, on Python 3.9, 3.10, 3.11 and 3.12, and that some optional dependencies (tensorflow, keras, opencv-python) do not yet ship wheels for the very latest releases (3.13+), so one of those versions is recommended for running everything. On a current interpreter you can still read and run the pure-Python modules, but a full pip install -r requirements.txt is likely to be the slowest and most fragile part of getting started, and it is the step most likely to fail for reasons that have nothing to do with the algorithms you came for.
Where aima-python is the wrong tool
The test suite is the clearest signal of intent. tests/ uses assert statements rather than a fixture-heavy framework, and the README calls it lightweight. That is appropriate for a teaching repository and inappropriate for anything where a silent regression matters. There is no published release to pin.
If you need a search or graph library with a stable public API, a release cadence and a support window, this is the wrong dependency. If you need a planner or an inference engine to sit under a product, the same applies. The code follows the book's pseudocode, which means function signatures and data structures mirror the exposition rather than a designed API. Renaming or restructuring a module to suit your application is normal here, and it also means you own the result. Treat the repository as a reference you read and copy from, and treat the package install as a convenience for running the notebooks and tests, not as a runtime dependency to declare.
How it compares with writing the algorithms yourself
The realistic alternative is not a competing library but the standard scientific Python stack used directly: networkx for graph structures and traversal, scipy for optimization, and your own implementation of the specific search, CSP or MDP routine you need. The difference in approach is the point. networkx gives you a maintained graph API with a documented release process and no dependency on a textbook's notation; aima-python gives you the book's own decomposition, where the frontier, the state representation and the goal test are laid out to match the figure you just read.
That makes aima-python better for understanding and worse for shipping. A reader who wants to know why uniform-cost search behaves differently from A* will get more from aima/search.py than from a general graph library, because the code is organized around the explanation. A team that wants a graph algorithm in a service will get more from networkx, because the API will not move to follow a new edition. Choosing between them is choosing between an explanation and a dependency.
Licence, maintenance and the cost of upgrading
The repository is MIT licensed, and pyproject.toml declares license = { file = "LICENSE" }, so the terms travel with the code you copy. MIT is permissive, which matters here precisely because the intended use includes lifting an implementation into your own project. Keep the licence file with any substantial copy, and check the licences of the dependencies you actually install, since requirements.txt reaches into tensorflow, keras and opencv-contrib-python, whose terms differ from MIT. That is a description of the files, not legal advice.
The last push to the repository was on 2026-11-01, so the repository is not archived and has seen work within the last few months. The repository has no published GitHub releases, which means the upgrade path is git history rather than version numbers. In practice, upgrading means pulling the default branch and re-running py.test, then checking the modules you depend on for signature changes that follow a new printing of the book. The README's edition policy makes the direction of travel explicit: the 4th edition is canonical, and new algorithms, fixes and pseudocode references should follow the 4e numbering and content. Code written against the merged 3e/4e layout will keep working, but anything you wrote against the old *4e module names will not.
Editorial conclusion
Adopt aima-python if you are working through the book, teaching an AI course, or want a readable reference implementation of a specific algorithm such as astar_search, and you accept that the package targets Python 3.9 through 3.12 because tensorflow, keras and opencv-python do not yet ship wheels for 3.13 and later. Do not adopt it as a production search, planning or learning library: there is no release history, the interfaces follow the book's pseudocode rather than a stable API contract, and the test suite is built from plain assert statements. Before committing, verify three things: that pip install -e . resolves requirements.txt on your interpreter version, that git submodule init and git submodule update actually populate the aima-data directory, and that the module you need exists under aima/ with the function name you expect from the book's index.
Frequently asked questions
What is aima-python?
It is the Python implementation of the algorithms from Russell and Norvig's Artificial Intelligence: A Modern Approach, published as the aima package with notebooks and a pytest suite. The README describes it as usable alongside an AI course or for study on your own.
How do I install aima-python?
Clone the repository, run pip install -r requirements.txt, then run git submodule init and git submodule update to fetch the aima-data datasets. For an editable install the README gives pip install -e ., and pytest is installed separately before running py.test.
Which Python version does aima-python need?
The project requires Python 3.9 or later and does not run on Python 2. The README notes that continuous integration covers 3.9 through 3.12, and that tensorflow, keras and opencv-python do not yet ship wheels for 3.13 and later, so one of those versions is recommended for running everything.
Can I run aima-python without installing anything?
Yes. The README links a Binder environment for the notebooks, and the lite/ directory is a JupyterLite proof of concept that runs a few notebooks entirely in the browser through Pyodide.
Why is there no aima/search4e.py file any more?
The 3e/4e split is done: the README states that no *4e.py files remain, that the old pairs were merged, and that the 4e-only modules such as deep_learning.py and game_theory.py were de-suffixed. New 4th edition content goes directly into the relevant module.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/aimacode-aima-python)Star history chart for your README
[](https://hysenlabs.com/projects/aimacode-aima-python)Was this useful?