ai-memory: a self-hosted markdown memory server that lets Claude Code hand work to Codex
Solution for long term memory for agent coding CLIs and to facilitate handoff between different agent vendors.
At a glance
- What is it?
- Fabio Akita's ai-memory is a Rust binary that captures agent sessions through lifecycle hooks, stores them as a git-backed markdown wiki, and passes typed handoffs between more than twenty coding harnesses. It solves the one-machine, one-agent memory problem, but only if you are willing to run and expose a server yourself.
- Who is it for?
- ai-memory fits developers who switch between Claude Code, Codex, Cursor or other harnesses on the same project, and teams willing to host one shared server for that work. It does not fit someone who uses a single agent on a single machine and is happy with that agent's built-in notes, or anyone on native Windows who needs a stable setup.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
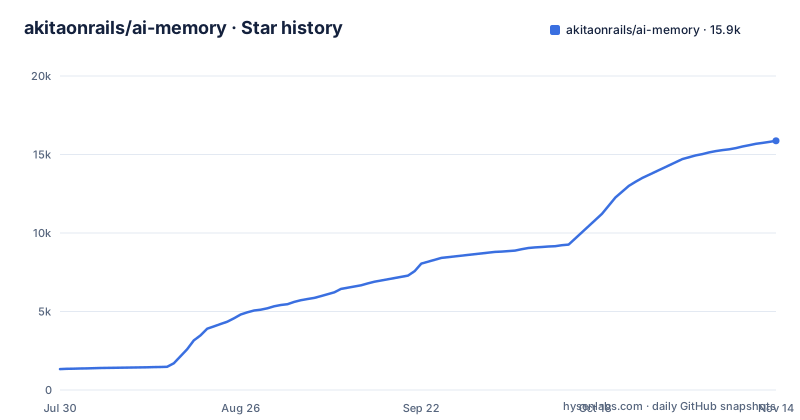
- akitaonrails/ai-memory15,875 ★ · +14,543
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| akitaonrails/ai-memory | 1.3k | 15.9k |
14,543 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Handoffs are a typed protocol with one owner, claimed exactly once
The problem ai-memory targets is narrow and concrete: the memory features built into Claude Code, Cursor and similar tools keep notes on one machine, for one agent, and those notes disappear from view when you switch tools or pass work to a teammate. ai-memory replaces that with one shared store fed by more than twenty harnesses, including Claude Code, Codex, Cursor, Gemini CLI, OpenCode, Grok, Devin, Kimi and Kiro.
The piece that makes switching work is the handoff. When you quit Claude Code mid-task and open Codex in the same directory, the next agent receives a handoff stating where you stopped, what failed and what is still open. Each handoff has an owner and is claimed exactly once, so two agents starting at the same time cannot both pick up the same baton. Knowledge is shared per project, while personal handoffs stay personal, which matters once several people point at the same server.
ai-memory run ships a private projection of the previous agent's transcript
A handoff is a summary, and summaries drop details. For that case the project adds a launcher: start agents through `ai-memory run`. If you quit Claude Code and then run `ai-memory run codex`, Codex receives the shared workstream plus a private, temporary local projection of Claude's visible native history, so it can look up exact details that the bounded startup packet left out.
The privacy line here is specific. The remote server receives only the harness and session identity, never the local transcript path or its body; the projection stays on your machine. The consequence for your workflow is that you only get this richer continuity when you launch through the wrapper. Starting a harness directly behaves exactly as it did before, so habits like typing `claude` or `codex` straight into a terminal will silently skip the transcript projection and fall back to the handoff alone.
The source of truth is a git-backed wiki of plain .md files
Captured sessions do not go into a vector store or a binary blob. At session end, sanitized observations become markdown pages in the project's wiki, which is a git repository of ordinary `.md` files. You can `grep` it, open it in Obsidian, edit pages by hand or `rsync` the whole thing to another box. The database sitting next to it is a derived index that can always be rebuilt from those files.
Recall happens in two layers. A new session, in any agent on any machine, gets a bounded brief injected at start, and it can search everything: full-text, entities, links and, if you turn them on, vectors, all fused into one ranking. Consolidation into pages can be LLM-written, but it is useful without one. The default path makes zero LLM calls, so capture, search and handoffs work with no API key configured at all.
Memory decays and compacts without an LLM, but the destructive parts start switched off
ai-memory ages notes on a schedule you can tune per tier, and memory you use decays slower: opening a page, searching it, or reaching it through a link counts as use. That access-weighted retention is always on, because it can only keep memory longer.
The features that change content are a different story. Compacting cold episodic notes down to durable facts such as file paths, error codes and decisions, collapsing near-duplicates into one page, and per-tier decay curves all stay off by default. Possible contradictions get flagged, also with zero API calls. If you install it and never touch the settings, the wiki will keep growing rather than tidy itself, and you need to opt in before it trims anything. Nothing is hard-deleted when you do: originals stay in git and in the version chain, and `restore-page` brings a page back.
Dreaming requires an LLM and has not earned default status
With an LLM configured there is a further, opt-in background pass the project calls dreaming. While you are idle, it rewrites whole clusters of cold notes into single coherent pages, and it cancels as soon as you return to work. It never deletes a source; the pre-merge versions stay reachable.
The limit worth knowing is that this pass is off by default and has to pass a recall eval before it could become default behavior. In practice that means the tidy, merged knowledge base some readers will picture is not what runs out of the box. Unless you configure a model and enable dreaming, what you get is the zero-LLM path: hook capture, session summaries, search and handoffs. That path is also what keeps the tool usable without paying for API calls, so the trade is deliberate rather than an omission.
Cross-machine and team memory only work if you host a reachable server
Memory lives in a server you run, whether on the same laptop, a homelab box or somewhere else. That is what lets a project left on the desktop resume on the laptop with the same knowledge and open questions, and it is what lets a team share one store. Multi-user auth, per-person attribution and an audit log of every mutation are built in and are not a paid tier.
The cost is operational. If you want memory on two machines, both need a network path to a server you run and keep up. On a shared server the cross-project profile, which carries your package manager, test layout and architecture habits into every new repository, is opt-in and private per person, while for a single user it is on by default. The write ceiling of roughly 700 writes per second is a measured figure, which sets an upper bound for a busy team.
Native Windows is experimental and some harnesses get only MCP
Every row in the support matrix is a first-party integration checked by CI, through MCP registration, lifecycle hooks or both. Linux, macOS, the NixOS module and Windows via WSL2 are supported. Native Windows is marked experimental, so a Windows user who does not want WSL2 is running a configuration the project does not yet stand behind.
Harness coverage is uneven in a way that changes what you get. Claude Code, Codex, Cursor, Gemini CLI, Devin CLI, OpenCode, Pi, OpenClaw and Grok Build CLI are listed as supported. Claude Desktop and Swival CLI are MCP-only, which means no lifecycle hooks, so silent capture of prompts and tool calls does not happen there. Crush is managed-only, and managed workstreams are opt-in. Check `docs/support-matrix.md` for per-agent notes before assuming your tool records sessions automatically.
Eleven crates, Rust 1.95, and a console behind two separate flags
The project ships as one self-contained binary built from a Cargo workspace on edition 2024 with `rust-version = "1.95"`. The shipped crates split the system along its pipeline: ai-memory-core, ai-memory-store, ai-memory-wiki, ai-memory-mcp, ai-memory-hooks, ai-memory-llm, ai-memory-consolidate, ai-memory-web, ai-memory-cli and ai-memory-workstream, plus a test-support crate that is never shipped. An evals harness lives in the workspace but is excluded from a bare `cargo build`.
The repository root also carries `install.sh`, `install.ps1`, a `flake.nix`, a `docker/` directory and an `INSTALL_FOR_AGENTS.md`, and tagged builds are on the GitHub releases page; v3.3.2 was published on 2026-11-03, two days after v3.3.1. The optional server-rendered management console, which handles user administration, session inspection and deletion and personal MCP API keys, is not in a default build. You must compile with `--features management-ui` and then start `serve --transport http --enable-management-ui`. A prebuilt binary without that feature will not expose the console no matter which runtime flag you pass.
Editorial conclusion
ai-memory fits developers who switch between Claude Code, Codex, Cursor or other harnesses on the same project, and teams willing to host one shared server for that work. It does not fit someone who uses a single agent on a single machine and is happy with that agent's built-in notes, or anyone on native Windows who needs a stable setup. Before adopting it, check docs/support-matrix.md for your exact harness, since some rows are MCP-only or managed-only, and decide where the server will live so every machine can reach it.
Frequently asked questions
What is ai-memory by akitaonrails?
ai-memory is an MIT-licensed Rust server that gives AI coding agents long-term memory shared across agents, projects and machines. It stores memory as a git-backed wiki of markdown files and passes handoffs between harnesses such as Claude Code and Codex.
How do you use ai-memory to switch from Claude Code to Codex?
Quit Claude Code and start the next agent with `ai-memory run codex`. Codex then gets the shared workstream plus a private, temporary local projection of Claude's visible history; launching a harness directly gives you only the handoff.
What is the main problem with AI memory that ai-memory tries to fix?
Built-in agent memory lives on one machine, belongs to one agent, and drops out of view when you switch tools or hand work to a teammate. ai-memory moves that memory into a shared server that more than twenty harnesses read and write.
What kind of memory system does ai-memory use?
Lifecycle hooks capture sanitized observations, the server consolidates them into markdown wiki pages at session end, and a derived index supports full-text, entity, link and optional vector search. The default path makes zero LLM calls.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/akitaonrails-ai-memory)Star history chart for your README
[](https://hysenlabs.com/projects/akitaonrails-ai-memory)Was this useful?