SAM3DBody-cpp: single-camera 3D body reconstruction in pure C++
Real-time 3D full-body reconstruction from a single camera, Multiperson BVH output, Pure C++ runtime, ONNX + ggml, 70-joint skeleton with hands.
At a glance
- What is it?
- SAM3DBody-cpp runs the SAM-3D-Body model through ONNX Runtime and ggml with no Python at runtime, and can write per-person BVH or MPEG ARF files. The catch is the hardware: the standard model files are BF16 and will not load on a CPU execution provider.
- Who is it for?
- Adopt SAM3DBody-cpp if you have a CUDA GPU and want 3D body pose or BVH motion files without a Python runtime in the loop; skip it if your only target is a CPU-only machine and you need video throughput, because the README puts one backbone pass at 5 to 15 seconds there.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
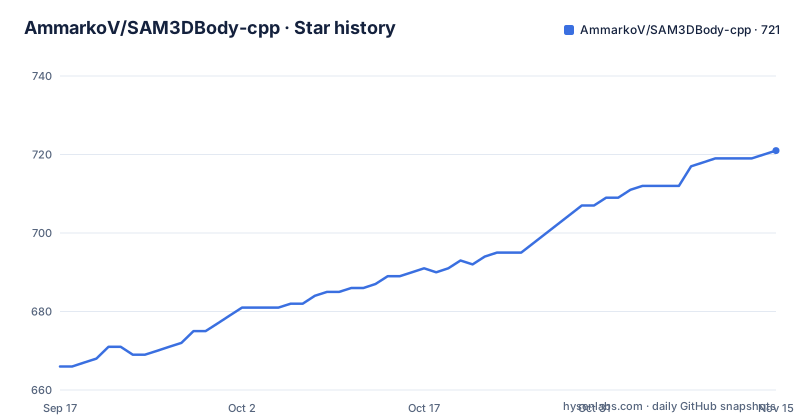
- AmmarkoV/SAM3DBody-cpp721 ★ · +55
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| AmmarkoV/SAM3DBody-cpp | 666 | 721 |
55 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What SAM3DBody-cpp reconstructs from one camera
The project is a standalone C++ inference engine for the SAM-3D-Body model. It takes a BGR image and returns, per person, MHR body pose parameters, a camera translation, and optionally full 3D mesh vertices plus 70 body and hand keypoints. Everything runs through ONNX Runtime and ggml, with the stated goal of zero Python dependency at runtime. Python frontends exist, but they call the compiled shared library through ctypes rather than running the model themselves.
The README is explicit that this is not 2D-to-3D lifting. The network regresses 3D body model parameters directly from image features. There is no depth sensor, no floor plane and no stereo pair involved. That distinction matters to anyone who has tried pose-lifting pipelines and found the depth ambiguity hard to pin down: here the depth is a learned output of the model, not something inferred from a 2D skeleton afterwards.
The audience is fairly narrow. You need a CUDA-capable GPU, a C++ build toolchain, and a reason to want motion-capture files rather than an API response. The BVH and ARF exporters point at animation and avatar work: driving a rigged character in Blender, or producing a container that carries mesh and skinning data alongside the skeleton. A team that only needs 2D keypoints for an analytics dashboard is not the target and will pay a large download cost for capabilities it never uses.
The inference path from YOLO boxes to LBS vertices
The pipeline has five stages, and the README states each one. YOLO detects person bounding boxes. Each crop goes to a DINOv2-ViT-H backbone that produces a [1280, 32, 32] spatial feature map. A transformer decoder, conditioned on the crop's ray directions and focal length, compresses that map into a 1024-dim pose token. Two small FFN heads then run on CPU through ggml and decode the token into 519 pose parameters and 3 camera parameters.
The 519 parameters break down as global orientation in 6D continuous rotation, per-joint Euler angles for 127 joints, 45 SMPL-like shape betas, 108 hand pose values and 72 face expression values. The camera parameters are [scale, tx, ty], which map to a world-space translation [tx, ty, tz]. Focal length is estimated from the image diagonal and baked into the decode step rather than being supplied by the caller.
Those parameters then drive linear blend skinning over 18,439 vertices to produce the mesh and the 70 keypoints. Two design choices stand out. The FFN heads deliberately run on CPU via ggml even in a GPU configuration, which keeps the small head computation out of the GPU graph. And the backbone and decoder are separate ONNX graphs, which is what makes the CPU substitution described later possible: you can swap in an fp32 backbone and an fp16 decoder without touching the rest of the pipeline.
Installing SAM3DBody-cpp and running a first clip
Models are not in the repository. They are hosted on HuggingFace at AmmarkoV/SAM3DBody-cpp-onnx-models, and tools/fetch_model.sh pulls them into onnx/ at the repo root. The README notes that scripts/setup.sh does this for you and that the binaries fetch models on first run if onnx/ is missing, so the manual fetch is only needed for a manual install.
For a CUDA machine, the shared cuda profile is roughly 5.2 GB:
bash tools/fetch_model.sh shared cudaRe-running the script only fetches what is absent, and an interrupted download resumes. Other profiles exist: shared cpu (~3.6 GB), shared trt (~1.9 GB) for TensorRT, and all for every variant. The refined profile (~607 MB of iterative decoder graphs plus pipeline_refined.gguf) is only needed if you pass --refined-pose, and the README says it is fetched automatically on first run with that flag.
The quickest end-to-end path is the video script with BVH export, which writes one file per detected person:
./scripts/video.sh --from clip.mp4 --bvh ./p.bvh --headlessThe README shows the result as p_0.bvh, p_1.bvh and so on. Identities are kept stable across frames by a built-in 2D-bbox IoU tracker, each file's joint OFFSETs are auto-resized to the actor's measured bone lengths, and the output is meant to drop into Blender, BVHTester or another DCC tool. A bundled blender/blender_bvh_plugin.py drives a MakeHuman-rigged character from the result.
On a CPU-only machine the substitution is different. The standard backbone.onnx and decoder.onnx are both exported in BFloat16 and require a CUDA GPU, because the ORT CPU execution provider has no BF16 kernels and refuses to load either graph. You download backbone_fp32.onnx with its ~3.2 GB .data file and decoder_fp16.onnx with its ~97 MB .data file from the same HuggingFace repo, place them in onnx/, and then select the CPU device explicitly:
./scripts/video.sh --from your_video.mp4 --cuda -1The README states that --cuda -1 picks both files up by itself, with no extra flags. CMake will warn at configure time if neither onnx/ nor the zip is found.
Why CPU inference is a single-image tool, not a video tool
The README does not soften this. DINOv3-ViT-H has roughly 630 million parameters, and on a modern laptop CPU one backbone forward pass takes 5 to 15 seconds. The README's own conclusion is that video processing is impractical and that only single-image or low-frequency use cases are feasible. For anything approaching real-time, a CUDA-capable GPU is required.
That is a hard boundary, and it is worth being blunt about what it means. The project's headline capability is real-time 3D full-body reconstruction from a single camera. On CPU you get the reconstruction but not the real time, and no amount of flag tuning changes it, because the cost is in the parameter count of the backbone rather than in the surrounding code. If your deployment target is a CPU-only edge box and you need frame-rate output, this is the wrong tool and the README says so before you download anything.
There is a second failure mode worth naming. The BF16 graphs fail at load time with execution-provider errors, not with a friendly message about missing GPU support. The README quotes the shape of those errors: "Could not find an implementation for Expand(13)" and "MatMul(13)". If you see that, the fix is the fp32 and fp16 downloads, not a rebuild. The README does not document rollback of a partially fetched model directory, so it is worth checking what landed in onnx/ before assuming a fetch succeeded.
BVH versus ARF export, and what each one leaves out
The two exporters answer different questions. --bvh PATH writes a standard BVH motion-capture file per detected person, carrying the skeleton and its animation. --arf PATH writes an MPEG Avatar Representation Format .arfz container per detected person, and the README's distinction is precise: unlike --bvh, it carries the mesh and skinning data too, not just the skeleton. The ARF container holds a base avatar with skeleton, skin weights and a personalized rest mesh, plus facial blendshapes when --dev-face is passed, animated by a per-frame Avatar Animation Unit stream.
The two flags are independent. You can pass either, neither, or both. That is a sensible arrangement: a pipeline that only needs to retarget motion onto an existing character takes the BVH and skips the mesh payload, while an avatar pipeline needs the skinning data that BVH cannot express.
ARF is the more speculative of the two. The README points to knowledge/ARF.md for the container layout, the JSON schema subset that is actually implemented, and how it maps onto ISO/IEC 23090-39. A schema subset is exactly what it sounds like: the implementation covers part of the specification, and the README does not claim full conformance. Anyone evaluating the ARF path should read that document before assuming a given field will round-trip. The BVH path has no equivalent caveat in the README, and the bundled Blender plugin gives it a concrete consumer to test against.
How SAM3DBody-cpp differs from a Python pose stack
The obvious alternative is running the SAM-3D-Body model in Python through ONNX Runtime or PyTorch, which is how most research checkpoints are consumed. The practical difference is deployment shape. A Python stack brings an interpreter, a package environment and a dependency tree into your runtime. SAM3DBody-cpp compiles to a shared library and a set of binaries, and the Python frontends in the repository are thin ctypes callers rather than the engine itself. If your product ships as a native application or a container where a Python environment is unwelcome, that difference is the whole reason to pick this project.
The second difference is output format. A generic pose library returns arrays. This project writes BVH files whose joint OFFSETs are auto-resized to the actor's measured bone lengths, with identity tracking across frames, and it ships a Blender plugin for a MakeHuman rig. That is a motion-capture deliverable rather than a pose estimate, and it changes who the user is: an animator or a technical artist can consume the output without writing a retargeting layer.
The trade-off is flexibility. A Python stack lets you swap backbones, fine-tune, or bolt on a new head in an afternoon. Here the pipeline is fixed at five stages with two ONNX graphs and a ggml head, and the substitution points are the ones the README documents: fp32 and fp16 model variants, a TensorRT profile, an optional LibreYOLO detector selected with --detector libreyolo, and the refined decoder profile behind --refined-pose. If your work is research rather than deployment, the C++ engine will feel like a constraint.
Licence, maintenance and the cost of the model download
The repository is MIT licensed, and the LICENSE file is at the top level alongside AUTHORS and INSTALL. The engine code being MIT does not automatically settle the terms of the model weights, which live in a separate HuggingFace repository. The README does not state a licence for those files, so anyone shipping a product that embeds them should check that repository directly rather than assuming the MIT grant covers the whole stack. This is a factual gap in the documentation, not a legal opinion.
The repository is not archived, and the last push was on 2026-09-11, which is recent. The repository has no published GitHub releases, so there is no versioned artifact to pin against; you are tracking the default branch. That has a practical consequence for upgrades: with no releases, the way to know what changed is to read commits, and the way to keep a working build is to pin a commit hash yourself.
The upgrade cost is dominated by the models rather than the code. The CUDA profile is about 5.2 GB, the CPU profile about 3.6 GB, and the fp32 backbone weights alone are about 3.2 GB. A model refresh means re-downloading that payload, and any change to the graph interface would require matching binaries. The fetch script's resume behaviour and its habit of only fetching what is absent make this less painful than it sounds, but the storage and bandwidth budget is real. Budget for it before you plan a CI job that pulls models on every run.
Editorial conclusion
Adopt SAM3DBody-cpp if you have a CUDA GPU and want 3D body pose or BVH motion files without a Python runtime in the loop; skip it if your only target is a CPU-only machine and you need video throughput, because the README puts one backbone pass at 5 to 15 seconds there. Before committing, fetch the model set with tools/fetch_model.sh and confirm which of backbone.onnx, backbone_fp32.onnx, decoder.onnx or decoder_fp16.onnx your execution provider will actually load, then check the LICENSE file for the MIT terms and the HuggingFace model page for the weights' own conditions.
Frequently asked questions
What is SAM3DBody-cpp?
It is a standalone C++ inference engine for the SAM-3D-Body model, with zero Python dependency at runtime. It takes a BGR image and produces per-person MHR body pose parameters, camera translation, and optionally full 3D mesh vertices plus 70 body and hand keypoints, using ONNX Runtime and ggml.
Can SAM3DBody-cpp run on a CPU without a CUDA GPU?
Yes, but not with the standard model files. The standard backbone.onnx and decoder.onnx are exported in BFloat16 and the ORT CPU execution provider has no BF16 kernels, so it refuses to load them. You download backbone_fp32.onnx and decoder_fp16.onnx from the same HuggingFace repository and then pass --cuda -1, which the README says picks both up by itself.
How fast is SAM3DBody-cpp on CPU?
The README states that DINOv3-ViT-H has about 630 million parameters and that one backbone forward pass takes 5 to 15 seconds on a modern laptop CPU, which makes video processing impractical. Single-image or low-frequency use cases are described as feasible, and a CUDA-capable GPU is required for anything approaching real-time.
How do I install the SAM3DBody-cpp models?
Run bash tools/fetch_model.sh shared cuda for a CUDA machine, or shared cpu for a CPU-only machine. The models are hosted at huggingface.co/AmmarkoV/SAM3DBody-cpp-onnx-models and land in onnx/ at the repo root; scripts/setup.sh does the fetch for you, and the binaries fetch them on first run if onnx/ is missing.
What is the difference between the BVH and ARF export in SAM3DBody-cpp?
The --bvh flag writes a standard BVH motion-capture file per detected person, carrying the skeleton and its animation. The --arf flag writes an MPEG Avatar Representation Format .arfz container per person, which carries the mesh and skinning data too, not just the skeleton. The README states the two flags are independent, so you can pass either, neither, or both.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ammarkov-sam3dbody-cpp)Star history chart for your README
[](https://hysenlabs.com/projects/ammarkov-sam3dbody-cpp)Was this useful?