Pholcus: a distributed Go crawler framework you compile yourself
Pholcus is a distributed high-concurrency crawler software written in pure golang
At a glance
- What is it?
- Pholcus is a pure Go crawling framework with three run modes, three downloader engines and rules written either in Go or in hot-loaded XML/JS. Here is what its architecture implies in practice, and where it stops being the right tool.
- Who is it for?
- Adopt Pholcus if you are comfortable in Go and want a single binary that runs a Web UI, a scheduler and a persistent output pipeline on your own machines. Do not adopt it if you need a managed scraping service, a Python ecosystem, or rules authored by non-programmers on a deadline.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 83 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
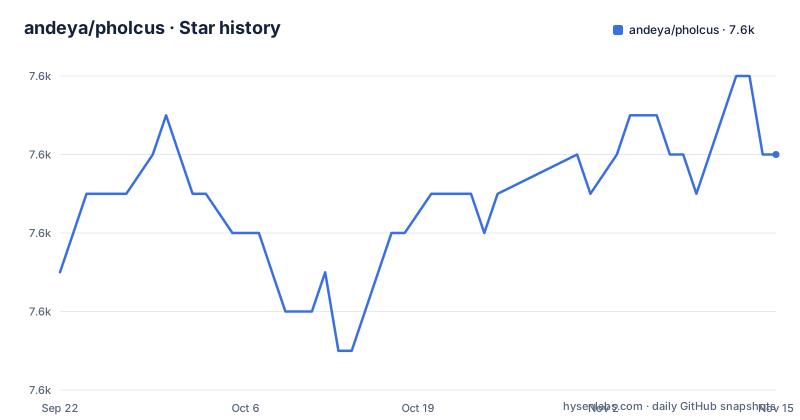
Star history
- andeya/pholcus7,584 ★ · +3
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| andeya/pholcus | 7.6k | 7.6k |
3 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Pholcus is for, and who it is not for
Pholcus is a crawler framework, not a crawler. The repository ships an engine, a scheduler, a downloader layer, a pipeline layer and a rule engine, plus more than thirty example rules under sample/static_rules/. You supply the target site and the parsing logic. The README frames it as academic research software and carries an explicit disclaimer that users are responsible for complying with local law, pointing at a collection of Chinese crawler-related legal cases. That disclaimer is not boilerplate: it tells you the intended audience is someone building a crawler for their own project, not someone buying a scraping product.
The people who get value from it are Go engineers who already have a data target and want the plumbing solved. The people who do not are those who want a hosted API, a point-and-click selector builder, or a Python library that plugs into pandas. Pholcus gives you a running Web UI on port 2015 and a Go module to import, and everything between those two facts is your code.
Three run modes and the Master/Slave socket layer
The repository layout puts the crawling logic under app/, split into crawler (engine and concurrency pool), downloader (the surfer package), pipeline (output backends), scheduler (request dispatch), spider (the rule engine), distribute (Master/Slave communication) and aid (history records and proxy IP handling). That split is the architecture: a request enters the scheduler, gets fetched by the downloader, gets parsed by a rule, and the parsed record leaves through a pipeline.
The distributed mode is a full-duplex socket framework between a Master and Slaves, per the README. The README lists three run modes: single-machine, a server mode that distributes tasks, and a client mode that receives and executes them.
Persistence is handled in two separate places. The pipeline writes records to MySQL, MongoDB, Kafka, Beanstalkd, CSV, Excel or raw file downloads. Separately, the aid package keeps history records, and the README states that successful records are persisted so crawling can resume after an interruption. Those are different concerns and different failure modes: a pipeline that drops a batch and a history file that goes stale will both cost you data, but only the second one silently re-crawls.
Installing Pholcus and running the Web UI
The README lists Go 1.18+ as the environment requirement and recommends 1.22+. The go.mod in the repository declares go 1.24.0, so a toolchain older than that will refuse to build the module as written. Clone the repository first.
git clone https://github.com/andeya/pholcus.git
cd pholcus
You need an entry point. The README's example is a main.go that imports exec and the built-in rule library, then calls exec.DefaultRun with the UI name. The sample directory already contains this file, so the fastest path is to build the sample rather than write your own.
package main

import (
    "github.com/andeya/pholcus/exec"
    _ "github.com/andeya/pholcus/sample/static_rules"
)

func main() {
    exec.DefaultRun("web")
}
Build it and check the flags. On non-Windows platforms the README says the GUI package is excluded automatically.
go build -o pholcus ./sample/
./pholcus -h
The README states that after starting, you reach the interface at http://localhost:2015, where spider selection, parameter configuration and task start/stop are all done in the browser.
For headless servers, the cmd UI takes the parameters directly. This example is copied from the README and shows the shape of a batch run: spider selection, output type, thread count, batch capacity, pause interval and keyword input.
pholcus -_ui=cmd -a_mode=0 -c_spider=3,8 -a_outtype=csv -a_thread=20 \
    -a_batchcap=5000 -a_pause=300 -a_proxyminute=0 \
    -a_keyins="<pholcus><golang>" -a_limit=10 -a_success=true -a_failure=true
Writing a rule in Go versus loading one from XML
There are two rule systems and they are not equivalent. Static rules are Go files under sample/static_rules/ that compile into the binary. The README describes them as the highest-performance option, suited to heavyweight collection projects. A static rule is a spider.Spider value with a Name, a Description, an EnableCookie flag and a RuleTree. The RuleTree has a Root function that seeds the queue with request.Request values and a Trunk map of named rules.
Dynamic rules are .pholcus.xml files dropped into a dyn_rules/ directory and loaded without recompiling, which the README positions for lightweight collection. The XML carries Name, Description, Pausetime, EnableLimit, EnableCookie, EnableKeyin and a Namespace containing Script elements, among other fields. For the rest of the schema, read the files under sample/dyn_rules/.
That asymmetry is the real decision. Static rules give you the compiler, the type system and the profiler. Dynamic rules give you a file drop and an interpreter, and the interpreter here is otto, a JavaScript engine written in Go. If your rules change weekly and your operators do not write Go, dynamic rules are the only workable option. If your rules are stable and your throughput matters, static rules are the only sensible option. Choosing dynamic rules for a high-volume job means paying interpreter cost on every page.
The downloader engines and what each one costs you
The README describes three downloader engines under app/downloader/surfer: Surf for high-concurrency HTTP, PhantomJS, and Chrome via Chromium headless with automatic JavaScript execution. The go.mod confirms chromedp as a direct dependency, which is the Go library that drives Chrome over the DevTools protocol.
This is a genuine capability, not a checkbox. Many Go crawlers treat JavaScript rendering as an afterthought or a separate service. Here it is one of three selectable engines behind the same downloader interface, and a rule picks the engine by setting DownloaderID on a request. The cost is operational: Surf is a Go HTTP client and adds nothing to your deployment, while the Chrome engine requires a Chromium binary reachable from the process. The README says the Chrome engine depends on a Chrome or Chromium browser installed on the machine and gives install commands for macOS, Linux and Windows, so plan your container image around that binary.
Cookie handling is tied to the user agent in a way worth noting. The README states that a fixed UserAgent saves cookies automatically, while a random UserAgent disables cookies. That is a deliberate pairing rather than two independent settings, and it means you cannot have both rotating user agents and a logged-in session. If your target requires login and you also want to rotate identity, Pholcus will not do both at once.
Where Pholcus is the wrong tool
The framework assumes you will operate it. There is no managed service and no hosted dashboard beyond the local Web UI. Because static rules are compiled in, reverting a rule means rebuilding and redeploying the binary. Dynamic rules reload without compilation. If your team needs to ship a rule change and undo it in under a minute without touching a build pipeline, this is a poor fit.
Second, the output backends are a fixed list. MySQL, MongoDB, Kafka, Beanstalkd, CSV, Excel and raw file download are what the README names. Adding a backend outside that list means checking the pipeline package. If your destination is a warehouse that speaks its own protocol, budget for that work.
Third, the dependency set is old in places. The go.mod pins gopkg.in/mgo.v2, a MongoDB driver that has been superseded, and github.com/Shopify/sarama v1.23.1. Those pins are not necessarily broken, but they mean the Mongo and Kafka output paths carry more maintenance risk than the CSV path.
How it compares to a Colly-based setup
The closest thing in the Go ecosystem to a direct alternative is Colly, a scraping library rather than a framework. The difference is where the structure lives. Colly gives you a Collector with callbacks, and you write the main function, the persistence, the scheduling and the concurrency control yourself. Pholcus gives you the scheduler, the pipeline, the proxy pool, the history store and the distributed layer already assembled, and you write the rules.
That trade favors Pholcus when you want the Web UI, the resume-after-interruption history, and the Master/Slave split without building them. It favors Colly when you want a library that stays out of the way, when your output is a function call rather than a database, or when you want to pick each dependency yourself instead of inheriting a go.mod that pins a deprecated Mongo driver.
The distributed story is the sharpest difference. Pholcus has a documented Master/Slave socket layer, with a server mode that distributes tasks and a client mode that receives and executes them.
Licence and the cost of keeping up
Pholcus is Apache-2.0, which permits commercial use, modification and redistribution provided you keep the licence and notices and state significant changes. Apache-2.0 also includes an express patent grant, which matters if you are embedding this in a product. The repository's own disclaimer about lawful use sits on top of the licence and is a separate matter from what the licence permits; the licence does not authorize crawling a site whose terms forbid it. This is not legal advice, and the disclaimer in the README is worth reading in full before you deploy.
The upgrade cost is dominated by the go.mod pins. The module declares go 1.24.0, so the framework tracks recent Go releases, but several dependencies do not track recent upstream releases. The last push to the repository was on 2026-08-24, and the most recent release is v1.4.0 from 2026-03-03. Between v1.3.4 in 2020 and v1.3.5 in 2026 there is a six-year gap in the release history, which tells you the project has had long quiet periods and that a future gap is plausible. Pin your dependency version and read the diff before moving it.
Editorial conclusion
Adopt Pholcus if you are comfortable in Go and want a single binary that runs a Web UI, a scheduler and a persistent output pipeline on your own machines. Do not adopt it if you need a managed scraping service, a Python ecosystem, or rules authored by non-programmers on a deadline. Before committing, verify three things in your own checkout: that your Go toolchain satisfies the go.mod directive, that the output backend you need is actually wired in the pipeline package, and that the dynamic rule format covers the fields your target site requires by reading the files under sample/dyn_rules/.
Frequently asked questions
How do I install Pholcus and start the Web UI?
Clone the repository, build the sample entry point with go build -o pholcus ./sample/, and start the binary. The README states the interface is then reachable at http://localhost:2015.
Does Pholcus run on Windows?
Yes. The README documents a Windows-native GUI alongside the Web UI and command line, and gives a build command using -ldflags="-H=windowsgui -linkmode=internal" to hide the console window. On non-Windows platforms the README says the GUI package is excluded automatically.
Can Pholcus execute JavaScript on pages that need it?
The README lists three downloader engines under app/downloader/surfer: Surf for high-concurrency HTTP, PhantomJS, and Chrome via Chromium headless with automatic JavaScript execution. The go.mod confirms chromedp as a direct dependency for the Chrome engine.
What output formats does Pholcus support?
The README names MySQL, MongoDB, Kafka, Beanstalkd, CSV, Excel and raw file download as pipeline outputs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/andeya-pholcus)Star history chart for your README
[](https://hysenlabs.com/projects/andeya-pholcus)Was this useful?