antirez/ds4 (DwarfStar): a narrow C inference engine for DeepSeek V4 Flash that only loads its own GGUF files
DeepSeek 4 Flash and PRO local inference engine for Metal, CUDA and ROCm.
At a glance
- What is it?
- DwarfStar, the ds4 repository, is an MIT-licensed C engine that runs a short list of open-weight models, led by DeepSeek V4 Flash, on Apple Silicon, DGX Spark, Strix Halo and CUDA cards. It trades generality for a tight, integration-tested path, and it is beta software with no tagged releases.
- Who is it for?
- ds4 is a good fit for owners of a 96 GB or larger Mac, a DGX Spark, a Strix Halo machine or a set of CUDA cards including Ada L40S who want DeepSeek V4 Flash or one of the other listed models running locally, and who are comfortable building from source and reading platform guides. It is a poor fit for anyone who wants to load arbitrary GGUF files, needs a stable release to pin, or objects to code written with heavy AI assistance.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
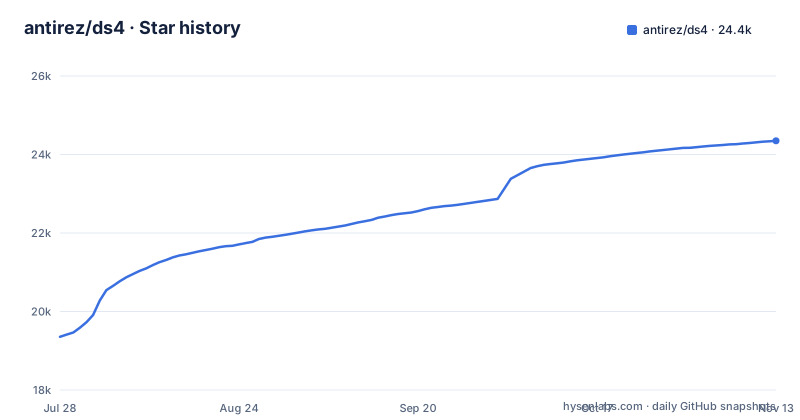
- antirez/ds424,350 ★ · +4,994
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| antirez/ds4 | 19.4k | 24.4k |
4,994 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
ds4 refuses to be a general GGUF runner
DwarfStar, built in the antirez/ds4 repository, is a small native inference engine aimed at running a few excellent large language models on hardware people can actually own. The list is short and deliberate: DeepSeek V4 Flash, including an experimental vision model; DeepSeek V4.1 Flash on Metal, with text inference on CUDA; GLM 5.2 and 5.3; GLM 5.3 Flash; DeepSeek V4 PRO; and Qwen3.8 Flash Next on Metal and CUDA.
The narrowness has a direct consequence. ds4 is not a general GGUF runner. You have to use the GGUF files that the project itself produces, which are part of the project. A GGUF you downloaded for another runtime is not a supported input, even for the same model family. In exchange, the parts that matter for daily use are built and tested together: model loading, prompt rendering, tool calls, KV state, the HTTP server, and the coding agent. The repository also carries its own tools and data for producing GGUF files, computing imatrix data, and checking quality and speed, which is how the project keeps its model files and engine in step.
Four make targets, and each binary is tuned to the build machine
Setup starts with a clone:
git clone https://github.com/antirez/ds4.git
cd ds4
Then you pick one build per hardware family, each with its own platform guide covering prerequisites, memory sizing, and hardware-specific setup. Metal on Apple Silicon uses make, guided by docs/METAL.md. DGX Spark uses make cuda-spark with docs/DGX_SPARK.md. Strix Halo and the Framework Desktop use make strix-halo with docs/STRIX_HALO.md. One or more CUDA cards, including Ada and L40S, use make cuda-generic with docs/CUDA_MULTI_GPU.md. None of the four guides covers Windows, so Windows users have no listed build target to follow.
The Makefile compiles with -O3 and -ffast-math and adds a native CPU flag: -mcpu=native on Darwin and -march=native elsewhere. The binary is optimized for the processor that built it, so rebuild on each host instead of copying a binary between machines with different CPUs. On Linux, CUDA_HOME resolves to /usr/local/cuda when nvcc is there, otherwise to the directory holding nvcc on your PATH. CUDA_ARCH is empty by default, and setting it to sm_120 or sm_121 switches the nvcc architecture flags accordingly.
Memory decides the model, and SSD streaming covers the gap
Metal is the primary target. A Mac with 64 GB can run Qwen Flash Next, while DeepSeek and GLM models need 96 GB or more. For a first run on a 96 or 128 GB machine, the suggested model is DeepSeek V4 Flash at Q2:
./download_model.sh ds4f-q2Downloads land in gguf/. If a download is interrupted, running the same command again resumes it, which matters for files of this size on a home connection.
The model weights are not the whole budget. You also need memory for the context and the runtime buffers, so a model that just fits in RAM on paper can still fail to leave enough room for long prompts. Machines below the thresholds are not shut out: SSD streaming lets smaller Macs run these models, at what the project calls a decent speed, and docs/SSD_STREAMING.md covers the setup. SSD streaming is also the required path for very large models such as full GLM 5.x, not the Flash variant, on 128 GB systems. The project's motivation leans on the same idea: compressed KV caches plus fast local SSDs make long contexts practical on personal hardware.
Older Ada Lovelace cards can serve models other runtimes reserve for newer GPUs
On NVIDIA hardware the DGX Spark is the main target, but the cuda-generic build also handles multi-GPU systems that other backends do not support. One example the project gives is running DeepSeek V4 Flash on Ada Lovelace cards, L40S included, where other inference implementations of newer models require newer GPUs.
That makes ds4 usable as a multi-user LLM server on hardware a team may already own. The project reports that its eight-L40S Flash setup reached about 126 tokens per second of aggregate generation across 16 sessions. That figure is aggregate, spread over sixteen concurrent sessions, so it describes throughput for a shared server rather than what a single user sees in one chat. Treat it as the project's own measurement on its own setup, and expect to measure again on yours.
On AMD, ROCm support targets Strix Halo systems such as the Framework Desktop. The source tree carries separate ROCm files, including ds4_rocm.cu and ds4_rocm_compat.cu, alongside the CUDA and Metal backends.
Gluing machines together with RDMA and pipeline parallelism
When one machine is not enough, ds4 offers two ways to combine several. With two 128 GB Macs connected over RDMA, you can run 4-bit DeepSeek Flash or GLM 5.3 Flash with tensor parallelism, splitting the work of each layer across both machines. Larger GLM 5.2 quants need bigger machines, such as Mac Studios, even in that configuration.
Pipeline parallelism is the second option. It glues multiple systems together so their RAM adds up, letting you run models larger than any one of them could hold. The distributed code lives in ds4_distributed.c, with tensor parallel support visible in the Makefile's ds4_tp.o object.
The project frames these implementations as rails rather than finished products. If DwarfStar shows a few good tensor parallel setups, the code is meant to serve as a template for the same feature under other conditions or with a new model. In practice that means an unusual cluster layout is something you adapt yourself, not a configuration option you switch on.
ds4, ds4-agent and ds4-server share one model link
Once built and with a model downloaded, the daily entry points are three binaries:
./ds4
./ds4 -p "Explain Redis streams in one paragraph."
./ds4-agent
./ds4-server --ctx 32768
The -p form passes a prompt on the command line. ds4-agent is the coding agent that is built and tested alongside the engine. ds4-server exposes the HTTP server, and --ctx sets the context length, 32768 tokens in the example.
The default model is ds4flash.gguf, which is a link rather than a file, so changing which model the tools load means changing what that link points to. The Makefile's test targets also default to ds4flash.gguf, and DSpark testing refers to a separate support file at gguf/DeepSeek-V4-Flash-DSpark-support-0731.gguf. Keep the gguf/ directory tidy, because the defaults all look there.
Beta quality, no tagged releases, and models that can be dropped
The project calls itself very fast changing and beta quality. A large QA run happens before each release, described in QA_BEFORE_RELEASES.md, yet instabilities and regressions are still possible. The repository has no GitHub releases, so there is no tagged version to pin; the last push to main was on November 2, 2026. If you depend on ds4 for a server, record the commit you built and test before pulling.
Model support is intentionally opportunistic. The project follows the best open weights for useful local machine sizes, especially 128 GB laptops and 256 or 512 GB workstations, and a model may be removed when a better replacement arrives. The consequence is that a setup built around one model today can lose upstream support later. Keep your own copy of the GGUF files and the matching source commit if continuity matters more than following the newest model.
Built with AI agents, and meant to be modified with them
The project is explicit that it is developed with strong assistance from AI coding agents, with humans leading the ideas, testing, and debugging. Anyone unwilling to run AI-developed code is told plainly that this software is not for them.
That disclosure connects to how Salvatore expects ds4 to be used. The shipped code targets the featured models and the most common hardware setups. For anything beyond that, he suggests pointing a coding agent at the repository: ask it to reach maximum prefill and generation speed on your specific hardware without impacting correctness, and to do a deep QA pass. An AGENT.md file sits at the repository root. The trade-off is that unusual setups are your responsibility to build and verify.
ds4.c does not link against GGML, but it owes a great deal to llama.cpp. Some source-level pieces are retained or adapted under the MIT license, including GGUF quant layouts and tables, CPU quant and dot logic, and certain kernels, and the GGML authors' copyright notice is kept in the LICENSE file.
Editorial conclusion
ds4 is a good fit for owners of a 96 GB or larger Mac, a DGX Spark, a Strix Halo machine or a set of CUDA cards including Ada L40S who want DeepSeek V4 Flash or one of the other listed models running locally, and who are comfortable building from source and reading platform guides. It is a poor fit for anyone who wants to load arbitrary GGUF files, needs a stable release to pin, or objects to code written with heavy AI assistance. Before committing, check the platform guide for your hardware, the memory sizing for your chosen model, and whether that model is still on the supported list.
Frequently asked questions
Can I run DeepSeek V4 Flash locally with ds4?
Yes. ds4 targets DeepSeek V4 Flash first, on Macs with 96 GB or more, DGX Spark, Strix Halo, and CUDA cards including Ada L40S. Smaller Macs can use SSD streaming.
Can ds4 load any GGUF model file?
No. ds4 is deliberately not a general GGUF runner and needs the GGUF files the project produces, fetched with download_model.sh into the gguf/ directory.
Which build command does ds4 use for each platform?
make for Metal on Apple Silicon, make cuda-spark for DGX Spark, make strix-halo for Strix Halo and the Framework Desktop, and make cuda-generic for one or more CUDA cards including Ada and L40S.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Directional steering is a runtime activation edit for DS4Hacker News · Sep 20, 2026 · 2 points · 0 comments
- Dwarf Star Support for Qwen3.8 Flash NextHacker News · Sep 16, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/antirez-ds4)Star history chart for your README
[](https://hysenlabs.com/projects/antirez-ds4)Was this useful?