FrontierAgent: a terminal agent runtime with a task board and a task-scoped sandbox
🧩 FrontierAgent, our agent framework, open-sourced alongside it — native command-line TUI, ReAct and Agent Team modes, one command on macOS and Linux, no preinstall, no hard Docker dependency.
At a glance
- What is it?
- FrontierAgent is an Apache-2.0 Python agent runtime from ApodexAI that ships a TUI with two workflows, ReAct and Agent Team, plus the benchmark harness used for its own models. It is aimed at long research and file-based work, and its main design bet is a shared sandbox with fail-closed authorization rather than a container-first deployment.
- Who is it for?
- Adopt FrontierAgent if you want a terminal-first agent that writes files into a per-task sandbox and leaves a trace you can inspect, and if you already have an OpenAI-compatible endpoint. Do not adopt it if you need a stable tagged release, a published Python API for embedding the loop in your own service, or a container-only deployment, because the repository shows no releases and Docker is described as optional rather than required.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
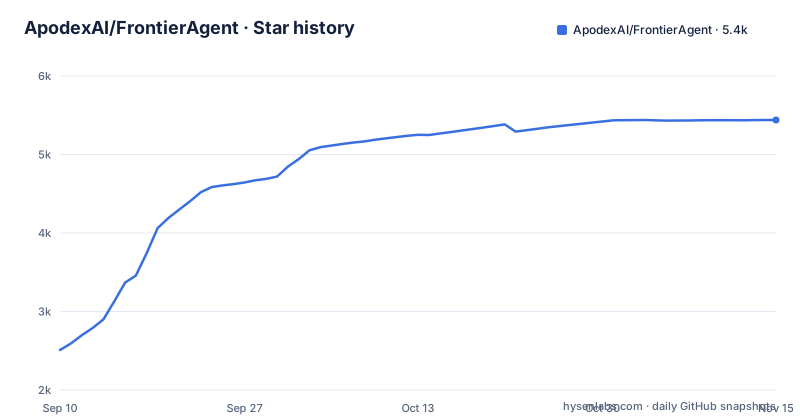
- ApodexAI/FrontierAgent5,440 ★ · +2,930
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| ApodexAI/FrontierAgent | 2.5k | 5.4k |
2,930 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What FrontierAgent is trying to fix about long agent runs
Most agent demos collapse the moment the work spans more than a few turns. State is lost between steps, a command that mutates the filesystem runs without review, and the final artifact ends up somewhere nobody can find it afterwards. FrontierAgent's answer is to treat a run as a session with a filesystem, an approval gate and an on-disk record. The README describes the target as "long-horizon research and file-based work", which is a narrower and more honest scope than general task automation. The intended user is someone who already has a model endpoint and wants an agent that reads files, runs commands and produces deliverables inside a directory they control. It is not pitched at teams that want a hosted service or a library they import into an existing Python application. The same workflow engine also powers the benchmark runner used to evaluate Apodex models, so the evaluation layer and the runtime are the same code path, separated in the repository so each can be reused independently.
ReAct and Agent Team: two workflows over one engine
The TUI ships two native workflows. ReAct is one stateful agent that researches, reads files, writes deliverables, runs commands and iterates inside a task-scoped sandbox. Agent Team puts a coordinator in front: it maintains a task board, delegates independent work to parallel sub-agents, collects their reports, and synthesizes the result. The task board is not a diagram in the README. `add_task` and `update_task` events appear live in the TUI sidebar with pending, active, completed, blocked and cancelled states, so you can watch the decomposition happen rather than guess at it. The coordinator can also use an optional fast reporter for a final evidence review. The distinction between the two modes matters for cost and for control. ReAct keeps one context and one line of reasoning, so an intervention steers the only agent running. Agent Team multiplies the number of model calls and the number of concurrent writers into the same sandbox, which is where the task board stops being decoration and starts being the mechanism that keeps parallel work from colliding.
The sandbox is the actual architecture
Shell and file tools share one task-scoped filesystem with three mounts. `/inputs` is read-only, `/workspace` is working state, and `/outputs` holds persistent deliverables. The README states that authorization and sandbox failures are fail-closed, meaning a rejected operation stops rather than degrading into an unguarded path. On macOS and Docker, `/outputs` maps to `.apodex/runs/<session-id>/outputs` on the host, and the same run directory holds the checkpoint, trace, engine log and trajectories. That layout is the most useful thing in the repository, because it means the evidence for a run survives the process. The repository splits responsibilities deliberately: `frontier_agent/` holds the generic loop, scheduling, registries, AgentBus and observers; `plugins/tools/` holds the web, shell, file, sandbox and team tool implementations; `workflows/` holds the ReAct and Agent Team pipelines, profiles, prompts and observers; `apodex/` holds the terminal CLI and TUI, approvals, sessions, traces and the Docker path; `benchmarks/` holds the public harness plus the bundled FrontierSearchBench and FrontierChallenge. If you want to change how tasks are scheduled without touching prompts, that boundary is where you would work.
Approval, intervention, revert and resume
Mutating operations show a diff and require approval unless `--yes` is enabled. That default is the right one for an agent with shell access, and it also means an unattended run needs an explicit flag rather than an implicit trust decision. Asynchronous intervention works by typing while an agent is running: the instruction is queued and injected at the next safe turn boundary without discarding the active run. In Agent Team mode the instruction steers the coordinator, and sub-agents already running are allowed to finish. That last detail is a real constraint, not a footnote. You cannot recall a sub-agent mid-flight, so a correction arrives after the work it was meant to prevent. Sessions are checkpointed, every action is traced locally, `/revert` restores session changes, and `--resume` continues a saved run. Revert applies to session changes, so anything written outside the session's tracked paths is not covered by that command.
Installing and starting the TUI
Requirements are Git, Python 3.12, uv, and an OpenAI-compatible model endpoint. Docker is optional. The README gives this sequence: clone the repository, change into it, then `uv sync --python 3.12 --extra dev`, then `cp .env.example .env`. The environment file takes `OPENAI_API_KEY`, `OPENAI_BASE_URL`, `OPENAI_MODEL`, and optionally `SERPER_API_KEY` and `JINA_API_KEY` for web research tools. The base URL points at an OpenAI-compatible endpoint, so a self-hosted server works as long as it speaks that API. Start the TUI with `uv run frontier-agent --mode react --cwd /path/to/project` for the single-agent workflow, or `uv run frontier-agent --mode agent_team --cwd /path/to/project` for the coordinator plus parallel sub-agents. Two details are worth noticing. First, pyproject.toml keeps the Office writers openpyxl, python-docx and python-pptx in the core dependencies, while the sandbox, eval, document-readers and plugins groups are optional extras. Second, the README's quick start mentions a free two-week Apodex API offer and an SGLang guide in the documentation index, so a hosted endpoint is one path and a self-hosted one is another.
Where the framework is the wrong tool
The repository shows no releases. There is no tagged release to pin, though the tree carries a CHANGELOG.md and pyproject.toml declares version 0.1.0, so an upgrade means tracking `main` and reading the changelog and commits. For a tool that runs shell commands against your files, that is the single biggest adoption risk. The second limitation is scope. Agent Team multiplies model calls by the number of sub-agents, and the README describes the parallel assignments only as bounded, so check the workflow configuration for limits before running it at scale. Third, Docker is optional rather than required. The Docker image installs bubblewrap and sets SANDBOX_BACKEND=bwrap, and in container mode the Dockerfile describes the container as the boundary, with an unprivileged account keeping model-run commands out of the harness's credentials. Finally, the evaluation harness is included, but the bundled benchmarks are FrontierSearchBench and FrontierChallenge; if your work does not resemble research or file-grounded tasks, the harness gives you less than the README's framing suggests.
How it differs from a general-purpose agent framework
Compare FrontierAgent with a general-purpose agent framework such as LangGraph or CrewAI. Those projects give you a library: you write the graph or the crew in Python, you own the loop, the state store and the deployment, and the framework supplies orchestration primitives. FrontierAgent inverts that. The loop, the scheduling, the tool registries, the AgentBus, the observers, the approval gate, the session checkpoints and the trace writer are all shipped, and the primary interface is a terminal TUI rather than an importable graph. You configure a mode and point it at a directory. The trade is control for a working default. With LangGraph you decide exactly where state lives and how retries work, and you get a stable package to pin. With FrontierAgent you get a task board, a three-mount sandbox, `/revert`, `--resume` and a run directory that already contains the trace and trajectories, but you accept `main` as your version and the TUI as your main surface. If your team already has an orchestration layer and wants model calls inside it, FrontierAgent's engine is the wrong layer to adopt. If you want an agent you can run from a shell against a project directory today, the shipped workflows are the point.
Maintenance cost and what the licence does and does not settle
The licence is Apache-2.0, which permits commercial use, modification and redistribution, and includes an explicit patent grant. It also requires that you keep the licence and notice files and state significant changes when you redistribute. That is a summary of the identifier, not legal advice; if you plan to redistribute a modified version or ship it inside a product, read the LICENSE file in the repository and get your own review. The maintenance picture is less comfortable than the licence. With no tagged releases, every upgrade is a diff against `main`, and the repository is organized so that a change in `frontier_agent/` scheduling can affect both workflows and the benchmark runner at once. Budget for reading commits before pulling, and pin a commit hash in your own checkout rather than following the branch if you need reproducibility.
Editorial conclusion
Adopt FrontierAgent if you want a terminal-first agent that writes files into a per-task sandbox and leaves a trace you can inspect, and if you already have an OpenAI-compatible endpoint. Do not adopt it if you need a stable tagged release, a published Python API for embedding the loop in your own service, or a container-only deployment, because the repository shows no releases and Docker is described as optional rather than required. Before committing, run `uv run frontier-agent --mode react --cwd /path/to/project` against a scratch directory, then inspect `.apodex/runs/<session-id>/` to confirm the checkpoint, trace, engine log and trajectories land where you expect and that `/outputs` maps to a path your team can archive.
Frequently asked questions
what is frontier agent
An open-source agent runtime, terminal product and evaluation suite for long-horizon research and file-based work, released under the Apache licence. The terminal interface ships two native workflows: a stateful ReAct workflow where one agent researches, reads files, writes deliverables and runs commands in a task-scoped sandbox, and an Agent Team mode where a coordinator maintains a task board and delegates to parallel sub-agents. The same workflow engine powers the benchmark runner.
What are the two workflows in FrontierAgent?
ReAct is a single stateful agent that researches, reads files, writes deliverables, runs commands and iterates inside a task-scoped sandbox. Agent Team is a coordinator that maintains a task board, delegates independent work to parallel sub-agents, collects structured reports and synthesizes a result, with an optional fast reporter for final evidence review. Both run from the same command with a different mode flag and a working directory argument.
How does FrontierAgent sandbox file work?
The shell and file tools share one task-scoped filesystem with three mounts: an inputs directory that is read-only, a workspace for working state, and an outputs directory for persistent deliverables. On macOS and under Docker the outputs directory maps to a per-session folder on the host that also holds the checkpoint, trace, engine log and trajectories. The documentation states that authorization and sandbox failures are fail-closed.
Does FrontierAgent require Docker?
No. The stated requirements are Git, Python 3.12, the uv package manager and an OpenAI-compatible model endpoint, with Docker described as optional. Docker or Compose is used when you want the container sandbox path, and the image is built from a slim Python base with bubblewrap and two LibreOffice components installed, while the compose file requires a dedicated unprivileged tool account for model-authored commands.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Apodex – FrontierAgentHacker News · Sep 16, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apodexai-frontieragent)Star history chart for your README
[](https://hysenlabs.com/projects/apodexai-frontieragent)Was this useful?