mergekit: Merging Pretrained LLMs in Weight Space Without a GPU Farm
Tools for merging pretrained large language models.
At a glance
- What is it?
- mergekit is a Python toolkit for combining pretrained language models by operating directly on their weights. It targets engineers who want to blend model capabilities without retraining and who may lack high-end hardware.
- Who is it for?
- Adopt mergekit if you need to combine pretrained LLMs without retraining and you are comfortable with YAML-driven configuration and LGPL-3.0 licensing. Skip it if your goal is to train a new model from scratch or if you require a GUI, since the tool is command-line and configuration-file oriented.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
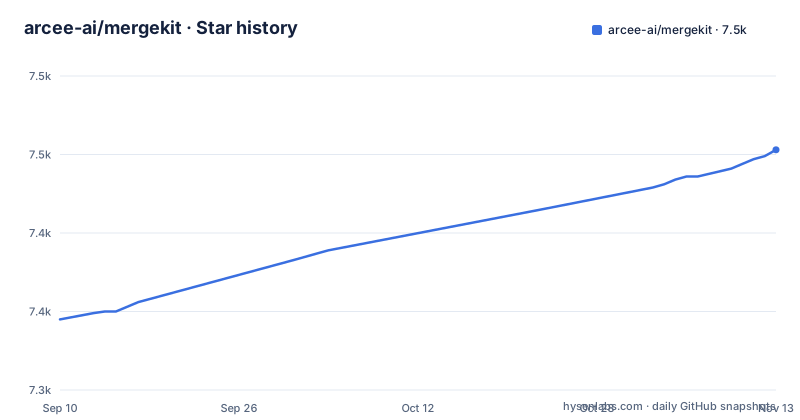
- arcee-ai/mergekit7,453 ★ · +108
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| arcee-ai/mergekit | 7.3k | 7.5k |
108 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Problem It Solves and Who It Is For
mergekit addresses the problem of combining the strengths of multiple pretrained language models without the cost of training or the runtime overhead of ensembling. Ensembling forces you to run several models at inference time, which multiplies compute and memory. A merged model keeps the same inference cost as a single model while, according to the README, often achieving comparable or superior performance. The intended user is an engineer or researcher who has access to pretrained checkpoints, wants to transfer capabilities between them, or wants to find trade-offs between model behaviors, and who does not necessarily have a cluster of GPUs. The README specifically claims that merges can run entirely on CPU or with as little as 8 GB of VRAM, which makes the tool relevant to individuals with consumer hardware.
Out-of-Core Design and Lazy Tensor Loading
The central architectural choice in mergekit is its out-of-core approach. Instead of loading entire models into memory, it lazily loads tensors as they are needed for the merge operation. This is what allows merges to run in resource-constrained environments. The README describes this as 'lazy loading of tensors for low memory use' and mentions an 'out-of-core approach to perform unreasonably elaborate merges'. The practical implication is that the bottleneck may shift from RAM and VRAM to disk I/O, especially when merging very large models. The tool also supports GPU or CPU execution, so you can choose to offload computation to a graphics card if one is available. This design is a deliberate trade-off: you can merge models that would otherwise not fit in memory, but the speed of the merge will depend on how fast your storage can feed tensors to the merge process.
Installation and Basic Command Flow
Installation is from source. The README instructs you to clone the repository and run pip install -e. inside the directory. It warns that if you get an error about editable mode requiring a setuptools-based build, you may need to upgrade pip to a version newer than 21.3 with python3 -m pip install --upgrade pip. The main entry point is a command-line script called mergekit-yaml. You give it a YAML configuration file and an output directory, for example: mergekit-yaml path/to/your/config.yml ./output-model-directory [--cuda] [--lazy-unpickle] [--allow-crimes]. The --cuda flag enables GPU execution, while --lazy-unpickle is another listed option. The presence of an --allow-crimes flag suggests that some merge configurations are considered unconventional or risky, and the tool makes you opt in explicitly. After the merge, mergekit generates a README.md for the output model, which you can edit or upload as-is.
Configuration Structure and Merge Methods
The YAML configuration describes the merge operation. The core fields are merge_method, which selects the algorithm, and either slices or models, which are mutually exclusive. Slices let you assemble a model from specific layer ranges of different source models, which is the mechanism behind 'Frankenmerging'. Models refers to using entire models as inputs. The README mentions tokenizer and chat template configuration options, so you can control how the merged model handles tokenization and conversation formatting. The supported merge methods include gradient-based interpolation inspired by Gryphe's BlockMerge_Gradient script, piecewise assembly, and more. This structure gives you fine control but also means you need to understand the semantics of each method before writing a valid config.
Beyond Simple Merges: LoRA, MoE, and Evolutionary Methods
mergekit is not limited to averaging weights of full models. The README lists LoRA extraction as a feature. It also supports Mixture of Experts merging, which is a different paradigm (the mergekit-moe script). Evolutionary merge methods are also present, with a mergekit-evolve script and an evolve extra. These features broaden the tool from a simple weight averager to a general kit for model recombination. However, each of these advanced methods adds complexity and may have specific constraints.
Multi-Stage Merging and Tokenizer Transplantation
For complex workflows, mergekit includes mergekit-multi, which allows chaining multiple merge operations in a single pipeline. This is useful when a final model requires several sequential steps, such as first merging a base with a specialized model, then applying a second merge to add another capability. The README also mentions mergekit-pytorch for merging raw PyTorch models, which implies that the main tool may require a certain format or wrapper, and this subcommand gives you lower-level access. Another distinct feature is tokenizer transplantation via mergekit-tokensurgeon. This is important because merging models with different tokenizers is a known pain point; transplanting a tokenizer lets you change the vocabulary and embedding layers of a model. This is a specialized operation that goes beyond simple weight interpolation and can be critical when you want a merged model to use a different tokenizer than its base.
Limitations and Wrong-Tool Scenarios
The most obvious limitation is that mergekit only combines existing weights; it cannot train new capabilities into a model. If your goal is to teach a model a new domain or improve its reasoning through fine-tuning, merging is not the right approach. Another limitation is that the quality of a merged model is not guaranteed; the README talks about 'optimal trade-offs' but does not promise that any given merge will improve performance. In fact, the --allow-crimes flag hints that some merges are experimental and may produce nonsensical results. The tool also depends on model architectures being compatible. While it supports Llama, Mistral, GPT-NeoX, StableLM, and more, you cannot merge models that have fundamentally different architectures.
Alternatives and Their Different Approaches
The main alternative to weight-space merging is ensembling, where you run multiple models and combine their outputs at inference time. Ensembling does not require any configuration of weights and can be done with any set of models, regardless of architecture, but it multiplies inference cost. Another alternative is fine-tuning a single model on a mixture of datasets, which can achieve similar capability transfer but requires training data and compute. A more recent alternative is model composition via Mixture of Experts, where you keep separate experts and route tokens to them. mergekit itself supports MoE merging, but if you want to train a custom MoE from scratch, you would need a different framework. The key difference is that mergekit operates in weight space and produces a single model with the same inference cost as the original, while ensembling and MoE routing preserve multiple parameter sets and add routing or averaging overhead.
Maintenance, Licensing, and Community Context
The repository is under the LGPL-3.0 license, which has implications if you plan to distribute a merged model or the tool itself. LGPL is more permissive than GPL for linking, but you should consult a lawyer for specific obligations. The project is actively maintained, with the last push dated 2026-10-31 and a recent release v0.1.5 from 2026-10-20. The README mentions a contributing guide, so the project accepts external contributions. There is also a hosted platform called FrankensteinAI that is powered by mergekit, which indicates real-world usage. The README includes a citation section, suggesting that if you use mergekit in academic work, you are expected to cite it. The presence of multiple subcommands (mergekit-yaml, mergekit-pytorch, mergekit-tokensurgeon, mergekit-multi) means you have to learn several interfaces, and the documentation in the README is comprehensive but not exhaustive. Before adopting, check the GitHub Issues for known problems with your specific model family or merge method.
Editorial conclusion
Adopt mergekit if you need to combine pretrained LLMs without retraining and you are comfortable with YAML-driven configuration and LGPL-3.0 licensing. Skip it if your goal is to train a new model from scratch or if you require a GUI, since the tool is command-line and configuration-file oriented. Before adopting, verify that the merge methods you need are supported for your specific model architectures, and confirm that the out-of-core tensor loading performs acceptably on your storage subsystem, as lazy loading can be I/O-bound. Also check the current state of the evolutionary and multi-stage features, as these are more complex and may have sharper edges.
Frequently asked questions
how to use mergekit
Clone the repository and run pip install -e ., which makes the scripts available. The main entry point is mergekit-yaml, which takes a YAML config path and an output directory, plus options such as --cuda and --lazy-unpickle, and mergekit-yaml --help lists the rest.
mergekit alternative
The readme names one hosted option, FrankensteinAI, a browser-based platform powered by mergekit with a community gallery and leaderboard, for people who prefer not to set up hardware. Nothing else is offered as a replacement for the toolkit itself.
What does mergekit need before it will install cleanly?
Python 3.10 or newer, and a pip newer than 21.3 if the editable install fails with a message about setup.py or setup.cfg not found. The build backend is setuptools, and an older pip cannot do an editable install against the pyproject.toml.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/arcee-ai-mergekit)Star history chart for your README
[](https://hysenlabs.com/projects/arcee-ai-mergekit)Was this useful?