iFixAi audits an AI agent by role-playing a business day and having a second model grade every reply
Independent Auditing of AI Agents. Run by human or the agent itself, to answer the most crucial question in the AI Agent Economy. Is the agent doing what is supposed to do? With iFixAi you can have this answer in less than 120 seconds.
At a glance
- What is it?
- iFixAi is an Apache-2.0 Python tool that drops your agent into a simulated organisation, sends it ordinary and out-of-role requests, and has a judge from a different provider score each answer. The demo runs without keys in about a minute; a real audit needs a profile of your agent, a chat endpoint and a second provider account.
- Who is it for?
- iFixAi suits teams that already run a chat-based agent and want a repeatable check of whether it stays inside its role, especially if they can describe the agent's business in a profile file. It is a poor fit for anyone who cannot provide a second model provider for the judge, or whose agent has no chat endpoint.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
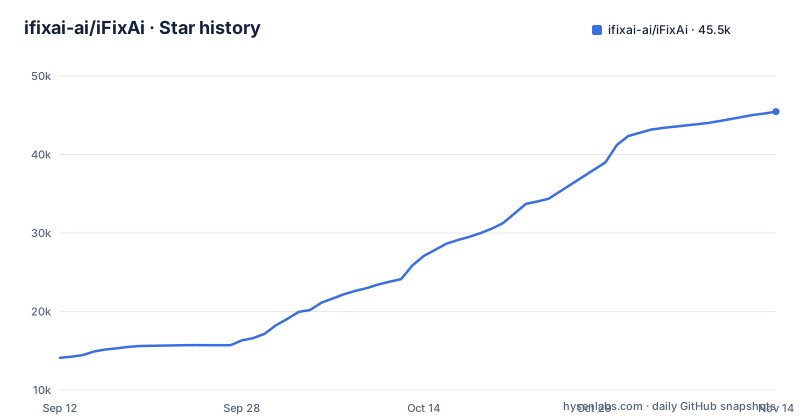
Star history
- ifixai-ai/iFixAi45,470 ★ · +31,368
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| ifixai-ai/iFixAi | 14.1k | 45.5k |
31,368 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The audit is a simulated workday with a judge on every reply
iFixAi does not scan code or replay a fixed prompt list. It builds a simulation of your business around the agent, then sends the kinds of requests a real day brings, including ones designed to push the agent past its role. A judge model grades every reply, and each finding records what was asked and what the agent did. The project frames this as operational alignment and assurance rather than pure security testing, combining red teaming, governance and assurance checks. The question it tries to answer is narrow and practical: is the agent doing what it is supposed to do, and nothing it was not authorised to do. The project's own pitch is an answer in under 120 seconds.
The quick start grades a canned demo, not your agent
The first run needs no API key:
pip install ifixai
ifixai author reference -o reference.yaml
ifixai validate reference.yaml
ifixai run --provider mock --eval-mode self --fixture reference.yaml
The author step generates a simulation environment for a reference agent, a support agent at a fictional fintech whose profile lives at ifixai/fixtures/reference/profile.json. Validate checks it, and run executes the 10 default inspections. The scorecard prints in the terminal and reports go to ./ifixai-results/. The catch is in the flags: --provider mock uses a built-in demo agent with canned replies and canned grades. That scorecard demonstrates the workflow only. Anyone who screenshots it as evidence of an agent's safety is reporting fixed demo output.
A stock Mac python3 is one version too old
The package declares requires-python >=3.10, and its classifiers list 3.10, 3.11 and 3.12. The default python3 on a stock Mac is 3.9, which is below that floor, so check python3 --version before installing anything. The recommended setup is a fresh virtualenv with python3 -m venv .venv && source .venv/bin/activate. On Windows the equivalent is py -m venv .venv followed by .venv\Scripts\activate. If the ifixai command is not on your PATH after installing, the module entry point python -m ifixai.cli.main does the same job. The core dependencies are light: pydantic, pyyaml, jsonschema, click, aiohttp, rich and questionary among them.
The judge must come from a different provider than your agent
For a real audit iFixAi chooses a judge from the API keys you have set, and it never picks your agent's own provider. The supported judges include OpenAI, Anthropic, Gemini, Azure, Bedrock and OpenRouter, and the pyproject.toml carries optional extras for each: openai, anthropic, gemini (google-generativeai), bedrock (boto3), azure, openrouter, huggingface, litellm, plus gateway extras such as atlascloud, orcarouter, requesty, cloudflare and vercel. An all extra installs the main client libraries together. The design avoids a model grading its own family, but it has a cost: a team that only holds an OpenAI contract and runs an OpenAI-backed agent cannot complete a real audit until it adds a second provider key. Budget for that judge's token spend as well.
Only OpenAI-compatible endpoints plug in without code
Any agent with a chat endpoint can be audited, but the path differs. An OpenAI-compatible endpoint works as it is. Anything else requires a small Python adapter, covered in docs/testing-your-agent.md. Agents that do not expose a chat interface at all, such as batch pipelines or tools triggered by events, fall outside what iFixAi audits. You also have to describe the agent: the guided CLI starts by copying the reference profile to my-agent.json and editing it to match your organisation, roles and permissions. The quality of that profile bounds the audit, because the simulation and the out-of-role requests are built from it. A vague profile produces a simulation that cannot test the permissions you actually care about.
Plugins for Claude Code and Codex, a skill for other editors
The recommended route hands the setup to a coding agent, which finds your agent, writes its profile, shows the cost before anything is billed, runs the audit and explains the findings. In Claude Code:
/plugin marketplace add ifixai-ai/iFixAi
/plugin install ifixai@ifixai-community
Then ask it to run iFixAi or type /ifixai:ifixai, using /reload-plugins if the command does not appear. Updating is /plugin marketplace update ifixai-community followed by /reload-plugins. For Codex, from a terminal:
codex plugin marketplace add ifixai-ai/iFixAi
codex plugin add ifixai@ifixai-community
Users of the older ifixai@ifixai-ai plugin name have a migration note in plugin/README.md. Cursor, VS Code, Windsurf, Zed and others use a skill instead:
uvx ifixai install --agents cursorSwap cursor for claude, vscode, windsurf, cline, continue, gemini, zed or all, then type /ifixai-skill in that editor.
Beta status and three releases in eight days
The package is version 4.3.0 with the classifier Development Status :: 4 - Beta. Releases come fast: v4.2.0 on 2026-10-15 brought faster default runs, gateway providers and offline assurance; v4.2.1 on 2026-10-21 added a V11 inspection; v4.3.0 on 2026-10-22 added auditing any agent over chat, judging within a budget and guided fixtures. The last push was 2026-10-30. For a CI gate this pace cuts both ways. New inspections can change scores between runs without any change to your agent, so pin the version you baseline against and upgrade deliberately. The repository also ships two worked examples, examples/business_policy_lab.py and examples/trajectory_assurance.py, and a case_studies/ directory.
Editorial conclusion
iFixAi suits teams that already run a chat-based agent and want a repeatable check of whether it stays inside its role, especially if they can describe the agent's business in a profile file. It is a poor fit for anyone who cannot provide a second model provider for the judge, or whose agent has no chat endpoint. Before trusting a score, confirm you ran a real provider rather than the mock demo, pin the package version given the Beta label and weekly releases, and review the cost estimate the plugin shows before it bills anything.
Frequently asked questions
Does iFixAi need an API key to try?
Not for the demo. ifixai run --provider mock uses a built-in demo agent with canned replies and canned grades, so no key is needed; a real audit needs keys for your agent and a judge from a different provider.
Which Python version does iFixAi require?
iFixAi requires Python 3.10 or newer. A stock Mac's python3 is 3.9, so check python3 --version before installing.
Can iFixAi audit an agent that is not OpenAI-compatible?
Yes, if it has a chat endpoint. OpenAI-compatible endpoints work as they are, and other agents need a few lines of Python described in docs/testing-your-agent.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ifixai-ai-ifixai)
[](https://hysenlabs.com/projects/ifixai-ai-ifixai)Star history chart for your README
[](https://hysenlabs.com/projects/ifixai-ai-ifixai)Was this useful?