python-tabulate: plain-text tables from Python data, and when that is enough
Pretty-print tabular data in Python, a library and a command-line utility. Repository migrated from bitbucket.org/astanin/python-tabulate.
At a glance
- What is it?
- python-tabulate formats lists, dicts, dataclasses, NumPy arrays and pandas DataFrames into plain-text tables in one function call, with roughly three dozen output formats. It is a small, MIT-licensed library plus a CLI, and it is not a terminal layout engine.
- Who is it for?
- Adopt python-tabulate when you need a compact, dependency-light way to print small tables in logs, tests or CLI output, and when the target is text you can paste into Markdown, reStructuredText or LaTeX. Do not adopt it for full-screen terminal UIs, live-updating dashboards or wide-character-heavy output unless you install the optional wcwidth extra.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
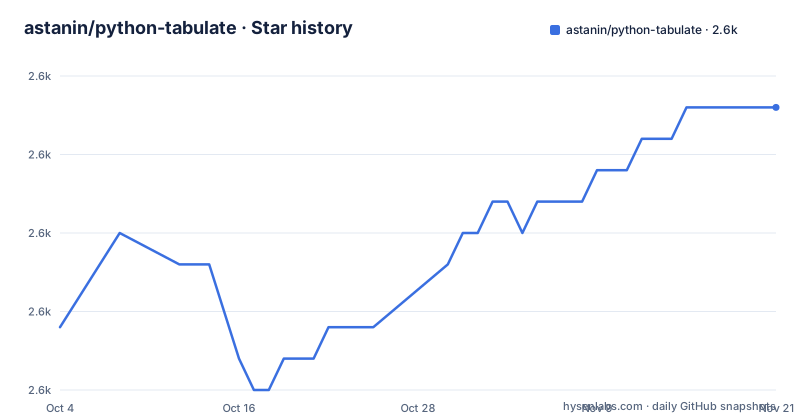
Star history
- astanin/python-tabulate2,594 ★ · +7
| Repository | 2026-10-04 | 2026-11-21 |
|---|---|---|
| astanin/python-tabulate | 2.6k | 2.6k |
7 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What python-tabulate is for, and who ends up using it
The README names three use cases. The first is printing small tables without hassle: one function call, with formatting guided by the data itself. The second is authoring tabular data for lightweight plain-text markup, where the output is meant to be edited or transformed further. The third is readable presentation of mixed textual and numeric data, which is where the library's alignment and number-formatting behaviour matters most.
That framing tells you who it is for. It suits someone writing a script that ends with a summary table, a test that asserts on text output, or a CLI that prints a result set. It suits anyone producing a Markdown table for a pull request body or a reStructuredText table for a docstring. It does not suit someone building an interactive terminal application. The library has no concept of a viewport, no redraw loop, and no cursor control. It produces a string. What you do with that string is your problem.
The module exposes one function, tabulate, which takes a list of lists or another tabular data type as its first argument. The supported inputs are broader than a list of lists: an iterable of iterables, an iterable of dicts with keys as columns, a dict of iterables, a list of dataclasses with field names as columns, a two-dimensional NumPy array, a NumPy record array with names as columns, and a pandas.DataFrame. That spread is the practical reason the library gets pulled in. You rarely reformat your data just to print it.
How tabulate() turns rows into aligned columns
The mechanism is straightforward and the README shows the result rather than the internals. You hand tabulate a table and it returns a string. Column widths are computed from the rendered content, and alignment is inferred from the data: numeric columns are right-aligned, text columns left-aligned. In the README's four-planet example, the mass column containing 1.9891e+09, 5973.6, 73.5 and 641.85 ends up right-aligned under a header, and the small integer column lines up under its own header.
The second argument, headers, controls the header row. Passing a list sets the labels explicitly. Passing the string "firstrow" consumes the first data row as the header. Passing the string "keys" uses dictionary or DataFrame keys, NumPy record-array field names, or column indices. When the data is a list of dictionaries, you can pass a dictionary as headers to rename keys, which the README demonstrates by mapping {1: "Name", 2: "Age"} onto records keyed by integers.
Row indices are a separate concern. By default only pandas DataFrames get an extra index column. For other data types you pass showindex="always" or showindex=True to add one, showindex="never" or showindex=False to remove it, or an iterable such as rowIDs to supply your own labels. The README's example with showindex="always" renders a leading 0 and 1 column for two rows.
The third argument, tablefmt, selects the output style. The README lists formats including plain, simple, github, grid, pipe, orgtbl, asciidoc, jira, presto, pretty, psql, rst, mediawiki, moinmoin, html, unsafehtml, latex, latex_raw, latex_booktabs, latex_longtable, textile and tsv, along with a family of box-drawing variants: simple_grid, rounded_grid, heavy_grid, mixed_grid, double_grid, fancy_grid and their outline counterparts. The default is simple, and the README notes the default may change in future versions. That sentence is worth taking literally: if your tests assert on exact spacing, pin the format explicitly rather than relying on the default.
Installing python-tabulate and printing your first table
The README gives a single install command for both the library and the command-line utility:
pip install tabulateOn Linux the CLI lands in bin, for example /usr/bin. On Windows it is installed as tabulate.exe into the Scripts directory of your Python installation. If you want the library only for the current user, the README offers pip install tabulate --user, which places the CLI at ~/.local/bin/tabulate on Linux and %APPDATA%\Python\Scripts\tabulate.exe on Windows.
There is also a library-only install path. On Unix-like systems you set an environment variable before the pip call:
TABULATE_INSTALL=lib-only pip install tabulateOn Windows the equivalent is two steps, setting the variable and then installing:
set TABULATE_INSTALL=lib-only
pip install tabulate
The entry point is declared in pyproject.toml as tabulate = "tabulate.cli:_main", which is why the command name matches the package name. Note the version floor: pyproject.toml sets requires-python = ">=3.10", and the classifiers list 3.10 through 3.14. On an older interpreter pip will refuse the install rather than fail at runtime.
A first real use is a summary table. The README's own example builds a list of lists and prints it:
from tabulate import tabulate

table = [["Sun", 696000, 1989100000], ["Earth", 6371, 5973.6],
         ["Moon", 1737, 73.5], ["Mars", 3390, 641.85]]
print(tabulate(table))
What you see is three columns separated by runs of spaces, with a dashed rule under the numeric columns and no header row, because none was supplied. Add headers and the same data gains a labelled first line. To emit a Markdown table for a pull request, switch the format:
print(tabulate(table, headers=["Planet", "R (km)", "mass (x 10^29 kg)"],
               tablefmt="github"))
The github format follows GitHub flavored Markdown and is described in the README as the pipe format with the same alignment colons, so numeric columns come out right-aligned with a trailing colon in the separator row. If you have a DataFrame, headers="keys" picks up the column names without you retyping them.
Where python-tabulate stops being the right tool
The library returns a string. It does not know how wide your terminal is. If a table is wider than the window, the output wraps or scrolls, and nothing in the README suggests column truncation or responsive layout. For a wide DataFrame you get a wide table, full stop.
Wide characters are a second boundary. The optional extra is declared as widechars = ["wcwidth>=0.6.0"], so correct width calculation for East Asian characters and other double-width glyphs depends on installing that extra. Without it, alignment in mixed-script tables is the thing most likely to look wrong.
There is also an html format and a separate unsafehtml format. The naming is a signal. If you are rendering untrusted data into HTML, the distinction between those two matters, and the README does not spell out the escaping rules. Treat that as something to check in the source before you put user input through it.
Finally, the project's own metadata says Development Status :: 4 - Beta. That is unusual for a library this widely depended on, and it is a fair warning that the default format is documented as subject to change. The repository was last pushed on 2026-03-11, which is under six months before the date of this review, so the codebase is not dormant. But a beta classifier plus a mutable default is a combination that argues for explicit tablefmt arguments in anything you intend to keep stable.
python-tabulate compared with prettytable, rich and pandas
The three comparisons people search for are all about the same axis: who owns the rendering.
pandas brings its own text rendering. DataFrame.to_string and the repr you see in a notebook produce tables without any extra dependency. If your data is already a DataFrame and you are happy with pandas' layout, you do not need python-tabulate. The difference in approach is that pandas renders its own object with its own conventions, while python-tabulate is format-agnostic: you choose tablefmt and you can feed it a list of lists, a list of dicts or a NumPy array just as easily. The cost is an extra dependency and an extra call.
rich is a terminal rendering framework. It handles colour, live-updating displays, panels, progress bars and console width. python-tabulate handles none of that. If you want coloured output, note that colour is not a documented feature of python-tabulate; people search for it, but the README's format list is about line-drawing characters and markup dialects, not ANSI styling. The reasonable division is that rich owns the screen and python-tabulate owns the string. If your output is going into a file, a test assertion or a Markdown document, rich is the wrong shape of tool.
prettytable is the closest in spirit: a small library for printing ASCII tables. Both give you a table object or a function and both let you pick a style. The practical difference visible in this repository is breadth of output dialects. The README lists Markdown, reStructuredText, MediaWiki, MoinMoin, Jira, AsciiDoc, LaTeX variants, TSV and HTML among the formats, which makes python-tabulate a converter as much as a printer. If you only ever print to a terminal, that breadth is dead weight; if you generate documentation, it is the whole point.
Maintenance, packaging and the MIT licence in practice
The repository was migrated from bitbucket.org/astanin/python-tabulate and now lives on GitHub. The last push recorded is 2026-03-11. The top-level layout is small: a tabulate/ package, a test/ directory, a benchmark/ directory, examples/ with people.csv and people.jsonl, plus CHANGELOG, HOWTOPUBLISH, LICENSE, README.md, pyproject.toml and tox.ini.
Packaging uses flit_core and flit_scm as the build backend, with the version marked dynamic and written to tabulate/_version.py. The practical consequence for upgraders is that the version is derived from source control metadata at build time, so a source tarball built outside a git checkout can behave differently from a wheel. The sdist includes CHANGELOG, test/ and tox.ini. Development tooling is pinned as a dependency group covering build, ruff, pre_commit, tox, tox-uv and twine. Tests run under pytest with --doctest-modules and --doctest-glob=README.md, which means the examples in the README are executed as tests. That is a real quality signal for documentation accuracy, and it also means a README example that stops matching the code breaks the build.
The licence is MIT, declared in pyproject.toml with license-files = ["LICENSE"]. MIT is permissive: it allows commercial use and modification with attribution and without a copyleft obligation on your own code. That is the shape of the obligation, not legal advice; read the LICENSE file for the actual terms.
Upgrade cost is low by design. The library has no required runtime dependencies, and the only optional extra is wcwidth for wide characters. The upgrade risk concentrates in two places: the default tablefmt, which the README says may change, and any test that asserts on exact whitespace.
Editorial conclusion
Adopt python-tabulate when you need a compact, dependency-light way to print small tables in logs, tests or CLI output, and when the target is text you can paste into Markdown, reStructuredText or LaTeX. Do not adopt it for full-screen terminal UIs, live-updating dashboards or wide-character-heavy output unless you install the optional wcwidth extra. Verify three things before committing: the exact tablefmt string your downstream consumer accepts, how your data type maps to headers (headers="keys" versus headers="firstrow"), and whether your Python version satisfies requires-python >=3.10.
Frequently asked questions
How do I install python-tabulate with pip?
Run pip install tabulate to install both the library and the command-line utility. The README also documents pip install tabulate --user for a per-user install, and TABULATE_INSTALL=lib-only for the library alone on Unix-like systems.
What is a tabulate format in python-tabulate?
The format is chosen with the tablefmt argument, which decides how the plain-text table is drawn. The README lists formats such as plain, simple, github, grid, pipe, rst, html, latex and tsv, with simple as the default, and notes the default may change in future versions.
How do I use python-tabulate to print a table?
Import the tabulate function, pass your data as the first argument, and print the returned string. Optional arguments named headers and tablefmt control the header row and the output style.
How do I install python-tabulate?
The README's install command is pip install tabulate. On Linux the CLI is installed to bin, and on Windows it becomes tabulate.exe in the Scripts directory of your Python installation.
What is python-tabulate?
It is a Python library and command-line utility for pretty-printing tabular data, distributed as the tabulate package under the MIT licence. The module provides one function, tabulate, which accepts lists, dicts, dataclasses, NumPy arrays and pandas DataFrames.
How does python-tabulate handle a pandas DataFrame?
A pandas.DataFrame is one of the supported tabular data types, and it is the only type that gets an extra row index column by default. Passing headers="keys" uses the DataFrame column names as the header row.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/astanin-python-tabulate)Star history chart for your README
[](https://hysenlabs.com/projects/astanin-python-tabulate)Was this useful?