AUTOMATIC1111 stable-diffusion-webui: The Gradio-Based Front End for Stable Diffusion
GitHub describes it as Stable Diffusion web UI. The repository metadata lists Python as its primary language. The metadata lists the AGPL-3.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- AUTOMATIC1111's stable-diffusion-webui is a browser interface for Stable Diffusion built on Gradio. It bundles a long list of generation, editing, and training features, with trade-offs you should weigh before adopting it.
- Who is it for?
- Adopt stable-diffusion-webui if you want a single, familiar interface that covers txt2img, img2img, inpainting, upscaling, and training without leaving the browser, and if you can live with the AGPL-3.0 license and a codebase that moves slowly (last release v1.10.1 in February 2025). Skip it if you need a lightweight, node-based workflow for production pipelines, or if you cannot accept AGPL obligations.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
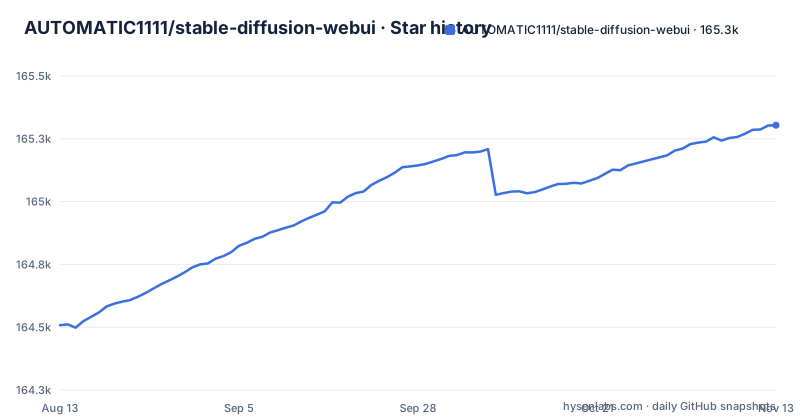
- AUTOMATIC1111/stable-diffusion-webui165,304 ★ · +796
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| AUTOMATIC1111/stable-diffusion-webui | 164.5k | 165.3k |
796 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Project Actually Solves
Stable Diffusion is a text-to-image model, but the raw Python code does not give you a way to type a prompt, see a preview, or adjust a seed. AUTOMATIC1111's stable-diffusion-webui solves that by wrapping the model in a Gradio web interface. The README lists the core modes: txt2img and img2img, plus outpainting, inpainting, and a color sketch tool. It is aimed at people who want to experiment with prompts, settings, and model variants without writing code. That includes hobbyists, artists, and researchers who need a quick visual loop. It is not aimed at teams who want to embed image generation into a larger application; the UI is the product, not a library.
The Feature List Is the Architecture
The repository's real substance is the feature checklist in the README. It is long, and that length is a design decision. The project does not try to be minimal. It bundles attention control, where you can write `((tuxedo))` or `(tuxedo:1.21)` to shift the model's focus. It also includes prompt editing, which changes the prompt mid-generation, and a prompt matrix for systematic variation. The X/Y/Z plot is a grid generator that varies parameters across three axes. These are not small add-ons; they change how you work. The UI also stores generation parameters in PNG chunks or JPEG EXIF, and you can drag an image back into the PNG info tab to restore those settings. That is a concrete data flow: image out, parameters embedded, image in, parameters recovered. It is a closed loop that makes experiments reproducible without a separate logging system.
How to Get It Running: Commands and Dependencies
The README says there is a one-click install and run script, but it immediately qualifies that: you must still install Python and git yourself. For NVidia GPUs, the wiki gives specific instructions; AMD and Intel have separate wiki pages. The README tells you to make sure the required dependencies, documented on a wiki page, are met before following the install instructions. The key runtime flag mentioned is `--xformers`, which gives a major speed increase on select cards. Another flag is `--allow-code`, which enables running arbitrary Python code from the UI. That is a security-sensitive option, and the README is explicit that it must be enabled manually. The UI also supports reloading checkpoints on the fly, so you can swap models without restarting the server. The default resolution restriction is that image dimensions must be a multiple of 8, not 64, which is a small but practical easing for users who want non-standard sizes.
Training and Extensibility: Where the Real Work Happens
The training tab is a significant part of the project. It supports embeddings and hypernetworks, and it includes preprocessing steps like cropping, mirroring, and autotagging with BLIP or DeepDanbooru (for anime). That means you can train a custom embedding on a small dataset without leaving the UI. The project also supports LoRA, described in the README as 'same as Hypernetworks but more pretty'. There is a separate UI for selecting embeddings, hypernetworks, or LoRAs with previews. The extension system is the other major extensibility point. The README points to a wiki for custom scripts and mentions specific extensions like the History tab and Aesthetic Gradients. The checkpoint merger is another standout: you can merge up to three checkpoints into one. This is not a toy feature; it is how many users create custom models. The combination of training, merging, and extension support makes this a tool for model tinkering, not just image generation.
The License and Maintenance Reality
The project is licensed under AGPL-3.0. That is a strong copyleft license, and it has real implications if you plan to use the web UI as part of a service. The README even says 'Now with a license!', which suggests the license was added later. The last push was on 2026-03-02, and the newest release is v1.10.1, published on 2025-02-09. The previous release, v1.10.0, was July 2024, about six months earlier. The project is not archived, but the pace is slow. For a tool that many people rely on for daily work, that is a maintenance risk. The README also notes support for Stable Diffusion 2.0, Alt-Diffusion, and Segmind Stable Diffusion, but those are listed as features, not as promises of ongoing support. If you adopt this project, you are adopting a codebase that changes slowly and may lag behind new model formats.
Where It Falls Short: VRAM, Security, and Scope
The README claims 4GB video card support, with reports of 2GB working, but that is a claim, not a guarantee. The xformers speedup is only for select cards, so on AMD or Intel hardware you may not get the same performance. The `--allow-code` flag is a glaring security hole if you enable it in a shared environment, since running arbitrary Python from a web UI is inherently risky. The project is also monolithic. It does not offer a node-based workflow like ComfyUI; instead, it is a single page with tabs. That is fine for interactive use, but it makes automation harder. The README lists an API among its features. If you need to integrate image generation into a scripted pipeline, that is the place to start. The project is also heavy: it bundles many upscalers (RealESRGAN, ESRGAN, SwinIR, Swin2SR, LDSR) and face restoration tools (GFPGAN, CodeFormer), which increases download size and memory use even if you only need one.
The Alternative: ComfyUI and the Node-Based Difference
The most direct alternative is ComfyUI, which is also open source but uses a node graph instead of a fixed tabbed interface. The difference is fundamental. In stable-diffusion-webui, you work within predefined modes: txt2img, img2img, inpainting, and so on. In ComfyUI, you connect nodes for loading a checkpoint, sampling, upscaling, and saving. That gives you more control over the data flow, and it makes complex pipelines easier to build and reuse. But it also has a steeper learning curve. If you want a quick start and a familiar UI, stable-diffusion-webui wins. If you want to script a specific workflow or run a headless server, ComfyUI's graph model is often a better fit. The choice is not about which is 'better' but about whether you want a fixed workflow or a custom one.
Who Should Adopt It, Who Should Not, and What to Check First
Adopt stable-diffusion-webui if you are an individual or small team that wants a comprehensive, all-in-one interface for Stable Diffusion, and you are comfortable with the AGPL-3.0 license. It is especially good for learning, because the UI exposes many parameters and the wiki has detailed instructions for different GPU vendors. Do not adopt it if you need a lightweight, embeddable library, or if you must comply with a license that is incompatible with AGPL. Do not adopt it if you need fast, frequent updates to support the latest model architectures; the release cadence is slow. Before you commit, verify three things: that your GPU is supported (check the NVidia, AMD, or Intel wiki pages), that your Python and git versions meet the dependency list, and that you understand what `--allow-code` does if you plan to enable it. Also check the wiki for the current list of extensions, because the core project is stable but the ecosystem is where new features appear. The project is not dead, but it is not moving fast. That is a fact you should weigh before building a workflow around it.
Editorial conclusion
Adopt stable-diffusion-webui if you want a single, familiar interface that covers txt2img, img2img, inpainting, upscaling, and training without leaving the browser, and if you can live with the AGPL-3.0 license and a codebase that moves slowly (last release v1.10.1 in February 2025). Skip it if you need a lightweight, node-based workflow for production pipelines, or if you cannot accept AGPL obligations. Before adopting, verify that your GPU is supported (the README emphasizes NVidia, with AMD and Intel paths via external wikis), and check the wiki for the current dependency list, because the one-click script still requires you to install Python and git yourself.
Frequently asked questions
How do I install the Stable Diffusion web UI?
The README asks you to meet the dependencies on a wiki page and then follow instructions for your hardware, with separate pages for NVidia, marked as recommended, for AMD GPUs and for Intel CPUs and GPUs. The one click install and run script still requires you to install python and git first.
How do I run the Stable Diffusion web UI?
The repository root carries the launchers: webui.sh and webui.bat, webui-user.sh and webui-user.bat, a webui-macos-env.sh environment script, and the Python entry points launch.py and webui.py. The local address the project configures is port 7860, taken from the pytest base_url in pyproject.toml.
How do I update the Stable Diffusion web UI?
Check what has actually shipped: the last commit to the repository was on 2026-03-02, and the newest release tag is v1.10.1 from 2025-02-09, before v1.10.0 in July 2024. CHANGELOG.md at the root is the place to read before assuming a newer version is waiting for you.
How do I use a LoRA in the Stable Diffusion web UI?
Loras are listed alongside hypernetworks and embeddings, described as the same idea but easier to use, and training covers hypernetwork and embedding options. A separate interface lets you choose, with a preview, which embeddings, hypernetworks or Loras to add to your prompt.
How do I open the Stable Diffusion web UI in a browser?
It is a web interface for Stable Diffusion built with the Gradio library, so it serves a page locally once the process is running. The port the project configures for that local page is 7860.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/automatic1111-stable-diffusion-webui)Star history chart for your README
[](https://hysenlabs.com/projects/automatic1111-stable-diffusion-webui)Was this useful?