MockingBird: A Chinese-Focused Voice Cloning Toolbox That Needs Extra Synthesizer Models
🚀Clone a voice in 5 seconds to generate arbitrary speech in real-time
At a glance
- What is it?
- MockingBird clones a voice in seconds using a pretrained encoder and vocoder, but the pretrained synthesizer is not reused, so additional synthesizer models are required. This review covers its setup, real limitations, and why it is not a drop-in tool.
- Who is it for?
- Adopt MockingBird if you need a Chinese-capable voice cloning pipeline and are willing to train or obtain additional synthesizer models, since the pretrained encoder and vocoder are reused but the synthesizer is not. Do not use it if you expect a ready-to-run CLI or a fully pretrained model, because the demo_cli is broken and additional synthesizer models are required.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
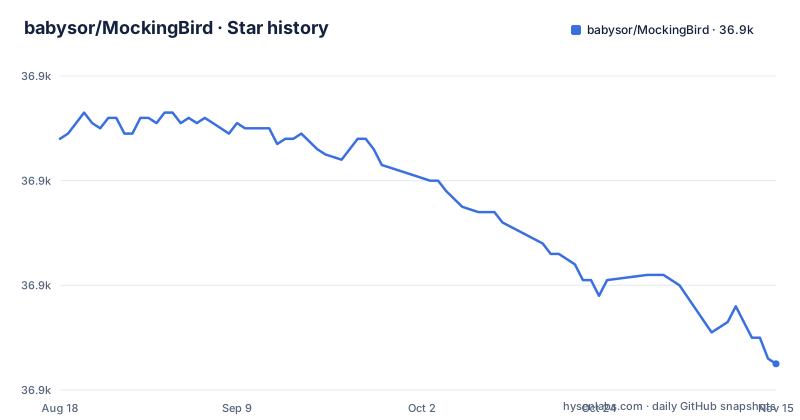
Star history
- babysor/MockingBird36,865 ★ · -43
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| babysor/MockingBird | 36.9k | 36.9k |
-43 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MockingBird Actually Solves
MockingBird addresses a specific gap in open-source voice cloning: support for Chinese (Mandarin) with a real-time inference pipeline. The original Real-Time Voice Cloning project, which MockingBird builds on, was trained with English phonemes and cannot handle Chinese symbols. MockingBird replaces the synthesizer with one trained on Chinese datasets like aidatatang_200zh, magicdata, aishell3, and data_aishell. The project's pitch is that you can clone a voice in five seconds and generate arbitrary speech in real time, but only after you have a working synthesizer. Who is it for? Researchers and developers who need Mandarin TTS cloning and are comfortable training neural models. It is not for a casual user who wants a one-command install and immediate results.
The Three-Model Architecture and Where the Gap Lies
The repository follows the SV2TTS (Speaker Verification to Text-to-Speech) architecture from Real-Time Voice Cloning. There are three components: an encoder that extracts speaker embeddings, a synthesizer that converts text and embeddings into mel spectrograms, and a vocoder that turns spectrograms into audio. MockingBird reuses the pretrained encoder and vocoder from the original project. The synthesizer, however, is not reused. The README says: 'we are using the pretrained encoder/vocoder but not synthesizer, since the original model is incompatible with the Chinese symbols.' This means the demo_cli is not working at the moment, and additional synthesizer models are required. That is the central trade-off: you get a working voice cloning pipeline, but the most training-intensive component is left to you.
Getting It Running: Commands and Configuration
The README gives a clear, if dated, installation path. You need Python 3.7 or higher, but the README warns that a low version causes a torch installation error, and suggests using Python 3.9. Install PyTorch, then ffmpeg, then run 'pip install -r requirements.txt'. The recommended environment is 'Repo Tag 0.0.1', PyTorch 1.9.0, Torchvision 0.10.0, and cudatoolkit 10.2. For M1 Macs, the setup becomes manual: you must install PyQt5 via a Rosetta terminal, compile pyworld from source, and compile ctc-segmentation from its own GitHub repository, with explicit environment variable exports. To run the toolbox, you execute 'demo_toolbox.py', or 'web.py' if you want a web server. Training the encoder is optional: 'python encoder_preprocess.py <datasets_root>' and 'python encoder_train.py my_run <datasets_root>/SV2TTS/encoder'. The point is that the setup is not a single command; it is a series of version-pinned steps that can break with newer libraries.
The M1 Mac Setup Is a Warning, Not a Feature
The README dedicates an entire section to making MockingBird work on Apple Silicon, and the procedure is a long list of workarounds. You create a Rosetta terminal, use the system Python to make a virtual environment, install PyQt5, then manually compile pyworld and ctc-segmentation. The README notes that pyworld and ctc-segmentation are 'unique to this project' and lack wheels, so pip tries to compile from C and fails to find Python.h. For ctc-segmentation, you must clone a separate repository, run cythonize, and build with x86 architecture. This is a genuine failure mode: on any non-x86 system, the install becomes a debugging session. Even on Linux, the README warns that requirements.txt was exported months ago and does not work with newer versions. This is not a tool you can install and forget.
Limitations: Broken CLI, Missing Synthesizer, and Stale Dependencies
The most concrete limitation is that demo_cli is not working. The README states this directly: 'the demo_cli is not working at this moment, so additional synthesizer models are required.' That means the only way to generate speech is through the toolbox GUI or the web server, and only if you have a suitable synthesizer model. Another limitation is the dependency fragility. The README says requirements.txt was exported a few months before it was written and does not work with newer versions, and it recommends specific versions of PyTorch and CUDA. If you use a newer Python or a newer PyTorch, you will likely hit compatibility errors. The author says they no longer actively update this repo, so fixes for newer library versions are unlikely. This is the wrong tool if you need a production-ready service or if you cannot train a synthesizer due to lack of GPU or data. The README mentions GPU models Tesla T4 and GTX 2060, so CPU-only users will have a hard time.
The Real Alternative: Real-Time Voice Cloning
MockingBird is a fork of CorentinJ's Real-Time Voice Cloning (RTVC). The difference is in language support and readiness. RTVC provides pretrained models for all three components, so you can run the toolbox immediately on English speech. MockingBird reuses RTVC's encoder and vocoder but swaps the synthesizer for a Chinese-trained one, which is why the pretrained synthesizer is absent. RTVC uses English-only symbols, so it fails on Chinese text. If you need English, RTVC is the more mature and directly usable option. If you need Chinese, MockingBird is the only one of the two that offers a path, but it needs additional synthesizer models. The trade-off is clear: language coverage versus out-of-the-box functionality.
Maintenance and License Reality
The repository is archived? No, but it is effectively unmaintained. The last push was on March 3, 2026, but the author states in the README: 'I no longer actively update this repo.' There is a single release, v0.0.1, which is described as 'a previous version checkpoint.' The license is listed as NOASSERTION, which means the repository does not declare a standard license. The README shows a badge linking to a choosealicense.com page for MIT, and the repository root contains a LICENSE.txt, but GitHub does not identify a standard license. Read LICENSE.txt for the actual terms before adopting MockingBird. The author points to a commercial cloud version at noiz.ai, which suggests the open-source project is a showcase rather than a maintained product.
Who Should Adopt It, and What to Verify First
MockingBird is for a developer who needs Mandarin voice cloning and is prepared to train or obtain additional synthesizer models. You should have a GPU (the README says it was tested with a Tesla T4 and GTX 2060) and be comfortable with PyTorch 1.9.0. You should also be willing to pin your environment to the exact versions in the README. Do not adopt it if you want a quick demo or a production API. Before you start, verify that your Python is 3.9, that you can install PyTorch 1.9.0+cu102, and that you have a dataset like aidatatang_200zh or magicdata. Also check the license situation, because NOASSERTION is a red flag. The project's own author has moved on to a cloud service, so you are on your own for maintenance. If you are willing to handle that, MockingBird offers a path to Chinese voice cloning with real-time inference.
Editorial conclusion
Adopt MockingBird if you need a Chinese-capable voice cloning pipeline and are willing to train or obtain additional synthesizer models, since the pretrained encoder and vocoder are reused but the synthesizer is not. Do not use it if you expect a ready-to-run CLI or a fully pretrained model, because the demo_cli is broken and additional synthesizer models are required. Before adopting, verify that your Python version is 3.9 or higher, install PyTorch 1.9.0 with CUDA 10.2, and confirm that you can compile pyworld and ctc-segmentation on your OS, especially on M1 Macs where the setup is manual. The author says they no longer actively update the repo, so budget time for dependency pinning and potential code fixes.
Frequently asked questions
Why does the MockingBird demo_cli not work out of the box?
The project reuses the pretrained encoder and vocoder but not the synthesizer, because the original model is incompatible with the Chinese symbols. The stated result is that the demo_cli is not working at this moment and additional synthesizer models are required, so additional synthesizer models are required; you can either train your own or use existing ones.
Which Python and PyTorch version does MockingBird expect?
The toolbox needs Python 3.7 or higher, and the recommended environment is repo tag 0.0.1 with PyTorch 1.9.0, Torchvision 0.10.0 and cudatoolkit 10.2. If pip reports that it cannot find a version satisfying torch==1.9.0+cu102, the documented fix is to use Python 3.9 instead.
Does MockingBird run on Apple silicon M1 chips?
It runs on M1 macOS through a workaround rather than natively. The PyQt5 packages used in demo_toolbox.py are not compatible with M1, so you either skip demo_toolbox.py or use web.py, and the environment is built under a Rosetta Terminal with every command run through arch -x86_64.
How do you train the encoder with your own dataset in MockingBird?
Preprocess the audio and mel spectrograms with `python encoder_preprocess.py <datasets_root>`, adding `--dataset {dataset}` to choose among librispeech_other, voxceleb1 and voxceleb2, where only the train split is used and comma separates multiple datasets. Then run `python encoder_train.py my_run <datasets_root>/SV2TTS/encoder`. Training uses visdom, which you start in a separate process, and `--no_visdom` disables it.
What does the MockingBird Docker setup need from the host machine?
The compose file reserves GPU device 0 with the nvidia driver and publishes port 8080. Training behavior is controlled by DATASET_MIRROR, FORCE_RETRAIN, TRAIN_DATASETS and TRAIN_SKIP_EXISTING, and the image installs ffmpeg, parallel and aria2 on top of pytorch/pytorch:latest.
Which datasets does MockingBird list as tested?
Chinese support covers Mandarin, and the listed datasets are aidatatang_200zh, magicdata, aishell3, data_aishell and others. For the optional encoder training the possible dataset names are librispeech_other, voxceleb1 and voxceleb2.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/babysor-mockingbird)Star history chart for your README
[](https://hysenlabs.com/projects/babysor-mockingbird)Was this useful?