Unlimited OCR 2: Baidu's whole-document OCR model and the GPU memory knobs it comes with
Unlimited OCR parses long documents and images in one pass, producing structured text for document and AI workflows.
At a glance
- What is it?
- baidu/Unlimited-OCR publishes a vision-language OCR model that reads every page of a document in one request, with version 2 bounding attention through SR-SWA. The model is MIT licensed and easy to try; serving it means a CUDA GPU, a customized SGLang wheel and careful memory settings.
- Who is it for?
- Unlimited OCR 2 suits teams that need to turn long, multi-page documents into structured text and have an NVIDIA GPU to run it, either through Transformers for quick tests or SGLang for serving. It does not suit anyone who needs a CPU-only OCR library, a versioned package with GitHub releases, or a stock SGLang install.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
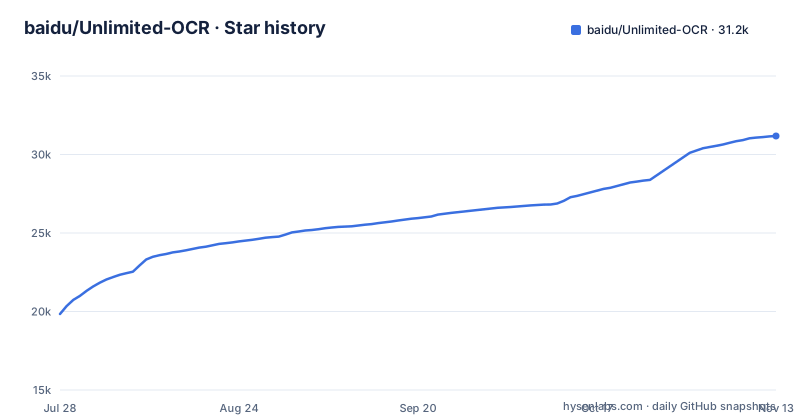
- baidu/Unlimited-OCR31,177 ★ · +11,338
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| baidu/Unlimited-OCR | 19.8k | 31.2k |
11,338 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
SR-SWA keeps decoding cost flat as documents grow
Unlimited OCR is Baidu's document parsing model, released under the MIT license, that takes long documents and images and produces structured text in one pass. The first version, presented on June 22, 2026 and kept on the UnlimitedOCR1.0 branch, was framed as pushing DeepSeek-OCR one step further. Unlimited OCR 2 followed on October 27, 2026, and its paper went up on arXiv on November 2, 2026.
The change in version 2 is Sparse Reference Sliding Window Attention, or SR-SWA. Instead of letting attention between text and visual tokens grow with the whole sequence, it compresses those interactions down to a fixed-size set of working references, for example 512 tokens. The stated effect is that per-step decoding latency and memory stay nearly constant regardless of document length, which is how the project justifies the word unlimited: parsing is unbounded inside a finite context window. Baidu reports state-of-the-art results on both dozens-of-pages benchmarks such as MPDocBench and hundred-page benchmarks such as its own MarathonDocBench, released on Hugging Face on October 27.
The Transformers path was tested on one GPU with pinned versions
The quick-test route is native Transformers. It was tested with Python 3.10 on an NVIDIA A800-80GB, with these exact versions:
pip install torch==2.13.0 torchvision pillow transformers==4.52.1 huggingface-hub==0.36.0 \
  tokenizers==0.21.4 addict==2.4.0 einops==0.8.2 easydict==1.13
The model then loads once:
import torch
from transformers import AutoModel, AutoTokenizer

model_name = "baidu/Unlimited-OCR-2"
tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
model = AutoModel.from_pretrained(model_name, trust_remote_code=True, use_safetensors=True,
                                  torch_dtype=torch.bfloat16).eval().cuda()
Two consequences are in that snippet. The .cuda() call means this path expects an NVIDIA GPU; the only tested configuration is an 80 GB data-center card, and smaller cards are untested territory. And trust_remote_code=True means the model's own Python code from the baidu/Unlimited-OCR-2 repository on Hugging Face runs in your process, so pin and review that code the same way you pin the package versions above.
infer_multi reads a whole document in one request
The multi-page method is what separates this model from page-at-a-time OCR. infer_multi parses all pages of a document in one request so the model can use cross-page context. You pass page images in page order:
pages = [f"your_doc/page_{i}.jpg" for i in range(1, 8)]

text, num_tokens = model.infer_multi(tokenizer, image_files=pages,
                                     output_path="output/multi", save_results=True)
The prompt is built automatically as one <PAGE><image> marker per page followed by Multi page parsing., and each page is encoded as a single global view, called base mode. The output contains one <PAGE> per input page in the same order as image_files, so page order is your responsibility: a shuffled list produces correctly delimited but misordered output. The method takes images, not PDFs, so a PDF has to be rendered to page images first; the SGLang setup adds PyMuPDF for exactly that conversion.
Single pages default to gundam tiling instead of base mode
Single-page inference uses a different encoding. infer encodes one page with dynamic tiling, called gundam mode, by default:
text = model.infer(tokenizer, image_file="your_doc/page_1.jpg",
                   output_path="output/single", save_results=True)
The practical point is that the two methods do not see a page the same way. infer_multi gives each page one global view, while infer tiles a single page dynamically. If you compare results from the two on the same page, differences can come from the encoding mode rather than from cross-page context. The SGLang server exposes the same split with separate page-window settings for gundam and base mode.
SGLang serving depends on a customized wheel shipped in the repository
For serving, SGLang is the recommended path, but not stock SGLang. The setup uses a uv-managed Python 3.10 virtualenv and installs a customized wheel, sglang-0.5.20.dev13+g75b9b06b02, from the repository's wheel/ directory, plus PyMuPDF and fastokens:
uv venv --python 3.10
source .venv/bin/activate

uv pip install wheel/sglang-0.5.20.dev13+g75b9b06b02-py3-none-any.whl
uv pip install pymupdf==1.27.2.2
uv pip install fastokens==0.3.2
The consequence is a dependency you cannot upgrade on your own schedule. The server is tied to a development build of SGLang carried in this repository, so security or performance fixes in upstream SGLang reach you only when Baidu ships a new wheel. Teams that already run a shared SGLang deployment will need a separate environment for this model.
Page windows and output caps are set through environment variables
Very long documents are scheduled in page windows, with the KV tail of the previous window reused. The server start block sets that behavior through environment variables:
export SGLANG_UOCR_EANABLE_DOC_LIMIT=1          # 1 = enable, 0 = whole document in one window
export SGLANG_UOCR_DOC_GUNDAM_PAGE_WINDOW=10    # pages per window (gundam mode)
export SGLANG_UOCR_DOC_BASE_PAGE_WINDOW=10      # pages per window (base mode)
export SGLANG_UOCR_MAX_PAGE_TOKENS=20000        # per-page output cap; must be > 0
Note the spelling of the first variable, EANABLE rather than ENABLE. Copy it as written, because a corrected spelling sets a different variable and leaves the default in place. Setting it to 0 puts the whole document in one window. SGLANG_UOCR_MAX_PAGE_TOKENS caps output per page and must be greater than zero, so a dense page that needs more than 20000 tokens will be cut at that limit unless you raise it.
Default memory settings can run out of GPU memory
The serving notes are candid about memory. The chunk cap for the SAM attention bias defaults to 512, which allows a single allocation of about 462 MiB and can cause an out-of-memory error; a cap of 64 is described as equivalent with a lower peak. --mem-fraction-static sets the share of memory reserved for weights plus KV cache, and 0.75 leaves too little headroom at 32 or more concurrent requests, while 0.7 is stable. --max-prefill-tokens also drives a temporary tensor whose size grows with the prefill token count.
The result is that a working server is a tuning exercise. The defaults are not the safe values, so start from the documented ones and load-test at the concurrency you expect before putting it in front of users.
Distribution lives on model hubs, not GitHub releases
The GitHub repository has no releases. The repository itself is small: infer.py, utils/, the wheel/ directory, assets/, a CONTRIBUTING.md and the Unlimited-OCR-2.pdf paper. The weights are on Hugging Face as baidu/Unlimited-OCR and baidu/Unlimited-OCR-2, on ModelScope as PaddlePaddle/Unlimited-OCR-2, and the model is available on Baidu Cloud. Hosted demos run on Hugging Face Spaces for both versions.
Around the model, the first version gained vLLM inference support on June 28, 2026, and ms-swift supports training, announced for the first version in July and for Unlimited OCR 2 on October 28, 2026. Without tagged releases, version tracking means pinning a Hugging Face model revision and a repository commit yourself. The last push to the repository was on November 2, 2026.
Editorial conclusion
Unlimited OCR 2 suits teams that need to turn long, multi-page documents into structured text and have an NVIDIA GPU to run it, either through Transformers for quick tests or SGLang for serving. It does not suit anyone who needs a CPU-only OCR library, a versioned package with GitHub releases, or a stock SGLang install. Before committing, try the Hugging Face Spaces demo on your own documents, confirm your GPU memory against the documented --mem-fraction-static guidance, and pin the exact package versions listed for each path.
Frequently asked questions
What is Unlimited OCR?
Unlimited OCR is Baidu's MIT-licensed model that parses long documents and images in one pass into structured text. Unlimited OCR 2 uses Sparse Reference Sliding Window Attention to keep decoding latency and memory nearly constant as documents grow.
How do I install Unlimited OCR?
For quick tests, install the pinned Transformers stack (torch==2.13.0, transformers==4.52.1, huggingface-hub==0.36.0 and others) and load baidu/Unlimited-OCR-2 with trust_remote_code=True on a CUDA GPU. For serving, create a Python 3.10 uv environment and install the customized SGLang wheel from the repository's wheel/ directory.
Is Unlimited OCR free?
The Unlimited OCR code is MIT licensed and the weights are downloadable from Hugging Face and ModelScope. Free hosted demos exist on Hugging Face Spaces, and running it yourself needs your own NVIDIA GPU.
Is Unlimited OCR open source?
Yes. The baidu/Unlimited-OCR repository is under the MIT license, the model weights are published on Hugging Face as baidu/Unlimited-OCR and baidu/Unlimited-OCR-2, and both papers are on arXiv.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/baidu-unlimited-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/baidu-unlimited-ocr)Was this useful?