chinese-poetry: A Static JSON Corpus of 300,000 Classical Chinese Poems
GitHub describes it as the most comprehensive database of Chinese poetry, with nearly 14,000 poets from the Tang and Song dynasties, close to 55,000 Tang poems plus 260,000 Song poems, and 1,564 Song-dynasty lyricists with 21,050 ci poems. The repository metadata lists JavaScript as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- This repository packages Tang and Song dynasty poetry into JSON files for developers. It is a data source, not a library, and its only tagged release, v0.1, dates from 2017.
- Who is it for?
- Adopt chinese-poetry if you need a ready-made, MIT-licensed JSON corpus of classical Chinese poetry for a prototype, a static site, or a text-generation experiment. Do not adopt it if you require curated scholarly accuracy, active maintenance, or a structured database with relational queries.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 152 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
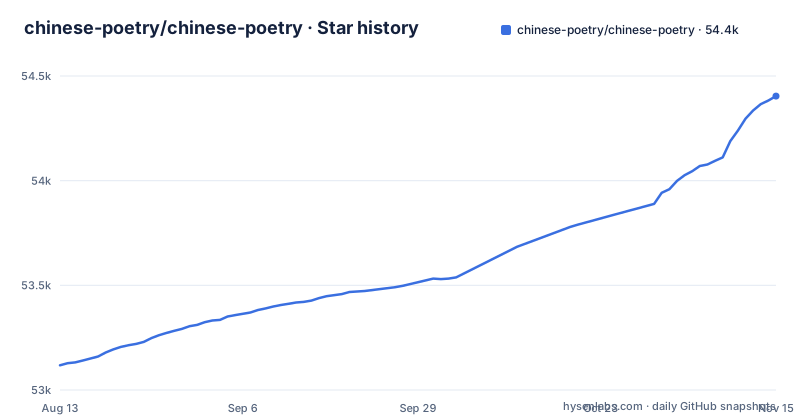
Star history
- chinese-poetry/chinese-poetry54,404 ★ · +1,286
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| chinese-poetry/chinese-poetry | 53.1k | 54.4k |
1,286 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Provides
One important detail is that the repository does not include a schema or documentation for the JSON structure. The README links to a wiki for contribution guidelines, but the actual structure is inferred from the files. You will need to inspect the JSON files yourself to understand the fields. This is a minor friction point, but it is manageable for a static dataset.
The Data Structure and How to Use It
The README mentions that the data was collected without a recorded process, which is a transparency gap. It also notes that the scraping had to be repeated due to interruptions. This suggests that the data may contain inconsistencies or missing entries. For a production application, you would need to validate the data against known sources, which is a significant task. The repository does not offer a checksum or versioning beyond the single v0.1 release from 2017. The v0.1 release is dated May 26, 2017, while the repository's last push was on June 17, 2026. If you need corrections or additions, you would have to fork it and maintain your own version.
Getting Started: Commands and Configuration
Since there is no code to install, the setup is simply cloning the repository. The command is git clone https://github.com/chinese-poetry/chinese-poetry.git. After that, you browse the directories. There are no configuration keys, environment variables, or command-line options to set. The README does not mention any dependencies. The only 'configuration' is your own code that reads the JSON files. The lack of a build system is a plus for simplicity, but it also means there is no automated way to update or transform the data. You must write your own scripts to convert the JSON into a database or an API. The README lists several projects that have done this, such as chinese-poetry-db-web, which integrates the data into MySQL. That project is an example of what you can build, but it is not part of this repository.
Limitations: Static Data, Incomplete Provenance, and No Maintenance
The most obvious limitation is the lack of formal releases: the only tag is v0.1 from 2017, although the repository is not archived and was last pushed on June 17, 2026. Poetry is a fixed historical corpus, so this does not change the poems themselves. The README states that the data comes from the internet, but it does not specify the source websites or the criteria for inclusion. There is a note that '部分有争议性的数据需要社区投票讨论决定是否加入', which means that some controversial data requires community voting. This indicates that the dataset may include poems of disputed authorship or authenticity. For scholarly or educational purposes, you would need to cross-check each poem against a critical edition. Another limitation is the lack of a formal schema. The JSON structure is not documented, so you must reverse-engineer it. This can lead to errors if the structure varies across files. The README does not mention any encoding issues, but Chinese text in JSON can have Unicode normalization problems. You should verify that the files use consistent UTF-8 encoding. Finally, the repository is not a database. If you need to query poems by author, dynasty, or keyword, you must build an index yourself. The README's example projects show that this is possible, but it is extra work.
Alternatives and How They Differ
A direct alternative is the Chinese Text Project (ctext.org), which offers a curated, searchable database of classical Chinese texts. The difference is that ctext.org provides a web interface and APIs, but it is not distributed as a downloadable JSON corpus. You would need to scrape it,. For developers who want a structured database, you could use the chinese-poetry-db-web project, which converts this repository into MySQL. That project is an alternative in the sense that it provides a relational schema, but it is derived from the same source data. If you need a maintained and validated dataset, you might consider building your own from official sources, such as the Quan Tang Shi critical edition. That would be a significant effort, but it would give you control over accuracy. The chinese-poetry repository is the easiest to start with, but it is not the most reliable.
Licence and Maintenance Costs
The repository is licensed under the MIT License, as stated in the README and the LICENSE file. This is permissive, meaning you can use, copy, modify, and redistribute the data with attribution. However, the MIT License covers the code and data as provided by the authors. The underlying poems are ancient texts, likely in the public domain, but the specific JSON formatting and any editorial notes may be subject to copyright. You should review the LICENSE file for exact terms. The repository has published no release since v0.1 in 2017, so do not expect versioned updates. The README mentions a wiki with contribution norms, but it is unclear if that wiki is still maintained. For a long-term project, you should fork the repository and take ownership of the data. This means you are responsible for verifying the accuracy and for any corrections you make. The lack of a release cadence is a benefit in terms of stability, but a drawback in terms of support.
Editorial conclusion
Adopt chinese-poetry if you need a ready-made, MIT-licensed JSON corpus of classical Chinese poetry for a prototype, a static site, or a text-generation experiment. Do not adopt it if you require curated scholarly accuracy, active maintenance, or a structured database with relational queries. Before use, verify the provenance of individual poems, check for encoding consistency across the JSON files, and confirm the license terms for any commercial redistribution. The repository has published no release since v0.1 in 2017, so pin the commit you use.
Frequently asked questions
what is chinese poetry
In this repository, chinese poetry means a database of Chinese classical literature rather than a literary category: 55,000 Tang poems, 260,000 Song poems, 21,000 Song ci, nearly 14,000 Tang and Song poets, and about 1,500 Song ci poets. The data is distributed as JSON under the MIT license, with the project homepage at awesome-poetry.top.
chinese poetry types
The repository separates Tang verse, Song verse, and Song ci, and adds the Five Dynasties Flower Between collection and the Southern Tang rulers' ci as separate links. It also carries the Analects, the Book of Songs, 幽梦影, the Four Books and Five Classics, primer texts, the Nalan Xingde poetry collection, and the Imperial Complete Tang Poems, plus directories for 元曲, 曹操诗集, 楚辞, and 水墨唐诗 that the dataset list does not mention.
What is the oldest collection of chinese poetry?
The repository does not make that claim anywhere. It hosts the Book of Songs, the Analects, the Four Books and Five Classics, primer texts, 幽梦影, the Nalan Xingde poetry collection, the Imperial Complete Tang Poems, a Chu ci directory, and the Tang, Song, and Five Dynasties verse collections, and it leaves the ordering of those to the reader.
does chinese poetry rhyme
The documentation does not describe a rhyme, metre, or pinyin field, because the data is distributed as JSON text without an annotated schema. What it does publish is frequency analysis: high frequency word tables and author work rankings for Tang poems, Song poems, and Song ci, plus a chart of the most popular ci tune names.
what is yijing in chinese poetry
The I Ching is not named in the dataset list. The closest entry is the Four Books and Five Classics directory, and the listed collections otherwise cover Tang verse, Song verse, Song ci, the Five Dynasties collections, the Book of Songs, the Analects, primer texts, and 幽梦影, so a search for a Yijing text would have to go through the 四书五经 directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chinese-poetry-chinese-poetry)Star history chart for your README
[](https://hysenlabs.com/projects/chinese-poetry-chinese-poetry)Was this useful?