Real-Time Voice Cloning: An SV2TTS Pipeline That Still Runs, With Caveats
GitHub describes it as Clone a voice in 5 seconds to generate arbitrary speech in real-time. The repository metadata lists Python as its primary language. The metadata lists the NOASSERTION license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- CorentinJ/Real-Time-Voice-Cloning turns a few seconds of speech into a speaker embedding that drives a Tacotron synthesizer and a WaveRNN vocoder. Its vocoder works in real time, but the README itself admits the audio quality lags behind paid SaaS and newer open-source models.
- Who is it for?
- Adopt this repository if you need a self-contained, local voice cloning pipeline that runs locally and you accept its dated audio quality. Do not adopt it if you need state-of-the-art naturalness or if you cannot spend time debugging Python environment issues.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
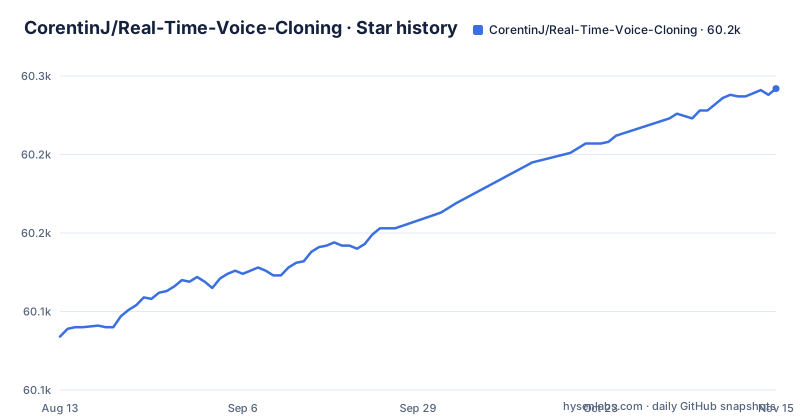
- CorentinJ/Real-Time-Voice-Cloning60,242 ★ · +158
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| CorentinJ/Real-Time-Voice-Cloning | 60.1k | 60.2k |
158 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Solves and Who It Is For
This project answers a specific question: can you clone a voice from a few seconds of audio and then speak arbitrary text in that voice, in real time, on a local machine? The repository description claims a voice can be cloned in 5 seconds. That makes it useful for hobbyists, researchers, and tinkerers who want to experiment with voice cloning without paying for a cloud API. It is not aimed at production teams seeking broadcast-quality output. The README is blunt: many paid SaaS apps give better audio quality. The intended user is someone who wants to understand the SV2TTS architecture, run a full pipeline on their own hardware, and accept the trade-offs.
The SV2TTS Pipeline: Encoder, Synthesizer, Vocoder
The architecture comes from the SV2TTS paper, and this repository implements the encoder itself and credits fatchord/WaveRNN for the synthesizer and vocoder. The first stage is a GE2E encoder that turns a few seconds of audio into a fixed-size speaker embedding. That embedding is the digital representation of the voice. The second stage is a Tacotron synthesizer, which takes the embedding and arbitrary text and produces a mel spectrogram. The third stage is a WaveRNN vocoder, which converts that spectrogram into actual audio waveforms. The vocoder is what makes real-time synthesis possible, because the README says it works in real time. The GE2E encoder comes from this repo; the Tacotron synthesizer and WaveRNN vocoder implementations are credited to fatchord/WaveRNN, as the table in the README shows. The key design choice is transfer learning: the encoder is trained for speaker verification, not synthesis, and that pre-trained representation is what lets the synthesizer generalize to new voices with minimal reference audio.
Getting It Running: uv, ffmpeg, and Two Entry Points
The setup is streamlined compared to older deep learning repos. You need ffmpeg installed for reading audio files, and the README tells you to verify it by running `ffmpeg` in a command line. Then you install uv, either via the PowerShell or curl script, or with `pip install -U uv`. After that, a single command creates a virtual environment and launches the toolbox. For NVIDIA GPUs, run `uv run --extra cuda demo_toolbox.py`. Without a GPU, use `uv run --extra cpu demo_toolbox.py`. There is also a command-line interface: `demo_cli.py` with the same extra flags. uv automatically creates a `.venv` directory with the correct Python environment. Pretrained models are downloaded automatically, with a manual fallback from Hugging Face. The trade-off is that uv is a third-party tool, and if the automatic download fails, you need to know where to put the files.
The Honest Limitation: Audio Quality and Age
The README contains a section titled 'Heads up' that does something rare: it tells you the project is outdated. It says the repo has 'quickly gotten old' and that many paid SaaS apps offer better audio quality. This is the most important limitation to note. The README says that, like everything else in deep learning, the repo has quickly gotten old. It gives no benchmark number, so the gap cannot be quantified, but the author's own warning is enough. This is the wrong tool if you need to generate customer-facing voiceovers or any application where audio quality is a product feature. It is the right tool if you want to study how the three-stage pipeline works, because the repository has separate encoder, synthesizer and vocoder directories.
A Real Alternative: Chatterbox for 2025 SOTA
The README explicitly points to Chatterbox as a similar project that is up to date with 2025 state-of-the-art voice cloning. That is the alternative to consider. Real-Time-Voice-Cloning uses a fixed three-stage pipeline with a speaker embedding from a verification-trained encoder. Chatterbox is described in the README only as a similar project that is up to date with the 2025 SOTA in voice cloning. If you are starting a new project today, the README's own author suggests you look at Chatterbox first. This repo remains useful as a reference implementation of SV2TTS, but not as a competitive tool.
Maintenance, Licensing, and Upgrade Cost
The repository is not archived, and the README covers uv-based setup and automatic model downloads, but the last push was on 2026-03-09 and the repository publishes no releases, so do not expect active feature development. GitHub lists the licence as NOASSERTION, meaning it could not classify it, although a LICENSE file is present at the root. Read that file directly before using the code in any project. The upgrade cost is low in the sense that the repo is self-contained, but the real cost is switching away from it later. If you build a workflow around this pipeline and then outgrow it, you will have to migrate to a different model. The README's own suggestion for newer work is to look at Chatterbox.
Editorial conclusion
Adopt this repository if you need a self-contained, local voice cloning pipeline that runs locally and you accept its dated audio quality. Do not adopt it if you need state-of-the-art naturalness or if you cannot spend time debugging Python environment issues. Before you commit, decide whether you will use the cuda or cpu extra, that ffmpeg is installed, and that the automatic pretrained model download from Hugging Face works on your network. If it fails, you have a manual download path. The project is not archived, but the README's own advice points you to Chatterbox for current SOTA, so treat this as a learning tool or a fallback, not a long-term production solution.
Frequently asked questions
What does the Real-Time-Voice-Cloning toolbox need installed?
ffmpeg, which is necessary for reading audio files, and uv for package management, which creates the .venv automatically. The run command then chooses the cuda or cpu extra, and demo_toolbox.py or demo_cli.py for the GUI or the command line.
Does Real-Time-Voice-Cloning run on Windows and on Linux?
Both are stated as supported, and the uv configuration restricts resolution to Windows and Linux on x86_64 so the lock file does not pick wheels missing on Windows. The installation instructions give separate uv commands for each platform.
Can I run Real-Time-Voice-Cloning without an NVIDIA GPU?
Yes, by using the cpu extra instead of cuda in the run command, for example uv run --extra cpu demo_toolbox.py. The two extras are declared as conflicting so that one is chosen rather than both.
Where do the pretrained models come from?
They are downloaded automatically. If that does not work, the project says to fetch them manually from a Hugging Face repository published by the author, which is where the SV2TTS weights are hosted.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/corentinj-real-time-voice-cloning)Star history chart for your README
[](https://hysenlabs.com/projects/corentinj-real-time-voice-cloning)Was this useful?