Dagster models a data pipeline as Python asset functions, and ships core and libraries on two version lines
An orchestration platform for the development, production, and observation of data assets.
At a glance
- What is it?
- Dagster is an Apache-2.0 orchestrator in which you declare tables, models and reports as decorated Python functions and let it schedule and track them. This piece looks at the asset model, what the quick start installs and leaves out, how releases are numbered, and how the repository tests and deploys itself.
- Who is it for?
- Dagster fits data teams who think in terms of the tables, models and reports they produce and want those declared as Python functions with lineage and a web UI attached. It is a weaker fit for anyone outside Python 3.9 to 3.14, or for a team that only needs a cron replacement for a few scripts.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
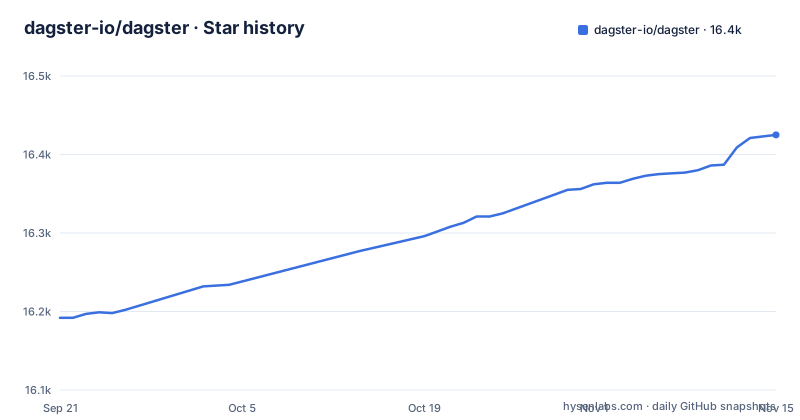
Star history
- dagster-io/dagster16,425 ★ · +233
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| dagster-io/dagster | 16.2k | 16.4k |
233 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
An asset is a decorated function, and its parameters are its upstream edges
Dagster is built around data assets: tables, data sets, machine learning models and reports. You declare each one as a Python function, and Dagster takes on running those functions at the right time and keeping the results up to date. The repository's own example starts like this:
import dagster as dg
import pandas as pd

from sklearn.linear_model import LinearRegression

@dg.asset
def country_populations() -> pd.DataFrame:
    df = pd.read_html("https://tinyurl.com/mry64ebh")[0]
    df.columns = ["country", "pop2022", "pop2023", "change", "continent", "region"]
    df["change"] = df["change"].str.rstrip("%").astype("float")
    return df
The next asset in that example, continent_change_model, takes country_populations as a typed parameter and returns a fitted LinearRegression. That is the whole wiring: there is no separate task list or dependency file in the example, and the graph of three assets that appears in Dagster's web UI comes from the function signatures. The upside is that lineage is a by-product of ordinary code. The cost is that renaming an asset function is a graph change, so every downstream parameter that refers to it has to be renamed in step.
The quick start installs three Dagster packages and none of the example's imports
Dagster is published on PyPI and officially supports Python 3.9 through Python 3.14. The quick start is a single uv command:
uv add dagster dagster-webserver dagster-dg-cliThree packages arrive: the core dagster library, dagster-webserver for the UI, and dagster-dg-cli.
What that line does not cover is the example you just read. The README's asset graph imports pandas and scikit-learn, and neither is in the install command. Copying the example into a fresh project after only the quick start install fails on the imports. The first asset also calls pd.read_html against a tinyurl address, so the example needs network access and depends on a third-party web page keeping the same table layout of six columns. Treat it as an illustration of the model, not as a smoke test of your install. The docs at docs.dagster.io and the ETL pipeline tutorial are the guided starting points.
Core and integration libraries move on two different version numbers
Every Dagster release carries two numbers. The release on 2026-10-30 was 1.13.28 for core and 0.29.28 for libraries; 1.13.27 and 0.29.27 shipped on 2026-10-26, and 1.13.26 and 0.29.26 on 2026-10-09. The patch digits line up, but the major and minor do not, so a core version does not tell you its matching library version at a glance.
For anyone pinning dependencies, this is the practical trap. Integration packages sit on the 0.x line while core sits on 1.x, and upgrading one without the other means mixing versions from different releases. Pin them as a pair taken from the same release. The repository keeps CHANGES.md and MIGRATION.md at the top level, and with the last three releases arriving 17 days and then 4 days apart, reading them before an upgrade is part of running Dagster rather than an occasional chore. The last push to the master branch was on 2026-10-30.
Instance storage and code locations are tested against SQLite, Postgres and gRPC servers
The pytest markers in pyproject.toml show which runtime shapes the project exercises. The dagster-graphql context test suite builds its context from groups of markers, including sqlite_instance for a context backed by a SQLite instance, postgres_instance for one backed by Postgres, and asset_aware_instance. Code locations are tested both as managed_grpc_env, a code location served by a managed gRPC server, and as deployed_grpc_env.
For a reader planning a deployment, this is a useful map of what Dagster's own CI treats as first-class: a SQLite-backed instance, a Postgres-backed one, and user code served over gRPC separately from the instance. Other markers separate integration tests that need real git operations or other I/O, slow tests that take more than one second, and nettest for tests that need network access. Deselecting the slow ones uses the form given in the config comments:
pytest -m "not slow"Deployment patterns live in the examples directory and a Helm chart
The README stays at the level of the asset model and links outward for everything operational. The repository itself carries the concrete material. The examples directory has deploy_docker, deploy_ecs and deploy_k8s for container, Amazon ECS and Kubernetes setups, development_to_production for moving a project between environments, and a top-level helm directory. Further examples cover dbt with Python assets, dynamic partitions, pandas with PySpark, data quality patterns, ingestion patterns, and Databricks with Snowflake.
The consequence is that evaluating Dagster for production means reading those example projects rather than the front page. The integrations themselves are listed at dagster.io/integrations. If your stack includes a tool not covered there, the asset functions that talk to it are yours to write and maintain.
The contributor toolchain runs on just, Buildkite, ruff and ty
Contributors meet a different toolchain from users. CI recipes sit in a justfile that replaced the equivalent Makefile targets. The stated reason is specific: just propagates signal exit codes such as 130 for SIGINT and 143 for SIGTERM instead of masking them, which lets Buildkite's automatic retry detect infrastructure failures like spot instance reclamation.
Linting is ruff, run as both a check and a format check:
ruff check .
ruff format --check .
Prettier formats YAML under python_modules and helm plus Markdown files, excluding docs and Helm templates. Type checking uses ty through scripts/run-ty.py, with a quick-ty recipe that checks only files changed against origin/master, and each ty recipe raises the open file limit with ulimit -Sn 4096 first. pytest runs with --strict-markers, so a misspelled marker is an error rather than a silently skipped test. The contributing guide on docs.dagster.io covers running the project for development.
One package spans local runs, tests and production
Dagster's stated goal is to be used at every stage of the data development lifecycle: local development, unit tests, integration tests, staging environments and production. Testability is pitched alongside the asset model, and the production side is described as a multi-tenant, multi-tool engine, so the same project definitions are meant to move from a laptop through staging into production.
The trade is commitment. Dagster wants to be the place where your metadata, lineage, cataloging and observability live, which is the point of calling itself a control plane. That is valuable when many assets and many people share one platform. For a small team with a handful of scheduled scripts, adopting the asset model, the web server and the instance storage is more structure than the problem requires.
Editorial conclusion
Dagster fits data teams who think in terms of the tables, models and reports they produce and want those declared as Python functions with lineage and a web UI attached. It is a weaker fit for anyone outside Python 3.9 to 3.14, or for a team that only needs a cron replacement for a few scripts. Before adopting it, pin the core and library versions as a matched pair, read MIGRATION.md for the release you land on, and add the packages your own assets import, since the quick start installs only Dagster itself.
Frequently asked questions
What is Dagster used for?
Dagster orchestrates data pipelines built around data assets such as tables, data sets, machine learning models and reports. You declare each asset as a Python function, and Dagster runs them at the right time and keeps them up to date.
Is Dagster Python based?
Yes. Dagster assets are Python functions decorated with @dg.asset, the package is published on PyPI, and it officially supports Python 3.9 through Python 3.14.
How do I install Dagster?
Run uv add dagster dagster-webserver dagster-dg-cli in a uv project. That installs the core library, the web UI server and dagster-dg-cli.
Does Dagster cost money?
The Dagster open-source project in dagster-io/dagster is licensed under Apache 2.0 and installed from PyPI, so the code itself is free to use.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dagster-io-dagster)Star history chart for your README
[](https://hysenlabs.com/projects/dagster-io-dagster)Was this useful?