The Data Engineering Handbook: A Curated Portal, Not a Course
GitHub describes it as This is a repo with links to everything you'd ever want to learn about data engineering. The repository metadata lists Jupyter Notebook as its primary language. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- DataExpert-io/data-engineer-handbook is a GitHub repository that aggregates books, communities, boot camps, tools, and blogs for data engineers. It is a directory of links, not a tutorial, and its value depends entirely on how you use the external resources it points to.
- Who is it for?
- Adopt this handbook if you are a beginner or intermediate data engineer looking for a single, well-organized index of high-quality external resources, including free boot camps, books, and tool lists. Skip it if you expect interactive tutorials or in-depth explanations, because the repo contains only links and brief pointers.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 104 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
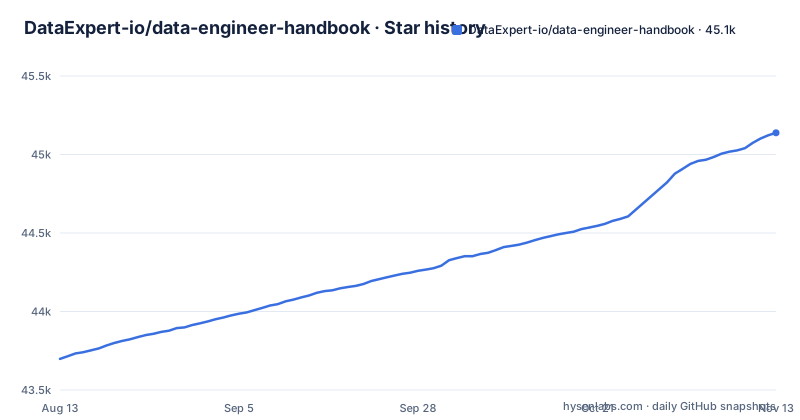
- DataExpert-io/data-engineer-handbook45,138 ★ · +1,440
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| DataExpert-io/data-engineer-handbook | 43.7k | 45.1k |
1,440 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Is
The Data Engineering Handbook is a GitHub repository that functions as a curated directory of resources for data engineers. Most of it is links rather than tutorials, although it also holds boot camp folders. Instead, it lists links to books, communities, boot camps, tools, and blogs, organized by category. The README opens with a claim that it has 'all the resources you need to become an amazing data engineer,' but that is an overstatement. What it offers is a starting point: a handpicked set of external materials that the maintainer considers high quality. The repository's primary language is listed as Jupyter Notebook, which is odd for a link collection, but that likely reflects the presence of notebooks in the beginner or intermediate boot camp folders. The actual content is mostly Markdown files, as seen in references to files like 'beginner-bootcamp/introduction.md' and 'projects.md'. For someone new to the field, this is a useful map; for someone expecting a self-contained learning path, it will disappoint.
The Core Mechanism: Curated Lists and External Links
The repository works by pointing you to external resources. The README lists over 25 books, with the top three being 'Fundamentals of Data Engineering', 'Designing Data-Intensive Applications', and 'Designing Machine Learning Systems'. It also lists over 10 communities, including Discord servers and Slacks like DataExpert.io Community and Data Talks Club. The bulk of the README is a categorized list of companies and tools: orchestration tools like Airflow and Dagster, data lake solutions like Delta Lake and Apache Iceberg, data warehouses like Snowflake, data quality tools like dbt and Great Expectations, and analytics platforms like Metabase and Superset. Each entry is just a name and a link; there is no explanation of what each tool does or when to use it. That is a deliberate design choice: the repository is an index, not a textbook. The data flow is simple: you read the list, click a link, and learn from the source. This works well if you already know what you are looking for, but it offers little guidance for a beginner who does not know the difference between a data lake and a warehouse.
Getting Started: The Boot Camp Path
The README provides clear instructions for getting started. If you are new to data engineering, it directs you to a '2024 breaking into data engineering roadmap' on the DataExpert blog. For hands-on learning, it points to two free boot camps: a 4-week beginner boot camp and a 6-week intermediate boot camp. Each has its own folder in the repository, with files like 'introduction.md' and 'software.md'. The README also links to a one-week Databricks AI boot camp on August 3rd, with a signup for Databricks Free Edition. To use the repository, you simply clone or browse it on GitHub, open the relevant Markdown files, and follow the links. There are no installation commands or configuration keys, because the repository is not a software project. The only 'setup' is having a web browser and a GitHub account. This is both a strength and a weakness: it lowers the barrier to entry, but it also means the repository cannot teach you anything by itself.
The Limitations: Stale Links and Missing Depth
The most obvious limitation is that the repository is only as good as its links. The README promotes a boot camp on August 3rd, and the last push was on 2026-08-03, so that event has already passed. Similarly, many links point to external sites that could change or disappear. It is a static list. Another limitation is the lack of depth. For example, the tools list includes 'DuckLake' with a link to 'ducklake.select', which is a separate entry from DuckDB, listed under Modern OLAP. For a beginner, this can be confusing: you might click a link and land on a dead page, or you might not know which tools are essential versus optional. The repository also has no interactive elements, and no quizzes. If you need structured guidance, this is the wrong tool.
Alternatives: Structured Courses and Interactive Platforms
The most direct alternative is a structured online course, such as the boot camps that the repository itself links to. These provide a sequential curriculum, deadlines, and often instructor feedback. Another alternative is a platform like DataCamp or Coursera, which offers interactive exercises and assessments. The difference is in approach: the handbook is a passive directory, while a course is an active learning experience. If you prefer a more community-driven approach, the Data Talks Club Slack is another alternative, listed in the README's communities. The key distinction is that the handbook requires you to self-direct your learning, whereas courses and communities provide structure and accountability. For a self-motivated learner, the handbook is sufficient; for someone who needs external pressure, a course is better.
Maintenance and License Considerations
The repository's license is listed as unknown, which is a red flag for anyone planning to reuse its content. The repository metadata shows no declared license, so reuse rights are unclear. This is a practical concern if you want to create a derivative resource. The last push was on 2026-08-03, the repository is not archived, and it has no GitHub releases, so check how recently the lists were updated. For maintenance, you should check the repository periodically for updates, but there is no clear signal of when that happens. The maintenance cost is low for a user, but the risk of outdated links is real.
Who Should Use This Handbook
This handbook is best suited for a beginner who wants a curated list of high-quality resources without having to search the web. It is also useful for an intermediate data engineer who wants to discover new tools or communities. The books section alone is worth the visit, as it includes classics like 'Designing Data-Intensive Applications'. The communities section is also valuable, as it lists active Discords and Slacks where you can ask questions. However, if you are a complete novice with no prior knowledge, you may feel overwhelmed by the sheer number of links and the lack of guidance on where to start. The README does provide a roadmap, but it is a single link. For that reason, I would recommend pairing this handbook with a structured course, such as the free boot camps it links to. The handbook is a supplement, not a replacement for a curriculum.
Editorial conclusion
Adopt this handbook if you are a beginner or intermediate data engineer looking for a single, well-organized index of high-quality external resources, including free boot camps, books, and tool lists. Skip it if you expect interactive tutorials or in-depth explanations, because the repo contains only links and brief pointers. Before relying on it, verify that the external links are still active and that the boot camp schedules match your availability, since the README promotes specific dated events that may expire. The handbook is a starting point, not a destination; its real value is in the curated curation, so check the linked resources themselves for depth.
Frequently asked questions
What is the Data Engineering Handbook?
It is a curated repository of links for learning data engineering, described as everything you would want to learn about the field. The README groups companies by category and links books, communities, company engineering blogs and whitepapers, with separate files for projects, interviews, newsletters, data cleaning, books and communities.
Which orchestration tools does the Data Engineering Handbook list?
The Orchestration group holds Mage, Astronomer, Prefect, Dagster, Airflow, Kestra, Shipyard and Hamilton, with no further guidance on choosing between them. Other groups cover data lake and cloud, data warehouse, data quality, education, analytics and visualization, data integration, semantic layers, modern OLAP, LLM application libraries, real-time data and data lineage.
Does the Data Engineering Handbook teach the tools or only link to them?
It links. The lists need nothing installed, since they are Markdown files and folders, including the book, community, project, interview, newsletter and data cleaning files. The closest thing to instruction is in the boot camp folders, which hold an introduction and a software list for the beginner and intermediate cohorts.
What is in the boot camp folders of the Data Engineering Handbook?
The README links beginner-bootcamp/introduction.md and beginner-bootcamp/software.md for the 4-week free beginner boot camp, and intermediate-bootcamp/introduction.md and intermediate-bootcamp/software.md for the 6-week free intermediate community boot camp. A separate databricks-ai-bootcamp folder exists, and the README advertises a Databricks AI boot camp alongside a Databricks Free Edition signup.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dataexpert-io-data-engineer-handbook)Star history chart for your README
[](https://hysenlabs.com/projects/dataexpert-io-data-engineer-handbook)Was this useful?