Marker: A PDF-to-Markdown Converter That Picks Its Battles
GitHub describes it as Convert PDF to markdown + JSON quickly with high accuracy. The repository metadata lists Python as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Marker converts PDFs and other document types into markdown and JSON using a hybrid of text-layer extraction and a local VLM server. It offers a fast mode for CPU users and an optional LLM pass, but the real question is whether the accuracy gains justify the infrastructure.
- Who is it for?
- Marker is for teams that need high-fidelity markdown from heterogeneous PDFs and are willing to run a local VLM server on GPU or CPU. It is not for those who want a zero-dependency text extractor or who cannot manage the vllm/llama.cpp backend.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
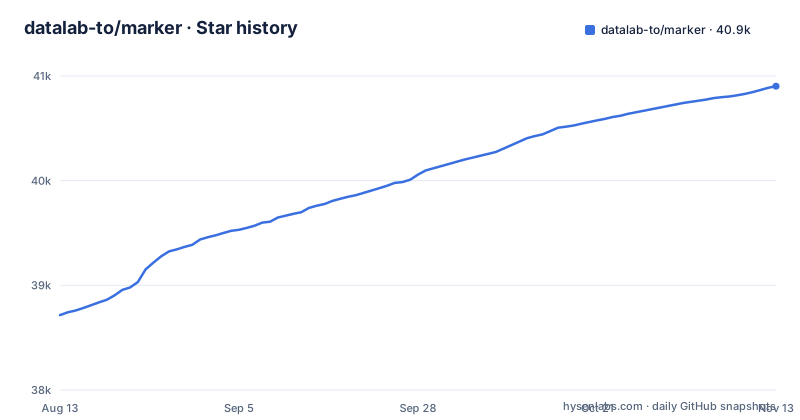
- datalab-to/marker40,903 ★ · +2,187
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| datalab-to/marker | 38.7k | 40.9k |
2,187 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Marker Actually Solves
The core value proposition is accuracy without a cloud dependency. Marker runs everything locally, including the VLM server, which matters for organizations with data retention constraints. The managed platform exists as a separate commercial offering, that uses Chandra and other models and is described as higher accuracy than Marker. That local-first design is both the strength and the operational burden, as the next section explains.
The Hybrid Architecture: Text Layer Plus a Local VLM Server
Marker does not OCR everything blindly. It uses a two-tier approach. In fast mode, it starts with the PDF text layer using pdftext, and only invokes the VLM for specific repairs: equations, surgical block-level fixes for garbled or empty blocks, and a single full-page pass for scanned pages or pages that are mostly bad. Balanced mode, which is the default on GPU, uses the surya VLM for layout and re-OCRs the whole page whenever any embedded text is bad. Both modes reconstruct tables from the text layer, with low-confidence reconstructions falling back to the VLM. The key insight is that the VLM is not always running. A clean digital document without equations never starts the VLM server in fast mode, according to the README. That is a deliberate trade-off: you sacrifice some layout accuracy on complex pages to avoid the latency and resource cost of a full VLM pass on every page. The `--disable_ocr` flag turns off all VLM calls, including equations, giving you a pure text-layer extraction path. This is a useful escape hatch for simple documents where OCR would be overkill.
Getting It Running: Installation and Backend Prerequisites
Installation is straightforward with pip: `pip install marker-pdf` for PDFs only, or `pip install marker-pdf[full]` for other document types. You need Python 3.10+ and PyTorch. The real setup complexity is the inference backend. Surya, the VLM, auto-spawns a local server on first use. On NVIDIA GPUs, you need Docker and the NVIDIA Container Toolkit, and the server runs through vLLM. On CPU or Apple Silicon, you need the `llama-server` binary from llama.cpp, installable via `brew install llama.cpp` on macOS. You can also point Marker at an already-running server with `SURYA_INFERENCE_URL=http://host:port/v1`. That is a practical option for teams that want to centralize the model server. The default mode depends on your device: balanced on GPU, fast on CPU/MPS. This is a sensible default, but it means a laptop user gets lower accuracy unless they explicitly pass `--mode balanced` and have a GPU.
The LLM Hybrid: When You Need More Than Local Models
For the highest accuracy, Marker offers a `--use_llm` flag that runs an LLM alongside the VLM. This is not a replacement for the VLM; it is an additional pass that handles tasks the VLM struggles with, such as merging tables across pages, handling inline math, formatting tables properly, and extracting values from forms. The README lists Gemini, Claude, OpenAI-compatible, Azure, Vertex, OpenRouter, and Ollama as supported providers, with `gemini-3.5-flash` as the default. This is a significant operational decision. You are no longer running a purely local pipeline. You are sending document content to an external API, which raises data privacy questions. The hybrid mode is optional, but the fact that Marker ships it as a separate flag suggests that the base model alone is not sufficient for all documents. If your workload includes complex tables or forms, you will likely need this flag, and you must budget for API costs.
Known Limitations and Wrong-Use Cases
Marker is not a universal document converter. The README is honest about the fact that fast mode is optimized for CPU and keeps VLM use minimal, but that means a scanned document with heavy math will trigger the full-page OCR pass. The `--disable_ocr` flag turns off all VLM calls, but then you get only the text layer, which is useless for scanned PDFs. So the tool has a clear failure mode: if you have a mix of born-digital and scanned documents, you must choose a mode that handles the worst case, and that choice affects speed on the best case. Another limitation is the model weights license. The code is Apache-2.0, but the weights use a modified AI Pubs Open Rail-M license that is free for research, personal use, and startups under $5M funding/revenue. For commercial use beyond that, you need a paid license. This is a real constraint for enterprises that want to embed Marker in a commercial product. If your documents are simple, single-column text PDFs, a tool like `pdftotext` or a simple text extraction library will be faster and simpler. Marker is overkill for that use case.
Alternatives: MinerU, Docling, and the Trade-Offs
The README explicitly names MinerU and docling as competitors in the benchmark comparison. The key difference is that Marker gives you a binary choice: a cheap text-layer path and an expensive VLM path, with a hybrid mode that selectively applies the VLM. If you have a GPU and need the highest accuracy on complex layouts, Marker's balanced mode is designed for that, but you must manage the vLLM Docker setup. The right choice depends on your hardware and document mix.
Maintenance, Upgrade Cost, and License Implications
Marker is actively developed, with a v2.1.0 release on 2026-10-29, a v2.0.0 release on 2026-07-20 and v1.10.2 on 2026-01-31. The jump from v1.10.2 to v2.0.0 suggests a significant change, so you should check the release notes before upgrading. The main maintenance cost is the inference server. For a startup under $5M funding, it is free; for a larger company, you need to evaluate the commercial license terms. Check the licence terms before production use. The managed platform is a way to avoid that, but it is a paid service.
Editorial conclusion
Marker is for teams that need high-fidelity markdown from heterogeneous PDFs and are willing to run a local VLM server on GPU or CPU. It is not for those who want a zero-dependency text extractor or who cannot manage the vllm/llama.cpp backend. Before adopting, verify that your document mix (born-digital vs scanned, math-heavy vs plain text) matches the benchmark categories, and test the fast mode on your own files to see if the VLM fallback triggers too often. Also confirm the model weights license terms if you exceed the startup threshold, since the code is Apache-2.0 but the weights carry a separate restriction.
Frequently asked questions
What does "marker" mean in English?
In this repository, Marker is a document converter. The Python package is named marker-pdf and is installed with `pip install marker-pdf`.
how to install marker lights on a trailer
Trailer lights are a different meaning of the word entirely. This project is a Python package that needs python 3.10+ and PyTorch, installed with `pip install marker-pdf`, or with `pip install marker-pdf[full]` if you want to handle documents other than PDFs.
What is a marker?
In this repository it is a document converter that turns PDF, image, PPTX, DOCX, XLSX, HTML and EPUB files in all languages into markdown, JSON, chunks and HTML. It formats tables, forms, equations, inline math, links, references and code blocks, extracts and saves images, removes headers and footers, and runs on GPU, CPU or MPS.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Convert PDF to Markdown and JSONHacker News · Nov 12, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datalab-to-marker)Star history chart for your README
[](https://hysenlabs.com/projects/datalab-to-marker)Was this useful?