Data Engineering Zoomcamp: A Free 9-Week Pipeline Course Worth Your Time
GitHub describes it as Data Engineering Zoomcamp is a free 9-week course on building production-ready data pipelines. The next cohort starts in January 2026. Join the course here 👇🏼. The repository metadata lists Jupyter Notebook as its primary language. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- DataTalksClub's Data Engineering Zoomcamp is a free, cohort-based course that walks you through building a production-grade data pipeline with Docker, Terraform, Kestra, BigQuery, dbt, Spark, and Kafka. It is not a tool tutorial; it is a structured curriculum with homework, peer review, and a certificate.
- Who is it for?
- Adopt this course if you are a developer, analyst, or data scientist with basic coding and SQL who wants a structured, free path into data engineering. Skip it if you need live instruction or prefer to learn by building your own projects without deadlines.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 30 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
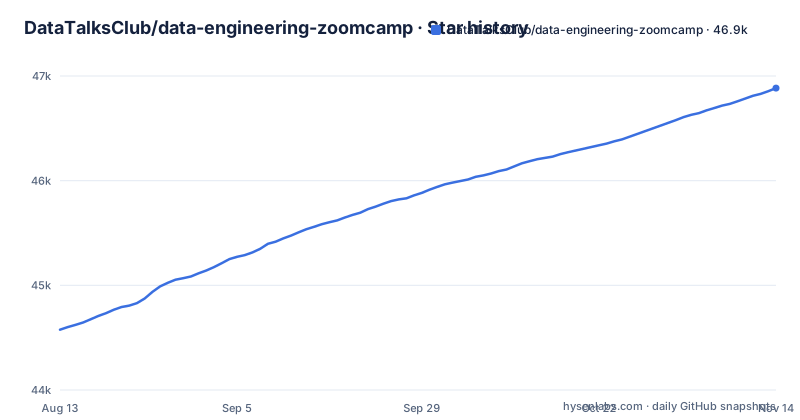
Star history
- DataTalksClub/data-engineering-zoomcamp46,884 ★ · +2,308
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| DataTalksClub/data-engineering-zoomcamp | 44.6k | 46.9k |
2,308 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Course Actually Solves
Data Engineering Zoomcamp addresses a specific gap: many developers and analysts know how to write code but have no map for the modern data engineering stack. The course gives you a 9-week path to build an end-to-end data pipeline from scratch. It is aimed at developers, analysts, and data scientists who want to move into data engineering. The README states that no prior data engineering experience is necessary, but it does require basic coding and familiarity with SQL. This is not a theoretical survey. Several modules and the workshop list homework, and the final project forces you to apply everything. The course is free, which removes a financial barrier, but the real value is the structure: a syllabus, deadlines, and peer review that you would not get from random YouTube tutorials.
The Architecture of the Course: Modules and Tools
The syllabus is organized into seven modules plus a workshop and a final project. Module 1 covers containerization with Docker and infrastructure as code with Terraform, using Google Cloud Platform. Module 2 moves to workflow orchestration with Kestra, which is a newer choice compared to Airflow. Workshop 1 focuses on data ingestion using dlt, covering API reading, normalization, and incremental loading. Module 3 introduces BigQuery, including partitioning, clustering, and machine learning inside the warehouse. Module 4 covers analytics engineering with dbt, using DuckDB and BigQuery. Module 5 is about building end-to-end pipelines with Bruin, a tool that combines ingestion, transformation, and quality checks. Module 6 dives into Apache Spark, covering DataFrames, SQL, and the internals of GroupBy and Joins. Module 7 deals with streaming using Kafka, Kafka Streams, KSQL, and Avro schema management. The progression is logical: you start with infrastructure, then orchestration, then storage, then transformation, then batch and streaming. The tools are not all industry-standard; Kestra and Bruin are less established than Airflow or dbt, but they represent a modern, lighter-weight approach. The final project applies the concepts learned in a real-world scenario, including a peer review and feedback process.
Live Cohort vs Self-Paced: The Real Difference
The README makes a clear distinction between the live cohort and self-paced learning. The live cohort starts in January 2027 (the description mentions January 2026, but the README table says January 2027, so check the registration page). All lectures are pre-recorded in both modes. The difference is the surrounding structure. In the live cohort, homework is graded, there is a leaderboard, peer review, and you can earn a certificate. Self-paced learners get the same materials but no grading, no leaderboard, no peer review, and no certificate. The README explicitly warns that 'live' does not mean live classes. This is a crucial point for anyone expecting interactive sessions. The live cohort is essentially a shared schedule with accountability mechanisms. If you are the type who needs external deadlines, the live cohort is worth the wait. If you prefer to go at your own pace, the self-paced option is always available, but you lose the certification and the peer feedback. The certificate is only awarded to learners who complete the final project during a live cohort, so that is a concrete incentive to join the cohort.
Getting Started: Commands and Setup
The course repository is organized by module folders, such as 01-docker-terraform, 02-workflow-orchestration, and 03-data-warehouse. To start, you clone the repository and follow the README in each module. The first module introduces Docker and Docker Compose, so you will need Docker installed. You will run PostgreSQL in a container using docker-compose. Terraform is used to provision GCP resources, so you need a GCP account and credentials. The module folders (01-docker-terraform, 02-workflow-orchestration and so on) hold the materials for each step. The course also directs you to register on the course platform at courses.datatalks.club to access deadlines and homework. Joining the Slack channel is recommended for questions. The prerequisites are basic coding and SQL, so you should be comfortable with the command line and writing simple queries before starting.
Limitations and Failure Modes
The most obvious limitation is that the course is not a live class. If you learn better with real-time interaction, this will feel like a self-study course with a schedule. Another limitation is the tool selection. The course uses Kestra and Bruin, which are not as widely adopted as Airflow or dbt. If your goal is to learn the most marketable skills, you might want to supplement with Airflow. The course also relies heavily on Google Cloud Platform, specifically BigQuery. If your organization uses AWS or Azure, you will need to translate the concepts. The final project requires peer review, which is only available in the live cohort. Self-paced learners miss that feedback loop. There is also a time commitment: 9 weeks is short, but the homework and project can be demanding. The README includes a testimonial that says the course was 'really hard', so do not underestimate the workload. Finally, the certificate is not a formal qualification; it is a completion certificate. It may help in job applications, but it is not a substitute for real-world experience.
Alternatives: What Else Is Out There
The main alternative to Data Engineering Zoomcamp is the self-paced path of building your own projects using official documentation and tutorials. That approach gives you full control over the tools and data, but it lacks the curriculum structure and community support. Another alternative is a paid bootcamp or online specialization, which costs money. The key difference is that Zoomcamp is free and community-driven, with a Slack channel and a Telegram channel for announcements. It also has a specific focus on a modern stack: Docker, Terraform, Kestra, BigQuery, dbt, Spark, and Kafka. If you want a free, structured introduction, Zoomcamp is hard to beat. If you need a credential that employers recognize, a paid program might be better. The course materials remain in the repository, so you can always start the self-paced version and then join a later cohort for the certificate.
Maintenance and Upgrade Cost
The repository is actively maintained, as indicated by the fact that it is not archived and the default branch is main. The README shows cohorts for 2026 and 2027, which means the course is updated regularly. The syllabus lists Kestra for orchestration and Bruin for the data platforms module. GitHub reports no licence for this repository and the top-level file list has no license file, so check with the maintainers before reusing the materials. For a course, this is not a big issue if you are just learning, but if you want to adapt the materials for your own training, you should contact the maintainers. The cost of upgrading is mainly time: you need to keep up with the changes in the tools. The course is free, but the cloud costs for GCP and BigQuery can add up if you are not careful. Budget for cloud costs.
Editorial conclusion
Adopt this course if you are a developer, analyst, or data scientist with basic coding and SQL who wants a structured, free path into data engineering. Skip it if you need live instruction or prefer to learn by building your own projects without deadlines. Before joining, verify the January 2027 cohort dates on the registration page and check the Telegram announcements channel. The course is a solid, community-driven starting point, but it is not a substitute for hands-on work with your own data.
Frequently asked questions
What is the Data Engineering Zoomcamp?
A free 9-week course on data engineering that has you build an end-to-end data pipeline from scratch, structured as modules, hands-on workshops and a final project. It is aimed at developers, analysts and data scientists, and the repository says no prior data engineering experience is necessary.
Is the Data Engineering Zoomcamp good?
All lectures are pre-recorded on both the live and self-paced tracks, so the difference is structure rather than teaching. The live cohort adds deadlines, scored homework, a leaderboard, peer review and a certificate, while the self-paced track gives you the same materials with homework available but not scored.
Is the Data Engineering Zoomcamp worth it?
It costs nothing on either track, and the self-paced steps are to follow the materials on GitHub, ask questions in Slack, and do self-checked homework plus a project for your portfolio. A certificate is awarded only to learners who complete the final project during a live cohort, and that final project includes a peer review and feedback process.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datatalksclub-data-engineering-zoomcamp)Star history chart for your README
[](https://hysenlabs.com/projects/datatalksclub-data-engineering-zoomcamp)Was this useful?