DeepJIT: a header-only C++20 JIT runtime for CUDA and Ascend kernels
A lightweight library for xPU kernel JIT compilation
At a glance
- What is it?
- DeepJIT gives C++ and Python extension authors one compile, cache, load and launch interface across NVIDIA CUDA GPUs and Huawei Ascend NPUs. The trade-off is that it is still a WIP project with no releases and no documented licence.
- Who is it for?
- Adopt DeepJIT if you maintain a kernel library that must ship the same compile, cache and launch path on both CUDA and Ascend, and you are willing to vendor headers from a repository with no tagged releases and an undocumented licence. Do not adopt it if you need a stable versioned dependency, a documented licence before you ship, or an officially supported Windows build, since the README states the host environment must provide Linux.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
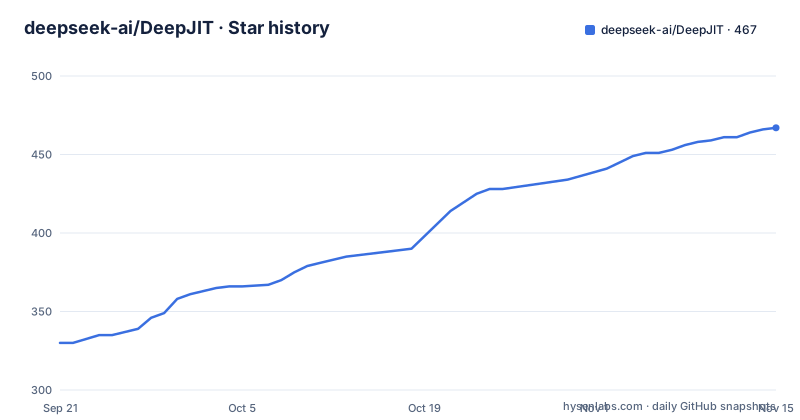
Star history
- deepseek-ai/DeepJIT467 ★ · +137
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| deepseek-ai/DeepJIT | 330 | 467 |
137 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem DeepJIT solves: two device backends, one compile and launch path
Kernel libraries that target more than one accelerator usually end up with two parallel code paths. One compiles CUDA source with NVCC, loads the resulting CUBIN through the CUDA Driver API and launches it with CUDA-specific options. Another drives Bisheng and ld.lld for Ascend, loads through ACL and carries a different set of launch options. The device code differs anyway. The infrastructure around it does not have to.
DeepJIT is aimed at that infrastructure layer. The README describes it as a lightweight, header-only C++20 JIT runtime for NVIDIA CUDA GPUs and HUAWEI Ascend NPUs, giving C++ and Python extension authors a shared interface for compiling kernel source at runtime, caching the resulting binaries, loading them onto the device and launching them. The intended audience is narrow and specific: people writing kernel libraries or PyTorch extensions who want to stop maintaining two cache implementations and two lazy-initialization schemes.
The project is not a kernel language and not a compiler. Kernel source and compiler and launch options stay backend-specific, which the README states explicitly. What is shared is the runtime configuration, source and include hashing, the in-memory and on-disk caches, and lazy initialization.
How the runtime, the cache keys and the shared disk cache fit together
The architecture splits into four directories under include/deep_jit. runtime/ holds the shared runtime and configuration. backend/cuda/ and backend/ascend/ hold the compiler integration, device queries, kernel loading and launch options for each target. cache/ holds the in-memory and on-disk kernel caches. python_api.hpp registers a consumer library's runtime through pybind11.
A consumer includes exactly one backend entry header, and that header exposes its backend type. The runtime is a template parameterized on the backend, so the workflow is written once and instantiated twice. Lazy initialization is the default posture: create_lazy_jit defers construction of the runtime until first use, which also defers device and compiler discovery. In a library loaded into a process that may never touch a device, that matters.
The cache design is the part worth reading closely. Cache keys account for source, tracked includes, compiler versions, effective compiler options and an application-provided dependency signature. That last item is the escape hatch: if your kernels depend on something the runtime cannot see in the source, you supply a signature so a stale artifact is not reused.
On-disk caching supports local and distributed filesystems that provide atomic directory rename within a filesystem and file and directory fsync. Builds write into unique temporary directories, synchronize their contents, and publish a complete entry through an atomic rename. Concurrent processes may compile the same entry and reuse the published result. The README notes that matching compilation inputs and cache tags let users reuse each other's compiled kernels, and that the cache should live in a trusted shared directory.
Installing DeepJIT: add the include path and pick one backend header
There is no package to install and no release to download. The README says DeepJIT is intended to be embedded into your extension as a header-only dependency, and the root CMakeLists.txt exists for debugging and IDE indexing rather than as the integration mechanism. Integration means adding DeepJIT/include to the include path of your host target, as the README shows:
target_include_directories(my_target PRIVATE third-party/deep_jit/include)Then include exactly one backend entry header. For CUDA:
#include <deep_jit/backend/cuda/backend.hpp>For Ascend, the README gives the parallel form:
#include <deep_jit/backend/ascend/backend.hpp>The selected header exposes its backend type, and you alias the runtime to your backend:
using JIT = deep_jit::Runtime<deep_jit::CUDA>;For the Ascend header, the README says to use deep_jit::Runtime<deep_jit::Ascend> instead. A lazy runtime is created with a Config that takes the library root and a prefix:
inline auto jit = deep_jit::create_lazy_jit<deep_jit::CUDA>(
    deep_jit::Config("/absolute/path/to/my_library", "MYLIB"));
The README also covers the case where configuration is only known during library initialization: start with an empty LazyInit object and assign its factory later inside an init function. Before any of this runs, the host environment must provide Linux, a C++20 compiler and standard library with std::format support, Python, pybind11, and the selected backend's toolchain. For CUDA that means CUDA headers 12.4+, NVCC 12.9+ and PyTorch with CUDA support. For Ascend it means CANN with bin/bisheng, bin/ld.lld and the Ascend adv_api headers, plus ACL and torch_npu headers and runtime. The working integration examples live under tests/test_cuda_proj and tests/test_ascend_proj.
Sharing one compiled kernel cache across users and nodes
The shared cache is the feature most likely to decide whether DeepJIT is worth adopting, because it is the one that changes operational cost rather than code structure. Point the runtime at a directory on a shared filesystem:
export DJ_JIT_CACHE_DIR=/shared/deep_jitThe README states that multiple users, processes and nodes can point to the same cache directory, and that directory permissions must let participating users read shared artifacts while writers can create and publish entries under the cache root. You can also combine a writable personal cache with a read-only shared lookup cache:
export DJ_JIT_CACHE_DIR="$HOME/.dj:/shared/deep_jit"DeepJIT searches all roots in order and writes cache misses only to the first root. A consumer library can use its own prefix instead, for example MYLIB_JIT_CACHE_DIR, which is the right choice when one process hosts several libraries that should not share a cache policy.
The constraint to plan around is the filesystem requirement. Atomic directory rename within a filesystem and fsync are the primitives the publish path depends on, so an object store, an NFS mount that does not give those semantics, or a cache directory on a filesystem where a rename can cross a boundary will not behave as described. The README also says to use a trusted shared directory. That is not boilerplate: any user who can write into the cache root can publish an artifact that other users will load.
What DeepJIT does not give you yet
Two features listed in the README are marked as under development and not yet available. Cache warmup from history would use historical cache entries to anticipate kernels a future run may need and compile them ahead of execution. A Python compilation API would let you pass kernel source directly from Python to compile CUDA or Ascend kernels. Neither is usable today, so any plan that assumes a Python-side compile call or proactive warmup is planning against a roadmap rather than a library.
The bigger practical gap is release engineering. The repository has no published GitHub releases, so there is no version to pin, no changelog to read before an upgrade, and no compatibility statement between commits. Integration is vendoring headers at a commit you choose. The root CMakeLists.txt is described as being for debugging and IDE indexing, which means there is no supported CMake target to consume either.
Licence is the other open question. The repository metadata does not identify a licence, and the README does not state one. Until that is resolved in the repository, shipping DeepJIT inside a distributed binary is a decision made without the information you would normally require. That is a fact about the current state of the project, not a judgement about its quality.
Finally, the platform surface is Linux only, per the host environment requirements. Windows is not covered. If your extension ships on Windows, this is the wrong tool regardless of the backend support.
DeepJIT against writing your own cache layer or using a full compiler stack
The obvious alternative is the one most kernel libraries already have: a hand-written cache keyed on source text plus a hash of compiler flags, with a directory per key and a file lock around it. That approach is not wrong, and for a single backend it is less machinery than DeepJIT. The difference is what happens when you add the second backend. Your cache key now has to fold in a different compiler version scheme, a different set of effective options, and a different notion of a tracked include. DeepJIT's answer is a cache key that accounts for source, tracked includes, compiler versions, effective compiler options and an application-provided dependency signature, applied identically to both backends. If you only ever target CUDA, you are paying for a generalization you will not use.
A second alternative is a full compiler stack such as TVM or a graph compiler that owns kernel generation end to end. Those tools generate kernels from a higher-level description and manage their own runtime. DeepJIT does the opposite: you keep writing CUDA or Ascend kernel source, and it handles compilation, caching, loading and launching. That makes it a poor fit if you want the framework to choose your kernels, and a reasonable fit if you already have device code and only want the plumbing around it.
There is also the option of using each vendor's own runtime directly. CUDA's driver API and Ascend's ACL both work, and both are documented by their vendors. What you give up is the single interface and the shared cache semantics. What you gain is a dependency with its own release and support process, which DeepJIT does not currently have.
Maintenance, upgrade cost and the licence question
The repository is not archived, and its last push was on 2026-09-14. The README names three main authors and lists two features as in development, which is consistent with a project that is being worked on rather than frozen. That is the whole of what the repository shows about maintenance; there is no release cadence to read.
Upgrade cost follows from the header-only, no-releases model. There is no version to bump in a manifest. Upgrading means moving the vendored include directory to a new commit and rebuilding, then checking whether any header you include changed its interface. The README does not document a deprecation policy, a compatibility guarantee between commits, or a rollback procedure, so the safe practice is to vendor a specific commit and treat the upgrade as a code change that needs its own review.
On licensing, the repository does not identify a licence, and the README does not state one. That is the fact to act on. Until a licence is present in the repository, you cannot determine the terms under which the headers may be redistributed, and header-only integration means the headers end up in your source tree. If you need to ship a product, resolve the licence question before you write the integration, not after. This is not legal advice; it is a statement that the information is currently missing from the repository.
Editorial conclusion
Adopt DeepJIT if you maintain a kernel library that must ship the same compile, cache and launch path on both CUDA and Ascend, and you are willing to vendor headers from a repository with no tagged releases and an undocumented licence. Do not adopt it if you need a stable versioned dependency, a documented licence before you ship, or an officially supported Windows build, since the README states the host environment must provide Linux. Before writing any integration code, verify two things in the repository itself: which licence the project is released under, and whether the CUDA and Ascend paths in tests/test_cuda_proj and tests/test_ascend_proj match the toolchain versions you have installed.
Frequently asked questions
How do I install DeepJIT?
There is no install step. The README shows adding DeepJIT/include to the include path with target_include_directories, then including exactly one backend entry header such as deep_jit/backend/cuda/backend.hpp or deep_jit/backend/ascend/backend.hpp. The root CMakeLists.txt is described as being for debugging and IDE indexing rather than as the integration path.
Which CUDA and Ascend toolchain versions does DeepJIT require?
For CUDA, the README lists CUDA headers 12.4+, NVCC 12.9+ and PyTorch with CUDA support. For Ascend, it lists CANN with bin/bisheng, bin/ld.lld and the Ascend adv_api headers, plus ACL and torch_npu headers and runtime. The host environment must also provide Linux, a C++20 compiler and standard library with std::format support, Python and pybind11.
Can several users or nodes share one DeepJIT kernel cache?
Yes, according to the README, which says multiple users, processes and nodes can point to the same cache directory through DJ_JIT_CACHE_DIR, and that a writable personal cache can be combined with a read-only shared lookup cache using a colon-separated list. The filesystem must provide atomic directory rename within a filesystem and file and directory fsync, and the README says to use a trusted shared directory.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- DeepJIT: Header-Only C++20 JIT Runtime for Nvidia CUDA and Huawei AscendHacker News · Sep 10, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepjit)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepjit)Was this useful?