DeepSeek-R1: What the Open Weights and Distilled Checkpoints Actually Buy You
The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- DeepSeek-R1 is a 671B-parameter reasoning model trained with reinforcement learning and no supervised fine-tuning, plus six smaller distilled checkpoints. The repository is thin on operational detail, so the real work is deciding which checkpoint fits your hardware and workflow.
- Who is it for?
- Adopt DeepSeek-R1 if you need an open reasoning model with a published training pipeline and you have the multi-GPU setup to run a 671B MoE with 37B activated parameters. The distilled 1.5B to 70B checkpoints are the realistic entry point for most teams, especially the Qwen-32B variant that the README claims beats o1-mini on several benchmarks.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 16 months ago, on June 27, 2025.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
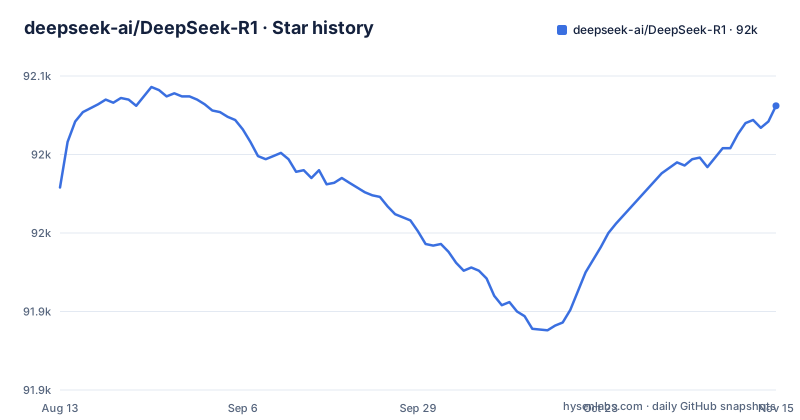
- deepseek-ai/DeepSeek-R192,031 ★ · +52
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| deepseek-ai/DeepSeek-R1 | 92k | 92k |
52 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Contains
The DeepSeek-R1 repo is not a software project in the usual sense. It is a release hub for model weights, a paper, and a set of benchmark tables. The README introduces two flagship models: DeepSeek-R1-Zero and DeepSeek-R1. Both are 671B-parameter mixture-of-experts models with 37B activated parameters and a 128K context length, built on DeepSeek-V3-Base. Alongside those, the repo points to six distilled dense models based on Qwen2.5 and Llama3, ranging from 1.5B to 70B parameters. The only release tag is v1.0.0, dated 2025-06-27, which suggests this is a stable snapshot rather than a moving target. If you are looking for code to run, you will be redirected to the DeepSeek-V3 repository for architecture details, and to Hugging Face for the actual weights. That split is the first thing to understand before you plan any adoption.
The Training Pipeline: RL Without SFT, Then SFT, Then RL Again
The core claim in the README is that reasoning capabilities can be incentivized purely through reinforcement learning, without supervised fine-tuning as a precursor. DeepSeek-R1-Zero is the proof: the team applied large-scale RL directly to the base model and observed the emergence of self-verification, reflection, and long chain-of-thought generation. But that raw model had problems: endless repetition, poor readability, and language mixing. So DeepSeek-R1 was built with a different pipeline that adds cold-start data before RL. The README describes two RL stages and two SFT stages. The first RL stage discovers improved reasoning patterns; the second aligns with human preferences. The SFT stages seed both reasoning and non-reasoning capabilities. This is a meaningful architectural difference from the typical post-training flow, where SFT comes first and RL is a refinement. Here, the order is inverted for R1-Zero, and the final R1 model uses a hybrid. For a team evaluating whether to fine-tune or distill from this model, that pipeline detail matters because it explains why the outputs look the way they do.
Distilled Checkpoints: The Practical Path to Local Inference
Running a 671B model is out of reach for most organizations. The README acknowledges this by open-sourcing six distilled dense models: DeepSeek-R1-Distill-Qwen-1.5B, 7B, 14B, 32B, and DeepSeek-R1-Distill-Llama-8B and 70B. These are fine-tuned from open base models using samples generated by DeepSeek-R1. The README makes a strong claim: the Qwen-32B distill outperforms OpenAI-o1-mini across various benchmarks and achieves state-of-the-art results for dense models. That is a specific, checkable claim. The distill models are not just weight copies. The README warns that configs and tokenizers were slightly changed, and that you must use the project's settings to run them. That is a concrete constraint. If you plan to plug these into an existing serving stack, budget time to reconcile those modified configs with your inference framework.
Evaluation Settings You Need to Replicate
The README gives precise evaluation parameters for the R1 models: maximum generation length of 32,768 tokens, temperature 0.6, top-p 0.95, and 64 responses per query to estimate pass@1. That is not a footnote; it is a load-bearing detail. If you want to reproduce the reported benchmark numbers, you must use those settings. The 64-sample pass@1 protocol is expensive, especially at 32K tokens per generation. For a team that wants to compare DeepSeek-R1 against another model, this means the evaluation cost is high. It also means the numbers in the README, such as MMLU 90.8 for R1 versus 91.8 for o1-1217, are not single-shot scores. They come from a specific sampling strategy. If you run with a single greedy decode, you will see different results. You are left to decide whether to replicate the full protocol or accept that your numbers will differ.
What Is Missing from This Repository
The README is a model card, not a deployment guide. The repository holds only the README, the paper PDF, a licence file and figures, so there are no inference scripts or Docker files. The README's opening note asks you to review its Usage Recommendation section before running the models locally. The paper link is there, and the architecture points to DeepSeek-V3, but the repo itself gives you nothing to run. For an engineer evaluating adoption, that is a real gap. You will need to pull weights from Hugging Face, write your own serving code, and likely consult the DeepSeek-V3 repo for architecture details. The absence of a quickstart is not a flaw in the model, but it is a cost you should factor in. The repository shows an MIT license; check each checkpoint's page on Hugging Face for the terms that apply to the weights.
The Wrong Tool for Certain Jobs
DeepSeek-R1 is a reasoning model, not a general-purpose chat model. The README emphasizes math, code, and reasoning tasks. If your workload is simple classification, summarization, or retrieval-augmented generation with short answers, a smaller dense model like Llama-3.1-8B or Qwen2.5-14B will be faster and cheaper. The 32,768-token maximum generation length and the 64-sample pass@1 protocol used in evaluation suggest the model is designed for tasks that require long chain-of-thought. For latency-sensitive applications, the 671B model with 37B activated parameters still requires substantial GPU memory. Even the 32B distill model will not run on a single consumer GPU comfortably. If your team lacks the infrastructure for multi-GPU inference or the patience for long generations, this is the wrong tool. The distill models are the only viable option, and even those need careful config handling.
Alternatives: OpenAI o1 and the Distill Base Models
The README itself names OpenAI o1-mini and o1-1217 as comparison points. The difference in approach is fundamental. OpenAI o1 is a closed, proprietary model accessed via API. DeepSeek-R1 is open weights, which means you can self-host, fine-tune, and distill further. That is the real alternative: use the API and avoid infrastructure costs, or host the open model and control your data. The README also implies a second alternative: the base models used for distillation, such as Qwen2.5-Math-1.5B or Llama-3.3-70B-Instruct. If you do not need the reasoning patterns that R1 distills, you could fine-tune those base models yourself with your own data. That is a different cost structure. The R1 distill models give you a head start, but they come with modified configs and tokenizers. The base models are more standard and easier to integrate. The trade-off is performance: the README claims the distilled 32B model beats o1-mini, so you are trading integration ease for benchmark gains.
Maintenance and Upgrade Cost
The repository has a single release tag, v1.0.0, and the last push was 2025-06-27. There is no evidence of active development beyond that date. For a team adopting this, the maintenance cost is mostly on your side. You will track Hugging Face for new checkpoints, and you will need to re-test your inference stack whenever the weights change. The modified configs and tokenizers for the distill models mean that upgrading to a new base model version is not a drop-in replacement. The paper link is static. So the cost is not in maintaining the repo itself, but in maintaining your integration with it.
Editorial conclusion
Adopt DeepSeek-R1 if you need an open reasoning model with a published training pipeline and you have the multi-GPU setup to run a 671B MoE with 37B activated parameters. The distilled 1.5B to 70B checkpoints are the realistic entry point for most teams, especially the Qwen-32B variant that the README claims beats o1-mini on several benchmarks. Skip it if you want a turnkey deployment guide, because the repository holds only the README, the paper PDF, a licence file and figures, with no inference scripts or serving config. Before you commit, verify your inference stack supports the modified configs and tokenizers that the distill models require, and check the license terms on the Hugging Face pages for each checkpoint, since the GitHub repo shows an MIT license.
Frequently asked questions
Is DeepSeek-R1 any good?
On MMLU pass@1 the README reports DeepSeek R1 at 90.8, above GPT-4o 0513 at 87.2 and o1-mini at 85.2, and a point below o1-1217 at 91.8. Those numbers are pass@1 estimated from 64 sampled responses per query at temperature 0.6, not a single run.
Is DeepSeek AI better than ChatGPT?
The repository compares against GPT-4o 0513 rather than a current ChatGPT build, and puts DeepSeek R1 ahead of it on MMLU pass@1 at 90.8 against 87.2. It also states that DeepSeek-R1-Distill-Qwen-32B outperforms OpenAI-o1-mini across various benchmarks.
How do I install DeepSeek-R1 locally?
This repository contains no code to run. The download table links every checkpoint on HuggingFace, and the README's opening note asks you to review its Usage Recommendation section before running the series locally. The architecture itself is documented in the separate DeepSeek-V3 repository.
How much does DeepSeek-R1 cost?
The README states no price. It mentions an API alongside the open-sourced weights as something that will benefit the research community, and the licence is MIT, so the cost of running the models yourself is whatever hardware the 671B checkpoints or the chosen distill need.
How do I access DeepSeek-R1?
Every row of both download tables links a HuggingFace repository, one for the two full checkpoints and one per distilled model. The header also links a web chat at chat.deepseek.com, the company site, a Discord and an X account, alongside the paper PDF held in the repository itself.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-r1)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-r1)Was this useful?