frankengraphdb: A Rust Property-Graph Database That Puts MVCC, Time Travel, and Branches in One Commit Stream
A blank-slate, memory-safe, ultra-high-performance property-graph database in Rust — unified MVCC/time-travel/branches/replication over a fountain-coded commit stream, WCO+factorized execution, incremental everything, and deterministic auditable results.
At a glance
- What is it?
- frankengraphdb is a Rust property-graph database that unifies MVCC, time-travel history, branches, and replication into a single fountain-coded commit stream. The README describes an ambitious design, but the repository is early-stage and the current code runs only a simple example.
- Who is it for?
- Adopt frankengraphdb if you want to experiment with a property-graph database that treats time travel, branches, and replication as the same mechanism, and you are comfortable with a pre-1.0 codebase that currently runs only a single example. Do not use it for production workloads: there are no releases, no installer, and the README itself warns that it describes a future target state.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
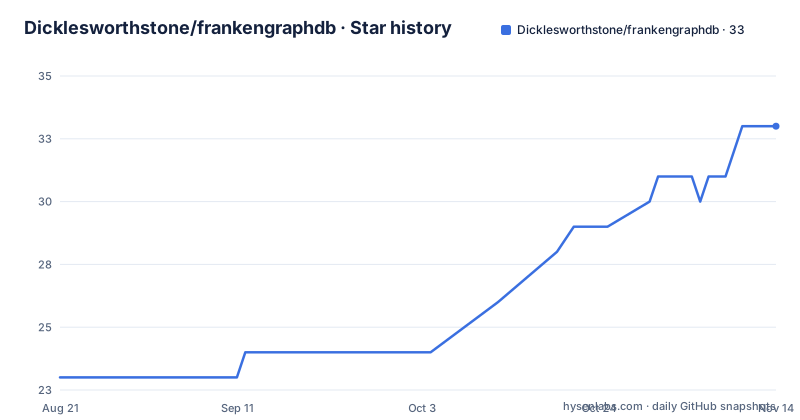
- Dicklesworthstone/frankengraphdb33 ★ · +10
| Repository | 2026-08-21 | 2026-11-14 |
|---|---|---|
| Dicklesworthstone/frankengraphdb | 23 | 33 |
10 Stars in the last 85 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Problem frankengraphdb Targets
The README opens with a blunt claim: every existing graph database is a compromise fossilized around one old decision. Neo4j is pointer-chasing on the JVM, TigerGraph is MPP with a proprietary language, Kùzu got the query story right but its upstream was archived after an acquisition. frankengraphdb wants to compose the hard subproblems that have only been solved in isolation: durability without double-write journaling, unbounded time-travel history, git-style branches, and deterministic query results. Who is it for? The README does not name a specific user profile, but the design targets engineers who need a graph database that can serve both transactional writes and analytics on the same store, with temporal queries and branch-based experimentation. That is a demanding audience, and the project aims at it with a single codebase that offers an embedded library, a server, and a CLI, all speaking GQL with an openCypher on-ramp.
The Six Bets: One Version Universe, Strata, and Loom
The core idea is a set of six bets, each described in one line. The first bet, B1, is the foundation: MVCC versions, time-travel history, replication stream, change subscriptions, and branches are all the same mechanism, an append-only, content-addressed, RaptorQ-coded commit stream called Chronicle. This is not a temporal engine bolted on; it is the storage model itself. B2, called Strata, organizes adjacency in three temperature tiers: versioned delta blocks for hot data, sealed compressed CSR runs for cold data, and archived anchors. The goal is to handle high transactional ingest and static-CSR-class scans with one store. B3, called Loom, unifies execution into a single Free-Join operator family that subsumes binary hash joins, worst-case-optimal multiway joins, and factorized intermediates. The README claims that runs already are tries, meaning the physical layout supports factorized execution directly. These bets are not small features; they are architectural choices that define the entire system.
How the Commit Stream Drives Everything
The commit stream is the central mechanism. It is append-only, content-addressed, and erasure-coded with RaptorQ. The README claims there is no double-write journaling anywhere, which is a strong durability claim: bit-rot becomes a maintenance event, not an outage. Because the stream is content-addressed, every commit has a unique identifier, and the README shows queries that reference a specific sequence number, like FOR SYSTEM_TIME AS OF SEQ 41999. That syntax is a direct consequence of the design: time travel is just reading the stream at a given commit. Branches work the same way, described as O(1) and zero-copy, with support for 10k+ concurrent branches. The commit stream also serves as the delta stream for incremental processing. The README says one DBSP-style Z-set engine drives recursion, materialized views, subscriptions, and incremental analytics. This is an elegant unification, but it is also the most complex part of the design, and the README does not explain how the Z-set engine interacts with the temperature-tiered storage beyond stating that it does.
Determinism and Plan Certificates
A distinctive promise is deterministic query results. The README states that the same state plus the same query plus the same policy yields byte-identical results, including order. This is unusual for a database, where result order is often unspecified. The mechanism is a plan certificate that ships with every result, described as auditable and replayable. The idea is that you can reproduce the exact output by replaying the certificate. This is a verification feature that goes beyond typical query logging. The README also mentions a deterministic lab runtime with virtual time, DPOR schedule exploration, and chaos injection, inherited from the asupersync ecosystem. That is a FoundationDB-class testing approach, but the README does not specify which of these features are implemented in the current code. The plan certificate is a concrete artifact that would be valuable for auditing, but it is unclear how it is generated and what it contains.
Getting It Running: Current State and Commands
The README is explicit that there are no releases or installer yet. The only way to run the project is from a source checkout. The command is simple: clone the repository, change into the directory, and run cargo run -p fgdb --example open_a_database. This runs an example that presumably opens a database. The README does not show any configuration keys or server startup commands. The project uses Rust 2024 edition, and the workspace forbids unsafe code, with a ledgered boundary for SIMD, arena, and VFS islands. The dependency policy is a closed universe: only std, a pinned nightly, and three owned foundations. No serde, tokio, rocksdb, arrow, tantivy, or hnswlib, ever. That is a bold constraint that simplifies auditing but also means the team must implement a lot of low-level functionality themselves. The README warns that it is written in the present tense as if the entire design were realized, but that is a deliberate choice to avoid rewriting the document as milestones land.
Limitations: What the README Admits and What It Does Not
The README admits one genuine limitation: horizontal sharding is future work, covered under a Limitations section. That is a significant gap for a database that claims to handle larger-than-memory data as first-class. The README also says that the actual performance rates are CI-enforced benchmark gates, not assumptions, but it does not provide any current benchmark numbers. Without releases, you cannot verify the claims. The README's own note about tense is a red flag for evaluation: the document describes a target state, and the only evidence of running code is a single example. The latest default-branch commit visible on 7 November 2026 was dated 7 November 2026. A commit date alone does not establish a maintenance schedule. The license is listed as NOASSERTION, meaning you must contact the maintainers to clarify terms before using the code in any project.
Alternatives: Kùzu and the In-Memory Engines
The README itself names Kùzu as the closest architectural competitor: it got the query story right with columnar CSR, vectorization, factorization, and worst-case-optimal joins. The difference is that Kùzu's upstream was archived after an acquisition, so community forks carry the architecture forward. frankengraphdb wants to take that query engine and add durability, temporal, and multi-writer capabilities. If you need a property-graph database with mature query execution today, Kùzu or its forks are a real option, but you inherit the gaps in durability and time travel. On the other end, Memgraph and FalkorDB are fast in-memory engines with thin durability. They are simpler to deploy and have active communities, but they do not offer the unified commit stream or deterministic certificates. The choice is between a proven but limited engine and an ambitious design that may not be fully implemented yet.
Maintenance and Upgrade Cost
The maintenance cost of frankengraphdb is impossible to estimate from the README alone. The closed-universe dependency policy means fewer external updates to track, but it also means the team must maintain every piece of infrastructure, including the fountain coding and the deterministic runtime. The README mentions a comprehensive plan document. The Rust 2024 edition and nightly toolchain pinning suggest a fast-moving codebase that may require frequent updates to keep compiling. The lack of releases means no stable API to build against. The license being NOASSERTION is a legal risk: you cannot assume it is open source without clarification. Before adopting this for any serious use, you would need to inspect the repository's commit history, read the full plan document, and run the example to see what actually works. The README's ambition is clear, but the gap between the spec and the running code is the decisive factor for any engineer evaluating this project.
Editorial conclusion
Adopt frankengraphdb if you want to experiment with a property-graph database that treats time travel, branches, and replication as the same mechanism, and you are comfortable with a pre-1.0 codebase that currently runs only a single example. Do not use it for production workloads: there are no releases, no installer, and the README itself warns that it describes a future target state. Before committing, verify which of the six bets are actually implemented in the source tree, check the license (listed as NOASSERTION, so you must clarify it), and run the open_a_database example to see what the current code supports. The design is coherent and technically interesting, but the gap between the spec and the running code is the decisive factor.
Frequently asked questions
What is GraphDB used for?
frankengraphdb stores property graphs and queries them in GQL, ISO/IEC 39075:2024, with an openCypher on-ramp. The query surface covers pattern matching, quantified paths, shortest paths such as `SHORTEST`, and time travel through `FOR SYSTEM_TIME AS OF` or `BETWEEN`.
What are the top 5 graph databases?
The README compares itself against Neo4j for pointer chasing on the JVM, TigerGraph for MPP with a proprietary language, Kùzu for columnar CSR plus vectorization and factorization, Memgraph and FalkorDB as fast in-memory engines with thin durability, and JanusGraph and NebulaGraph for a generic KV underlay. It notes that the Kùzu upstream repository was archived read-only after Apple acquired Kùzu Inc.
Is GraphDB a triple store?
frankengraphdb describes itself as a property-graph database, and the quick example writes properties straight onto relationships, with an edge created as `-[:KNOWS {since: 1833}]->`. The README does not discuss triple stores at all.
Is Neo4j better than SQL?
The README argues that every graph database on the market is a compromise frozen around one old decision, and names Neo4j's as pointer chasing on the JVM, which it credits with great ergonomics and painful memory, and a runtime that took 15 years to vectorize.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dicklesworthstone-frankengraphdb)Star history chart for your README
[](https://hysenlabs.com/projects/dicklesworthstone-frankengraphdb)Was this useful?