DuckLake: a lakehouse format where the catalog is a SQL database
DuckLake is an integrated data lake and catalog format
At a glance
- What is it?
- DuckLake stores metadata in a SQL catalog database and table data in Parquet, and the DuckDB extension attaches it with a single ATTACH statement. The design is easy to reason about, but the README leaves deployment questions open.
- Who is it for?
- Adopt DuckLake if you already work in DuckDB and want SQL tables that live in Parquet with a catalog you can query, back up and read directly. Do not adopt it if you need a documented production hardening story, a non-DuckDB engine as the primary writer, or a metadata layer that does not depend on a separate database process.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
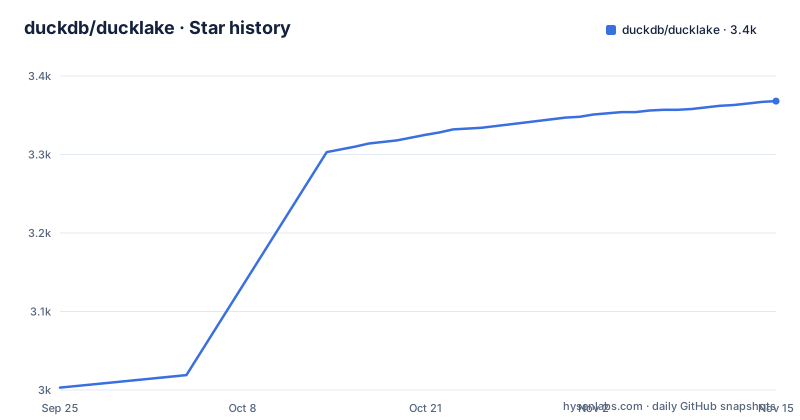
- duckdb/ducklake3,368 ★ · +365
| Repository | 2026-09-25 | 2026-11-15 |
|---|---|---|
| duckdb/ducklake | 3k | 3.4k |
365 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem DuckLake solves: metadata that outgrows a single file
Table formats that keep metadata in object storage force every reader to list and parse metadata files before it can plan a query. DuckLake moves that metadata into a catalog database and keeps only the data in Parquet. The README states the split plainly: DuckLake stores metadata in a catalog database, and stores data in Parquet files. The extension lets DuckDB read and write that data directly.
The audience is anyone already using DuckDB who has outgrown a single .duckdb file. If your tables need versioned reads, schema changes over time, and a record of which rows changed between snapshots, DuckLake exposes those as SQL rather than as a separate toolchain. The README points to a page on choosing a catalog database, which implies the catalog is a decision you make, not a fixed component. That is the central trade-off of the project: you gain a queryable catalog and lose the simplicity of having no server to run.
How DuckLake stores metadata and data: catalog database plus Parquet
The mechanism is visible in the attach syntax. A DuckLake database is opened with ATTACH 'ducklake:metadata.ducklake' AS my_ducklake (DATA_PATH 'file_path/'). The ducklake: prefix tells the extension this is a DuckLake catalog; the path after it is the catalog database; DATA_PATH is where Parquet files land. After that, tables are created, modified and queried with standard SQL, so the extension is not a new query language, it is a storage backend behind the SQL you already write.
Several capabilities follow from keeping version history in the catalog. Time travel reads a prior state with FROM my_ducklake.my_table AT (VERSION => 2). Change data feed returns per-row changes over a snapshot range through a table function, FROM my_ducklake.table_changes('my_table', 2, 2), whose output columns include snapshot_id, rowid, change_type, and the table's own columns. Schema evolution is an ordinary ALTER TABLE ADD COLUMN, and existing rows come back with NULL in the new column.
The repository layout backs this up. The test suite runs DuckLake against PostgreSQL and SQLite catalog databases through test/configs/postgres.json and test/configs/sqlite.json, and there is a separate config for deletion vectors. Those config files are the clearest evidence in the repository that the catalog is pluggable and that deletion vectors are a distinct, toggleable behavior rather than the default path.
Installing the DuckLake extension in DuckDB and creating your first table
The README gives the install command directly. Inside a DuckDB session, run INSTALL ducklake; and the extension is fetched. If you want the development build instead of the released one, the README documents FORCE INSTALL ducklake FROM core_nightly;
INSTALL ducklake;After installing, attach a catalog and point the data path at a directory. The README's example uses a DuckDB database file named metadata.ducklake and a directory named file_path for the Parquet output.
ATTACH 'ducklake:metadata.ducklake' AS my_ducklake (DATA_PATH 'file_path/');
USE my_ducklake;
CREATE TABLE my_ducklake.my_table(id INTEGER, val VARCHAR);
INSERT INTO my_ducklake.my_table VALUES (1, 'Hello'), (2, 'World');
FROM my_ducklake.my_table;
You should see a two-row result with columns id and val, typed int32 and varchar. From there the README shows UPDATE changing a row, AT (VERSION => 2) reading the pre-update state, and ALTER TABLE ... ADD COLUMN adding a column that reads back as NULL for existing rows.
If you want to build the extension from source rather than install it, the README lists the steps: git submodule init, git submodule update, make pull, then make, with make GEN=ninja release for a multi-core build. Running the bundled shell is ./build/release/duckdb. Tests run through ./build/release/test/unittest, and the Makefile shows the default test filter is T ?= $(TEST_FLAGS) "~[.]test/*", which excludes hidden or slow tests unless you override it.
Where DuckLake is the wrong tool: catalog dependencies and thin operations docs
The catalog database is a dependency you must operate. The README links to a page about choosing a catalog database but does not, in the text available on the repository front page, describe backup, failover, or what happens when the catalog is unreachable while readers are running. For a single-user analytics setup that is fine. For a multi-writer pipeline it is the first question you should ask, and the README's own test suite hints at the shape of the problem: there is a test file at test/sql/transaction/create_conflict.test, so conflicting creates are a scenario the project tests. The README does not describe an operational locking policy or a retry contract for writers.
Second, the README does not state a production readiness position, and the repository has no published releases, so there is no version history to inspect here. If your adoption decision depends on a stability guarantee, the README alone will not give you one.
Third, DuckLake is not a replacement for DuckDB itself. DuckDB is the engine; DuckLake is a format and catalog the engine talks to. Choosing DuckLake does not change how queries execute, and it does not give you a distributed compute layer. If your data fits comfortably in one DuckDB file and no one needs historical versions or a shared catalog, attaching DuckLake adds a catalog database and a Parquet directory for no benefit.
DuckLake compared with Iceberg and Delta Lake: catalog in a database, not in object storage
The related searches pair DuckLake with Iceberg and Delta Lake, and the architectural difference is the metadata location. DuckLake keeps its catalog in a SQL database, which the repository's test configs show can be PostgreSQL or SQLite, and keeps table data in Parquet. The catalog is therefore queryable with ordinary SQL and its consistency properties come from the database you choose rather than from a protocol implemented over object storage.
The practical consequence is that readers do not need to list and parse metadata files to plan a scan; they consult the catalog. The cost is that the catalog is a service you run and protect, and every reader needs access to it. That is a different failure surface from a format whose metadata lives beside the data.
DuckLake also differs from DuckDB in kind, not degree. DuckDB is the query engine; DuckLake is the storage and catalog format. The README's example of running DuckDB core tests with DuckLake as the storage backend, via --test-config test/configs/attach_ducklake.json, shows the relationship: DuckLake is a backend DuckDB can be pointed at.
Maintenance cost and the MIT licence
The repository's last push was on 2026-09-22, and it is not archived. The README states that active development happens on main and that contributions should target that branch, so the extension tracks a moving DuckDB codebase; there is a duckdb submodule in the repository and the build instructions begin with git submodule init and git submodule update. Expect to re-run make pull when you build from source, because the extension is compiled against a specific DuckDB revision.
For users who install the binary extension, the maintenance surface is smaller: INSTALL ducklake fetches a build that matches your DuckDB version, and the README offers FORCE INSTALL ducklake FROM core_nightly for the development track. The upgrade cost that remains is the catalog database. Schema changes to the catalog, if any, are not described in the README, so a version upgrade path for an existing catalog is something to confirm against the documentation before you rely on it.
The project is MIT licensed. That is a permissive licence, and the practical implication is that you can embed the extension in commercial work; it says nothing about the licence of the catalog database or object store you pair it with, which you should check separately.
Editorial conclusion
Adopt DuckLake if you already work in DuckDB and want SQL tables that live in Parquet with a catalog you can query, back up and read directly. Do not adopt it if you need a documented production hardening story, a non-DuckDB engine as the primary writer, or a metadata layer that does not depend on a separate database process. Before committing, verify three things against the documentation: which catalog database you will run, whether your DuckDB version ships the ducklake extension or needs FORCE INSTALL ducklake FROM core_nightly, and how you will handle concurrent writers, since the README's test suite includes transaction conflict tests but does not describe an operational locking policy.
Frequently asked questions
What is DuckLake in DuckDB?
DuckLake is an open lakehouse format built on SQL and Parquet, and the DuckDB extension lets DuckDB read and write it directly. Metadata lives in a catalog database, and table data lives in Parquet files.
How do I install DuckLake?
Inside DuckDB, run INSTALL ducklake;. The README also documents FORCE INSTALL ducklake FROM core_nightly; for the development version, and building from source with make pull followed by make.
How do I set up DuckLake and use it?
Attach a catalog with ATTACH 'ducklake:metadata.ducklake' AS my_ducklake (DATA_PATH 'file_path/'); then run USE my_ducklake and create tables with standard SQL. The README shows CREATE TABLE, INSERT, UPDATE, time travel with AT (VERSION => 2), ALTER TABLE for schema evolution, and table_changes for a change data feed.
Is DuckLake a lakehouse?
The README describes DuckLake as an open Lakehouse format built on SQL and Parquet, with metadata in a catalog database and data in Parquet files.
What are the differences between DuckLake and DuckDB?
DuckDB is the query engine and DuckLake is the storage and catalog format it can be pointed at. The README shows DuckDB core tests being run with DuckLake as the storage backend via a test config.
Is DuckLake open source?
Yes. The repository is licensed under MIT, and the README welcomes external contributions, stating that active development happens on the main branch.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- DuckDB DucklakeHacker News · Oct 7, 2026 · 233 points · 36 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/duckdb-ducklake)Star history chart for your README
[](https://hysenlabs.com/projects/duckdb-ducklake)Was this useful?