meshoptimizer: seven passes in a fixed order, and the padding rule that quietly defeats indexing
Mesh optimization library that makes meshes smaller and faster to render
At a glance
- What is it?
- zeux/meshoptimizer is a C and C++ library of GPU-oriented mesh algorithms: vertex remapping, cache and fetch optimization, quantization, index filtering and codecs, shipped alongside gltfpack and clusterlod.h. Its sharp edges are byte-equality vertex comparison and a pipeline that assumes you have already controlled your vertex struct.
- Who is it for?
- Adopt meshoptimizer when you control the vertex and index buffers on the CPU and can run the passes in the documented order. If your bottleneck is bytes over a network, evaluate its vertex and index codecs rather than relying on the GPU-ordering passes alone.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 31 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
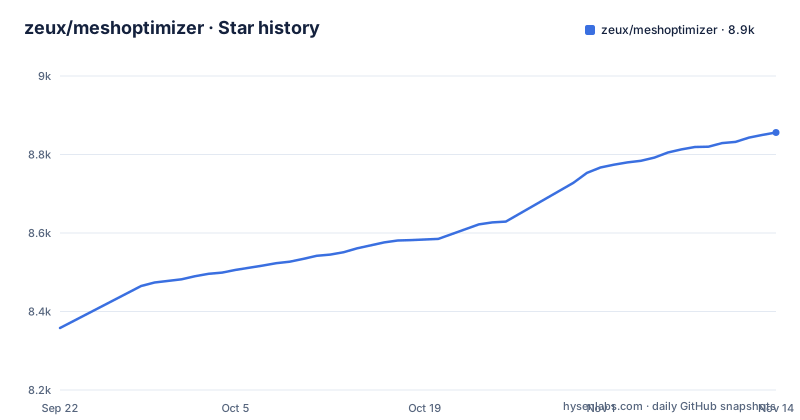
- zeux/meshoptimizer8,856 ★ · +498
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| zeux/meshoptimizer | 8.4k | 8.9k |
498 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The pass order is fixed, so indexing cannot move to the end
The core pipeline is a seven step sequence, and the order is not a suggestion. Indexing comes first, then vertex cache optimization, optional overdraw optimization, vertex fetch optimization, vertex quantization, index filtering, and optional shadow indexing.
Most of those algorithms assume the same input shape: a vertex buffer, an index buffer, and no redundant vertices left in the vertex buffer. That assumption is why indexing sits at position one instead of being a cleanup pass at the end. Run cache optimization over a buffer that still carries duplicates and those duplicates occupy the same cache and fetch slots the real vertices needed. The README states that you can then keep optimizing the resulting buffers by calling the other functions on them in place, so this is a chain of rewrites against the same memory rather than a set of independent filters.
Overdraw optimization and shadow indexing are the two optional entries, and leaving them out is a supported choice.
Binary equivalence counts padding bytes, and uninitialized gaps keep duplicates alive
meshopt_generateVertexRemap builds its remap table from binary equivalence of the input vertices, and binary equivalence considers every input byte. If your Vertex struct has gaps, the padding has to be zero-initialized. Skip that and two vertices carrying identical position, normal and texcoord data will compare as different, the remap keeps both, and no warning fires, because from the library's point of view they really are different vertices.
The consequence is a failure that never announces itself at runtime. The mesh renders the same, the vertex count stays high, and every later pass in the chain receives data that indexing was meant to remove. It shows up as a larger buffer and a worse cache hit rate. The remap table is a temporary array sized to the unindexed vertex count:
size_t index_count = face_count * 3;
size_t unindexed_vertex_count = face_count * 3;
std::vector<unsigned int> remap(unindexed_vertex_count); // temporary remap table
size_t vertex_count = meshopt_generateVertexRemap(&remap[0], NULL, index_count,
    &unindexed_vertices[0], unindexed_vertex_count, sizeof(Vertex));
With the table in hand you allocate vertex_count elements for vertices and index_count elements for indices, then write both buffers:
meshopt_remapIndexBuffer(indices, NULL, index_count, &remap[0]);
meshopt_remapVertexBuffer(vertices, &unindexed_vertices[0], unindexed_vertex_count, sizeof(Vertex), &remap[0]);
That NULL in the first call is only correct when the input mesh is unindexed. If you already have indices, they replace the NULL in meshopt_generateVertexRemap, together with the correct source vertex count.
meshopt_generateVertexRemapCustom hands the tolerance decision to you
Byte equality is a blunt test. Attributes that drifted during export keep vertices apart even when a human would call them the same point, and the documented workarounds come in two forms: quantize some attributes before generating the remap, most importantly normals and tangents, or switch to meshopt_generateVertexRemapCustom and supply a comparison function of your own.
size_t vertex_count = meshopt_generateVertexRemapCustom(&remap[0], NULL, index_count,
    &unindexed_vertices[0].px, unindexed_vertex_count, sizeof(Vertex),
    [&](unsigned int lhs, unsigned int rhs) -> bool {
        const Vertex& lv = unindexed_vertices[lhs];
        const Vertex& rv = unindexed_vertices[rhs];

        return fabsf(lv.tx - rv.tx) < 1e-3f && fabsf(lv.ty - rv.ty) < 1e-3f;
    });
The example compares two tangent components against a 1e-3f tolerance and calls the pair equivalent when both comparisons pass. That number becomes your decision, and both directions of it have a visible cost. Set it too tight and the duplicates you meant to merge survive into cache and fetch optimization. Set it too loose and vertices that were supposed to stay distinct get welded together, which changes what the mesh looks like on screen. You supply the predicate.
One convention is worth knowing before this reaches your code. The library generally works with 32 bit unsigned int indices, C++ callers may use any integer type for index data through the provided template overloads, but remap tables always use unsigned int. If your renderer runs on 16 bit indices, the remap array is still 32 bit wide.
Cloning the v1.3 tag, or pinning a distro package that trails it
The library is hosted on GitHub and the release tags are what you clone. The current tag is v1.3, published on 2026-09-25:
git clone -b v1.3 https://github.com/zeux/meshoptimizer.gitWhat you get is a C-compatible header at src/meshoptimizer.h plus C++ sources under src/, with a CMakeLists.txt at the repository root. Either let CMake build it or add the sources to your own build system, and add only the source files for the algorithms you actually call. They are meant to build without warnings and without special compilation options on all major compilers, and if you want a single translation unit you can concatenate the sources into one .cpp instead. The root Makefile compiles C++ sources with -std=c++11 and C sources with -std=c89.
Distribution packages exist for ArchLinux, Debian, FreeBSD, Nix and Ubuntu, alongside a Vcpkg port and a Conan recipe, and those pin whatever the distribution shipped. Releases went out as v1.1 on 2026-04-02, v1.2 on 2026-06-30 and v1.3 on 2026-09-25, a cadence of a few months, so a distro package can sit a version behind the tag you would otherwise clone. The last push to master landed on 2026-10-14, nearly three weeks after v1.3.
The Makefile WebAssembly target exports decoders and nothing that optimizes
The root Makefile carries a second target that describes a narrow slice of the library. WASM_DECODER_SOURCES lists src/vertexcodec.cpp, src/indexcodec.cpp, src/vertexfilter.cpp and tools/wasmstubs.cpp. WASM_DECODER_EXPORTS names meshopt_decodeVertexBuffer, meshopt_decodeIndexBuffer, meshopt_decodeIndexSequence, meshopt_decodeFilterOct, meshopt_decodeFilterQuat, meshopt_decodeFilterExp and meshopt_decodeFilterColor, alongside sbrk and __wasm_call_ctors for runtime support.
Those are decode entry points. Nothing in that list optimizes anything, so a plan to run the full pipeline inside a WebAssembly module at runtime is not served by this target; the Makefile defines a separate WASM_ENCODER_SOURCES list that includes src/vcacheoptimizer.cpp. The link flags narrow the surface further: -mcpu=mvp keeps the compiler away from post-MVP features such as sign extension, the stack is pinned to 36864 and the initial memory to 65536, and MESHOPTIMIZER_VERTEXCODEC_ZEROCOPY is defined for the build. Toolchain paths are overridable, with WASI_SDK defaulting to /opt/wasi-sdk.
Browser coverage comes from elsewhere. The repository has a js directory, the README points to the meshoptimizer.js npm package for some algorithms, and demo/ carries index.html, simplify.html and remesh.html next to main.cpp, nanite.cpp, meshletdec.slang, ansi.c, pirate.obj, pirate.glb and tests.cpp. Expect to read those files to see how the browser and engine paths are meant to be wired.
gltfpack from npm drops the texture compression the native build has
gltfpack is the command line tool distributed alongside the library, and it takes a glTF file and optimizes it without you writing the pipeline yourself. It has two install routes: a pre-built binary on the Releases page, or the npm package. The project says which one to pick. Native binaries are recommended since they are more efficient and support texture compression, so the npm route costs you texture compression and throughput rather than download size.
Building it locally exposes where that difference comes from. The root Makefile compiles gltfpack from gltf/*.cpp and only adds -DWITH_BASISU when BASISU is defined, which also pulls -lpthread and $(BASISU)/libbasisu_encoder.a into LDFLAGS. Leave BASISU unset and the gltfpack you produce has no Basis Universal path wired in, which is a quieter failure than a missing flag because everything still builds.
The other companion project is clusterlod.h, a single-header C/C++ library in demo/ for continuous level of detail using clustered simplification. It is not part of the main library build. If you want distance-based level of detail at runtime, you add that header to your engine, and the main library stays out of the decision about when to switch.
The library stops at the buffer boundary and leaves the loader to you
meshoptimizer takes vertex and index buffers plus a vertex stride. Everything around that is your code. It does not parse glTF, walk a node hierarchy, or decide when a distant mesh should drop to a coarser one. For the offline path that job belongs to gltfpack. For runtime level of detail it belongs to clusterlod.h, and only if you adopt that header.
The cost lands in your loader. You define the Vertex struct, you own the padding rule from the remap step, you choose where quantization sits relative to the rest of the chain, and you unpack the filters at load time. The repository layout shows the shape of that work, with tools/, extern/ and js/ sitting next to src/ and demo/ holding the reference consumers.
Two boundaries deserve to be said plainly. The C and C++ interface is the library itself, other languages arrive through FFI such as P/Invoke, the README redirects Rust users to the meshopt crate, and the JavaScript interface covers some algorithms rather than all of them. Keep the unoptimized buffers until you have compared the output against the source mesh. The licence is MIT.
Draco compresses the transfer, meshoptimizer reorders what the GPU reads
Draco, the other geometry compression tool you will be compared against, quantizes attributes and entropy codes the result, and the consumer pays a decode step before it can draw. meshoptimizer takes the opposite position. It leaves data in a layout the GPU can consume, with standard index types, quantized attributes in vertex formats and filters to unpack them, and it reorders that data for the post-transform cache and for vertex fetch. Its README names two aims: making data cheaper for GPU pipeline stages, and reducing mesh complexity and storage overhead, and it ships vertex and index codecs with matching decoders.
That difference decides the fit. If a mesh has to be compressed for transport and decoded on arrival, compare Draco with meshoptimizer's own vertex and index codecs. If the mesh is already inside the render path and the complaint is that the GPU reads it badly, then a codec inserts a step meshoptimizer has no part in. Measure output size and frame time on your own meshes before choosing.
Editorial conclusion
Adopt meshoptimizer when you control the vertex and index buffers on the CPU and can run the passes in the documented order. If your bottleneck is bytes over a network, evaluate its vertex and index codecs rather than relying on the GPU-ordering passes alone. Before committing anything, run meshopt_generateVertexRemap over a mesh whose vertex struct has gaps and check that the vertex count actually drops; if the padding bytes are not zero-initialized, the remap will not notice.
Frequently asked questions
What is mesh simplification?
Mesh simplification is reducing the complexity of a triangle mesh. meshoptimizer names reducing mesh complexity and storage overhead as one of its two goals, the other being cheaper data for GPU pipeline stages, and its companion clusterlod.h does continuous level of detail using clustered simplification.
How do I use meshoptimizer?
Clone a release tag, include the header src/meshoptimizer.h, add the source files for the algorithms you call, and run the passes in the documented order: indexing, vertex cache optimization, optional overdraw optimization, vertex fetch optimization, vertex quantization, index filtering, then optional shadow indexing. Keep the original buffers until you have compared results.
Is there a Rust binding for meshoptimizer in this repository?
Not in this repository. The README says Rust users should use the meshopt crate, and that other languages reach the library through FFI such as P/Invoke.
How do I get gltfpack, and does the npm build compress textures?
gltfpack ships as a pre-built binary on the Releases page and as an npm package. The README says native binaries are recommended since they are more efficient and support texture compression.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Meshoptimizer Version 1.3 ReleasedHacker News · Sep 30, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zeux-meshoptimizer)Star history chart for your README
[](https://hysenlabs.com/projects/zeux-meshoptimizer)Was this useful?