ExcelDataReader reads xls from BIFF2 to OpenXml without a COM dependency
Lightweight and fast library written in C# for reading Microsoft Excel files
At a glance
- What is it?
- ExcelDataReader is a C# library that parses Excel workbooks from a stream, covering formats from Excel 2.0 BIFF2 up to modern xlsx. It fits server-side and container ingestion where Excel cannot run, and its CSV reader costs a full extra pass over the file unless you change one setting.
- Who is it for?
- Adopt ExcelDataReader when a .NET job has to read many workbooks on a server, in a container or on Linux, where Excel and COM are absent. Do not adopt it to write files, and think twice before using its CSV reader in a typed pipeline, because every CSV field comes back as a string.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
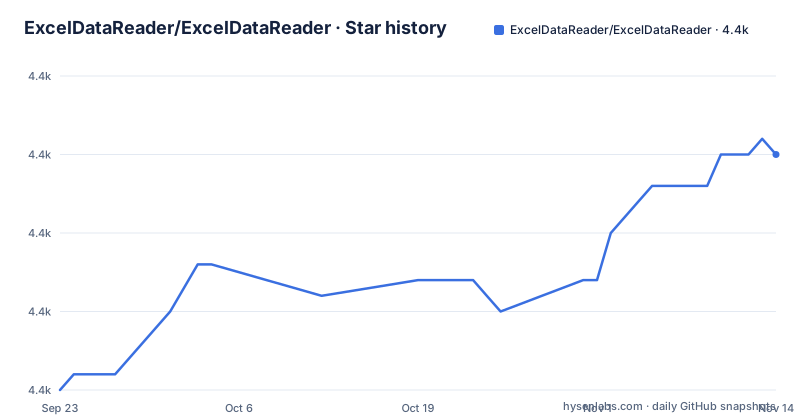
- ExcelDataReader/ExcelDataReader4,430 ★ · +15
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| ExcelDataReader/ExcelDataReader | 4.4k | 4.4k |
15 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One factory call, and the stream itself picks the binary parser
ExcelDataReader exists for a narrow job: reading a Microsoft Excel file you were handed, on a machine where Excel is not installed. ExcelReaderFactory.CreateReader(stream) inspects the stream and picks the parser. No file extension is required, and no Excel installation, COM registration or desktop session is involved.
That autodetection is why the format table is so wide. The same entry point handles .xlsx and .xlsb in the OpenXml container, .xls in CFB containers going back to BIFF5, .xls in bare BIFF2, BIFF3 and BIFF4 with no container at all, and SpreadsheetML .xml from the 2002 and 2003 XML Spreadsheet era; plain CSV goes through the separate CreateCsvReader call. A file written by Excel 2.0 and one written by Microsoft 365 arrive at the same call site.
The reader implements System.Data.IDataReader and IDataRecord, so the ADO.NET shape applies. Read() moves down a row, NextResult() advances to the next sheet, ResultsCount gives the sheet count, Name and CodeName identify the current sheet, FieldCount and RowCount describe its shape. Depth always returns 0 because nested result sets are not exposed at all. That is a design limit, not a gap waiting to be filled.
One detail gets skipped easily. RowCount counts terminal empty rows, which AsDataSet() excludes. The two ways of getting the same sheet therefore disagree on row totals, and code that asserts a count after loading through AsDataSet() will not match a RowCount read.
The CSV path parses the file twice, and one option removes the second pass
CSV is the sharp edge here. ExcelReaderFactory.CreateCsvReader is a separate call from CreateReader, and by default it examines the whole file during initialization to determine its column and row counts, before the caller walks the records.
The escape hatch changes the contract as well as the cost. Setting AnalyzeInitialCsvRows limits that analysis to the specified number of rows, and FieldCount is then based on the sampled rows. The documented price is specific: RowCount throws InvalidOperationException on CSV files when AnalyzeInitialCsvRows is in use. Ask for RowCount on a CSV after setting that option and you get an exception, not a slower answer.
Encoding and separator detection are configurable through FallbackEncoding and AutodetectSeparators. AutodetectSeparators lists possible delimiters, including multi-character ones, and the chosen one is exposed as reader.CsvSeparator; FallbackEncoding is for files that are not UTF-8 and have no encoding marker.
A library billed as fast, whose CSV reader reads the file twice
The README opens by calling this a lightweight and fast library, and for binary work that is a fair description of an approach with no COM layer and no Excel process. The CSV route is where the claim gets thinner, and the documentation is upfront about it: by default the whole file is examined during initialization unless AnalyzeInitialCsvRows is set.
The documented cost is easy to skim past. The whole-file analysis happens during initialization, so the wait lands ahead of your first Read() call rather than behind it.
CSV is also the branch where types disappear. Every field comes back as a string, with no attempt to convert numbers or dates. One column can hold a value, the same value with trailing zeros, and the same value again with a different decimal separator across three rows, and all three reach your code as text. Type interpretation is the caller's job, and that is a different amount of work from the binary paths.
Getting the binaries from NuGet, and the 3.0 package split
Installation goes through NuGet, either the Visual Studio Package Manager Console or the Manage NuGet Packages interface. Since version 3.0 the project ships as more than one package, and the base package is the one you want if you intend to drive the reader yourself.
One command covers the install, run once per package. The DataSet extension supplies AsDataSet() and pulls the base package in with it.
Install-Package <package>Run it twice, with the base package name and then with the DataSet extension name. Both packages target net462, netstandard2.0 and netstandard2.1. The base package alone gives the low level reader interface; the DataSet package is for populating a System.Data.DataSet.
Pull requests go to the develop branch, which is the default branch. Pin the package version you build against rather than tracking the default branch.
Reading a sheet, then jumping to the CSV reader
First use is the factory call plus a two level loop: an outer do/while over NextResult() for sheets, and an inner while over Read() for rows. That shape is what the sample code shows, and it is what the method table describes.
For plain text you swap the factory method and nothing else on that call site. This is the shape the sample code uses, opening the file stream and handing it straight to the factory:
using (var stream = File.Open(filePath, FileMode.Open, FileAccess.Read))
{
    using (var reader = ExcelReaderFactory.CreateReader(stream))
    {
        while (reader.Read())
        {
            // reader.GetDouble(0);
        }
    }
}
Two configuration keys sit next to the CSV entry point, FallbackEncoding and AutodetectSeparators, and they are the ones worth setting deliberately rather than leaving at defaults.
The AsDataSet() helper from the DataSet package is the shorter path when you just want rows. The project states that it is not always available or desirable, which is a hint to check whether it strips the trailing empty rows RowCount reports before you build assertions on top of either.
Where EPPlus and the Open XML SDK split from this reader
ExcelDataReader is read only, and that single fact decides most comparisons. It returns rows through IExcelDataReader and never writes a workbook back.
EPPlus is positioned as a full Office Open XML library, so it covers the write path, cell formatting and styling where this reader stops at values. Choose EPPlus when the job is to produce a spreadsheet, and this reader when the job is to consume one.
The Open XML SDK works at a different level again. It addresses an xlsx as a package of parts, exposing the sheet XML and the shared string table as document nodes you walk yourself. ExcelDataReader hides that structure and hands you typed cell values. If you need comments, formatting, or any part of the package outside the cell grid, the SDK exposes it and this library does not.
The reader goes one direction only, and nothing is written back
Two boundaries decide whether this library fits. First, direction: it reads. There is no write, edit or save path in the described API, so a round trip through ExcelDataReader means writing the file with something else.
Second, deployment. The library is MIT licensed, and no per-seat or per-machine fee is described for production use.
Upgrade cost is close to nothing for a read-only service: there is no schema to migrate and nothing written back to disk. The repository is not archived and the last push was on 2026-11-02.
Editorial conclusion
Adopt ExcelDataReader when a .NET job has to read many workbooks on a server, in a container or on Linux, where Excel and COM are absent. Do not adopt it to write files, and think twice before using its CSV reader in a typed pipeline, because every CSV field comes back as a string. Before committing, run the reader against the oldest file format your users actually send: BIFF2 and BIFF3 files have no ZIP container at all, and RowCount throws InvalidOperationException on a CSV read whenever AnalyzeInitialCsvRows is set.
Frequently asked questions
How do I install ExcelDataReader in C#?
The project directs you to NuGet through the Visual Studio Package Manager Console or the Manage NuGet Packages interface. Installing ExcelDataReader gives you the low level reader interface; installing ExcelDataReader.DataSet additionally provides the AsDataSet() method and pulls the base package in with it. Both target net462, netstandard2.0 and netstandard2.1.
How do I use ExcelDataReader in C#?
Open the file stream and pass it to ExcelReaderFactory.CreateReader, then loop with Read() for rows and NextResult() to move between sheets. For comma separated text use ExcelReaderFactory.CreateCsvReader instead, configured through FallbackEncoding and AutodetectSeparators. ResultsCount, Name, FieldCount and RowCount describe the current sheet.
Is ExcelDataReader free?
Yes. The repository describes no paid tier, and the packages are distributed through NuGet for free. There is no licence fee described for reading files in a production application.
Is ExcelDataReader open source?
Yes. The repository is published under the MIT licence, with source under src/ and the licence text in the top level LICENSE file. Contributions are handled by forking and submitting pull requests to the develop branch, which is also the default branch.
What is the difference between ExcelDataReader and EPPlus?
ExcelDataReader is read only. It returns rows through an IExcelDataReader that extends System.Data.IDataReader and never writes a workbook. EPPlus is positioned as a full Office Open XML library, so the approaches diverge the moment your code has to produce a file or handle formatting rather than only consume one.
Should I use ExcelDataReader or the Open XML SDK instead?
The Open XML SDK works at the package level, where parts of an xlsx such as the sheet XML and the shared string table are addressed as document nodes you walk yourself. ExcelDataReader hides that structure and hands back typed cell values. If you need formatting, comments or write access, the SDK path exposes those and this reader does not.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/exceldatareader-exceldatareader)Star history chart for your README
[](https://hysenlabs.com/projects/exceldatareader-exceldatareader)Was this useful?