Haxl and the N+1 select problem in Haskell
A Haskell library that simplifies access to remote data, such as databases or web-based services.
At a glance
- What is it?
- Haxl is Facebook's Haskell library for batching and concurrency in remote data access, with a generic IO data source and a SQL example that folds many selects into one query. It asks you to write one data source per backend, and that work is not small.
- Who is it for?
- Adopt Haxl if your Haskell service fans out to a database, an identity API and a flag store in the same pass, and if you can afford to write a data source module for each backend. Do not adopt it for a single hot query or a small application, where a bounded Async pool or a rewritten IN clause costs less than a new abstraction.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Haskell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
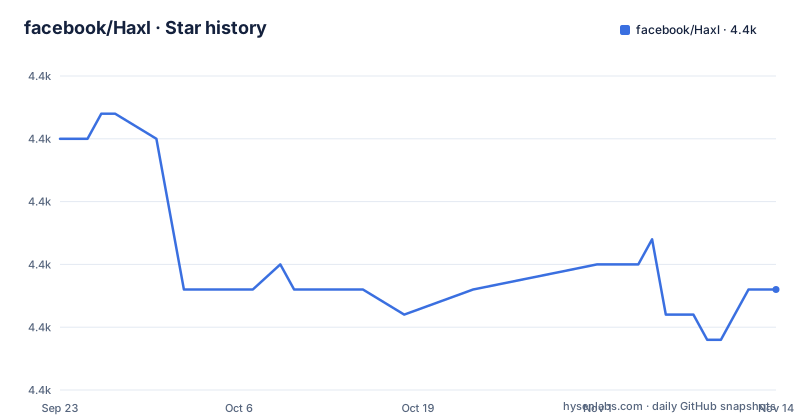
Star history
- facebook/Haxl4,369 ★ · -6
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| facebook/Haxl | 4.4k | 4.4k |
-6 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The N+1 select problem Haxl was built to absorb
A Haskell service that reads remote data hits a wall fast. One row of output needs one request, a thousand rows need a thousand requests, and the code either blocks on each one in turn or spawns threads it then has to manage. The README links The Story of Haxl, which explains how Haxl came about at Facebook.
The audience is Haskell engineers writing services that fan out to SQL databases, REST APIs or internal services and who do not want every handler to carry its own batching logic. Haxl claims four automatic behaviours: batch multiple requests to the same data source, request data from multiple data sources concurrently, cache previous requests, and memoize computations. That list is the whole pitch, and each item is a behaviour you would otherwise write by hand.
The sharpest demonstration in the repository is not the framework itself but the SQL example under example/sql. Its readme explains how Haxl addresses the N+1 select problem by batching multiple queries into a single query without the programmer specifying that behaviour. A developer still writes one ordinary select per logical call.
Two packages, and a data source you have to build yourself
The repository ships two Haskell packages. haxl is the core framework. haxl-facebook lives in example/facebook and is described in the README as an incomplete example data source for the Facebook Graph API, built on top of the fb package.
The structural point matters for anyone budgeting the work. Haxl is not a driver library. It is the machinery that runs requests, and the thing that actually knows how to talk to your database or your API is a data source, which the README calls the thin layer between Haxl and the data you want to fetch. For every backend, that layer is yours to write. The framework cannot batch a protocol it has never seen.
If you only need arbitrary IO concurrency, the README points at Haxl.DataSource.ConcurrentIO, described as a generic data source that can perform arbitrary IO operations concurrently, given some boilerplate to define the IO operations you want to perform. That is the shortest path in, and the boilerplate sentence is the honest caveat. Wrapping an existing client in the required interface is not a large job, but it is not zero either.
Getting Haxl without an install recipe
There is no install command anywhere in the README.
The project gives you three places to go. Haxl documentation is published on Hackage under the package name haxl, which is where a Haskell developer normally picks up the library and its API surface. A stack.yaml and stack.yaml.lock sit at the top level of the repository, and the repository root carries haxl.cabal, so the standard Haskell build path applies to the checkout. If you want the worked example rather than the library, the README links an example Facebook data source that walks through querying the Graph API concurrently.
The first real use, then, is a code task rather than a shell task: add haxl to your own package dependencies and write the data source module for one backend. The example/facebook readme and the SQLite blog engine walkthrough linked from the README are the two published routes through those steps. Neither is reproduced in the root README, so plan on following the links rather than a snippet.
Caching and memoization change what your handler recomputes
Two of the four automatic behaviours are about avoiding repeated work rather than about scheduling work, and they are the ones that surprise people.
Caching previous requests means a second lookup inside the same execution can return an earlier result instead of going out again. Memoize computations extends the same idea to values derived from fetched data. Both are what make declarative code cheap: you can ask for a user inside a loop without reasoning about whether that user was already loaded.
The flip side is that Haxl changes the semantics of your code without changing a single line of it. Code that assumed each call meant a fresh read will no longer have that assumption. If part of your service depends on seeing the current state of a row on every access, you need to know how Haxl scopes its cache, and the root README does not explain cache lifetime or invalidation. Read the Hackage documentation before you assume a cache is scoped per request rather than per thread or per environment.
Where the automatic batching has nothing to grab
Concurrent IO against several sources is only as safe as the sources. Haxl can run three data sources at once, but it cannot make a non thread safe driver safe, and the ConcurrentIO boilerplate it asks you to write is where that decision has to be made. Separately, haxl-facebook is labelled incomplete in the README, so it is a teaching artifact rather than a maintained client.
Haxl next to plain IO and next to a hand written cache
The obvious alternative is not a competing library but the ordinary Haskell approach: run your effects in IO, use a bounded pool such as Control.Concurrent.Async when you want parallelism, and accept one request per call. The difference in approach is exactly what Haxl removes. With plain IO you choose concurrency manually and you write batching yourself, either by restructuring the query or by loading a page and indexing it. Haxl keeps the per item calls in the source and moves deduplication, request grouping and memoization into the runtime.
Another alternative is to solve the problem at the data layer instead. Batch the SQL by rewriting the query as a join or an IN clause, use a connection pooler, and cache with a library such as memcached or a Redis client. That approach avoids a framework and keeps request lifetime in application code, which is a real advantage when a request must never see stale data. Haxl's route wins when calls are spread across several sources and the fan out pattern repeats; the SQL route wins when there is one hot query and you are willing to change its shape.
For a single backend with a known access pattern, Haxl adds a dependency and a data source for something a few lines of Async could do. For a service that reads from a database, an identity service and a feature flag store in one pass, that is the cost worth paying.
Two example data sources do the teaching the core package does not
A large share of what Haxl teaches lives outside the library. The repository root holds Haxl/ for the library itself, example/ for two worked data sources, tests/ for the test suite, and stack.yaml for the build definition. That split tells you where to look when a data source misbehaves, and it is also where the maintenance burden sits.
example/sql is the one to read first if your problem is a database. Its readme is the clearest statement in the repository of what the automatic batching is worth. example/facebook is the one to read if your problem is a REST API, and it is explicitly labelled incomplete, so treat it as a pattern to copy rather than a component to depend on.
The generic data source in Haxl.DataSource.ConcurrentIO is the third piece of the teaching material and the only one you can lift directly. The README says it needs a bit of boilerplate to define the IO operations you want to perform.
Editorial conclusion
Adopt Haxl if your Haskell service fans out to a database, an identity API and a flag store in the same pass, and if you can afford to write a data source module for each backend. Do not adopt it for a single hot query or a small application, where a bounded Async pool or a rewritten IN clause costs less than a new abstraction. Do not adopt it expecting the GitHub releases to track the source tree: the latest one listed is 0.5.1.0 from July 2017, while the last push was in March 2026. Before committing, open Haxl.DataSource.ConcurrentIO and check whether its boilerplate covers your access pattern, then read the cache lifetime rules in the Hackage documentation, because caching and memoization change handler semantics without changing any call site.
Frequently asked questions
What problem does Haxl solve in Haskell?
Haxl simplifies access to remote data such as databases and web based services. It automatically batches requests to the same data source, runs requests across data sources concurrently, caches previous requests and memoizes computations.
What is a Haxl data source and do I have to write my own?
A data source is the thin layer between Haxl and the data you want to fetch, whether that is a database, a web API or a cloud service. To use Haxl in your own application you will need to build one or more, though Haxl.DataSource.ConcurrentIO offers a generic starting point for arbitrary IO operations given some boilerplate.
How does Haxl fix the N+1 select problem?
The SQL example explains that Haxl can address N+1 selects by automatically batching multiple queries into a single query, without the programmer specifying this behavior.
How do I install Haxl?
The root readme gives no install command. It points to the Haxl documentation on Hackage for the haxl package, and the repository ships haxl.cabal plus stack.yaml for building from a checkout.
Is the haxl-facebook package production ready?
The readme describes haxl-facebook as an incomplete example data source for accessing the Facebook Graph API. It exists to show how a Haxl data source is built on top of the fb package.
What license does Haxl use?
Haxl uses the BSD 3-clause License, with the license text in the LICENSE file in the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebook-haxl)Star history chart for your README
[](https://hysenlabs.com/projects/facebook-haxl)Was this useful?