FalkorDB: a Redis-protocol graph database built on sparse matrices
A super fast Graph Database uses GraphBLAS under the hood for its sparse adjacency matrix graph representation. Our goal is to provide the best Knowledge Graph for LLM (GraphRAG).
At a glance
- What is it?
- FalkorDB stores graph adjacency as sparse matrices and executes OpenCypher through linear algebra, positioning itself as a low-latency knowledge graph for LLM and GraphRAG workloads. The design is genuinely different from row-based graph engines, but the licence metadata and the query surface deserve a close look before adoption.
- Who is it for?
- FalkorDB fits teams that already speak OpenCypher and want a knowledge graph reachable through ordinary Redis clients, especially where the graph is a retrieval layer for an LLM and the queries are traversals rather than global analytics.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
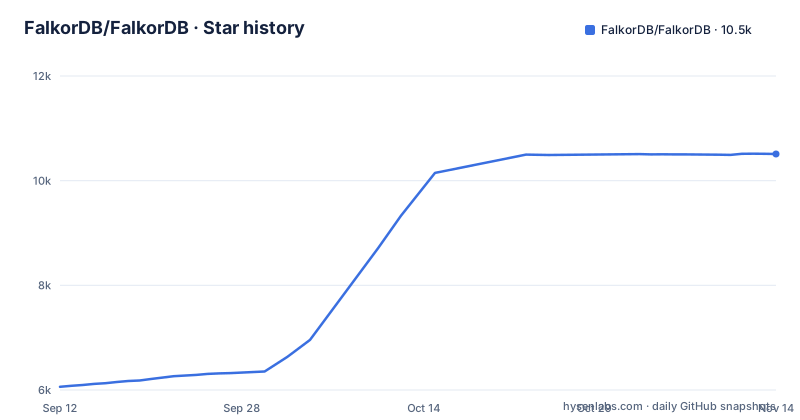
- FalkorDB/FalkorDB10,510 ★ · +4,449
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| FalkorDB/FalkorDB | 6.1k | 10.5k |
4,449 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem FalkorDB targets: graph traversal latency inside an LLM loop
FalkorDB's stated goal is to be a knowledge graph for large language models, with the README framing low latency as the priority so that information delivery stays fast. That framing matters because it implies a specific workload shape. In a GraphRAG pipeline the graph is queried many times per user request, often for short multi-hop traversals that pull a neighbourhood of entities and relationships to feed a prompt. A database that answers those traversals quickly is worth more than one that answers a single large analytical job quickly.
The project also describes itself as multi-tenant, which points at a second use case: many separate graphs served from one instance. The README's own example reflects this, calling select_graph('MotoGP') and select_graph('social') to address distinct graphs by name rather than creating separate database deployments. For anyone building agent memory, where each agent or each session might own a graph, that naming model is the relevant part of the design.
Fraud detection and cloud security appear in the tagline as domains the project is aimed at, but the documented surface is property graph storage plus OpenCypher querying. Treat the domain list as positioning, not as a feature inventory.
Sparse adjacency matrices and linear algebra as the execution model
The central claim in the README is that FalkorDB is the first queryable property graph database to represent the adjacency matrix using sparse matrices and to query with linear algebra. The mechanism follows from that: a graph is stored as a sparse adjacency matrix, and a query is evaluated as operations over that matrix rather than as pointer chasing through adjacency lists.
Sparse representation means only non-zero entries are stored, so an edge set that is a tiny fraction of the possible node pairs does not pay for the empty space. Whether that translates into an advantage for a given query is something only measurement against your own data will settle.
The README also states compliance with the Property Graph Model, meaning nodes and relationships carry attributes, and compatibility with OpenCypher, with the caveat that FalkorDB adds proprietary extensions for advanced querying. That last phrase is the one to watch. OpenCypher compatibility plus extensions means the query language is a superset in places, and any Cypher you port from another engine should be checked rather than assumed.
Running it: one Docker command, port 6379, and a browser UI on 3000
The README gives a single command to start an instance:
docker run -p 6379:6379 -p 3000:3000 -it --rm -v ./data:/var/lib/falkordb/data falkordb/falkordb
Three details are worth extracting. Port 6379 is the standard Redis port, which is the clearest signal of how the server presents itself. Port 3000 serves a browser interface, and the README's second step is simply to open http://localhost:3000. The volume mount at /var/lib/falkordb/data is where the graph data lives, so persistence depends on that mount being present and on the container not being discarded; the --rm flag in the documented command means the container itself is ephemeral.
From a client, the README shows two paths. The Python client connects with FalkorDB(host='localhost', port=6379) and then db.select_graph('MotoGP') to obtain a graph handle, followed by g.query(...) with a Cypher string. The README example then queries which riders ride for Yamaha. The alternative path is the raw Redis protocol: the README shows redis-cli sending GRAPH.QUERY social "CREATE (:person {name: 'roi', age: 33, gender: 'male', status: 'married'})", where GRAPH.QUERY takes the graph name as its first argument and the query as its second. That command name is the interoperability hook, and the README states plainly that you can call FalkorDB's commands from any Redis client.
Client libraries and the language coverage trade-off
The README lists official clients for Java (jfalkordb, BSD, published to Maven), Python (falkordb-py, MIT, on PyPI), Node.js (falkordb-ts, MIT, on npm), Rust (falkordb-rs, MIT, on crates.io), Go (falkordb-go, BSD), and C# (NFalkorDB, Apache-2.0, on NuGet). The licence split is notable: the Python, Node and Rust clients are MIT, Java and Go are BSD, and the C# client is Apache-2.0. Those are permissive terms for the client code.
The server is a separate question. The repository metadata reports the licence as NOASSERTION, while the Cargo.toml manifest declares `SSPL-1.0`, the Server Side Public License. These two signals do not agree, and a manifest field is a label rather than the licence text itself. Anyone who needs to know the terms should read the LICENSE file on the main branch directly. No interpretation of those terms is offered here; the point is that the metadata and the manifest conflict, and that conflict is exactly the kind of thing that surfaces late in a procurement review.
The language coverage itself is broad enough that most teams will find a native client. Where a client does not exist, the Redis protocol fallback applies, though the README warns that the exact method for sending raw commands varies by client. That warning is honest: raw command access is a lowest common denominator, not a uniform API.
Where the documented surface runs out
The README is a getting-started document, and the gaps are visible. Questions about transaction semantics, isolation levels, memory behaviour under a large graph, sharding and replication need to be answered from the FalkorDB documentation or by testing.
The README says OpenCypher support includes proprietary extensions for advanced querying. Anyone migrating an existing Cypher workload should check the FalkorDB documentation to see which constructs are standard and which are FalkorDB-specific. The demo directory is referenced as the place to see FalkorDB in action, which suggests the examples carry more weight than the prose.
A second limitation is structural rather than documented. A sparse-matrix execution model is a poor fit when the query is not a traversal. If your workload is dominated by full-graph scans, heavy aggregation over every node, or iterative algorithms that touch the entire edge set repeatedly, the sparse representation buys you nothing that a conventional adjacency store would not also provide, and the linear algebra layer adds a mental model you have to learn. FalkorDB is the wrong tool when the graph is an analytics target rather than a lookup structure.
How this differs from a conventional property graph engine
The obvious comparison is a property graph database that stores adjacency as index-free linked lists and executes Cypher by walking those pointers. In that model, a traversal step costs roughly the degree of the node you are leaving, and the engine's job is to follow edges efficiently. FalkorDB instead keeps the adjacency structure as a sparse matrix and evaluates the query as linear algebra over it. The difference shows up in how work is batched: matrix operations naturally process a set of frontier nodes together, while pointer chasing tends to be per-node.
That is the real distinction, and it is a design difference rather than a feature checklist item.
The trade-off is in the query language. A conventional engine's Cypher support tends to track the standard closely because the execution model maps onto the language's traversal semantics. FalkorDB's README claims OpenCypher compatibility plus extensions, which is a broader surface to verify. If your application generates Cypher programmatically, the generator is what you should test against FalkorDB, not a handful of hand-written examples.
Release cadence and what upgrading actually costs
The release history shows v4.22.3 on 2026-10-28, v6.0.3 on 2026-10-22, and v4.22.2 on 2026-10-20. Two release lines, 4.22 and 6.0, are being published side by side, so check which line you are on before upgrading. The last push to the repository is dated 2026-11-02, which is consistent with ongoing work.
The Docker command in the README mounts a host directory at /var/lib/falkordb/data, which means an upgrade is a matter of replacing the image and reattaching the same volume. Whether the on-disk format is forward compatible across 4.22.x is not stated, so the safe assumption is that a patch upgrade should be rehearsed against a copy of the data directory before it touches production.
On licence cost, the Cargo.toml manifest declares SSPL-1.0 (Server Side Public License) while the repository metadata reports NOASSERTION. Those are not the same thing and the discrepancy is unresolved. The practical implication is that if your deployment model involves offering FalkorDB as a service to third parties, you need to read the LICENSE file on the main branch and get your own answer. Nothing here substitutes for that.
Editorial conclusion
FalkorDB fits teams that already speak OpenCypher and want a knowledge graph reachable through ordinary Redis clients, especially where the graph is a retrieval layer for an LLM and the queries are traversals rather than global analytics. Teams that need a permissively licensed server, or that rely on bulk analytical graph algorithms over a whole graph, should verify the licence file at LICENSE on the main branch and check whether their workload maps onto the supported OpenCypher surface before committing. The first concrete step is to run the documented docker command against a copy of your own data and confirm the exact Cypher constructs your application emits are accepted.
Frequently asked questions
what is falkordb
A multi-tenant graph database written in Rust that loads into Redis. It stores the adjacency matrix of the graph as a sparse matrix and queries it with linear algebra, supports the OpenCypher query language with proprietary extensions, and can be driven from any Redis client or from one of six official client libraries.
how to use falkordb
Run the container with the published ports 6379 and 3000, then open http://localhost:3000 in a browser, or connect a client library to port 6379. Commands go through a named graph, as in the redis-cli example that sends a GRAPH.QUERY with a CREATE clause.
Is FalkorDB open source, and under what license?
The manifest declares SSPL-1.0 and a LICENSE file sits at the repository root, but the repository's own license metadata carries no value, so the file itself is the only authoritative text. The six official client libraries are listed under BSD, MIT and Apache-2.0, and those licenses belong to the clients rather than to the database.
Is FalkorDB in memory, and where does its data go?
The README's quick start mounts a local directory at /var/lib/falkordb/data inside the container and passes --rm, so the container is discarded while that directory remains. Check the FalkorDB documentation for how memory use and persistence work.
Is FalkorDB free?
The README shows a Docker image for self-hosting and a hosted signup at app.falkordb.cloud; check the FalkorDB website for the pricing of the hosted service.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- Three crashes, one body shop: a fraud agent where the graph picks the next querydev.to · Oct 18, 2026 · 5 points · 0 comments
- The $6,000 we couldn't take backdev.to · Oct 17, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/falkordb-falkordb)Star history chart for your README
[](https://hysenlabs.com/projects/falkordb-falkordb)Was this useful?