Firecrawl: A Web Data API That Turns the Messy Web Into Agent-Ready Markdown
The API to search, scrape, and interact with the web at scale. 🔥
At a glance
- What is it?
- Firecrawl is an open-source API and self-hostable service for searching, scraping, and interacting with web pages. It targets AI agents and developers who need clean markdown or structured JSON without managing proxies or JavaScript rendering.
- Who is it for?
- Adopt Firecrawl if you are building AI agents or data pipelines that need reliable, LLM-ready web content without proxy management. Skip it if you require a permissive license for proprietary use, or if your workloads are simple static pages where a plain HTTP client suffices.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
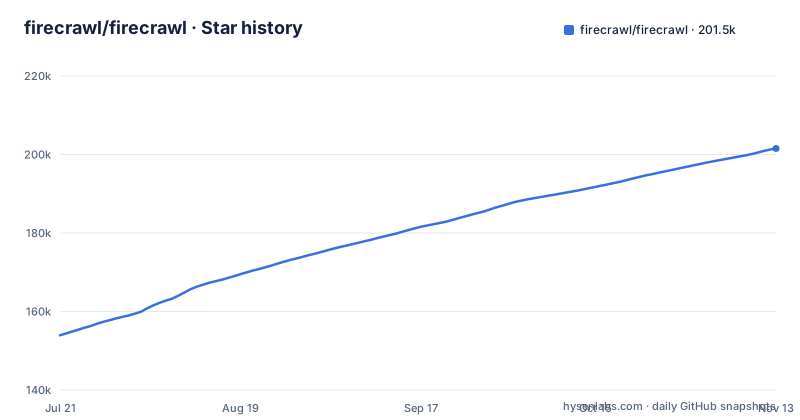
- firecrawl/firecrawl201,530 ★ · +47,594
| Repository | 2026-07-21 | 2026-11-13 |
|---|---|---|
| firecrawl/firecrawl | 153.9k | 201.5k |
47,594 Stars in the last 115 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Scraping the Modern Web Is a Proxy Nightmare
Firecrawl solves a specific pain: fetching web pages that are behind JavaScript rendering, rate limits, or bot detection. The README claims it covers 96% of the web, including JS-heavy pages, and that it handles rotating proxies, orchestration, and rate limits with zero configuration. That is a bold promise, and the README links the benchmark to a post on firecrawl.dev rather than describing the method, so treat the number as a vendor claim until you verify it against your own target sites. The intended user is an AI agent developer or a data engineer who wants clean markdown or structured JSON, not raw HTML with script tags. Firecrawl positions itself as the context API for AI agents, meaning it turns a messy URL into a digestible text blob that a language model can consume without burning tokens on boilerplate.
Architecture: A Single API Wrapping Search, Scrape, and Interact
The repository is a TypeScript monorepo that exposes a REST API and official SDKs for Python and Node.js, plus a CLI. The core flow is straightforward: you send a URL or a search query to an endpoint, and Firecrawl returns markdown, HTML, screenshots, or structured JSON. The Search endpoint does a web search and returns full page content for each result, which is unusual because most search APIs give snippets. The Scrape endpoint converts a single URL. The Interact endpoint goes further: you scrape a page, get a scrape_id, then send prompts like 'Search for mechanical keyboard' or 'Click the first result'. The service executes those actions in a live browser session and returns an output string plus a liveViewUrl for visual verification. That interaction model is the differentiator: it is not just a scraper, it is a remote browser you can drive with natural language.
Getting Started: SDKs, CLI, and a Single Command for Agent Integration
The quick start requires an API key from firecrawl.dev, and the README shows Python, Node.js, cURL, and CLI examples. For Python, you install the firecrawl package and instantiate a client with your key. The search call is app.search('firecrawl', limit=5), and the scrape call is app.scrape('firecrawl.dev'). The CLI is invoked as firecrawl scrape https://firecrawl.dev, and it accepts a --only-main-content flag to strip navigation. For agent integration, the README highlights a Skill feature: npx -y firecrawl-cli@latest init --all --browser installs a skill that works with Claude Code, Antigravity, and OpenCode. The setup is genuinely minimal: no proxy configuration, no headless browser management, just an API key and a call.
The Interaction Model: Where Firecrawl Differs from a Simple Scraper
Most scraping tools fetch a page and return its HTML. Firecrawl's Interact endpoint adds a stateful session: you scrape first, get a scrape_id, then issue multiple prompts against that same session. The README example uses Amazon: scrape the product page, then prompt 'Search for mechanical keyboard', then 'Click the first result'. The output is a JSON object with a success flag, an output string, and a liveViewUrl. That live view is a useful debugging aid, because you can see what the browser actually did. This design is clearly built for agents that need to navigate multi-step workflows, like filling a form or comparing prices across pages. The trade-off is that each interaction is a network call, so latency accumulates. The README claims a P95 latency of 3.4 seconds across millions of pages, but that likely applies to a single scrape, not a chain of interactions. For real-time agent loops, that latency could be a bottleneck.
What the README Does Not Tell You: Limitations and Self-Hosting Reality
The README is heavy on benefits and light on constraints. It does not describe pricing or the resource footprint of self-hosting in the opening sections. The license is AGPL-3.0, which is a genuine limitation for companies that want to embed the code in proprietary products without open-sourcing their own code. The README says 'Open source and available as a hosted service', and the quick start tells you to sign up at firecrawl.dev for an API key. Another gap: the README shows a benchmark claim of 96% web coverage, but no methodology. If you target niche sites or pages with aggressive anti-bot measures, you should test those specific URLs before trusting the claim. For simple static pages, Firecrawl is overkill.
Alternatives: Comparing to a Plain HTTP Client and Other Scraping APIs
The most obvious alternative is to write your own scraper with an HTTP client like axios or requests, plus a headless browser like Playwright for JS-rendered pages. That approach gives you full control and no per-call cost, but you own the proxy rotation, rate limiting, and CAPTCHA handling. Firecrawl abstracts all of that away. Another alternative is Scrapy, a Python framework for large-scale crawling. Scrapy is a library, not a hosted API, so you manage the infrastructure. The key difference is the interaction model: Scrapy does not have a natural language prompt interface. Firecrawl's closest competitor is probably a combination of a search API (like SerpAPI) and a scraper, but Firecrawl bundles both into one call.
Maintenance and Upgrade Cost: What the Release Cadence Suggests
The repository shows a recent release history: v2.11.0 in June 2026, v2.10 in May 2026, and v2.9.0 in April 2026. The three releases were roughly a month apart, but the latest of them is v2.11.0 from 2026-06-19, while the repository was last pushed to on 2026-11-02. For adopters, that means you should expect API changes and new features regularly. The README uses a v2 API, so there is a chance of breaking changes between minor versions. The CLI is distributed via npx, so updates are automatic. The AGPL-3.0 license means that if you modify the source and deploy it as a network service, you must offer the source code to users. That is a real obligation to plan for if you self-host.
Editorial conclusion
Adopt Firecrawl if you are building AI agents or data pipelines that need reliable, LLM-ready web content without proxy management. Skip it if you require a permissive license for proprietary use, or if your workloads are simple static pages where a plain HTTP client suffices. Before committing, verify the self-hosted deployment's resource requirements and test whether the hosted API's latency and pricing fit your traffic. Also confirm the AGPL-3.0 implications for your distribution model.
Frequently asked questions
Why use Firecrawl?
The readme names three core endpoints, Search, Scrape, and Interact, plus Agent, Crawl, Map, and Batch Scrape. It claims coverage of 96% of the web including JS-heavy pages with a P95 latency of 3.4s, and links its benchmark to a post on its own domain.
Is Firecrawl free to use?
The readme directs you to sign up at firecrawl.dev for an API key and to the playground, and the repository includes a SELF_HOST.md file for self-hosting.
Is Firecrawl safe to use, and what does the repository say?
The readme claims Firecrawl handles rotating proxies, orchestration, rate limits, and JS-blocked content with zero configuration. The compose file leaves USE_DB_AUTHENTICATION at false by default.
how to use firecrawl mcp
The readme says you can connect Firecrawl to any AI agent or MCP client in minutes. Its one-command route is the skill installer, npx -y firecrawl-cli@latest init --all --browser, which works with Claude Code, Antigravity and OpenCode.
how to use firecrawl locally
The compose file is named firecrawl and relies on Postgres, Redis at redis://redis:6379, and a Playwright microservice at http://playwright-service:3000/scrape. SELF_HOST.md is the document for running it yourself.
Is web scraping illegal, and does Firecrawl address it?
It describes the project as an API to search, scrape, and interact with the web and lists document parsing plus click, scroll, write, wait, and press actions.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/firecrawl-firecrawl)
[](https://hysenlabs.com/projects/firecrawl-firecrawl)Star history chart for your README
[](https://hysenlabs.com/projects/firecrawl-firecrawl)Was this useful?