A Paper-by-Paper Path Through Deep Learning's Core Canon
Deep Learning papers reading roadmap for anyone who are eager to learn this amazing tech!
At a glance
- What is it?
- This repository is a curated reading list that orders deep learning's foundational papers from history to method to application. It is a map, not a codebase, and its value depends on how well its selection still matches your goals.
- Who is it for?
- Adopt this roadmap if you are a newcomer who wants a chronological, well-annotated path through deep learning's foundational papers, especially the classic CNN, RNN, and optimization works. Skip it if you need code, tutorials, or coverage of recent advances.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Probably not. The repository last received commits 48 months ago, on November 27, 2022.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
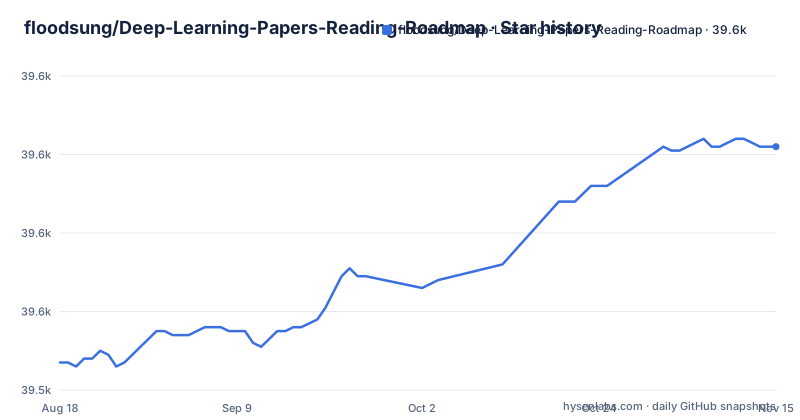
- floodsung/Deep-Learning-Papers-Reading-Roadmap39,602 ★ · +55
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| floodsung/Deep-Learning-Papers-Reading-Roadmap | 39.5k | 39.6k |
55 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Roadmap Actually Solves
The repository answers a single, practical question: which paper should a deep learning newcomer read first? The README frames it exactly that way. It is not a textbook, not a code library, and not a list of every important paper. It is a curated sequence. The author organized the papers along four explicit guidelines: from outline to detail, from old to state-of-the-art, from generic to specific areas, and with a focus on state-of-the-art. That ordering is the core value. A beginner facing thousands of arXiv preprints gets a finite, ordered list with annotations. The intended audience is someone eager to learn the technology through primary sources rather than through a secondary course. The README's tone is personal and direct, which fits a self-study resource. There is no claim of completeness, and the author states they would continue adding papers, implying the list is a living document.
How the Roadmap Is Structured
The structure is hierarchical and thematic. It starts with history and basics, then moves to methods, and later sections cover applications. The first section, Deep Learning History and Basics, begins with a book, then a survey, then milestone papers. The book is Bengio, Goodfellow, and Courville's Deep Learning, marked as the bible. The survey is LeCun, Bengio, and Hinton's Nature paper. Then come DBN papers, the ImageNet evolution with AlexNet, VGGNet, GoogLeNet, and ResNet, and a speech recognition evolution track. The second section, Deep Learning Method, covers models like Dropout, Batch Normalization, Layer Normalization, Binarized Neural Networks, and synthetic gradients. Most entries have a citation, a PDF link, and a short annotation in parentheses, such as AlexNet, Deep Learning Breakthrough. The annotations are terse but useful for prioritization. Star ratings (from one to five) give a quick quality or importance signal, though the criteria for the stars are not defined in the README. The structure lets a reader jump to a topic of interest, but the linear order from old to new is the recommended path.
Getting Started: No Installation, Just Links
The roadmap itself is a markdown README file, so reading it needs no installation. The repository also contains download.py and a requirements.txt listing mistune, beautifulsoup4 and six. To use it, you clone the repository or view it on GitHub, then click the PDF links. The only practical step is to open the README and start with paper [0], the Deep Learning book. The links point to external PDFs, mostly on arxiv, author or university pages, and proceedings sites. Some links include tracking parameters, like the Layer Normalization PDF with a utm_source parameter, which is a minor annoyance but not a blocker. Because the material is just a list, the barrier to entry is essentially zero. You need a PDF reader and an internet connection. The list itself contains no implementations, so you cannot verify one from it, but that is not the point. The point is to guide reading, not to provide runnable examples.
The Selection Bias: What Is In and What Is Out
The roadmap covers a specific slice of deep learning history. It starts with 2006 DBN papers and includes papers up to 2016, with papers like Deep Speech 2 and Microsoft's human parity speech recognition. The ImageNet evolution is well covered, as are core training techniques like Dropout and Batch Normalization. The early sections show a 2016-era perspective. That is a limitation, not a flaw. The roadmap is honest about its focus on state-of-the-art as of its writing, but state-of-the-art moves. A reader who follows this list alone will have a solid historical foundation but will miss most of the last decade's advances.
Annotation Quality: Useful, but Inconsistent
The annotations are a mix of factual labels and subjective praise. Some are descriptive, like Dropout: a simple way to prevent neural networks from overfitting, which is the paper's actual title. Others are evaluative, like Amazing Work or Outstanding Work in 2015. A five-star paper like the Nature survey is clearly foundational, but a three-star paper like VGGNet is also important. The inconsistency is a minor weakness. A newcomer might wonder why AlexNet gets five stars and VGGNet gets three. The annotations do not explain the difference. Still, the labels are short and do not get in the way. The README also includes a quote after the first section, suggesting that after reading the history papers, the reader will have a basic understanding of CNN, RNN, and LSTM, and can then choose papers based on interest. That guidance is practical and matches the roadmap's purpose.
The Real Limitation: No Code and No Updates
The biggest limitation is that the roadmap is static. The README does not include code, notebooks, or exercises. You cannot reproduce the papers' results from this repository. It is purely a reading list. The second limitation is the unknown maintenance status. The last push was on 2022-11-27, and the repository has no GitHub releases. The PDF links may rot over time. The README itself acknowledges the author would continue adding papers, but it does not confirm that happened. If you rely on this roadmap as your sole source, you will miss newer foundational work. It is also not a substitute for a course or a textbook. The Deep Learning book is recommended, but the roadmap does not provide study questions or projects. For a hands-on learner, this is the wrong tool. The repository's value is as a historical map, not as a living resource.
Alternatives: From Static Lists to Interactive Courses
A direct alternative is the Deep Learning Book itself, which the roadmap recommends. The book provides the same foundational material in a structured, self-contained format, with a consistent narrative. The difference is that the book is a full textbook, while the roadmap is a curated list of external papers. Another alternative is a modern course like fast.ai or DeepLearning.AI, which include code, video lectures, and current topics. Those courses are interactive and updated, but they are not paper-first. If your goal is to read primary sources, the roadmap is closer to that. A third alternative is a curated list like Awesome Deep Learning on GitHub, which aggregates many resources. The roadmap's advantage is its explicit sequence and annotations. Its disadvantage is the lack of code and the stale selection. Choose the roadmap if you want a guided paper reading path; choose a course if you want hands-on practice.
Maintenance and Licensing: What You Need to Know
The repository's license is listed as unknown in the repository metadata. That is a practical concern if you plan to reuse the list or the annotations. Without a license, you do not have explicit permission to copy or redistribute the README content beyond fair use. For personal study, that is not a problem. For educational use in a course or a publication, you should contact the author or seek permission. The repository is not archived, but its last push was on 2022-11-27. The README's promise of continued additions is not verifiable from the repository. If you fork or bookmark it, you should check the commit history on GitHub yourself. The PDF links are external, so their longevity depends on the original publishers, not the repository. Verify any link before relying on it for a class or study group.
Editorial conclusion
Adopt this roadmap if you are a newcomer who wants a chronological, well-annotated path through deep learning's foundational papers, especially the classic CNN, RNN, and optimization works. Skip it if you need code, tutorials, or coverage of recent advances. Before relying on it, verify that the PDF links still resolve and check the repository's last push date, since some links may rot and the field has moved on. Use it as a historical backbone, then supplement with current survey papers and primary sources for recent architectures.
Frequently asked questions
What is a roadmap for learning deep learning in this repository?
It is a single markdown file ordering deep learning papers by four rules: from outline to detail, from old to state of the art, from generic to specific areas, and a focus on state of the art. Its entries range from 2006 deep belief net papers and a 2015 textbook through ImageNet and speech papers, including arXiv:1610.05256 from 2016.
How does the Deep Learning Papers Reading Roadmap handle explaining a DNN to a beginner?
The list is made of paper citations with short glosses rather than explanations, and the README states that reading the first block gives you a basic understanding of architectures including CNN, RNN, and LSTM, so the teaching is expected to come from the papers rather than from the list.
Is deep learning very difficult according to the Deep Learning Papers Reading Roadmap?
Entries are annotated with a short gloss and a run of star symbols that are not labelled as a difficulty scale, so they cannot be used to judge how hard a paper is or how long it will take you.
Does the Deep Learning Papers Reading Roadmap cover ChatGPT?
The early sections end with Xiong and others on human parity in conversational speech recognition, arXiv:1610.05256 from 2016, and the last push to the repository is dated 2022-11-27, so it is not a source for ChatGPT.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- 17 GitHub Repositories to Learn AIdev.to · Nov 2, 2026 · 3 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/floodsung-deep-learning-papers-reading-roadmap)Star history chart for your README
[](https://hysenlabs.com/projects/floodsung-deep-learning-papers-reading-roadmap)Was this useful?