Flux.jl: a pure-Julia ML library where any parameterised function is a model
Relax! Flux is the ML library that doesn't make you tensor
At a glance
- What is it?
- Flux.jl is a machine learning library written entirely in Julia, built on the language's native automatic differentiation and GPU support. Its distinguishing claim is that a model can be an ordinary Julia closure, not just a stack of predefined layers.
- Who is it for?
- Adopt Flux if you are already writing Julia and want training code that reads like the rest of your program, with gradients taken over plain functions rather than a separate graph DSL. Do not adopt it if your team is standardised on Python, or if you need a large catalogue of pretrained models and reference implementations to start from.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Julia, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
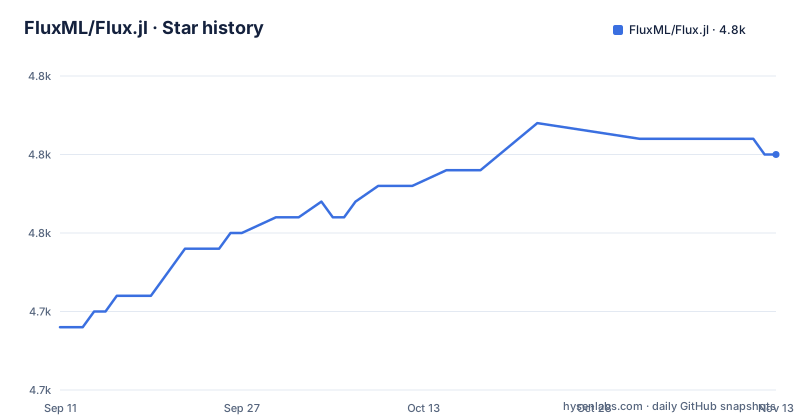
- FluxML/Flux.jl4,755 ★ · +11
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| FluxML/Flux.jl | 4.7k | 4.8k |
11 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Flux.jl addresses: gradients over ordinary Julia functions
Most deep learning frameworks ask you to describe a model in their own vocabulary. You subclass a Module, register parameters in a container, and call a framework-specific backward pass. Flux takes the opposite position. The README states that "almost any parameterised function is a valid model," and gives a closure over three arrays as the demonstration. The library then supplies the machinery to differentiate that function and update whatever parameters it closes over. This matters to people who already work in Julia: numerical code, differential equation solvers, and scientific models are usually written as functions, and Flux lets the trainable part stay a function instead of being rewritten as a layer graph. The audience is therefore narrower than a general ML framework's. It is Julia users who want training inside a larger Julia program, not Python users looking for a faster alternative to what they have.
How the closure-as-model design actually works
The README example defines three arrays w, b and v, then builds a function that computes sum(v .* tanh.(w*x .+ b)). There is no layer object and no explicit parameter registry. The parameters are simply the arrays the closure captures. Flux.setup(Adam(), model) returns the optimiser state for that model. Flux.train! then takes a loss function, the model, the data, and that state, and performs the update loop. The same README example notes the equivalent built-in form, commented out as Chain(vcat, Dense(1 => 23, tanh), Dense(23 => 1, bias=false), only), so the two styles are meant to be interchangeable. The architecture underneath is Julia's own automatic differentiation and GPU array support, which the README calls "lightweight abstractions on top of Julia's native GPU and AD support." That is the whole data flow: a callable, a loss closure, a state object produced by setup, and a training loop that repeatedly calls train!.
Getting it running: the commands and calls in the README
The README says Flux "works best with Julia 1.10 or later," so the first step is a Julia installation at or above that version. The example then begins with using Flux and constructs data as a vector of input/target pairs, here [(x, 2x-x^3) for x in -2:0.1f0:2]. The model is either the closure described above or the commented Chain form. Training is three lines: opt_state = Flux.setup(Adam(), model), then a loop over epochs calling Flux.train!((m,x,y) -> (m(x) - y)^2, model, data, opt_state). The loss is passed as the first argument to train!, written as an anonymous function of model, input and target. The README's plotting lines use Plots and call scatter! directly on the model, which works because the model is callable. Two things are worth noting for anyone copying this. The example uses randn(Float32, 23), so parameter element types are chosen explicitly rather than inherited from a global default. And the closure form depends on w, b and v being in scope; if you build the model inside a let block as shown, the captured arrays are the only thing setup can find.
Where the design costs you: implicit parameters and thin error surfaces
The closure style is convenient until it is not. Because parameters are whatever the function happens to capture, a typo that introduces a new array inside the closure body changes the model silently, and there is no layer list to inspect. A second limitation is scope. The README points to the documentation, the model zoo and the examples folder (GPT-2 pretraining and ResNet on TinyImageNet) for examples, and lists layers and losses for MLPs, convolutional, recurrent and attention models. There is no mention of pretrained weights, a hub, or a conversion tool for checkpoints from other frameworks. If your project depends on starting from an existing trained network, this is the wrong tool, and the README gives no indication otherwise.
Flux.jl compared with PyTorch: same loop shape, different unit of composition
PyTorch is the obvious reference point, and the comparison is not about speed or features. It is about what counts as a model. In PyTorch the unit of composition is nn.Module, a class with a forward method, and parameters are registered attributes discovered by the framework. In Flux, per the README, the unit of composition can be any callable, including a closure that captures arrays. Both frameworks end up with a similar training loop: define a loss, hold optimiser state, iterate. The difference shows up when the model is not a stack of layers. A Julia function that solves a differential equation and returns a prediction can be trained in place, with the closure's captured coefficients as the parameters. In PyTorch the equivalent requires wrapping that computation in a Module and threading tensors through it. The trade is real in both directions: PyTorch's registry makes parameters enumerable and inspectable by default, while Flux's flexibility means the set of trainable values is defined by what your function closes over, which is powerful and easy to get wrong. Neither approach is a superset of the other.
Maintenance, versioning and what the release cadence implies
The repository shows three releases in under two weeks: v0.16.13 on 2026-10-19, v0.16.14 on 2026-10-24 and v0.16.15 on 2026-10-27, with the last push to master on 2026-11-02 and no archive flag. That pattern suggests active patch-level maintenance on the 0.16 line rather than a frozen project. The practical consequence for adopters is that minor-version bumps are frequent enough that pinning matters. Julia's package manager records a compat bound in Project.toml. The README also asks researchers to cite the work via CITATION.bib and links a JOSS paper DOI, which is a maintenance signal in itself: the project expects academic use. On licensing, the repository metadata reports NOASSERTION. Read the LICENSE.md file in the repository before you depend on it, and treat that as a separate step from evaluating the code.
Who should adopt Flux.jl, and what to check first
The fit is a Julia codebase that already has a differentiable or parameterised computation and wants to train part of it. The README's own example is a curve fit, and the closure form generalises to any function whose captured values can be updated. The mismatch is a Python team, or a project whose first requirement is a library of pretrained models and reference architectures. For those, the README offers the model zoo as examples, not as weights. Two verification steps are worth doing before writing production code. First, confirm that Flux.setup and Flux.train! behave as the README's example implies for the version you install. Second, confirm that the layers you need appear in the stable documentation rather than only in the dev documentation, because the README links both and they are not the same target. If both checks pass, the library does something most frameworks do not: it lets the trainable object be a plain Julia function, and that is the reason to pick it over anything else.
Editorial conclusion
Adopt Flux if you are already writing Julia and want training code that reads like the rest of your program, with gradients taken over plain functions rather than a separate graph DSL. Do not adopt it if your team is standardised on Python, or if you need a large catalogue of pretrained models and reference implementations to start from. Before committing, verify two things in the documentation for your target version: that Flux.setup and Flux.train! match the signatures you intend to call, and that the layers you need are actually listed in the API reference rather than only appearing in the model zoo.
Frequently asked questions
What does Flux.jl provide?
Flux is a machine learning library written in Julia. It provides model and training tools, uses Zygote by default for automatic differentiation, and supports GPU execution through the Julia ecosystem. Its stated goal is to keep common tasks straightforward while remaining flexible.
Which version of Julia does Flux.jl work with?
Julia 1.10 or later is what the README states, phrased as what it works best with. Recent releases include v0.16.15, v0.16.14 and v0.16.13, and the package dependencies are declared in Project.toml at the repository root.
Do I have to build Flux.jl models from layers?
No. Almost any parameterised function in Julia is a valid model, such as the closure over `w`, `b` and `v` in the README example. The same function can also be written with built-in layers, shown there as a commented Chain of Dense layers.
Where are longer Flux.jl examples?
The quickstart page carries a longer version of the README example, the documentation site has the details, and the model zoo repository holds more worked examples. Questions are directed to the Julia discourse and the Julia Slack.
How should I cite Flux.jl?
If you use Flux in your research, cite the work using the CITATION.bib file at the repository root. The README also carries a Journal of Open Source Software DOI badge, 10.21105/joss.00602.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fluxml-flux-jl)Star history chart for your README
[](https://hysenlabs.com/projects/fluxml-flux-jl)Was this useful?