Graphiti: Temporal Knowledge Graphs for Agents That Must Remember What Changed
Build Real-Time Knowledge Graphs for AI Agents
At a glance
- What is it?
- Graphiti is an Apache-2.0 Python framework that builds and queries temporal context graphs, where every fact carries a validity window and traces back to a raw episode. It is a good fit if you are willing to operate your own graph database and accept that retrieval quality is your problem to solve.
- Who is it for?
- Adopt Graphiti if you need fact-level temporal history, provenance back to raw episodes, and you already run Neo4j or FalkorDB and can own retrieval tuning yourself. Do not adopt it if you want managed user and thread storage, a dashboard, or sub-200ms retrieval at scale out of the box; the README directs that profile to Zep instead.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
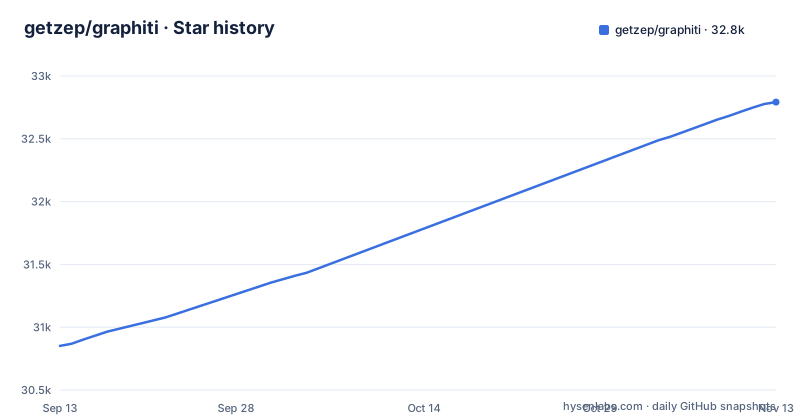
- getzep/graphiti32,792 ★ · +1,941
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| getzep/graphiti | 30.9k | 32.8k |
1,941 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: RAG Chunks Cannot Express That a Fact Stopped Being True
The README frames the target problem directly: traditional RAG approaches often rely on batch processing and static data summarization, making them inefficient for frequently changing data. When a user changes their shoe brand, a flat vector store either keeps the stale chunk or overwrites it. Neither behaviour answers the question of what was true last month.
Graphiti's answer is the context graph. A fact like "Kendra loves Adidas shoes (as of March 2026)" is stored as an edge with a validity window: when it became true, and when it was superseded. Old facts are invalidated, not deleted, per the README's description of temporal fact management. That single design decision is the whole product thesis.
The audience follows from it. This is for teams building agents over data that changes: support conversations, account state, policy revisions, product catalogues. If your corpus is a static set of PDFs that nobody edits, the temporal machinery buys you nothing and costs you ingestion time.
Four Components: Entities, Facts, Episodes, Custom Types
The README lays out the graph model in a table, and it is worth reading literally. Entities are nodes (people, products, policies, concepts) with summaries that evolve over time. Facts are edges, stored as triplets of Entity, Relationship, Entity, each with a temporal validity window. Episodes are the raw data as ingested, described as the ground truth stream, and every derived fact traces back to one. Custom Types are developer-defined entity and edge types expressed as Pydantic models.
Episodes are the part that distinguishes this from a generic property graph. Provenance is not an afterthought field; the episode is the unit of ingestion, and the graph is a derived view over the episode stream. That means you can reason about extraction errors by going back to the source rather than trusting the graph alone.
The ontology story is split in two, and the README is explicit about it: the framework supports both prescribed and learned ontology. Prescribed means you declare Pydantic models for your entity and edge types. Learned means the system works out types from the data. Most teams will start learned and add prescribed types once they see what the extractor produces, because a learned ontology over a specialised domain tends to produce generic labels.
Hybrid Retrieval: Semantic, Keyword, and Graph Traversal Together
Querying is described as hybrid retrieval combining semantic search, keyword search, and graph traversal. That is three different recall mechanisms over the same store, and the README's claim is that you query across time, meaning, and relationships rather than picking one.
The mechanism matters because each leg fails differently. Semantic search misses exact identifiers such as ticket numbers. Keyword search misses paraphrase. Graph traversal misses anything not already connected. Running all three and merging is the standard mitigation, and the README positions it as a first-class feature rather than a bolt-on.
If you need to tune how the three legs are combined, plan on reading the source. This is also where the Zep comparison bites. The README's own table states that Zep ships pre-configured, production-ready retrieval with sub-200ms performance at scale, while Graphiti requires a custom implementation and performance depends on your setup. Treat retrieval quality as work you are signing up for, not a feature you are installing.
Incremental Ingestion Without Full Graph Recomputation
The README states that Graphiti supports incremental data updates, efficient retrieval, and precise historical queries without requiring complete graph recomputation. That is the operational claim that makes the temporal model affordable. A batch pipeline that rebuilds the graph on every change would make historical validity windows pointless, because you would pay full extraction cost each cycle.
Ingestion uses an LLM, so estimate the cost per episode from your own measurement.
The practical consequence is that ingestion is the expensive path and querying is the cheap path. If your workload is read-heavy over slowly changing data, the temporal layer is overhead. If your workload is write-heavy with frequent corrections, invalidation instead of deletion is exactly what you want, and the incremental path is what keeps it viable.
Getting It Running: Graph Backend, API Keys, and Pydantic Types
Graphiti is self-hosted only, per the README's comparison table, and it expects you to bring a third-party graph database. The README's comparison table lists Neo4j, FalkorDB, or Amazon Neptune as the databases you bring yourself, and pyproject.toml has extras for falkordb and neptune alongside the required neo4j dependency.
Beyond the backend, the README names the other moving parts: an LLM for extraction and embeddings for semantic search. Those are credentials you supply. The framework does not ship a model.
The one configuration surface the README does show concretely is Custom Types, defined as Pydantic models for entity and edge types. That is where you encode your domain: declare the node and edge classes you care about, and the extractor has a target schema instead of inventing one. If you skip this step, expect generic entity labels and edges that are hard to query by type later.
The repository also contains an mcp_server/ directory and a server/ directory alongside the core library; check them against your agent tooling before wiring them in.
Where Graphiti Is the Wrong Choice
Three cases stand out from the README itself.
First, if you want managed users, threads, and message storage, Graphiti does not provide them. The comparison table lists those as Zep features, with Graphiti marked "build your own." Teams that expect a conversation store bundled with the graph will end up writing one.
Second, if you need predictable low-latency retrieval at scale without tuning, the README's own table says Graphiti requires a custom implementation and that performance depends on your setup. That is an honest statement, and it should be read as a warning rather than a footnote.
Third, if your data does not change, the temporal layer is dead weight. Validity windows, invalidation, and episode provenance all exist to answer questions about change. A static corpus gets none of that benefit and pays the ingestion cost anyway.
The Alternative Is the Same Team's Managed Product, and the Difference Is Operational
The real alternative here is Zep, and the README is unusually direct about the split. Zep is described as the unified context layer for enterprises, managing millions of context graphs with governance. Graphiti builds and queries individual context graphs.
The architectural difference is the database. Zep runs on Konig, its own graph database service, built for millions of context graphs with low-latency retrieval, so production deployments do not require a separate third-party graph database. Graphiti requires exactly that third-party database. This is not a feature-parity gap; it is a different operational contract. With Zep you buy the retrieval stack and the dashboard and the SLAs. With Graphiti you own the graph database, the retrieval implementation, and the developer tooling.
There is a second alternative worth naming for contrast: a conventional vector store with metadata filters. That approach can approximate validity windows by stamping timestamps on chunks and filtering at query time. What it cannot do is invalidate a specific fact and keep the superseded version queryable as a graph edge, because chunks are not facts. If your questions are document-shaped, the vector store is simpler. If your questions are fact-shaped and time-shaped, it is the wrong primitive.
Licence, Maintenance, and Upgrade Cost
Graphiti is Apache-2.0, which permits commercial use, modification, and distribution with the usual attribution and notice requirements. This article is not legal advice; read the licence text and your own obligations before shipping.
Maintenance cost deserves attention. Release cadence is fast: v0.31.2 landed on 2026-10-20, v0.31.1 on 2026-10-15, and v0.31.0 on 2026-10-14. Patch releases within days of each other, with titles such as "update certifi to mitigate eMudhra compromise" and "gpt-6-luna as the default OpenAI model," mean you should pin versions and read release notes before upgrading.
Because Graphiti is self-hosted only, there is no vendor patching your deployment. You own the graph database upgrades, the driver compatibility, and the retrieval tuning. The repository shows lint, unit test, and type-check workflows in its badges, which indicates the project type-checks and tests in CI. It does not tell you anything about how your workload will behave. That measurement is yours to make.
Editorial conclusion
Adopt Graphiti if you need fact-level temporal history, provenance back to raw episodes, and you already run Neo4j or FalkorDB and can own retrieval tuning yourself. Do not adopt it if you want managed user and thread storage, a dashboard, or sub-200ms retrieval at scale out of the box; the README directs that profile to Zep instead. Before committing, verify three things against your own data: how the default entity extraction handles your domain vocabulary, whether the FalkorDB or Neo4j driver version you have installed matches what the release you pin (currently v0.31.2) expects, and how many LLM calls a single episode ingestion actually triggers on your corpus.
Frequently asked questions
How does graphiti work?
It builds a temporal graph in which every fact carries a validity window, so you can ask what is true now and what was true at an earlier point, and every entity and relationship traces back to the raw episodes it was derived from. Retrieval combines semantic embeddings, keyword search and graph traversal rather than relying on summarisation by a model.
what is graphiti knowledge graph
It is what the project calls a context graph: entities as nodes with summaries that evolve, facts as triplets with temporal validity windows, episodes holding the raw data as ingested, and custom entity and edge types defined by you as validation models. The example the file gives is a statement with a date attached to it.
how to install graphiti
The manifest names the package graphiti-core, requires Python 3.10 or newer below version 4, lists a small set of required dependencies and then extras for model providers, embeddings, tracing and each graph backend, and the repository ships a compose file and a Dockerfile for running the server locally.
graphiti vs zep
The file answers this with a table. Zep is managed infrastructure with its own graph database service (Konig), built-in users and threads, pre-configured retrieval, a dashboard and SDKs, service levels and support. Graphiti is the open source framework, where you bring your own graph database, build your own user and conversation management, and self host.
Is it graphiti or graffiti?
The project is spelled Graphiti, with one t, and the name is used consistently across the repository, the package manifest and the documentation site. The framework builds temporal context graphs for agents.
graphiti vs neo4j
They are different layers rather than competitors. The graph database driver is a required dependency of the framework and is the default backend in the development compose file, while the framework builds the temporal graph on top of it and also supports other backends through extras, one of which is marked deprecated in the manifest.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Building an AI for hard conversations: five agents, one safety regex, and a supervisor who graded us blinddev.to · Nov 6, 2026 · 6 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/getzep-graphiti)Star history chart for your README
[](https://hysenlabs.com/projects/getzep-graphiti)Was this useful?